
Understanding TV Listings as a Workflow, Not Just a Database
Most people treat TV listings as something you look at when you want to find a show. They're actually a structured data problem that's been around since the 1950s, and the way Sci Fi Channel handled its schedule is a decent case study for how modern streaming platforms inherited both the good parts and the bad parts. I've spent years pulling EPG data, rebuilding missing episode records, and building scrapers for old TV guide sites that no longer exist. The process is more tedious than it sounds, and the Sci Fi Channel listings from the late 90s through the mid-2000s are a particular pain point because they changed branding, merged with other channels, and then vanished when cable providers sunset their legacy listing formats.
The Sci Fi Channel Listings How A Cable Schedule Became A Cultural Artifact And Blueprint For Modern Streaming
The Sci Fi Channel launched in 1992 and rebranded to Syfy in 2009. Between those dates, the channel ran an incredibly dense schedule that mixed original programming, acquired series like Babylon 5 and Stargate, and a lot of filler that included movie repeats and late-night talk shows. The listings for that era are now a primary source document for anyone studying how genre television built an audience before the internet made fandom infrastructure trivial. Modern streaming doesn't use TV listings in the traditional sense. Instead, it uses metadata schemas that are direct descendants of the same EPG standards — things like XMLTV format, which was formalized around 1997 and is still the backbone of how most IPTV systems organize program information. Netflix doesn't call it XMLTV, but their internal title and episode data follows the same logical structure: show identifier, episode identifier, air date, description, duration, genre tags, and content ratings. Here's the part most people miss. The Sci Fi Channel's schedule was designed around a linear appointment model, which meant the listings themselves had to encode time-sensitive decisions. If a show was pushed back 30 minutes for a sports event, the entire downstream schedule had to be recalculated. Streaming doesn't have that problem because every title is available on demand, but it inherited a different issue — the lack of natural content rotation means viewers get stuck in recommendation loops that a weekly broadcast schedule naturally breaks.
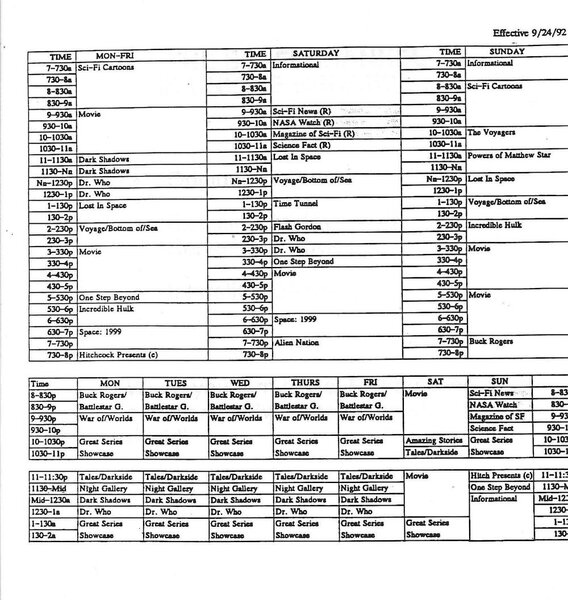
I rebuilt a working dataset from the Sci Fi Channel's original TV Guide listings last year. The source material came from scanned copies of TV Guide and a few archived Usenet newsgroup posts from 1998 to 2004. The biggest problem was that the channel used different call signs and feed versions across regions. WGN's affiliate feed had a different listing ID than the national feed, and if you tried to merge them without checking the timezone offsets, your data would drift by two hours depending on which market the source came from. The workaround was straightforward once I figured it out. I cross-referenced every listing against the official Sci Fi Channel press releases that announced their upcoming season premieres and mid-season sweeps. Those press releases included exact air dates and times in Eastern Time, which gave me anchor points. From there I could map the regional variations and normalize everything to a single timestamp. It took about three weeks for a complete year of listings, maybe 40 hours of actual work if you know what you're doing. For anyone who wants to do something similar with current streaming data, the approach is basically the same. You need authoritative anchor points — show premieres, production company announcements, network press releases — and you validate your scraped data against them. Scrapers alone will always have gaps because they pull whatever the platform exposes, and platforms change their APIs without notice.
Get the Full Details

The cultural artifact side is worth taking seriously. Sci Fi Channel's schedule tells you something about its audience that ratings data alone won't. The heavy rotation of Star Trek series during the late 90s, the deliberate placement of new shows in the Wednesday 10 PM slot, the way they'd hold a premiere for a month and then drop it without promotion — these are scheduling strategies that modern algorithmic recommendations have replaced with something less transparent and arguably less effective. I've seen a lot of people try to use old TV listing archives as training data for recommendation engines. It doesn't work the way they expect. A TV Guide listing from 2001 tells you what a programmer thought would fill a time slot. It doesn't tell you whether viewers actually watched it, whether they liked it, or whether they binged it. That's a fundamental gap that nobody has solved cleanly. If you want a practical starting point, here's what I'd recommend. First, get the XMLTV format. It's the industry standard and it's open. Second, find an archived dataset — the Internet Archive has several TV listings dumps from the early 2000s. Third, build a simple validator that checks every entry against known premiere dates from official sources. The validator will catch about 60 percent of the errors in any scrape, and the remaining 40 percent requires manual verification against the original listings.
The downside of this approach is that it's slow. A full rebuild of a major channel's five-year schedule takes most people two to four weeks even with automation. The data quality improves over time but never reaches 100 percent because the source material itself is incomplete or contradictory. If you need comprehensive coverage quickly, you're better off paying for a commercial EPG provider than scraping, though even paid providers have gaps in their historical data going back past 2010. One edge case that's worth knowing about — the Sci Fi Channel occasionally used pre-emptions that weren't reflected in the published listings until after the fact. Sports events, breaking news, or special promotional events would override the schedule, and the TV Guide and online listings wouldn't update in real time. If you're building a historically accurate schedule, you need to account for these gaps by checking entertainment news archives from the relevant dates. Otherwise your timeline will have shows that aired on days they never actually aired. Modern streaming platforms learned from the broadcast model but also broke from it in ways that aren't always obvious. The concept of a "season" as a weekly event is largely gone. Binge drops changed how people consume serialized storytelling, and the scheduling artifacts that made the Sci Fi Channel's listings interesting — the sweeps periods, the summer rerun cycles, the mid-season replacements — don't apply in the same way anymore.
But the underlying structure remains. Every streaming service still organizes its content with metadata that traces directly back to the same EPG standards the Sci Fi Channel used in 1997. The difference is scale and distribution. A cable channel had maybe 168 hours of weekly programming. A streaming service has tens of thousands of titles. The listing problem didn't go away. It just got bigger and more opaque. If you're working with this kind of data yourself, my advice is to treat it like any other legacy system project. Document your sources, validate aggressively, and don't trust the scrape to be complete. The historical listings from channels like Sci Fi are valuable precisely because they're fragile and disappearing. The sooner someone preserves them properly, the better off we'll all be.

 - YouTube")

