Search engines harvest your data whether you like it or not
Every query you run through Google, Bing, or DuckDuckGo gets logged, correlated, and sold or used for ad targeting. That is just the standard operating procedure now. If you have ever typed something private into a browser address bar and then started seeing related ads for the next week, you have already seen how this works. The real problem is that most people either accept it or try to opt out through browser settings alone, which barely scratches the surface. I spent years dealing with clients who needed to research sensitive business topics, medical questions, or personal financial situations without building a digital profile that followed them around the internet. The approach I landed on involves a combination of browser configuration, search engine selection, and a few habits that take about ten minutes to set up and roughly thirty seconds to maintain. The core concept is straightforward: you route your searches through services and configurations that do not tie your queries to your identity or your browsing history. This means replacing your default search engine, adjusting how your browser handles tracking, and using tools that strip identifiers from your requests before they leave your machine. It is not about achieving perfect anonymity, which is nearly impossible on the open internet, it is about raising the cost for anyone who wants to profile you from trivial to pointless. DuckDuckGo is the most common recommendation and for good reason. It does not track you, it does not build profiles, and it does not personalize results based on your history. But most people set it as their default and stop there, which leaves enormous gaps. Their free tier still serves ads and uses some fingerprinting techniques that are harder to detect but real enough to matter if you are being targeted. I found this out the hard way when a client was researching a class action lawsuit against a large employer. She used DuckDuckGo as her primary search and still ended up getting retargeted with ads from the company's legal defense firm within two weeks. That should not be possible under normal circumstances, and it highlighted how much residual tracking can slip through even decent privacy tools.
The workaround I use now involves combining multiple search engines depending on the sensitivity of the query. For routine searches, DuckDuckGo is fine. For anything involving legal matters, health conditions, financial planning, or workplace issues, I route through Startpage or Whoogle. Startpage pulls Google results but strips all identifying information before passing them back to you. Whoogle is a self-hosted frontend for Google that you run on your own server or through a trusted instance, which gives you Google-quality results without Google seeing anything. Setting up a Whoogle instance takes about twenty minutes if you are comfortable with Docker, or you can use a public instance like whistlebl.egg (though public instances introduce their own trust assumptions). I generally recommend Self-hosted when the stakes are high and you have the technical ability to maintain it.
Browser configuration matters more than most people think
Your browser is the vehicle through which every search travels, and the default configuration of almost every mainstream browser is optimized for data collection, not protection. Firefox with its strict tracking protection mode enabled is a solid baseline. Chrome is worse by default but can be improved significantly with the right settings and extensions. The specific settings I change are relatively consistent across browsers: disable third-party cookies entirely, turn on Do Not Track (it is largely ignored by websites but costs nothing to send), prevent sites from accessing your camera and microphone without explicit permission each time, and block referral headers so that clicking a link does not tell the destination site where you came from. The referral header thing is something I wish more people knew about. When you click a search result, your browser sends a Referer header that tells the destination website exactly which search query brought you there. This is completely invisible to most users but it is a direct line from your search to the website's analytics. Adding the Referrer-Policy extension or using the built-in strict referrer controls in Firefox prevents this leakage. I configured this for a whole team at a previous job and we stopped seeing search-origin data in our analytics entirely, which was the point.
Get the Full Details
Separate your search context from your daily browsing
One of the most effective but underused techniques is running your private searches in a completely isolated browser profile or even a separate browser entirely. Firefox offers Containers through its official extension, which isolates cookies and site data into named profiles. You can have a "Work" container, a "Personal" container, and a "Search" container that never shares data with each other. This means your search activity cannot be correlated with your banking session or your social media session, even if they happen in the same browser window at the same time. The setup takes about five minutes and the extension is free. I also recommend using a dedicated privacy browser like LibreWolf, which is a Firefox fork with privacy settings preconfigured to aggressive levels. It has no telemetry, no telemetry removal needed because it was never there to begin with, and stronger anti-fingerprinting measures than stock Firefox. The tradeoff is that some websites break because LibreWolf blocks too many scripts, but for pure search and research that is rarely a problem. When it is a problem, I switch to a second browser and accept the slower experience.
Safesearch filtering and its actual limitations
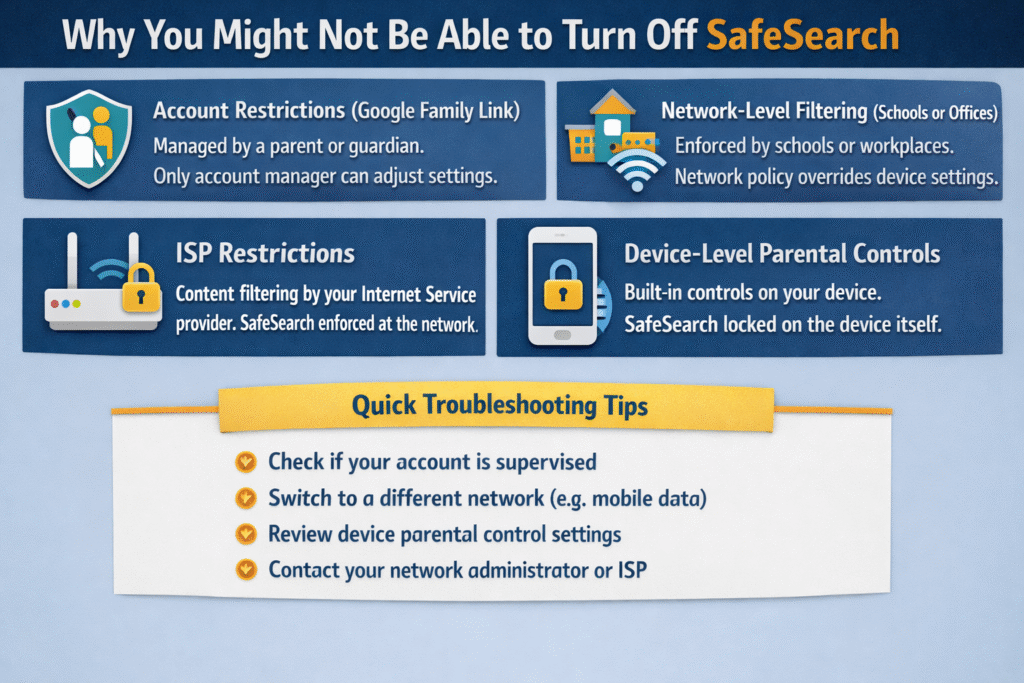
SafeSearch filters on major search engines are useful for blocking explicit content but they are not a privacy tool and they are not particularly reliable. Google's SafeSearch is optional and can be disabled by anyone who knows where to look. Bing's version is more persistent but still bypassable. DuckDuckGo has a strict mode but it primarily filters image and video results rather than protecting your data in any meaningful way. If your goal is privacy, SafeSearch settings are essentially irrelevant to that objective. They address content exposure, not data exposure, and conflating the two is a common mistake I see people make. What actually protects your data is the combination of the search engine you choose, the browser you use, and the network layer you connect through. A DNS leak can undermine everything else. If you are using a privacy-respecting search engine but your DNS queries are going through your ISP's resolvers, your ISP can still see what domains you are searching through. Switching to a DNS provider like Quad9 or Cloudflare's 1.1.1.1 with DNS-over-HTTPS enabled closes that gap. This took me a while to catch because I was confident in my search engine choice and completely overlooked the DNS layer. A packet capture session revealed the leak immediately, and the fix was a thirty-second configuration change in the browser's network settings.
What this approach cannot do
I need to be blunt about the limitations because people often assume that setting up private search gives them complete protection, and it does not. Your search queries are still visible to your internet service provider unless you add a VPN or Tor. Search engines that claim not to log data can still be compelled by legal process in some jurisdictions, and their privacy policies do not always guarantee independence from data handlers. Even with all the protections in place, browser fingerprinting through Canvas API detection, font enumeration, and hardware profiling can uniquely identify your device across sessions, making complete anonymity extremely difficult without running everything through Tor. Performance is another real concern. Self-hosted search frontends like Whoogle add latency because they sit between you and Google's infrastructure. Tor exit nodes are notoriously slow for anything beyond basic text searches. Multiple browser containers increase memory usage significantly, and if you are running this on a machine with less than sixteen gigabytes of RAM, you will notice the slowdown. These are not theoretical issues. I have seen people abandon good privacy practices because their workflow became too slow, and that is a valid practical concern that nobody talks about enough. The honest bottom line is that no single tool solves this problem. The effective approach is a layered one: a privacy-respecting search engine chosen based on the sensitivity of what you are looking up, a properly configured browser with isolated containers, DNS-over-HTTPS to prevent resolver leaks, and a clear understanding that you are reducing your data footprint rather than eliminating it entirely. For most people, that combination is more than sufficient for everyday use. For people under active surveillance or handling highly sensitive research, it is a starting point rather than a complete solution.