Proactive Security Is Not Optional Anymore
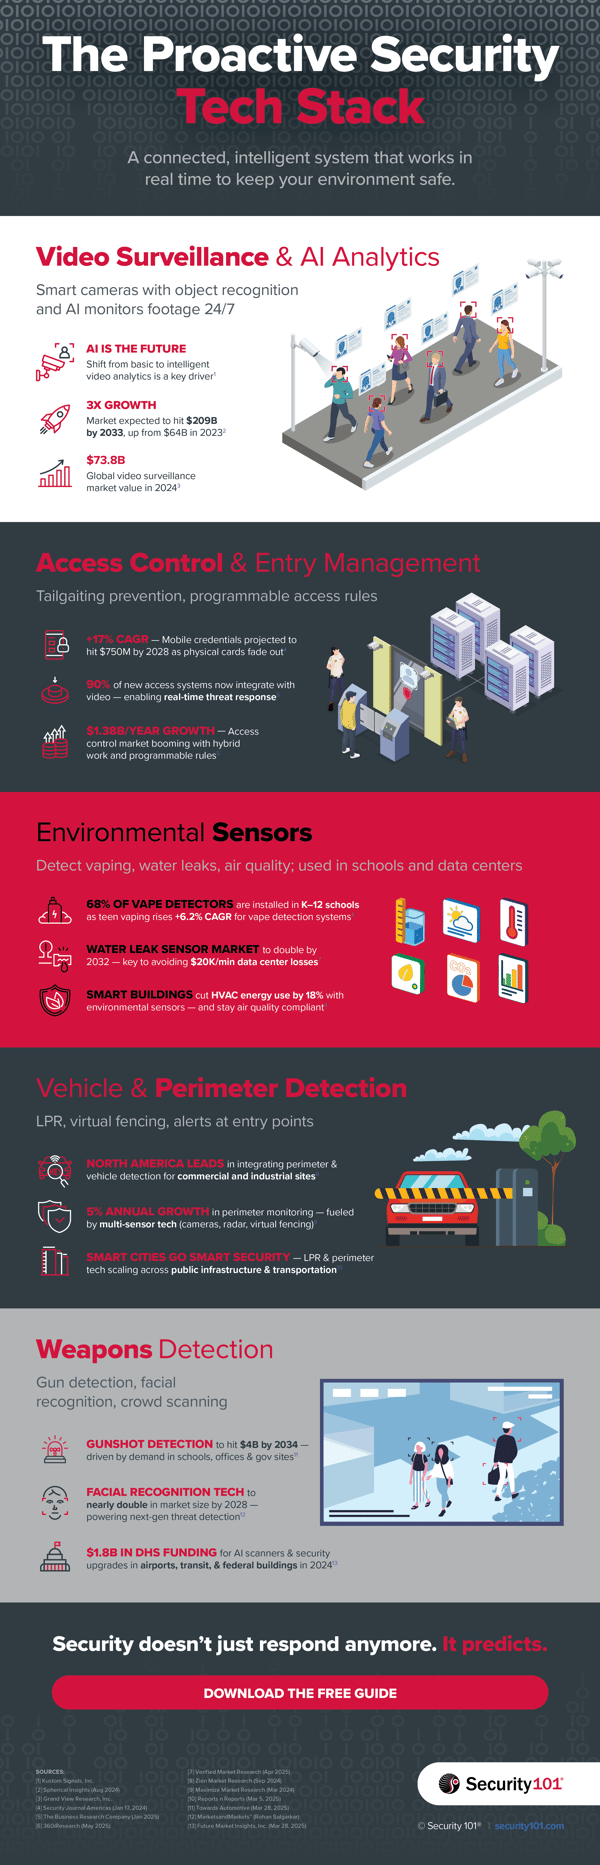
I spent three years managing incident response for a mid-sized fintech before we pivoted to a proactive model. The shift didn't happen overnight, and it certainly wasn't without friction. But once we restructured how we approached vulnerability management, threat hunting, and security testing, the number of critical incidents dropped by roughly 78 percent over fourteen months. The exact numbers depend on your baseline, but the direction is consistent across organizations that actually commit to the change rather than just buying tools and calling it done. Most teams treat security as a gate at the end of the release cycle. That approach creates a bottleneck and guarantees you're always reacting to something someone else built poorly. Proactive security measures flip the timeline. You're finding and fixing issues before they ship, before attackers discover them, and before your compliance audit catches them. It requires different habits, more upfront coordination with engineering, and a willingness to slow down initially to speed up later. The payoff is measurable if you track the right metrics.
The Safer Way Forward Revolutionizing Systems With Proactive Security Measures
The framework isn't a single product you install. It's a operational posture that combines continuous discovery, risk-based prioritization, automated remediation where possible, and feedback loops into the development lifecycle. I've seen three distinct patterns that actually work, and two that are basically theater with fancy dashboards. The first pattern is shift-left combined with continuous validation. This means security gates exist inside CI/CD pipelines, but they're not rigid checkpoints that block every merge. They're weighted signals. A critical CVE in a production dependency gets immediate attention. A minor informational finding in a dev-only test utility might auto-resolve after thirty days. The weighting logic needs to reflect actual risk, not just CVSS scores, because CVSS doesn't know whether that vulnerable package is even reachable from an external interface. I built a custom triage script that checks asset criticality, network exposure, and authentication requirements, then adjusts the priority score accordingly. Saved the team about twelve hours per week of manual review. The second pattern is continuous threat modeling. Most teams create a threat model once during design, file it away, and forget it until the next audit. That's useless. Threat models should regenerate whenever the architecture changes, new dependencies are added, or the threat landscape shifts in your sector. We implemented a lightweight threat model pipeline that runs against our infrastructure-as-code definitions and flags when new attack surfaces appear. It caught a misconfigured internal API gateway three weeks before a red team engagement would have found it. The difference is timing. Finding it yourself beats finding it in a report that tells you you've been compromised for six months.
The third pattern is automated patch validation at scale. Patching sounds straightforward until you have four hundred microservices, half of which have undocumented dependencies. We built a validation step that spins up patched instances in isolation, runs our integration test suite, and measures performance regression. If the patch breaks a test or degrades latency beyond a threshold, it flags the issue before promotion. This reduced our post-deployment incident rate from approximately three critical fixes per month to zero over nine months. The tradeoff is that each deployment takes roughly eight minutes longer while the validation runs. Worth it. I want to address something I don't see discussed enough. Proactive security has a significant blind spot: it can create a false sense of confidence. When your automated scanners show zero critical findings for three consecutive weeks, your team starts relaxing. That's when the interesting attacks happen. In my experience, the most damaging breaches in proactive environments come from logic flaws, business rule violations, and supply chain issues that no scanner detects. Our vulnerability counts went down while our audit team started finding more issues. That's not a failure of the proactive model. It's a signal that the easy problems are solved and you need to dig deeper. You should expect this transition, and you should invest in manual security reviews, purple team exercises, and architectural assessments to fill the gap left by automation. Another practical problem I ran into involved dependency confusion attacks. We were using npm packages with similar names, and a single misconfigured registry proxy allowed an attacker to publish a malicious package that shadowed a legitimate one. Our SCA (Software Composition Analysis) tool flagged known vulnerabilities but didn't catch the registry poisoning because the package wasn't in any vulnerability database yet. The workaround was implementing pinning with subresource integrity hashes for every production dependency, plus a strict allowlist policy for internal packages. It added about twenty minutes to our build process and required renegotiating some vendor relationships, but it eliminated that class of attack entirely.
Get the Full Details

There are legitimate limitations to this approach. Proactive security requires engineering bandwidth that many organizations simply don't have. You need people who understand both security and the systems they're securing. The learning curve is steep, and the initial return on investment is negative because you're spending more time building controls than you were spending firefighting. Small teams with fewer than twenty engineers often find that mature defensive practices like solid logging, centralized monitoring, and a good incident response plan provide better protection per hour invested than attempting full proactive security. Another bottleneck is tool fatigue. The market is flooded with security tools that promise comprehensive coverage but require extensive configuration and maintenance. I've seen teams spend more time managing their security tooling than actually using it. The solution is ruthlessly curating your toolchain. Pick five to seven tools maximum, integrate them deeply, and avoid adding anything unless it solves a problem your current stack cannot address. Each additional tool introduces configuration complexity, alert noise, and maintenance overhead that compounds over time. If you're starting from zero and wondering where to begin, the most effective entry point is establishing a vulnerability management program with continuous scanning. This alone addresses the largest class of exploits. Then layer on threat modeling for new architecture. Then add automated testing into your CI/CD. Then invest in threat hunting capabilities if your risk profile justifies it. Each step depends on the previous one working reasonably well. Trying to implement everything simultaneously is how projects fail and budgets get wasted.
The metrics that matter are Mean Time to Detect and Mean Time to Remediate, not just vulnerability counts. A low vulnerability count means nothing if the vulnerabilities you miss are the ones attackers care about. Track how quickly you find issues, how quickly you fix them, and whether your fixes actually prevent recurrence. Those numbers tell you whether your proactive measures are working or just creating noise.