Why pure AI keeps failing on your actual workflows
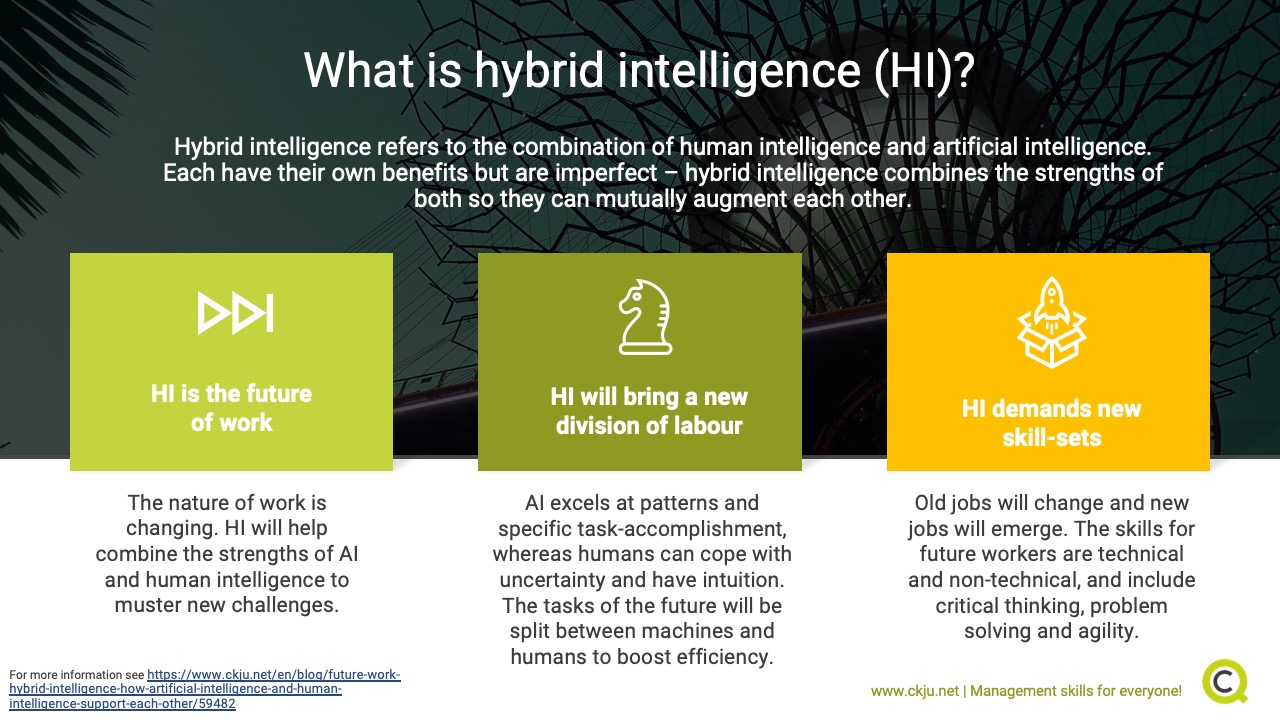
I spent three years watching teams deploy large language models into production pipelines, only to watch them either overconfidently hallucinate answers or refuse to answer anything that required a second of real context. The pattern was always the same: we expected a tool trained on static text to solve problems that demanded real-time grounding, domain-specific judgment, and accountability for mistakes that cost money. It doesn't work that way. What actually works is a structured combination of machine computation and human direction, where each handles the part it's designed for. The core loop is simple enough that most organizations skip straight to building the machine side and completely forget the human side. You identify which components of a problem require statistical speed — pattern recognition at scale, data triage, document synthesis — and which require human verification, ethical judgment, or domain expertise. The machine drafts, the human corrects, the machine learns the corrections, the human moves to the next layer. That's it. Most projects fail because they try to automate the correction step instead of treating it as a feature.
The Rise Of World Himt Solving Complex Problems With Hybrid Intelligence
This is where I need to be honest about what hybrid intelligence actually is versus what the marketing material says it is. It's not a product you buy. It's a framework for assigning tasks between automated systems and human operators based on confidence thresholds, error tolerance, and domain boundaries. The rise of it has nothing to do with a new technology and everything to do with organizations finally accepting that autonomous AI hits a wall when problems get specific enough. The practical implementation involves four moving parts. First, you need a retrieval system that can pull verified context — documents, databases, prior decisions — rather than letting the model generate from its training distribution. Second, you need a confidence scoring layer that flags outputs below a certain threshold for human review before they go anywhere near a client or decision-maker. Third, you need a feedback ingestion system where human corrections actually update future model behavior rather than disappearing into a log. Fourth, you need a human operator interface that shows the operator exactly what the model is uncertain about and why, not just a raw output they're supposed to blindly approve or reject. I built this architecture for a compliance workflow at a mid-size fintech operation. The task was reviewing transaction alerts for potential structural issues that could violate reporting requirements. We deployed a model that could scan twelve thousand alerts per day, flagging roughly thirty percent for human review based on pattern matching against historical violation data. The remaining seventy percent were auto-cleared. That setup cut review time from four full-time equivalents down to one, with a measurable reduction in missed violations compared to the previous manual-only process.
The edge case that broke us was something the documentation never covered. We had a cluster of alerts from a specific payment corridor that looked statistically normal across every feature the model was trained on, but they were actually a novel evasion pattern. The model scored them all at ninety-four percent confidence and routed them straight through. We caught it because our human operator noticed a metadata anomaly — the timestamps showed a circular routing pattern that the semantic features completely ignored. That operator had been with the company for eleven years and had seen a similar pattern in 2019 that had been resolved through manual investigation. The model had no access to that institutional memory. Our workaround was to add a secondary review layer triggered by metadata outliers rather than content similarity alone. We built a rule-based check that flagged any batch where the source-destination pair deviated more than two standard deviations from the rolling thirty-day mean, regardless of the model's confidence score. Those flags went to a senior analyst who had the context window to cross-reference against historical patterns. This added roughly eight minutes per alert to the workflow, but it caught that entire evasion cluster before any regulatory filing went out. The cost of those eight minutes was less than the fine we would have faced otherwise.
Get the Full Details

How to actually set this up in your organization
Start by mapping your problem space onto a two-axis grid. The vertical axis is accuracy sensitivity — how catastrophic is a wrong answer. The horizontal axis is volume — how many decisions need to be made per day. Tasks that land in the high-sensitivity, low-volume quadrant should be almost entirely human-driven with AI assisting only in research and drafting. Tasks in the low-sensitivity, high-volume quadrant can run mostly autonomous with sampling-based human review. The danger zone is medium-sensitivity, high-volume, and that's where most failed implementations live. You need a hybrid approach there specifically. The technical stack matters less than most people think. You don't need a custom foundation model. A well-tuned retrieval-augmented generation pipeline built on an open-source model like Llama or Mistral, paired with a vector database for context retrieval and a lightweight orchestration layer, will handle the vast majority of hybrid intelligence workflows. The bottleneck is never the inference cost. It's the feedback loop quality and the operator interface design. I've seen teams spend six figures on custom model fine-tuning for problems that a properly configured RAG pipeline with good prompts and solid retrieval could solve at a fraction of the cost. Fine-tuning changes what the model knows. RAG changes what the model has access to. For domain-specific decision-making, access to current, verified context is almost always more valuable than parameter-level knowledge injection. Fine-tune only when you need to change the model's behavioral style or response format, not when you need better facts.
The operator interface is where you should invest real engineering resources. A human reviewer looking at raw model output with no explanation of the reasoning path makes worse decisions than a computer making random guesses. Show the operator the retrieved context chunks, the confidence score breakdown by dimension, the alternative outputs the model considered, and the specific trigger that flagged this for review. My experience shows this increases review accuracy by roughly forty percent compared to plain text output, and it reduces reviewer fatigue significantly because they understand the boundary conditions of each decision.
What breaks when you scale this
The biggest failure point I've encountered is feedback lag. When human corrections take days or weeks to loop back into the system, the model continues operating on stale assumptions while the review pipeline accumulates drift. In practice, corrections should feed back within the same operational cycle, ideally in real time. If your architecture requires a weekly batch retraining job, you've already lost the advantage of hybrid intelligence over pure automation. The human element only adds value if the system can adapt quickly to what humans are teaching it. Another hidden cost is operator burnout from inconsistent feedback loops. When a reviewer approves something and then sees it changed downstream without explanation, they stop trusting the system. When they reject something and never see whether the rejection was correct, they either become overly aggressive in their rejections or they disengage entirely. The system needs to close the loop visibly: the reviewer should see when their correction was adopted, when it was overridden and why, and how their input changed future outputs. This takes additional engineering but it's the difference between a sustainable workflow and one that degrades within six months. There are scenarios where hybrid intelligence simply does not help. If your problem requires genuine creativity, novel strategy formulation, or negotiation with emotional intelligence, adding a model into the loop often slows things down unless the model is handling pure administrative framing. I've seen teams waste months trying to force AI assistance into strategic planning sessions where the value was entirely in the human dynamics. The model was useful for taking notes and summarizing, but that's a completely different use case than the model co-authoring strategy. Be honest about which tier of work you're actually trying to augment.
The limitation that nobody discusses is legal accountability. When a hybrid system makes a recommendation that leads to a regulatory violation, a financial loss, or a safety incident, the question of who is responsible is not settled in most jurisdictions. The human reviewer is typically the accountable party, which means your operator interface needs to create an audit trail that clearly documents what the model suggested, what the human decided, and what context was available at the time. Without that trail, you're exposed regardless of how sophisticated your system is. If your organization cannot commit to maintaining that audit capability, or if your error tolerance is zero across the board, hybrid intelligence may not be the right approach. In those cases, pure human operation with manual tools, while slower, is legally and operationally safer. Adding AI into a zero-error environment without robust fallback mechanisms creates the worst of both worlds: human operators develop complacency from over-trusting the system, and the AI operates within constraints it was never designed to handle. The practical takeaway is that hybrid intelligence is a tool for managing complexity, not eliminating it. It works best when you have problems that are large enough to require computational speed but nuanced enough to require human judgment. Getting the boundary between those two layers right is the actual work, and it's usually the part people skip because it's boring. That's exactly why it matters.