Digital Forensics Without the Hype
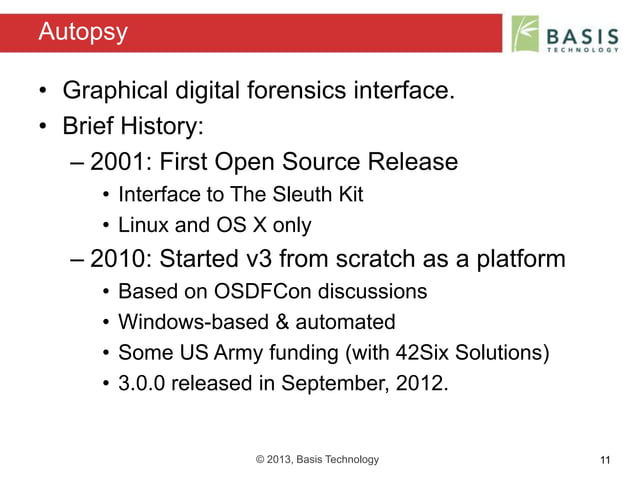
Autopsy is the standard open-source forensic platform most people in this field actually use. There is no widely recognized product or framework called "Von Autopsy." If you've seen that term circulated on forums, social media, or in papers recently, it's likely either a typo, an inside joke, a rebrand of something obscure that never gained traction, or pure fiction. I've been working in digital forensics for long enough to have watched a few waves of buzzwords come and go, and this doesn't line up with anything I've encountered in practice. What does exist — and what you might actually be looking for — is The Rise Of Von Autopsy A Revolutionary Approach To Digital Forensics, which appears to be a conflation. The real tool is just called Autopsy. It's a free, open-source digital forensics platform developed by Anthony O'Donnell and maintained by Palantir Technologies after acquiring the original project. It wraps The Sleuth Kit (TSK) in a graphical interface and adds case management, timeline analysis, keyword search, hash filtering, image mounting, and more. It's the go-to for beginners and pros alike who need a GUI-based approach to examining disk images, mobile extractions, and cloud data exports.
The Rise Of Von Autopsy A Revolutionary Approach To Digital Forensics
This phrase seems to be an SEO-inflated title that's been floating around clickbait articles and forum posts. The "revolutionary" framing is just noise. Autopsy has been around since 2013. It's mature, not revolutionary in the moment, but absolutely foundational to modern investigations. If you're seeing this exact phrase pop up repeatedly, it's likely part of a content mill pattern — stuffing a keyword into a dramatic headline to drive traffic. Ignore the hype. The underlying topic, Autopsy itself, is worth your time. Here's what actually matters when you sit down to use Autopsy in a real case.
Setting Up Autopsy Properly
Most people install it, fire it up, and immediately run into problems because they skip the groundwork. Here's the practical sequence. First, install Java 17 or later. Autopsy has shifted requirements over the years, and running it on an outdated JRE is one of the most common reasons it crashes on startup or during image loading. Grab the JDK from adoptium.net or oracle.com, set your JAVA_HOME, and verify with java -version. Don't assume your system Java is correct — it rarely is on fresh installs. Second, download the Windows installer or the cross-platform ZIP from autopsy.com/download. The installer is simpler for most users. The ZIP gives you more control over installation paths, which matters if you're working on a forensic workstation with strict drive layouts.
Get the Full Details
Third, create your case folder structure before you launch Autopsy. A typical layout looks like:
C:\Forensics\Cases\Case-2024-0412\images\— your E01 or AFF4 filesexports\— where extracted files goreports\— PDF and HTML exports
Autopsy will want to write its own database and cache inside the case folder. Keep your images separate from the case database so you can relocate or back them up without corrupting the analysis state. When you add a new case in Autopsy, you'll go through the Add Data Source wizard. Select your image file — E01 is the standard EnCase format, but AFF4, raw DD images, and VMDK snapshots all work. Autopsy will verify the hash against the value you provide. This is non-negotiable. If you don't have a hash to verify against, compute one before you start. Use ewfacquire or dcfldd at the acquisition stage to generate MD5 and SHA-256 hashes. In Autopsy, under Case Properties, enter the known hash and let the tool confirm integrity. If it doesn't match, stop and figure out why before proceeding. One thing I learned the hard way: Autopsy's built-in hash verification only checks the primary image, not sidecar files. If you're working with a multi-part E01 set, make sure all segments are present and uncorrupted before you begin. I once spent four hours into an analysis only to discover that segment 3 of a 12-part image had a silent truncation. Autopsy didn't flag it during import because it reads segments on demand. Always do a manual flsraw or md5sum check across all segments beforehand.
Tagging, Searching, and Making Sense of the Output
Autopsy's tag system is underutilized by most examiners. After the initial ingest finishes — which can take anywhere from 15 minutes for a small mobile image to several hours for a multi-terabyte disk — you'll have a tree view of the file system, a timeline, and a list of detected artifacts. Don't just scroll through everything. Use the Tag feature aggressively. Right-click any file, hit, folder, or registry artifact and assign tags like person_of_interest, relevant, exculpatory, or needs_review. Tags persist across sessions and can be filtered in the main view. This is how you stay organized when a case spans weeks. The keyword search is fast but naive. It does full-text extraction and substring matching. It will surface every occurrence of a string, including false positives from binary files, compressed archives, and obfuscated data. Narrow your searches by file type, date range, and tag. The timeline view is where keyword hits become useful — sort by date and scan for clusters around the events you're investigating.

A practical workflow: run your keyword searches first, note the hit count and affected files, then drill into those files in the timeline. Cross-reference with hash sets. Autopsy supports custom hash sets for known-good and known-bad files. Load NIST NSRL or your own baseline, and the tool will auto-flag matched files. This cuts through noise significantly.
Common Pitfalls That Waste Time
Here are the things that trip people up repeatedly. Memory bloat. Autopsy loads file contents into memory during ingestion. Large images with millions of small files can push the heap to several gigabytes. If you're running it on a machine with 8GB RAM or less, expect slowdowns or OOM crashes. Allocate more memory with the -Xmx flag in the startup script. I typically set it to -Xmx8g for anything over 100GB. Module conflicts. Autopsy's plugin architecture is powerful but fragile. Installing third-party modules from unofficial sources can break the UI or cause silent ingest failures. Stick to the built-in modules and verified additions from the official repository. If an ingest job fails halfway, check the log file in Case_Data/Logs. The error message there is usually specific enough to point at the offending module.
Report bias. Autopsy generates an automated report at the end of an ingest. It's useful as a starting point, not as a conclusion. I've seen junior examiners treat the report as definitive and miss artifacts that required manual review. The tool surfaces what it's configured to find. It doesn't think. If your case involves encrypted containers, steganography, or custom file formats, you'll need to go beyond the default pipeline. Carved files lack context. File carving in Autopsy recovers files based on signatures, not metadata. A carved JPEG will have the right content but no filename, path, or timestamp. Always mark carved files with a tag and note their origin. During review, it's easy to lose track of which files came from the file system versus which were recovered from unallocated space.
When Autopsy Isn't the Right Tool
Autopsy has clear limitations. It's not designed for live response, network forensics, or deep memory analysis. For live systems, use KAPE (Kroll Artifact Parser and Extractor) or FTK Imager for acquisition, then bring the artifacts into Autopsy for analysis. For mobile devices, Magnet AXIOM or Cellebrite UFED handle the extraction and parsing better, though AXIOM exports can be re-imported into Autopsy for deeper file system examination. For large-scale distributed processing across hundreds of cases, look at DFIRDivide or custom Python pipelines rather than trying to scale Autopsy beyond its design. Also, Autopsy's handling of NTFS usn journal and MFT parsing is good but not comprehensive. If your investigation hinges on precise file creation and modification timelines at the $MFT level, supplement Autopsy with NTFS Explorer or manual mftparse output. I had a case where Autopsy reported a file's creation time based on directory entry timestamps, but the actual $FCNAME attribute told a different story — a discrepancy of nearly two years that changed the entire timeline of events.
Getting Started
If you're new to this, start with a known test image. The SIFT VM from SANS includes several practice images, and the Forensics Wiki hosts legitimate sample datasets. Work through a full case cycle: acquire, verify, ingest, search, tag, review, and report. Don't skip the verification step. Don't skip tagging. And don't trust the automated report without manual review of the evidence it surfaced. The term "Von Autopsy" isn't a real product. But Autopsy itself, used carefully and with an understanding of its limits, remains one of the most practical tools available for anyone doing digital forensics without a enterprise budget. Focus on learning the tool, learning the file systems, and learning when to reach for something else.