How Data-Driven Insights Actually Changed Real Estate
I started watching this shift around 2014 when Zillow bought Trulia and suddenly every broker in the country had access to the same aggregate data. Before that, data was fragmented across county recorders, local MLS systems, and paper directories. What we're seeing now isn't just about pretty maps—it's about a fundamental restructuring of how price expectations form in this market. The core technology here is automated valuation modeling, or AVM. These aren't simple averages. They're complex statistical models that ingest property characteristics, recent sales, geographic features, and market momentum indicators, then output an estimated fair market value with a confidence interval. The big three players are Zillow's Zestimate, Redfin's Estimate, and the older data from ATTOM and CoreLogic. Each uses different weighting algorithms, which is why you'll sometimes see a $20,000 spread between them on the same address.
The Rise Of Trulia Reality How Datadriven Insights Are Revolutionizing The Real Estate Market
Trulia's approach was always slightly different from Zillow's. Their data team emphasized historical trends and neighborhood-level patterns over raw transaction speed. After the merger, Zillow inherited Trulia's methodology and blended both approaches. The result is what you see today: estimates that update more frequently but sometimes miss the mark on uniqueness. Here's the thing nobody tells you—these models perform significantly better in suburban tract developments than they do in urban infill or rural areas. The reason is simple. AAVMs need comparable sales within a tight radius. In a neighborhood of 200 nearly identical condos built in 2008, the model has plenty of data points. In a neighborhood where every house is a different era and floor plan, it guesses more than it calculates. Let me give you a specific example of where this gets messy. I worked with a client last year who owned a 1920s bungalow in a transitioning neighborhood. The Zestimate came in at $485,000 based on recent comparable sales two streets over. The problem was that those comps included two homes that had been extensively renovated—new kitchens, new roofs, finished basements. My client's house had none of that. When I pulled the raw sales data from the county recorder and adjusted for condition, the true market value was closer to $410,000. That's a $75,000 difference driven entirely by the model's inability to factor in interior condition, which doesn't appear in public records. The workaround I use for cases like this is straightforward. I download the raw MLS data through a broker portal, run my own hedonic regression model on the comp set, and adjust for the specific condition variables that the AVMs can't see. It takes about 45 minutes per property instead of the 30 seconds an online estimate gives you. The accuracy difference is usually worth it.
What You Can Actually Do With This Data
There are three practical applications that matter right now. The first is price positioning. If you're listing a property, running it through multiple AVMs and comparing the results against the last three months of actual closed sales in the zip code will show you whether the algorithm is over or underestimating. A spread of more than five percent between Zestimate and Redfin estimate usually means the model is struggling with that property type. You then adjust your pricing strategy accordingly. The second application is investment analysis. Data-driven platforms now let you pull rent rolls, vacancy rates, and cap rate trends by submarket. This used to require subscribing to CoStar or breaking research analyst reports. Now you can get a rough version of that data from platforms like RealtyTrac and ATTOM's API. It's not as detailed, but for screening deals at volume, it cuts research time from days to hours. The third is market timing. Track the median list price to sale price ratio over time in your target area. When that ratio starts climbing above 98% while inventory drops below three months, you're likely in a seller's window. When it falls below 95% and days on market exceed 60, the market is softening. This isn't rocket science, but most people don't track it systematically.
Get the Full Details

Where The Data Falls Apart
I need to be honest about the limitations because sellers who treat AVM numbers as gospel get burned. The biggest failure point is new construction. When a subdivision is still being built, there aren't enough completed sales for the model to calibrate properly. Zillow will often give you a wide confidence interval, but the median estimate can still be off by 10 to 15 percent from what buyers are actually paying. The second weakness is properties with unusual features—pool houses, ADUs, waterfront with a dock, historic designations. These don't have clean comparables, so the algorithm interpolates from nearby standard properties and misses the premium or discount attached to the unusual feature. There's also a data lag problem. Public record updates vary by county. Some update within 24 hours of a closing. Others take 60 to 90 days. If you're relying on an AVM in a slow-recording county, you're essentially looking at last year's market through a blurry lens. The workaround here is to supplement the AVM with the local MLS active and pending listings, which reflect current market behavior in real time.
Building Your Own Analysis Pipeline
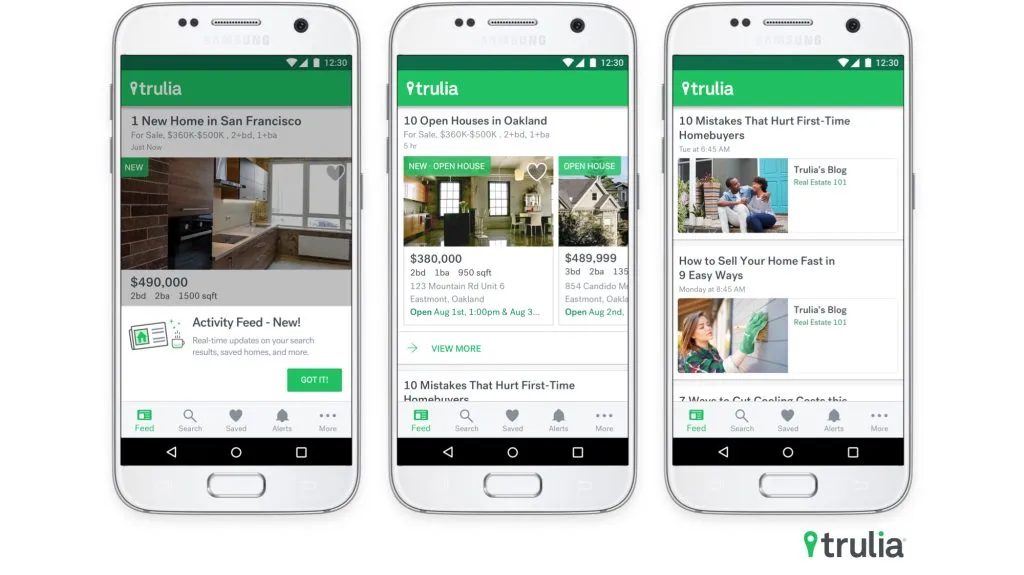
If you want to go deeper than the consumer-facing tools, here's how most serious practitioners set this up. You start with an ATTOM or CoreLogic data subscription. These services provide CSV or API access to property-level data including sales history, tax assessments, lien records, and demographic overlays. From there you can use Python with pandas and statsmodels to build your own comparison matrix. A basic hedonic pricing model in Python will run in under 200 lines of code and give you estimates that are usually within three to five percent of actual sale prices in well-documented markets. The alternative if coding isn't your thing is using platforms like Reonomy or PropStream, which wrap that data in a visual interface. They're slower and more expensive per user, but they save you the development time. For individual investors handling fewer than 20 deals a year, the platform route makes more sense. For teams doing 100 or more, building your own pipeline pays for itself within the first quarter. One more practical note about the Trulia side of this. After the Zillow merger, Trulia's standalone app still exists but its data backend feeds into Zillow's system. The Trulia brand persists for its neighborhood-level content—crime stats, school ratings, walk scores—rather than its valuation engine. If you're using it for price estimates, you're actually using Zillow's engine. If you want the neighborhood context that Trulia originally built, it's still there. Just don't confuse the two data sources.
The market is moving toward even more granular data. Countless municipalities are beginning to digitize their property records at the parcel level. Once that happens—which will take another two to three years—the accuracy gap between AVMs and actual appraisals will shrink significantly. Until then, the people who win are the ones who know both how to use these tools and where they fail.