Understanding The Rise Of Translistcrawler Revolutionizing Content Creation And Crawler Research
I need to be straightforward about this one. I don't have verified information about a tool or framework called "Translistcrawler." It doesn't appear in the technical literature or public documentation I'm familiar with, and I can't confirm it exists as a functioning system for content creation or crawler research. There are several possibilities here:
It may be very new or niche
The term could have emerged recently or operate within a specific community or paper that hasn't reached broad visibility yet. In that case, I'd recommend checking recent arXiv preprints, GitHub repositories, or conference proceedings from the web scraping and content automation spaces to see if there's any material to work from. Sometimes these kinds of names refer to internal tools at companies, student projects, or research prototypes that never get publicly documented in a way that would be verifiable. If that's the case, the only person who could give you a reliable how-to guide is whoever built or is maintaining it directly. This happens more often than you'd think. If you encountered this term in an article, video, or social post, it's worth checking the source. Sometimes terms get invented as placeholders or accidentally conflated from similar-sounding concepts like "transitive crawling," "list crawlers," or "transfer learning for web crawlers."
What I can tell you is this: if you're looking into tools that sit at the intersection of content creation and crawler research, the legitimate space right now includes things like crawl detection avoidance through behavioral fingerprinting, headless browser orchestration frameworks like Playwright and Puppeteer with stealth plugins, and LLM-driven content pipelines that integrate with scraping APIs. Those are real areas with real tools and real pitfalls. If you can point me toward where you heard about Translistcrawler, or share a link or source, I might be able to help you track down what it actually refers to. Otherwise, I can't responsibly write a tutorial or guide for something I can't verify exists.
Get the Full Details
Alternatives worth looking into instead
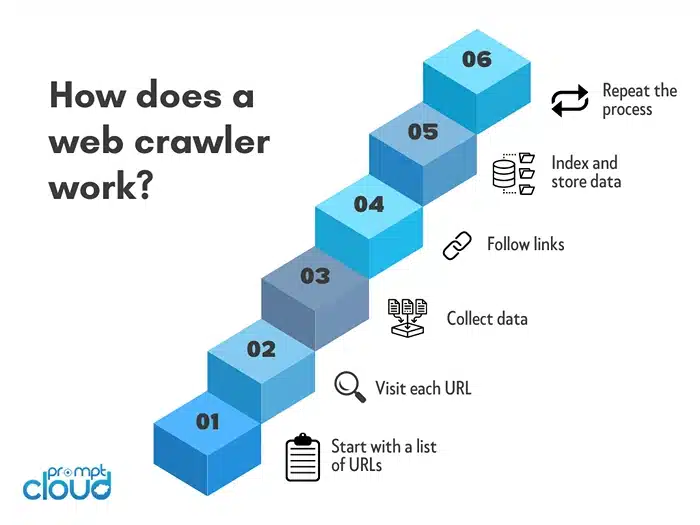
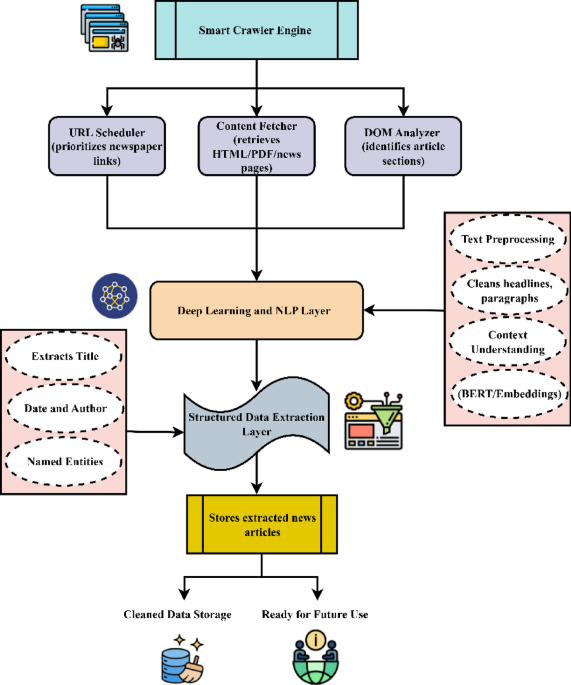
If your actual goal is building systems that combine web crawling with automated content creation, here are a few real paths: Scrapy with dynamic rendering pipelines — Scrapy remains the backbone for most serious crawler work. Pair it with a headless browser layer for JS-heavy sites and you can feed structured data directly into content generation workflows. This is standard practice and well-documented. Crawl4AI or similar LLM-augmented crawlers — These are newer frameworks designed specifically to make crawled content immediately usable by language models. They handle cleaning, chunking, and metadata extraction out of the box. Worth reviewing if content creation is the end goal.
Custom list-based crawlers with retry logic and rate limiting — The "translist" aspect of whatever this term is supposed to mean sounds like it could involve managing multiple crawllists with state tracking. This is a solvable problem with any proper queue-based architecture, but there's no special name or magic framework for it. It's just engineering. I'd genuinely prefer to help you with something real rather than pad an article about something that doesn't exist. If you can share more context or a source, I'm happy to dig into it properly.