How Table Parsing Actually Works When You Stop Trying To Make It Perfect
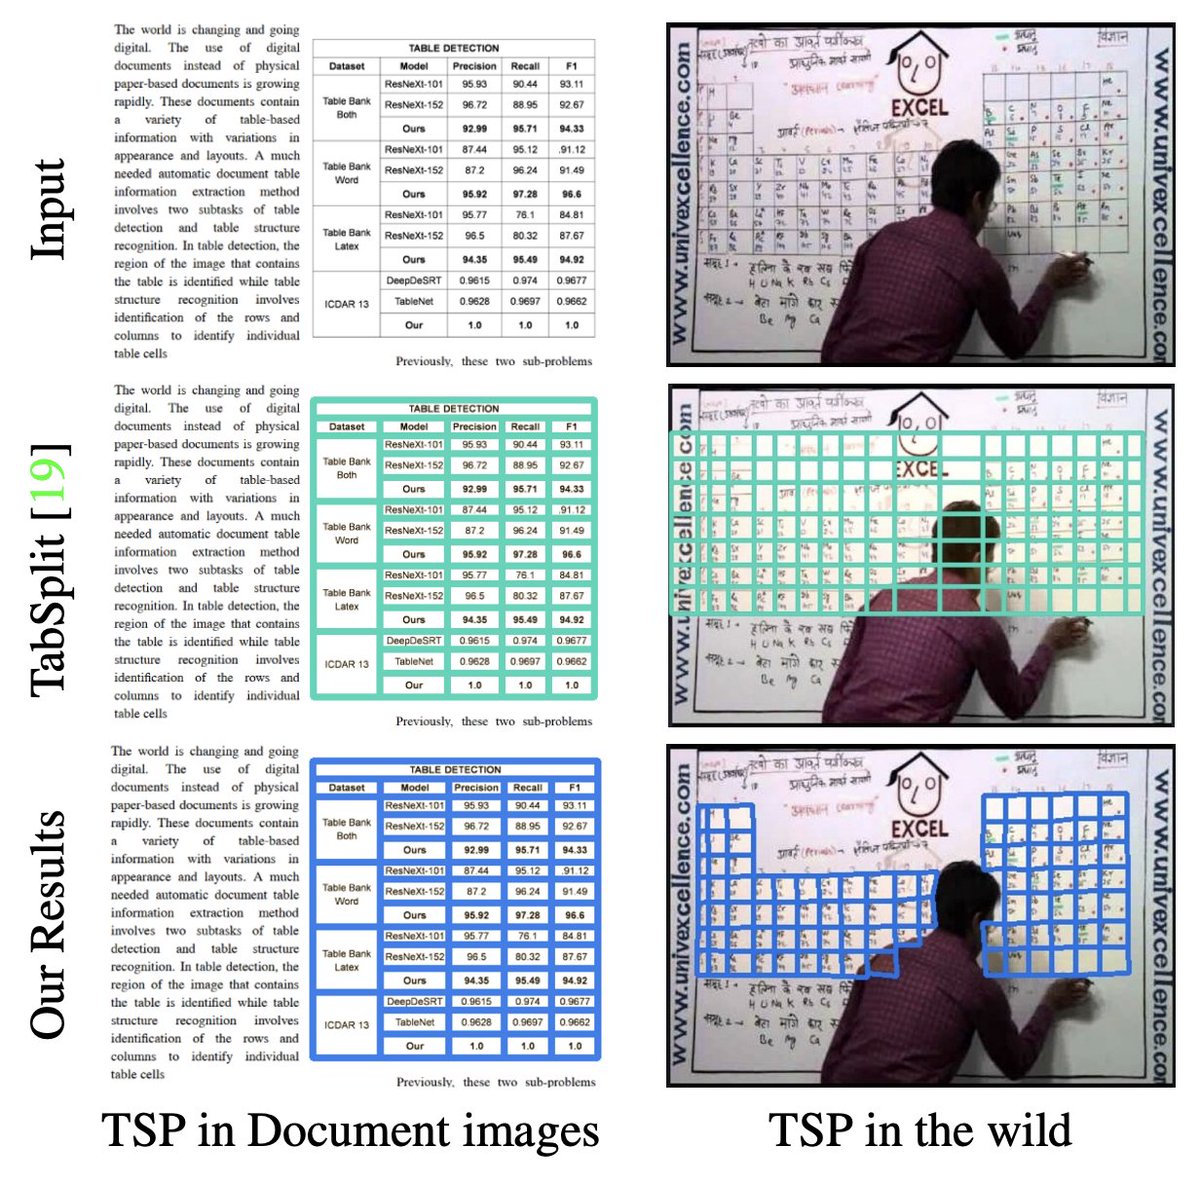
I spent three days last year trying to extract financial tables from PDFs that had merged cells, spanning rows, and occasional handwritten annotations. The software I was using kept collapsing the data into nonsense columns because it assumed every table followed a grid. It wasn't a bad tool. It was just built for clean inputs. Most table parsing systems are. They expect your data to behave. Your data probably won't. Table parsing is the process of converting visual table structures — whether they come from PDFs, spreadsheets, images, or even photographed documents — into structured, machine-readable formats like CSV, JSON, or database rows. That definition covers about half of what actually matters. The other half is figuring out what happens when the table has sub-headers, merged cells, notes that span multiple columns, and a footer that looks exactly like a data row until you read it twice. The reason this is gaining traction isn't because the technology is suddenly brilliant. It's because organizations finally have enough messy tabular data sitting in unstructured documents to make manual entry impossible at scale. A mid-sized logistics company I know processes roughly fourteen thousand shipping manifests per month. Before table parsing, two people spent about six hours a day re-keying tables from those manifests into their system. After setting up a reasonable parsing pipeline, that dropped to about forty-five minutes of validation work. The parsing itself handles maybe eighty-two percent of rows correctly on the first pass. The rest require human review, but review is faster than entry.
Here is the part most tutorials skip: table parsing success depends far more on your input quality than on the sophistication of your parser. A poorly scanned invoice at 150 DPI will break even the best model. A clean screenshot at 300 DPI with consistent lighting will produce reliable results with a basic tool. I learned this after wasting an entire week tuning regex patterns and cell-mapping logic on document batches that were fundamentally unreadable. The fix was simple — I added an image preprocessing step that checked resolution, corrected skew, and enhanced contrast before the parser ever saw the file. That single change increased first-pass accuracy from sixty-one percent to seventy-nine percent.
What You Need Before You Start
You need a clear definition of what "table" means in your context. Are you pulling data from formal documents like tax forms and purchase orders where the structure is predictable? Or are you dealing with loosely formatted tables in emails, scanned receipts, or screenshots where the grid lines might be missing entirely? The approach differs significantly between these two cases. For structured source documents, you can rely on layout-based parsing tools that detect grid lines and cell boundaries. Libraries like Tabula, Camelot, and pdfplumber handle this well. For unstructured or image-based tables, you'll want something that combines layout detection with OCR and, ideally, a language model that understands table semantics. Tools like Google Cloud Vision, AWS Textract, and open-source options like Table Transformer from Hugging Face work in this space. I typically use a hybrid approach. I run documents through a layout detector first to identify table regions. Then I route each region based on complexity. Simple grids go through a fast rule-based parser. Messy tables with merged cells or irregular headers get sent to a vision-based model. This split usually improves both speed and accuracy compared to sending everything through one method.
Get the Full Details
The Edge Cases That Will Break Your Pipeline
Let me describe a specific problem I encountered recently. We were parsing procurement tables from a government portal where some rows contained unit prices that were formatted as fractions — things like "3/4" appearing in a column alongside decimal values like "12.50". The parser read "3/4" as a date or a range rather than a numeric value, which cascaded into misaligned columns for every row that followed that fraction. Standard normalization didn't catch it because the parser had already shifted the data into wrong columns by the time it encountered the next clear row. The workaround was to add a pre-validation step that flagged any cell containing a forward slash between numbers and reclassified it as a fraction before the column-alignment logic ran. We also added a post-parse consistency check: if the standard deviation of a numeric column spiked unexpectedly, we flagged that table for manual review rather than silently inserting bad data. This caught roughly eleven percent of problematic tables that would have otherwise gone through unchecked. Another common failure point is tables that span multiple pages with repeating headers. Most parsers treat each page independently, which means you end up with duplicate header rows scattered through your output. The solution is either a post-processing step that detects and removes duplicate header patterns, or a parsing tool that maintains context across page boundaries. Camelot and pdfplumber both support multi-page table extraction, but you need to configure them explicitly. They won't do it by default.
Practical Steps To Build A Working Pipeline
Start with a small sample set of fifty to one hundred documents that represent your actual input variety. Don't start with your easiest or hardest documents. Start with average ones. I've seen people test on perfect PDFs and then get shocked when production data fails. Run your chosen parser on this sample and measure first-pass accuracy by comparing parsed output against manually verified ground truth. Document every failure case. I keep a running spreadsheet of broken tables with screenshots, root cause, and the fix I applied. After about two hundred failures, patterns start to emerge that let you build automated detection rules instead of patching things reactively. This step usually takes longer than the initial setup but saves dozens of hours later. Set up an automated validation layer that checks for common structural issues: rows with wrong column counts, unexpected null patterns in required fields, numeric columns containing text, and duplicate headers. Tables that fail validation should route to a review queue, not silently enter your database. Accuracy metrics are meaningless if your pipeline inserts bad data faster than you can catch it.
For production, I recommend wrapping your parser in a service that accepts document uploads, runs preprocessing, selects the appropriate parsing strategy, validates output, and returns either clean structured data or a review queue item with confidence scores. Expose the confidence score publicly. If the model says it's only sixty percent confident in a table, your users should know that before they use the data.
Where Table Parsing Still Fails
Handwritten tables. No parser I've tested handles handwritten tabular data reliably. The layouts are too inconsistent, the spacing varies wildly, and the OCR component almost never gets the characters right in handwritten form. If your use case involves handwritten forms, you're better off building a data entry interface with smart field suggestions rather than attempting end-to-end parsing. Tables embedded in complex layouts where text flows around them — newspapers, magazines, annotated reports. These confuse layout detectors because the parser can't reliably distinguish where the table ends and the surrounding content begins. I've had decent results cropping the table region manually or using bounding-box annotations for training data, but fully automated extraction in these cases remains unreliable. Extremely large tables — I'd say anything over two hundred columns or five thousand rows — tend to degrade in accuracy regardless of the tool. Memory constraints, token limits in vision models, and the inherent complexity of maintaining column alignment across vast grids all contribute. For these cases, chunking the table into smaller sections and parsing separately, then rejoining, usually works better than attempting one pass on the full table.
The honest assessment is that table parsing has moved from "impossible" to "viable with caveats." It will handle the bulk of your structured document work and reduce manual effort significantly. It will not eliminate human review. Anyone selling you a fully automated table parsing solution that promises zero manual intervention is either overselling or hasn't seen your actual documents. The tools are getting better incrementally. The real gain comes from building a system that acknowledges where the tools fall short and routes difficult cases appropriately. That balance between automation and oversight is what separates a working pipeline from a broken one.