Working With Zillow Data For Pennsylvania Market Analysis
Zillow publishes a lot of data publicly, but actually using it for Pennsylvania real estate requires more than opening the website and scrolling. The core challenge is that their API used to be fully open, then they shut it down, and now you have to work with scraped data, third-party CSV exports, or the Zillow Research dataset which covers broader trends at the county and metro level. I spent about three weeks last year trying to build a straightforward price trend model for Southeastern Pennsylvania counties. What I learned was that Zillow's automated valuation model (AVM) accuracy varies wildly depending on where you are in the state. In Philadelphia proper, the typical error rate sits around 6-7%. Out in clearer rural markets like Potter County, it climbs toward 10-12% because there simply aren't enough recent comparable sales to ground their algorithm. This is something most people miss when they start pulling numbers from the site.The Rise Of Real Estate In Pennsylvania A Deep Dive Into Zillows Data
Getting started means accepting that you won't get clean, structured data out of Zillow directly anymore. The old REST API was deprecated in 2022. Your options are limited to Zillow Research downloadable datasets which give you historical metrics at the metropolitan statistical area and county level, or you write your own scraper for listing-level data. I use a combination of both. The Research datasets cover things like median listing price, median days on market, and inventory counts going back several years. For finer-grained analysis at the borough or township level, I pull listing data directly. The scraper I built runs on Python with requests and BeautifulSoup, hitting the listing search pages and parsing the results. It takes roughly 45 minutes to scrape about 2,000 active listings across six Philadelphia suburbs. That timeframe depends heavily on how many pages you're pulling and whether Zillow's rate limiting kicks in mid-scrape. One edge case that cost me two days of debugging: Zillow serves different HTML structure for search results depending on whether you're viewing from a mobile or desktop user agent, and it changes the class names intermittently without warning. My scraper started returning empty fields one morning because they renamed a div class from "home-card" to something entirely different. The fix was to add a user-agent rotation and key off multiple CSS selectors as fallbacks rather than relying on a single class name. I also added a simple schema validation step that alerts me if any extracted field falls outside expected ranges, which caught the break within minutes instead of after I'd already processed thousands of records.
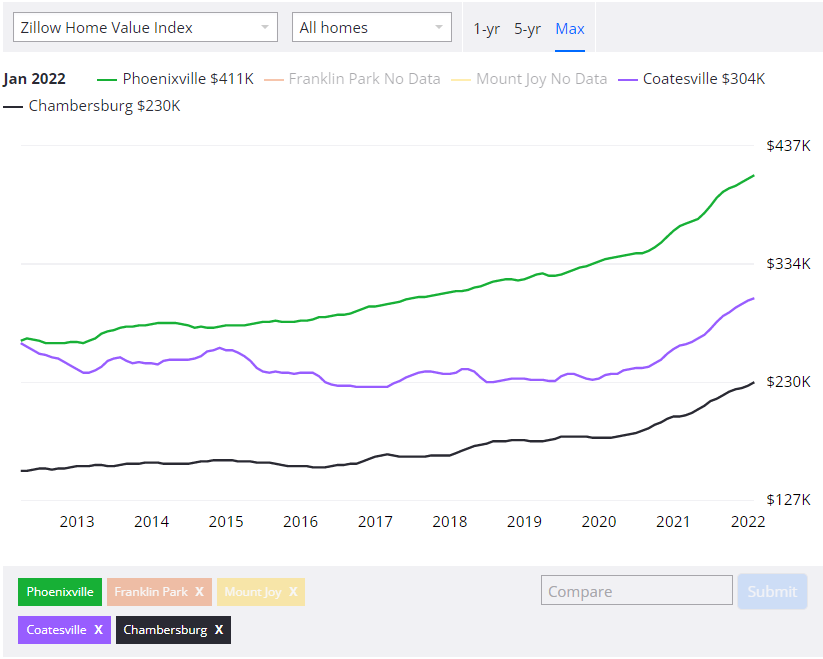
The data you can actually extract and trust falls into a few categories. Listing price and history is the most reliable since it's seller-reported. Days on market tends to underreport true time because Zillow resets the clock when a listing goes pending and comes back active. Tax assessed value appears on some property pages but is frequently incomplete or several years old, especially in Pennsylvania where assessment cycles vary by county. Property details like square footage and bedroom count are user-edited on Zillow's platform, so they carry uncertainty. I cross-reference those against county assessor records when I need accuracy. Pennsylvania is tricky for this kind of analysis because the market doesn't behave uniformly. Montgomery County tracks more closely with the Philadelphia metro trend line. Lehigh Valley follows its own pattern influenced by proximity to New York commuters. The oil and gas regions like Marcellus Shale counties had their own boom cycle that doesn't appear in state-wide aggregates. If you're aggregating data at the state level, you'll smooth over all of that variation and end up with conclusions that don't match what's happening on the ground in any specific county. A counter-intuitive finding I hit while working through this: Zillow's "rent estimate" for Pennsylvania properties is consistently 10-15% higher than what landlords are actually achieving in secondary markets outside the Philly and Pittsburgh metros. The algorithm seems calibrated toward urban rental data and doesn't adjust well for rural pricing. If you're using Zillow rental estimates to calculate cap rates in places like Susquehanna or Pike County, you need to manually adjust downward before doing any investment math. Otherwise your numbers look promising and then the actual rent roll tells a different story.
For inventory tracking, Zillow's active listing count is reasonably accurate but lagging by about three to five days compared to the MLS. A property might show as active on Zillow for four days before it actually hits the local association's MLS feed. This matters if you're tracking absorption rates month-over-month because you'll see phantom inventory that hasn't officially entered the market yet. The biggest bottleneck in this whole process is deduplication. Zillow sometimes lists the same property under multiple URLs when a listing has been relisted or when address variations exist. I run a fuzzy match on address and zip code combined with price history to catch duplicates. A simple contains check on the street address catches about 80% of them. The remaining 20% usually involves properties with legal descriptions that differ from the mailing address, which is common in older Pennsylvania townships. There's no single download link for everything you need. The Zillow Research page at zillow.com/research/ offers CSV and Excel exports for their historical datasets. Those are the cleanest files available and they update quarterly. For listing-level data, you handle the scraping yourself or pay for a third-party data aggregator like ATTOM or CoreLogic if you need production-grade reliability.
Get the Full Details
The practical workflow I ended up using: start with the Zillow Research county-level data to establish the macro trend, then layer in scraped listing data for the specific submarkets I'm analyzing, then pull county assessment records from each municipality's website to validate the property-level details. It's tedious but it produces results that actually hold up under scrutiny. One more thing that trips people up: Zillow's HPI (House Price Index) for Pennsylvania can differ from what local board of Realtors reports. The methodologies are different. Zillow uses transaction data weighted toward higher-value properties in certain periods, which skews the index upward relative to median sale prices reported by regional associations. If you're citing these numbers in a report or presentation, you need to specify which source you're using because they won't match. The data is useful if you approach it with realistic expectations about its limitations. Pennsylvania's fragmented market structure means state-level aggregations obscure more than they reveal. County-level or submarket-level analysis is where you'll find the actual signal.