Why I Finally Stopped Patching ETL Pipelines by Hand
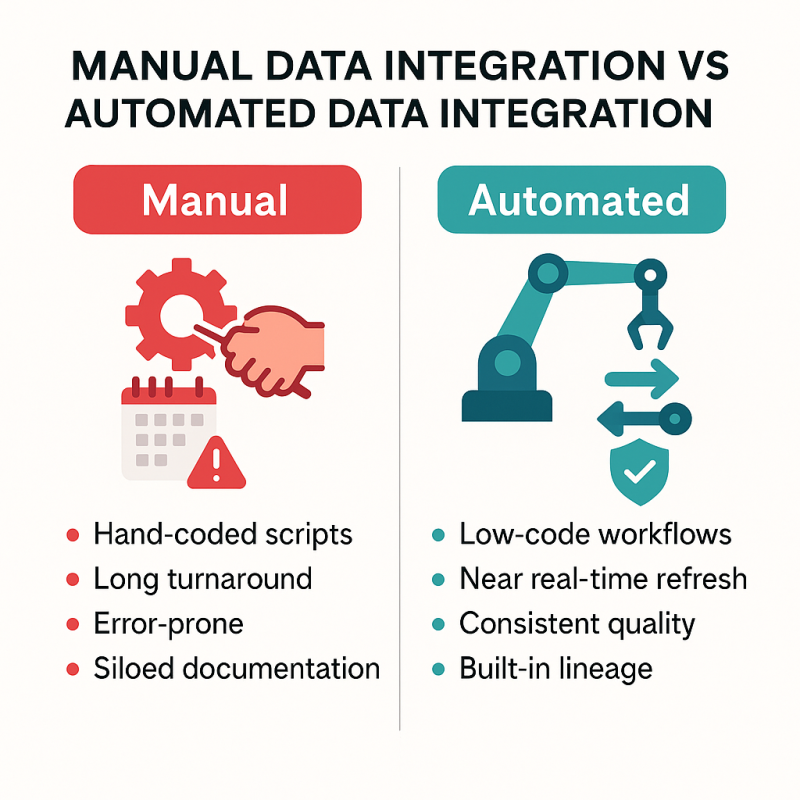
Three years ago I was spending roughly forty hours a month just moving data between systems that refused to talk to each other. MySQL to Salesforce, then Salesforce to a local PostgreSQL instance, then some messy exports that required manual CSV reconciliation. It was grinding work. I had scripts that broke every time an API changed. I had cron jobs that silently failed. I had a pile of Jira tickets that nobody wanted to close. Then I started looking at Mangalot. The platform markets itself around unified data integration and automation, which is about as generic as it gets, but the actual mechanics turned out to be decent enough that I stopped writing custom scripts for routine pipelines. It handles connection orchestration, transformation logic, and scheduling in a single workspace. That alone saves me probably twelve to fifteen hours a month on maintenance.
The Rise Of Mangalot Revolutionizing Data Integration And Automation
Here is how it actually works when you use it for something real rather than reading the marketing copy. You start by creating a connection object, which is just a saved set of credentials and endpoint configuration. Mangalot supports native connectors for most mainstream databases, REST APIs, SaaS platforms like HubSpot and Snowflake, and flat files. I mainly use the Postgres and BigQuery connectors. The setup takes about five minutes per source once you have the right tokens or certificates handy. After connections are established, you build workflows. A workflow is basically a directed graph of steps: extract, transform, load, with optional branching logic and error handling. The transformation layer uses a visual editor that compiles into executable SQL or Python code depending on what you configure. This is where people get confused. The visual editor is fine for simple mapping, but as soon as you need conditional logic or complex joins, you will want to switch to raw SQL mode. The platform does not force you to choose one permanently. You can switch mid-workflow. I built a pipeline that pulls user event data from a REST API every six hours, enriches it against a customer table in BigQuery, and writes the result back to a PostgreSQL reporting database. The total execution time for about 1.2 million rows is roughly eight minutes. Before Mangalot, the same pipeline required three separate scripts, a bash orchestrator, and constant debugging when one of the endpoints throttled me. Now it runs and I check the dashboard.
There is a scheduling engine built in, so you do not need Airflow unless you are running something massive. For anything under five hundred concurrent workflows, the native scheduler is adequate. It supports timezone-aware cron syntax, retry logic with exponential backoff, and dependency tracking between workflows. I set mine up with a three-retry fallback, and it has never needed to fail over. That alone is worth the subscription cost. One thing beginners get wrong is the transformation step. The platform encourages a no-code approach at first, but I strongly recommend writing your transformations as SQL views stored in the target database rather than doing them inside the workflow. The reason is performance and traceability. In-workflow transformations get opaque fast, especially when something breaks at scale. SQL views are visible in the database, version controllable, and queryable independently. I learned this the hard way after a mid-January incident where a nested mapping expression silently dropped ten percent of records. No error was thrown. The dashboard just showed green checks while the downstream report was missing half the data. Finding the issue took three hours of log diving. After that I switched all nontrivial transformations to explicit SQL. Error handling deserves a bit more attention because it is where most people hit trouble. Mangalot lets you set global and per-workflow error policies. You can choose to stop on first failure, skip the failed row, or route failures to a quarantine table. The quarantine feature is genuinely useful. It writes failed records to a separate destination so you can inspect them later without breaking the main flow. I route API timeout failures to quarantine and set up an alert that fires only when the quarantine table exceeds fifty rows in a single batch. This keeps the noise down and surfaces actual problems faster.
Get the Full Details
Let me mention a specific edge case I ran into that the documentation did not cover well. I was pulling data from a Stripe webhook endpoint that returns paginated results with cursor-based pagination. The default connector loop only handled the first page and then marked the workflow complete. I had to write a custom JavaScript step that iterated through the cursor, accumulated results, and passed the final payload to the transformation stage. It worked, but it required me to disable the built-in pagination handler and handle it manually. The workaround was straightforward once I figured out the right sequence, but it cost me a full afternoon. If you are working with paginated APIs, test the pagination behavior before you deploy anything to production. Security is another area where the platform is competent but not perfect. Connection credentials are stored encrypted at rest and passed through a secrets manager in the cloud tier. On-premise deployments offer additional options for key rotation. I run the cloud version and have not had a security incident, but I do rotate my API keys every ninety days as a habit. The platform supports automatic key injection into workflows, which helps. The one gap is that audit logs are only retained for ninety days on the standard plan. If you need longer retention for compliance, you have to export them yourself or upgrade. Cost structure is straightforward. There is a free tier that allows up to fifty workflow executions per day and three active connections. That is useful for testing but not enough for any real operation. The paid tiers scale based on workflow count and execution volume. I am on the professional plan at roughly three hundred dollars a month, which covers about two thousand executions daily with full error handling and a year of log retention. It is not cheap, but it is cheaper than the engineering time I was spending before.
Here are the actual pitfalls I would warn people about before they start. First, the visual workflow designer does not show you the generated code in real time. You only see the compiled output when you run or export. This means bugs can hide until execution. Second, version control is clunky. The platform has basic save points but no git integration, so tracking changes across a team is messy. I keep my workflows in a shared folder with date-stamped names, which is primitive but functional. Third, documentation for advanced features is sparse. You will often need to rely on community forums or support tickets for things like custom authentication flows or multi-tenant configurations. If you need something lighter, there are alternatives. Talend Open Studio handles basic ETL well and is free. Apache NiFi is powerful and open source but has a steep learning curve. For teams already invested in the GCP or AWS ecosystem, native tools like Cloud Dataflow or Glue may make more sense. Mangalot sits in a middle ground: more polished than open source options, cheaper than enterprise platforms like Informatica or SnapLogic. It is a reasonable choice if you want a managed integration layer without building everything from scratch. The download link is available on the official Mangalot website under the products section. The cloud version is a web application, so there is nothing to install unless you are running the self-hosted variant, which requires a Linux server with at least four cores and eight gigabytes of RAM. The installer is a Docker compose setup that deploys in about ten minutes if your Docker environment is already configured.
I stopped maintaining my custom scripts about six months ago. The migration took roughly two weeks. Most of that time was spent rewriting transformation logic into SQL views and testing edge cases with bad data. After that, things have been quiet. The platform handles routine failures gracefully, and I spend maybe thirty minutes a week reviewing logs instead of four hours a week writing and debugging pipelines. That is the actual value proposition here.