Setting Up Autonomous Systems for Business Operations
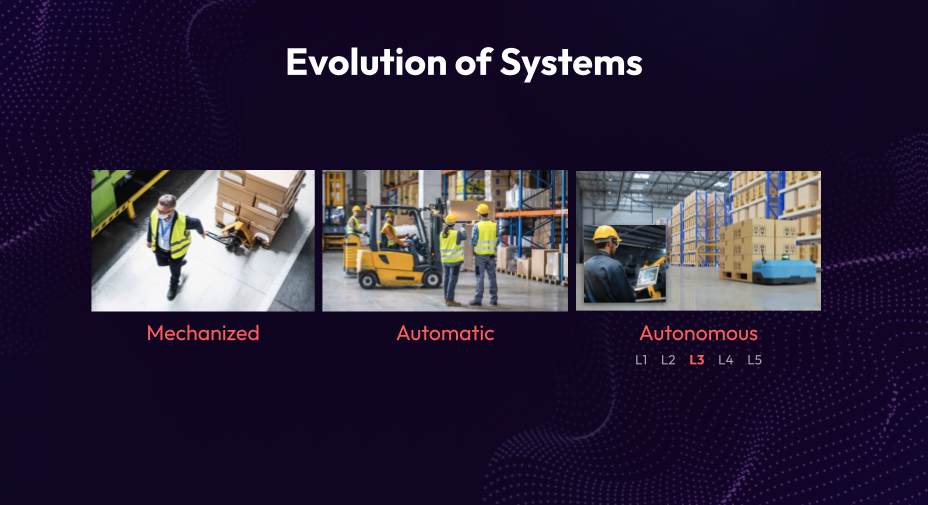
I got dragged into a project about three years ago where a mid-size logistics company wanted to replace their manual dispatch process with something autonomous. They had a spreadsheet with 847 routes, drivers showing up sick, weather delays compounding throughout the day. The idea was simple: let an agent-based system handle reassignment in real time. What actually happened was uglier than anyone predicted, and I think that's worth documenting before you go building your own. The core concept here isn't particularly complicated, but the implementation landscape is full of traps that nobody talks about until they hit one. Autonomous systems in business generally fall into three buckets: rule-based automation (the old guard, things like if-this-then-that triggers), model-driven agents (things that use prediction or optimization algorithms to make decisions), and fully autonomous agents (systems that observe, decide, and act without human approval). Most companies claiming they have autonomous systems actually have the first category dressed up in expensive software. Rule-based systems handle maybe sixty percent of what a business thinks it needs automated. The problem shows up at the sixty-one percent mark. That's where variability enters — things like a supplier changing delivery windows unexpectedly, or a key employee leaving and taking institutional knowledge with them. Rule-based systems freeze here. They need a human to reconfigure the logic. Model-driven agents handle this better because they're trained on distributions of outcomes rather than fixed conditions. But they introduce a different class of failure: they can look confident while being wrong.
I worked through a case where a demand-forecasting agent kept overcommitting warehouse capacity because it had been trained on pre-pandemic data that included seasonal spikes the model never properly internalized. It made reasonable decisions based on imperfect priors. The system wasn't broken. The data was. You'd catch this much faster if you tracked the confidence intervals on every autonomous decision, not just the final output. Most teams don't do this. They monitor whether the system is running, not whether the system is right.
How to Actually Evaluate What You Need
Start by mapping your decision surface. Not your processes — your decisions. Write down every choice that gets made in the workflow you want to automate. Who makes them? What information do they use? How often do they change their minds after making one? This last question is the one that kills most projects. If the answer is frequently, you need a system that can revise, not just execute. I mapped a procurement team's decision surface once. Ninety percent of their choices were low-stakes reorder triggers that could absolutely be rule-based. Ten percent were supplier negotiations involving relationship history, spot-market pricing, and qualitative factors like whether a vendor's account manager had recently become unreliable. The ten percent was where the budget kept getting allocated because leadership wanted something "smart." We ended up automating the nine-point-o and leaving the rest manual with a decision-support dashboard instead. It saved more money and caused fewer problems than the fully autonomous approach ever would have.
Get the Full Details

Architecture Choices That Matter
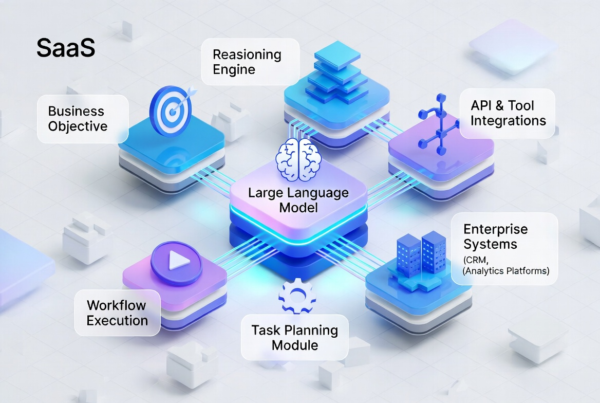
If you're going beyond simple automation, you'll need to think about how your autonomous components communicate and who gets final authority. The architecture I recommend for most business contexts is a hybrid loop: autonomous agents propose actions, a human-in-the-loop layer validates against a constraint set, and the system logs everything for audit and retraining. The constraint set is the part everyone underestimates. It's not enough to say "don't overspend." You need hard boundaries — budget caps per category, approval thresholds by dollar amount, time-of-day restrictions, geofenced operational limits. Without these, the system will find the edge cases you didn't think of and exploit them. For the logistics project I mentioned earlier, we ended up building a constraint engine that sat between the routing agent and the execution layer. It intercepted any route change that would increase driver overtime by more than fifteen percent and flagged it. The agent learned to respect that boundary within two weeks of deployment. The human reviewers only saw about four percent of proposed changes after that. The system was doing the heavy lifting, but the constraints kept it from drifting into unacceptable territory.
Common Pitfalls and What to Do Instead
The biggest mistake I see is treating autonomous systems as a replacement rather than a distribution shift. You're not removing work. You're moving it. The work that was previously done by people doing manual overrides becomes work done by engineers maintaining the system, monitoring its edge cases, and retraining it when the world changes. Budget for that ongoing cost. Plan for it before you launch. Companies that don't usually find out the hard way when their autonomous dispatch system starts making decisions that look correct but cost them three hundred thousand dollars in expedited shipping over a six-week period. Another pitfall is evaluation methodology. Most teams evaluate autonomous systems by looking at aggregate performance metrics. This hides degradation in specific sub-categories. If your system handles routine orders well but consistently fails on international shipments, your overall accuracy might look fine at eighty-nine percent while your international division quietly loses money every month. Segment your evaluation by business unit, region, product category, and customer tier. Monitor each separately. There's also the issue of feedback loops. Autonomous systems that interact with the same environment they help shape will eventually change that environment. A dynamic pricing agent that lowers prices to boost volume will push competitors to lower their prices too. Eventually everyone has lower prices and the agent is optimizing against a landscape it helped create. This isn't necessarily bad — it might be exactly what you want — but you need to be aware that your system is no longer reacting to external conditions. It's co-evolving with them. Track this. Simple regression analysis on your key metrics over time will show you when the environment starts shifting in response to your system's actions.
Practical Steps to Get Started
Pick one process. Just one. Make sure it has clear inputs, measurable outputs, and a current human operator you can interview about edge cases. Build a rule-based version first. Deploy it. Watch what it misses. Those misses are your model-driven agent specifications. Don't skip ahead to the fancy stuff. The rule-based version will teach you more about your process than any consultant's framework. Document everything from day one. Decision logs, constraint definitions, failure modes you observe, false positives and false negatives categorized by type. This documentation becomes your retraining dataset when the system starts drifting. Without it, you're guessing. With it, you're engineering. The tools available today make this approachable for small teams. There are agent orchestration platforms, constraint management systems, and monitoring frameworks that don't require a twenty-person engineering department. What they don't replace is the domain knowledge needed to define the right problems and constraints. That still comes from people who understand the business. The autonomous system is the engine. You still need to know where the car is supposed to go.