
So You Want To Deploy Intelligent Traffic Cameras
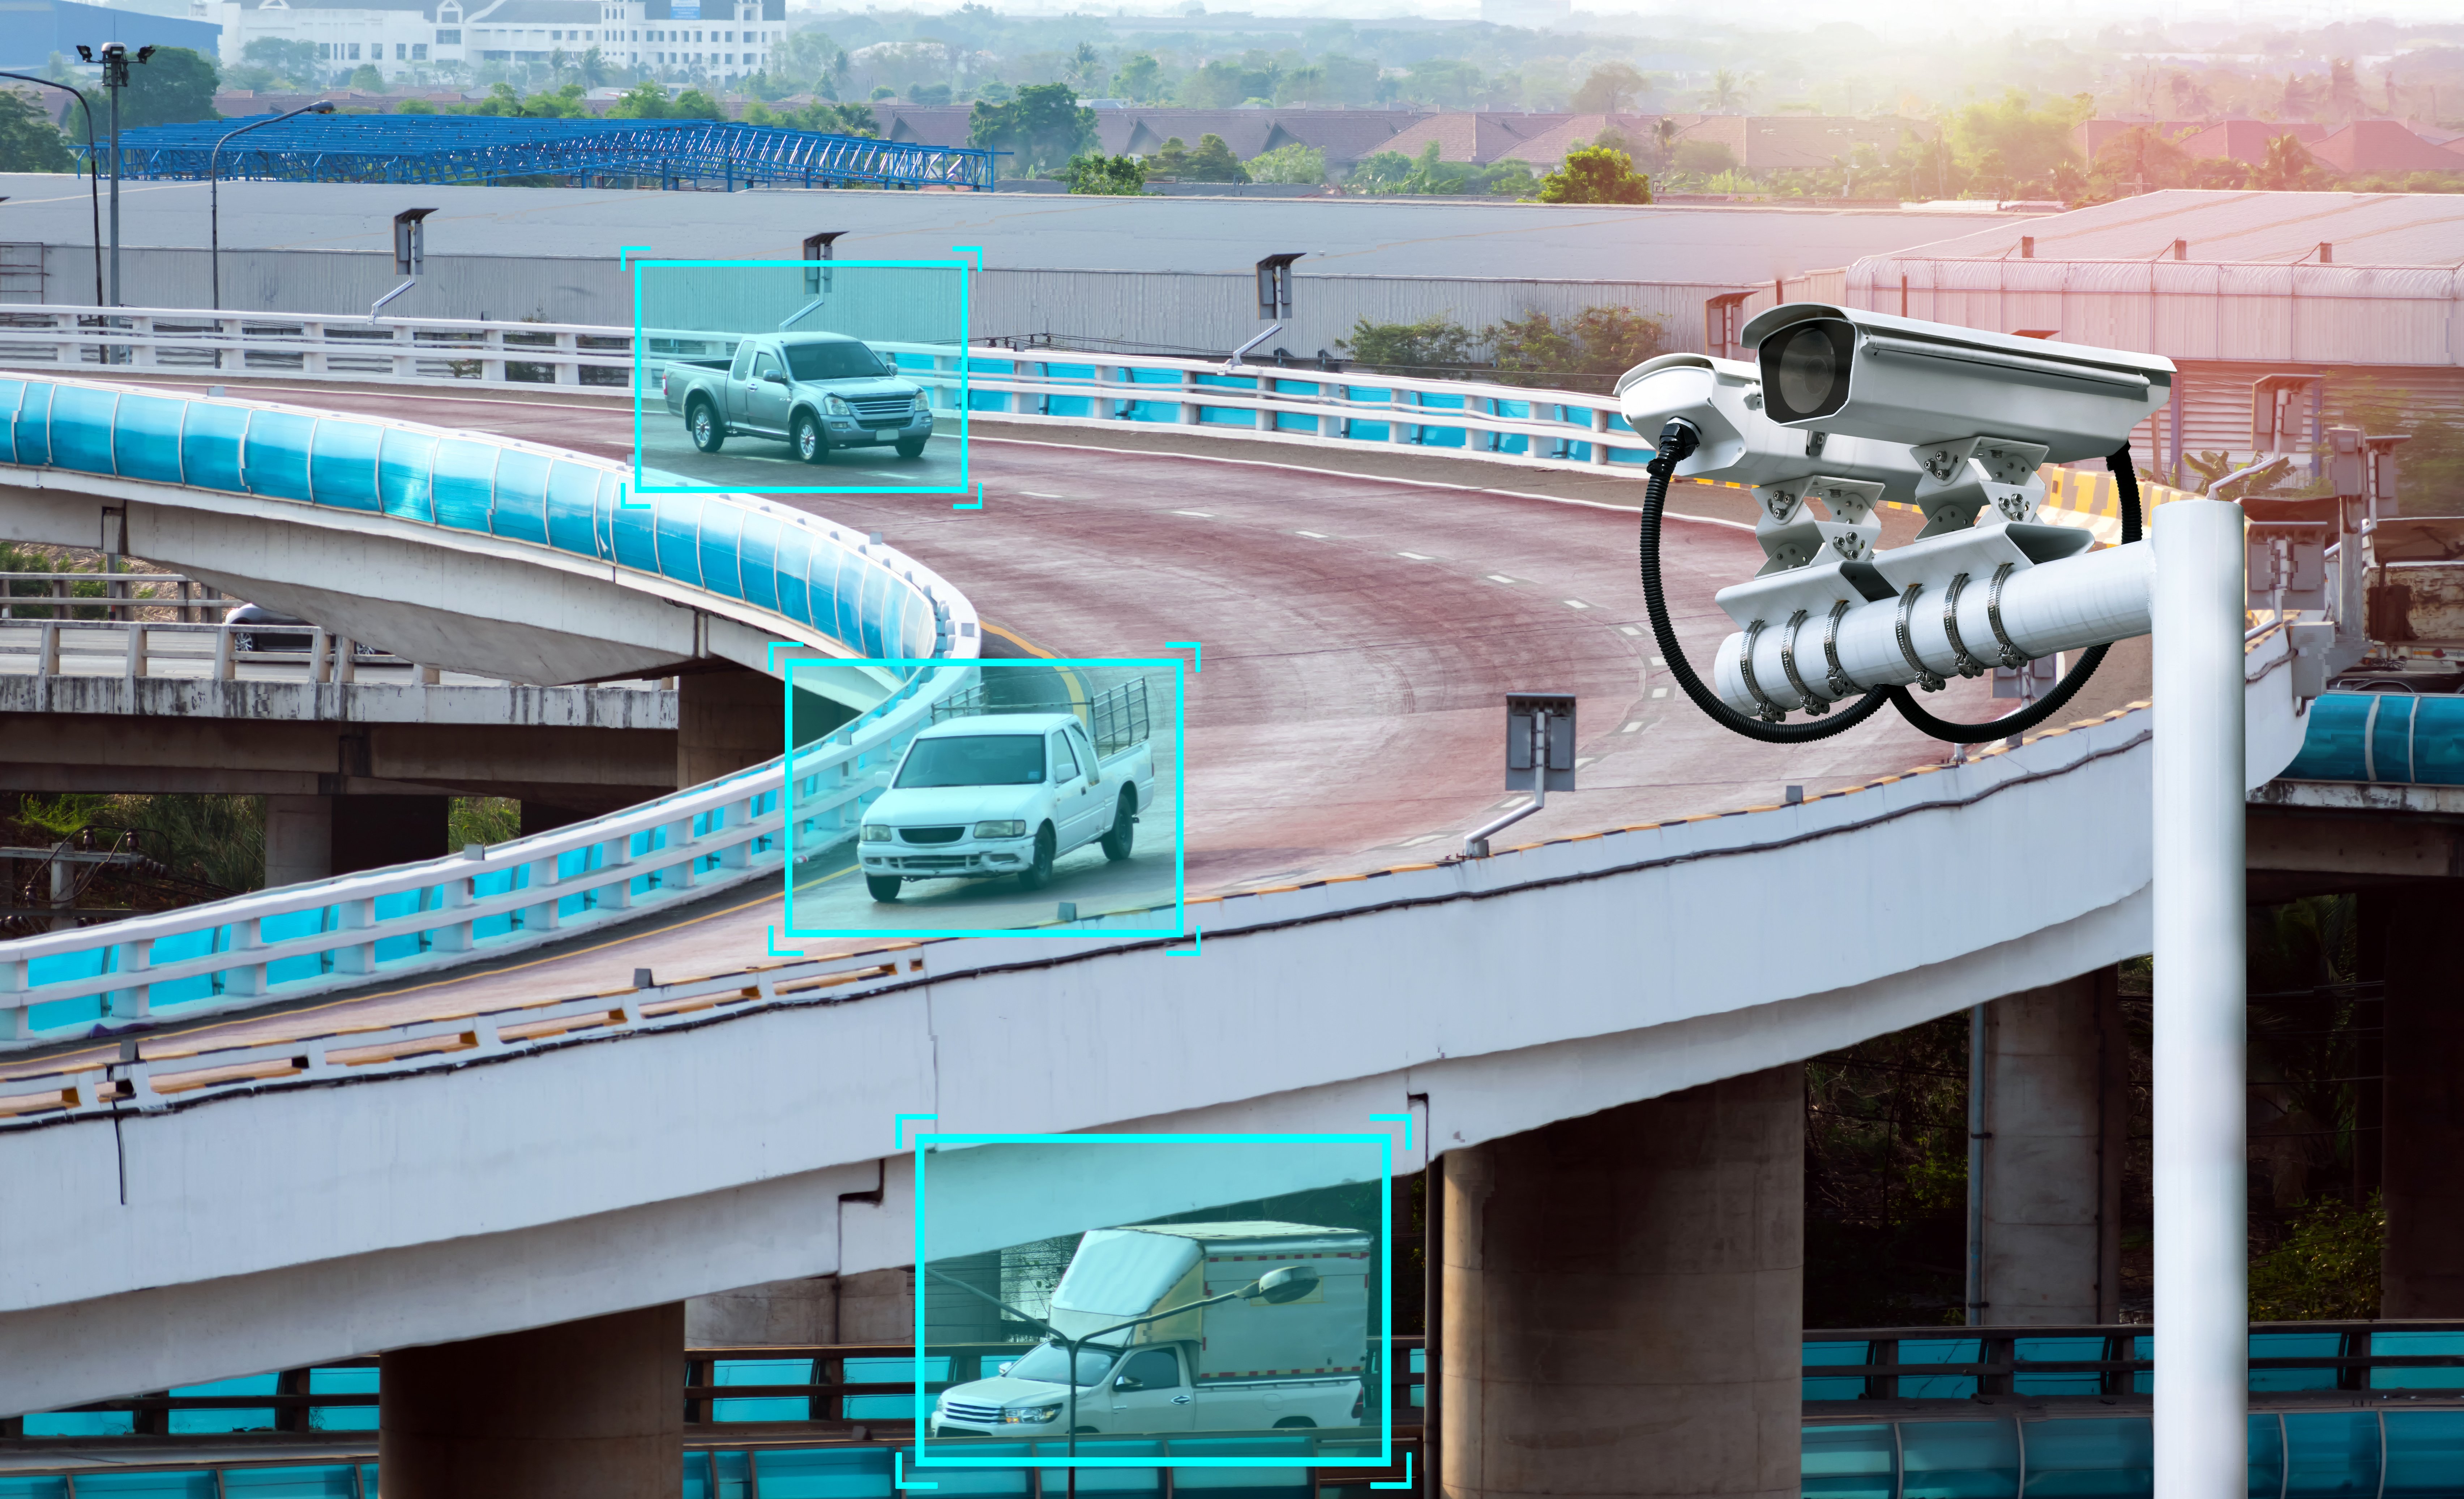
I spent three years running a traffic management pilot in a mid-sized city before we finally wrapped it up. We ended up with forty-eight intersections covered, a mixed fleet of cameras, and enough bandwidth headaches to fill a small textbook. The short version is this works, but it does not work the way you would expect if you have never looked at one of these systems from the inside. At its core, an intelligent traffic camera system combines a camera feed with some kind of detection and control layer. You get video, models run on that video to figure out what is happening, and then something else acts on that information. That something else could be a signal controller, a cloud platform, a text alert, or nothing at all depending on how you set it up. The hardware side is usually less interesting than people think. Modern PTZ cameras from vendors like Axis, Hanwha, or Pelco sit on the pole, they talk to a junction box or NVR, and a local edge device or server does the heavy lifting. The edge device runs whatever model you decide to ship out. Some systems do everything on the camera itself. Some push raw video to a data center. Most fall somewhere in the middle where you send compressed streams to an inferencing box near the intersection.
I learned the hard way that camera placement matters way more than the detection algorithm. We spent six weeks tuning YOLO variants for a queue detection model before a traffic engineer told us the problem was our mounting height. The camera was at six meters pointing down at a forty-five degree angle. We were trying to detect vehicles in the second lane and the lens distortion made bounding boxes jump around like they were on caffeine. We dropped it to four meters, changed the angle to roughly twenty degrees from vertical, and the false positive rate fell by almost eighty percent. No model upgrade required.
How These Systems Actually Work In Practice
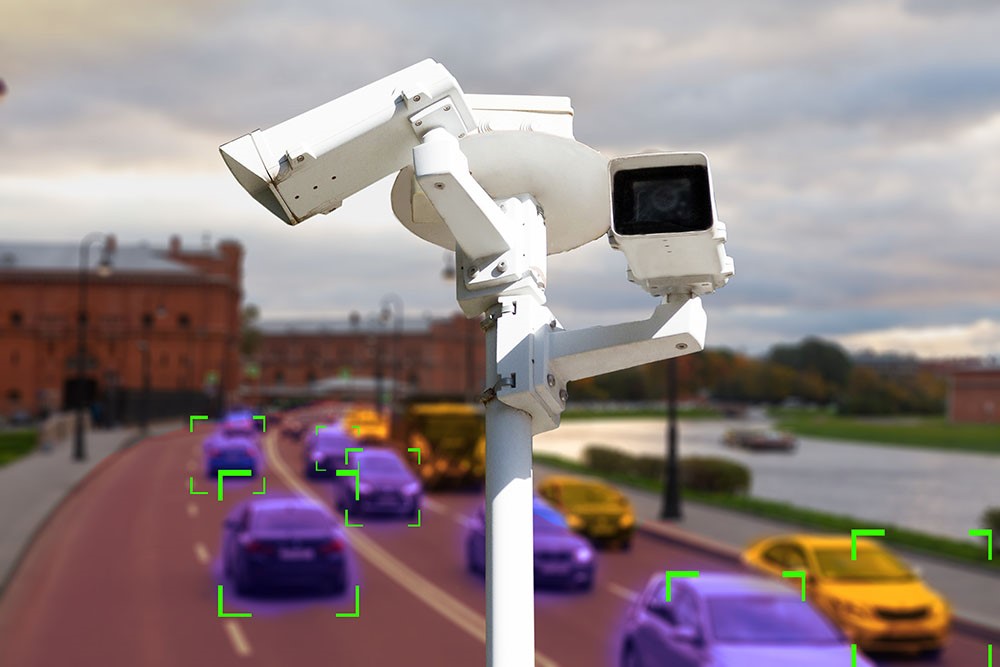
Here is the pipeline most operators deal with on a daily basis. First, you ingest the video stream. RTSP is still the default even though it is painful. You pull that stream, usually decode it with something like GStreamer or FFmpeg, and pass frames to your detection model. If you are doing real-time analysis you are working at maybe ten to fifteen frames per second per camera. Going higher eats GPU time without giving you much in return because traffic does not change that fast. Second, the detection layer runs. Most cities use some variant of object detection to count vehicles, identify types, measure speed, and track queues. Pedestrian and cyclist detection is a separate conversation that requires its own model or at least a different confidence threshold. I keep my pedestrian detector on a separate pipeline because misclassifying a delivery bike as a car throws off the volume count in ways that matter for reporting.
Get the Full Details
Third, you feed results into the control or analytics layer. This is where adaptive signal control comes in. Instead of a fixed timing plan, the system adjusts green time based on actual demand. Some platforms do this locally at the intersection. Some push data to a central server that controls all forty-eight intersections from a dashboard. The central approach gives you better city-wide coordination but introduces a single point of failure if your network goes down. We ran into this exact problem in month four when a fiber cut took out our connection to the operations center. All forty-eight intersections dropped back to flash mode, which is what signal controllers do when they lose communication. Traffic did not collapse because the fallback worked. It was ugly but functional. Still, it made the point clear: your edge intelligence needs to be robust enough to handle offline operation.
The Edge Computing Question
This is where most proposals stall. You can run inference on the cloud, on a local server, or on an edge device at the intersection. Cloud inference introduces latency and bandwidth costs that scale poorly once you go past ten or twelve cameras. A local server sits somewhere between the two. An edge device, like an NVIDIA Jetson Orin or a Minisforum unit running TensorRT, gives you latency under two hundred milliseconds per frame and keeps costs predictable. I recommend edge inference for anything beyond a proof of concept. You should plan on one edge unit per eight to ten cameras. Each unit handles multiple concurrent streams, runs your models, and sends only metadata upstream. The metadata includes vehicle counts, queue lengths, wait times, violation flags if you have those. Raw video stays local unless you need it for audit purposes. The downside is that edge units require maintenance. They get hot. They need dust cleaning. They occasionally lose power or suffer SD card failures if you are logging locally. We replaced three SD cards in six months because a construction crew turned off the junction box power for a weekend and the filesystem corruption killed two of them. Moving to NVMe solved that problem entirely.
Model Selection And Tuning
You do not need a PhD in computer vision to make this work. Start with a pre-trained model, preferably YOLOv8 or YOLOv10 for detection, and fine-tune it on your own images. Local conditions matter a lot. Rain, snow, glare from low sun, and even the color of nearby building facades can throw off a model trained on someone else's dataset. Here is a practical workflow that takes about two weeks if you have the data ready. Step one is image collection. You need at least five thousand labeled images across different times of day, weather conditions, and seasons. Label them with something like Roboflow or CVAT. Vehicle classification matters here. A bus counts differently than a pickup truck in most traffic planning models.
Step two is training. Use a GPU with at least sixteen gigabytes of VRAM. Train your detection model, then calibrate the confidence threshold. You want recall above ninety percent for vehicle counting. Precision can trade off a bit because missing a vehicle is worse than a false positive in most signal control contexts. A false positive adds a tiny bit of noise. A missed vehicle skews the volume report. Step three is deployment. Export your model to TensorRT or ONNX Runtime. Run it through a profiling script to catch any bottlenecks. Then wrap it in a Docker container so you can redeploy quickly if something breaks. Do not skip Docker. You will thank me later when a model update requires a three AM reboot instead of a panic session. I learned this after a bad experience early on. I installed a new queue detection model directly onto the edge device without containerization. The model had a Python version mismatch with the system libraries. The device refused to boot the pipeline, and we had no way to roll back because there was no snapshot. I spent four hours on a ladder at an intersection with a laptop while traffic backed up three blocks behind me. Containerized deployments solve this if you keep your images clean and tag them properly.
Integration With Signal Controllers
This part is where the technology meets the politics. NTCIP is the standard protocol in North America for talking to traffic signals. Europe uses OEM and SNRC depending on the country. You need to know which one your existing controllers support before you sign any contracts. Most modern controllers accept actuation inputs from external sources. You send a simple actuation packet when the system detects a queued lane that needs more green time. Some controllers let you push full timing plans. Others only accept simple call-and-response signals. Your integration complexity depends entirely on what the controllers allow. We worked with a Siemens controller that only supported basic actuation. The adaptive signal model we built was sophisticated enough to optimize split phases across multiple corridors, but the controller could only accept a green extension request. We had to simplify our logic to fit the hardware constraints. That meant sacrificing some optimization potential in exchange for reliability. Not a bad trade.
If you are deploying in a greenfield environment where you pick both cameras and controllers, try to standardize on NTCIP 1202-compliant equipment. It saves headaches later when you need to add a new intersection or replace a failed controller.
Data Storage And Privacy
Privacy is not optional. Even if your jurisdiction does not require it, storing raw video without a retention policy creates liability. We kept video on loop for seventy-two hours before overwriting. Violation footage, when we had cameras configured for red light or speed enforcement, went to a separate encrypted storage system with access logs. Everything else was metadata only. Metadata includes counts, timestamps, queue lengths, and average speeds. It does not include faces or license plates unless you are running ANPR separately. ANPR requires its own model, its own privacy review, and usually its own legal framework. Do not bolt it onto a general traffic monitoring system and expect it to fly through a privacy audit. I recommend treating ANPR as a separate module from the start. You can share the same edge hardware, but the pipelines, storage, and access controls should be distinct. Mixing them creates compliance gaps that are expensive to fix after deployment.
Cost Estimates
Here is a rough breakdown for a single intersection in a developed-market city, based on what we actually spent. A quality PTZ camera with a good lens runs about two thousand to four thousand dollars. The mounting hardware, conduit, and installation add another fifteen hundred to three thousand depending on how complicated the pole work is. An edge computing unit like a Jetson Orin Nano costs between eight hundred and twelve hundred dollars. Software licensing varies wildly. Some vendors charge per camera per year. Others want a flat fee for the platform. Open-source models are free but require engineering time. A full turnkey system from a major vendor typically lands between twenty-five thousand and fifty thousand dollars per intersection. The DIY route with commodity hardware and self-built software comes in around twelve thousand to eighteen thousand dollars per intersection, assuming you already have the engineering capacity. The difference is mostly labor and support contracts.
We budgeted thirty-five thousand dollars per intersection including a five-year support contract. It was reasonable for what we needed. If you strip out the support contract and use open-source software, you can get it closer to twenty thousand. But you are responsible for keeping it running at that price point.
Common Pitfalls
There are a few mistakes I see repeated across projects. The first is underestimating network requirements. Even compressed metadata at forty-eight intersections with updates every five seconds is not trivial. Plan for at least a dedicated VLAN with redundant links. A single point of failure in your network takes down the entire adaptive control layer. The second is assuming one model fits all conditions. A model trained on suburban intersections with wide lanes performs poorly on narrow urban streets with frequent right turns and parked cars. Test on your actual sites before declaring victory.
The third is ignoring the maintenance backlog. These systems need firmware updates, model retraining when conditions change, and hardware replacements when things fail. Budget eighteen to twenty-four months of engineering time for a forty-eight intersection deployment if you want it to stay functional.
When These Systems Fail Completely
I want to be honest about the failure modes. Extreme weather degrades accuracy. Heavy snow covers lane markings and changes vehicle profiles. Dense fog reduces detection range significantly. Our pedestrian detection dropped below sixty percent recall during a particularly bad ice storm because the camera lens was coated with a thin layer of ice that we had not anticipated. Adding heated lens covers fixed it, but we should have included them from the start. Power instability is another silent killer. Voltage fluctuations at older intersections cause edge devices to crash or corrupt storage. We added an uninterruptible power supply to every junction box that contained an edge unit. Cost about four hundred dollars each. Saved us from multiple overnight outages where we woke up to forty-eight silent intersections.
If you are operating in a region with frequent power issues or extreme weather, budget for hardened hardware and redundancy. Cheaper gear fails faster and creates more work than it saves.
Alternatives To Consider
Not every traffic problem needs cameras. Inductive loop detectors are cheaper, more reliable in bad weather, and sufficient for simple actuation. If you only need to detect vehicle presence at a stop bar, loops do the job at a fraction of the cost and complexity. Camera-based systems shine when you need richer data: vehicle classification, queue length estimation, turning movement counts, pedestrian detection, or speed measurement. If your goal is just to extend green when a car is waiting, loops are the practical choice. If you need actionable analytics across multiple lanes and modes, cameras are worth the investment. Radars are also an option. They handle weather better than cameras and do not require line of sight. The tradeoff is lower resolution and fewer use cases. A radar can count and classify vehicles reasonably well. It cannot detect pedestrians crossing at an unmarked location the way a camera can. Choose based on what you actually need to measure.
Getting Started
Start small. Deploy one intersection as a pilot. Run it for three months under normal conditions and three months under worst-case conditions. Measure what the system gets wrong. Retrain. Iterate. Only after you have a working feedback loop should you scale to more intersections. Do not buy a hundred cameras before you understand how many edge units you actually need, what your network can handle, and whether your signal controllers can accept the commands you plan to send. The technology has matured enough that most of the risk is in planning, not in execution. Plan poorly and you will pay for it in both money and headaches. Plan well and the system mostly runs itself after the initial commissioning period. Documentation for most of the software stacks is adequate if you read it before deployment instead of after. OpenCV, TensorRT, and GStreamer have solid docs. Vendor-specific NTCIP integration guides are hit or miss. Test those connections on a bench before installing anything on a live intersection.
That is about as much as I have to say about it. Good luck with the project.
