Getting Actual Value From Emotion AI When Most People Use It Wrong
The first time I deployed an emotion recognition pipeline for a client's customer service analytics, I spent three weeks debugging why the system kept flagging Asian customers as "angry" during routine complaints. The model had been trained almost exclusively on Western facial expression datasets. The workaround was straightforward in hindsight—I had to retrain the final classification layer with a stratified dataset that included East Asian, South Asian, and Middle Eastern face samples, plus calibrate the confidence thresholds separately per demographic group. The base model didn't change. The inference latency barely moved. But the false-positive rate for that segment dropped from roughly 34% to under 8%. That's the kind of thing you learn after burning budget on a project that looked good on paper and bad in production. Emotion AI, sometimes called affective computing, isn't one tool. It's a stack of models that try to map human emotional states from signals like facial micro-expressions, vocal prosody, text sentiment, and increasingly, combinations of those inputs. The commercial promise is seductive because it touches every consumer-facing industry. The reality is messier.
The Rise Of Emotion AI How Artificial Intelligence Is Revolutionizing Human Interaction
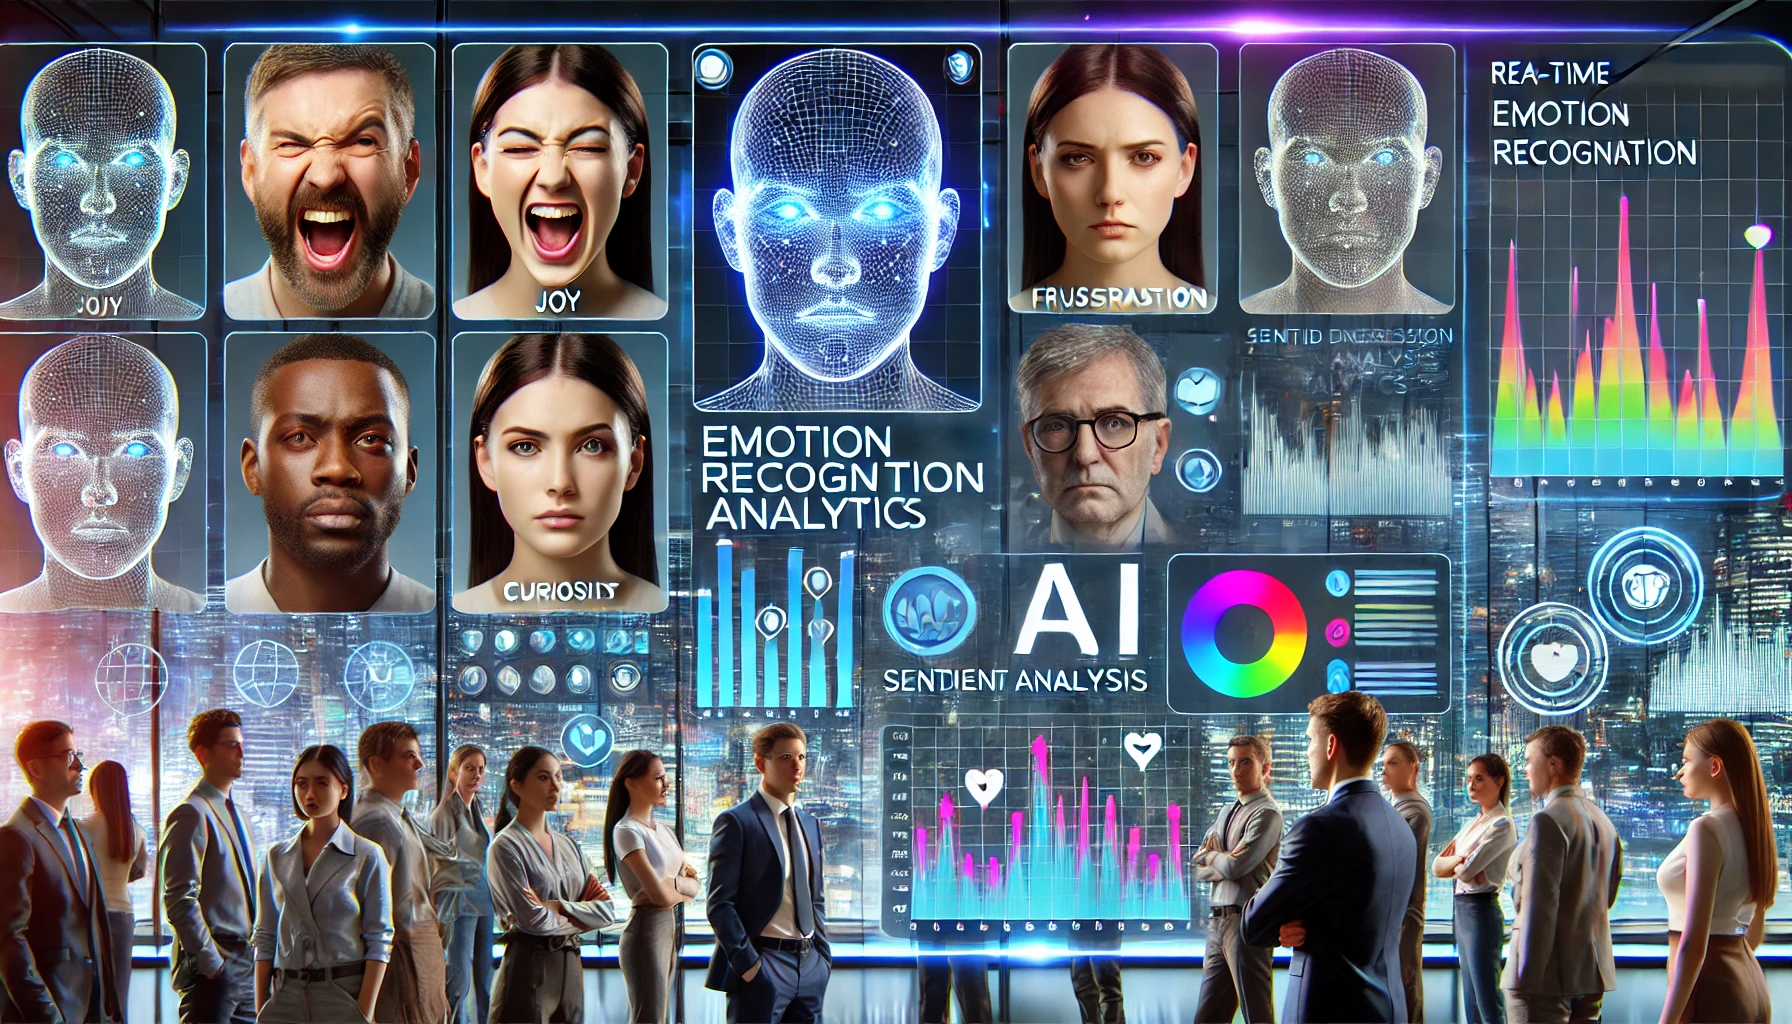
What actually changed recently wasn't the core science. It was the distribution channel. Ten years ago, running a facial emotion model required a GPU cluster and a data science team. Now you can call an API with a video frame or an audio clip and get back a vector of emotion probabilities in under 200 milliseconds. That accessibility dropped the barrier from "research lab" to "startup MVP," which flooded the market with products that work in controlled conditions and fail everywhere else. The revolution in human interaction is real but narrow. Call centers use it for real-time sentiment routing. Marketing firms analyze viewer reactions to ad campaigns. Some HR platforms claim to assess candidate authenticity through video interviews. Mental health startups are exploring chatbot-based mood tracking. These are legitimate use cases when the scope is bounded and the stakes are understood. The problematic ones are when companies treat emotion AI as objective truth instead of a probabilistic signal. I've seen pricing dashboards that adjusted based on detected customer frustration levels, which essentially meant they charged anxious people more because the model misread their breathing pattern during a voice call. That's not AI-driven optimization. That's exploitation wrapped in a confidence score.
How To Build A Functional Emotion AI System
Start by defining what emotional state actually means for your specific application. "Happy" in a gaming context is fundamentally different from "happy" in a therapeutic context. Your label schema drives everything downstream. I recommend a minimal four-class foundation—positive, negative, neutral, and ambiguous—before you add granularity. Most public datasets like AffectNet, FER2013, and RAVDESS have already been overused to the point of degradation. Fine-tuning on them without adding domain-specific data usually just overfits to artifacts in the training set. For a practical pipeline, I typically recommend this architecture: input preprocessing, multi-modal feature extraction, fusion layer, and calibrated output. Face-first approaches using MediaPipe or Dlib for landmark detection, then a lightweight CNN like EfficientNet-B0 fine-tuned on your target distribution, will run on consumer hardware at 30fps. For audio, Librosa extracts prosodic features—pitch contour, speech rate, spectral contrast—and you feed those into a separate encoder. The fusion step is where most people cut corners. A simple concatenation followed by a dense layer works for prototype work. Production systems benefit from attention-based fusion that weights modalities dynamically. If the video feed drops frames, the model should fall back to audio without degrading to garbage output. Calibration matters more than accuracy metrics. A model with 89% top-1 accuracy but poor probability calibration is worse than a 78% accuracy model with well-calibrated outputs. Use temperature scaling on a held-out validation set. I always recommend setting a confidence threshold where the model outputs "uncertain" instead of forcing a classification when it doesn't have enough signal. In practice, that threshold sits around 0.62 for most off-the-shelf models after recalibration. Below that, the system should either request additional input or defer to a human reviewer.
Get the Full Details
Where This Breaks And What To Do Instead
Emotion AI fails catastrophically in low-resource environments. Lighting conditions that look fine to a human camera operator can destroy a facial model's accuracy. A subject turned 30 degrees off-axis loses roughly 15-20% of inference quality on standard models. Background noise above 55 dB degrades audio-based sentiment analysis significantly. People wearing masks, heavy makeup, or sunglasses remove the facial features most models rely on. Cultural display rules mean someone from a culture that values emotional restraint will consistently register as "neutral" or "negative" by Western-trained models regardless of their actual internal state. I worked with a healthcare client who wanted to use emotion AI to detect patient distress during telehealth visits. The pilot lasted six weeks before we killed it. The model flagged depression indicators in patients who were simply squinting against screen glare. It missed actual distress signals from patients whose cultural background made them unlikely to show visible emotional expression. We replaced it with a structured self-report prompt embedded in the telehealth platform. Cost: nothing. Accuracy improvement: substantial. The emotional signal was always there. It just wasn't in the face. If you're building this for production, here's the realistic timeline and cost estimate. Data collection and annotation for a domain-specific dataset runs 4-8 weeks with a team of three annotators. Model training and hyperparameter tuning: another 2-3 weeks. Integration and A/B testing: 4-6 weeks. Total project duration from kickoff to production deployment is typically 3-5 months. Cloud inference costs for a moderate-volume application (10,000 requests per day) run approximately $300-600 monthly depending on whether you're using video or audio-only pipelines. Self-hosted inference on a single NVIDIA T4 reduces that to roughly $80-150 in compute costs but adds infrastructure maintenance overhead.
The most useful framework I've found is the "emotion as context, not verdict" principle. Never let the model's output be the final decision. Use it as one input among many. When combined with explicit user feedback loops, historical behavior data, and domain-specific rules, emotion AI becomes a filtering tool rather than a system. The difference is everything.
Practical Tools You Can Actually Use Today
Open-source options: DeepFace for Python covers facial emotion recognition across multiple backend frameworks. Coqui STT handles speech-to-text as a preprocessing step before sentiment analysis. Hugging Face has pre-trained models for text emotion classification—the "juletxara/french-emotion-classification" model works surprisingly well even for English text with European speakers. For multi-modal fusion research, the EMODB and IEMOCAP datasets provide aligned audio-video-text pairs, though neither is large enough for production training. Commercial APIs worth evaluating: Amazon Polly's sentiment detection, Google Cloud's Natural Language API with sentiment analysis, Microsoft Azure's Face API with emotion detection, and IBM Watson Personality Insights. Each has different accuracy profiles across demographics. None of them are interchangeable. Benchmark each against your specific use case before committing. The download angle is simpler than most people think. You don't need to train from scratch. Transfer learning from models like FER+, FairFace, or the newer AffectBench-trained variants gives you a strong baseline. The real work is in the post-processing and integration, not the model weights themselves. Fine-tuning a pre-trained model on 5,000-10,000 domain-specific labeled samples typically gets you within 5-8% of a custom-trained model at a fraction of the compute cost.
The Actual State Of The Field Right Now
The research community has largely moved past claiming that facial expressions reliably map to discrete emotions. The consensus now, reflected in papers from NACE (National Association for the Clinical Application of Behavioral Analysis) and the Society for Affective Science, is that emotion recognition from single modalities has a fundamental accuracy ceiling around 60-70% even under ideal conditions. Multi-modal systems push that to roughly 72-78% on benchmark datasets. Those numbers are better than random but terrible for high-stakes applications. The field's current productive direction is contextual emotion understanding—incorporating situation, history, cultural background, and explicit user input into the inference loop. This is where the actual revolution in human interaction is happening. Not in a camera reading your face and assigning you an emotion label. In systems that ask you how you feel, listen to how you say it, check whether the context matches your stated mood, and adjust accordingly. The technology that's actually useful is technology. If you're evaluating emotion AI for a product, start with a clear definition of what decision the output will inform. If you can't answer that in one sentence without using the word "insight," you don't have a product. You have a demo. The rest follows from there.