What Caption Booru Actually Is
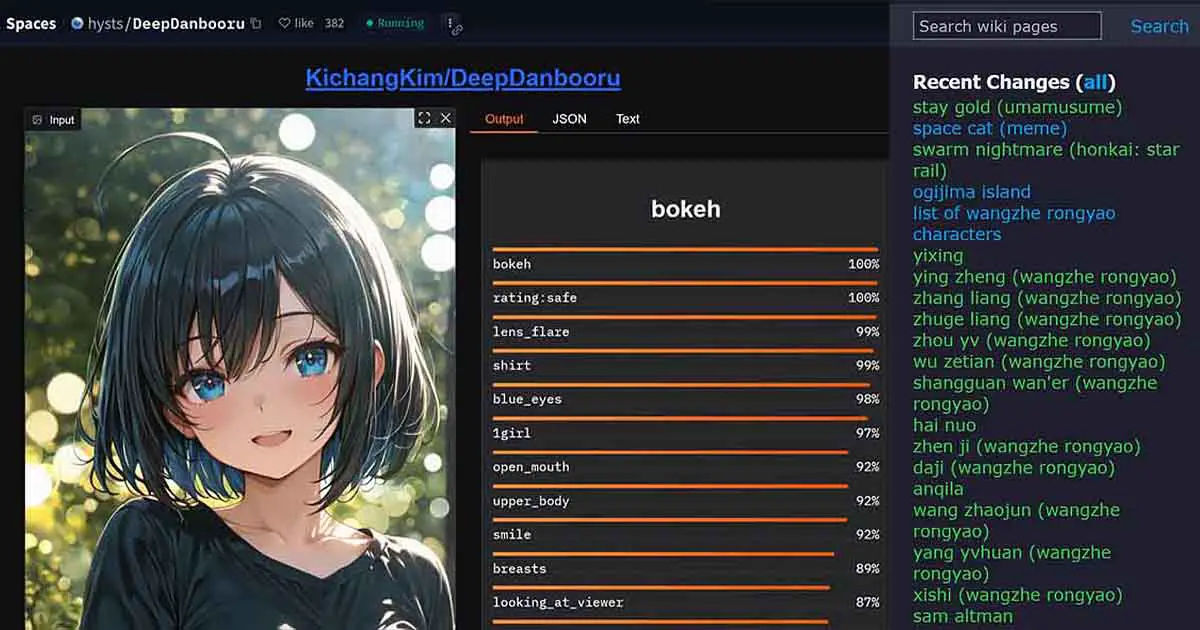
A Caption Booru is a hybrid between the traditional booru-style imageboard (think Danbooru, Gelbooru, Safbooru) and an automated tagging system that uses machine learning models to generate captions instead of relying solely on human taggers. The core idea is straightforward: you upload or browse an image, the system runs it through a classifier like WD-1.0 Tagger, DeepDanbooru, or more recently models based on SDXL architectures, and it spits back a block of tags or a prose caption that describes what's in the image. Then you can search by those tags the same way you would on any regular booru. Here's the thing most guides gloss over. The automation doesn't replace human curation entirely — it sits alongside it. On the major caption-enabled boards, you'll see three layers of metadata: tags added by humans, tags auto-generated by the ML model, and sometimes a raw caption string from a model like WD or BLIP. The search works across all of them, which means your queries become significantly more flexible. You can search for "blue eyes" and the system catches both manual taggers who wrote that and the model that inferred it. I ran a caption booru instance for roughly two years, mostly for personal use and a small community. The first thing I learned is that model choice matters far more than you'd expect. WD-1.0 Tagger v2 is decent for anime-style imagery but it wildly over-tags on photorealistic content. It'll give you 40+ tags on a photo that genuinely has maybe six relevant ones. If your board serves mixed content, you end up drowning users in noise. I switched to a weighted combination — WD for the general tags, then DeepDanbooru specifically for character and franchise metadata — and the signal-to-noise ratio improved dramatically. Not perfectly, but enough.
How The Tagging Pipeline Actually Works
The typical flow is: image comes in it gets resized or kept at original resolution depending on your config the classifier runs top-scoring tags above a threshold get applied the caption string gets generated and stored. The threshold is the critical knob. Set it too high (0.5 or above) and you miss subtle but accurate tags. Set it too low (0.15) and you get garbage like "looking_at_viewer" on every single image because the model is paranoid about faces. I settled on 0.35 as a default for WD and 0.40 for DeepDanbooru, with some tag general rules that override the raw scores — like demoting generic mood tags and boosting character-specific tags when a match is found. This is where the real work happens. Out of the box, the system will happily tag everything, but a well-configured tag filter is what separates a usable board from a spammy mess.
Setting It Up — The Practical Side
If you're spinning up your own instance, the common software stacks are moei-gelbooru, e621v4 with custom plugins, or the Danbooru source with a tagging extension like the WD Tagger plugin. Most people go with a pre-packaged solution like YiffBoard or a self-hosted Gelbooru variant because building from scratch takes a non-trivial amount of time. The hardware requirement is roughly a GPU with 8GB VRAM minimum if you want reasonable throughput. A single RTX 3060 can handle maybe 30-50 images per minute through the tagging pipeline at default settings. Scale that up and you're looking at multi-GPU or CPU fallback, which slows things considerably. Storage is another consideration nobody talks about until it bites them. A well-captioned booru with 100k images and full-resolution thumbnails plus original uploads easily eats 2-3 terabytes. The tag index itself is surprisingly small — maybe 5-10GB for a large board — but the images add up fast. I learned this the hard way when my VPS disk filled up mid-import and I lost about 4,000 recently tagged images because I hadn't configured proper backup snapshots.
Get the Full Details

Search Behavior And What Changes
With captions in play, the search experience shifts. On a traditional booru, you're limited to exact tag matches unless the instance has a fuzzy search plugin. With auto-captions, you can do natural-language queries and the backend maps them to tag space. Some implementations use embedding-based retrieval on top of the tag index, which is noticeably better for vague queries like "girl sitting in grass at sunset" — the system pulls relevant results even when no single tag on the image exactly matches that description. The catch is that embedding search adds latency. A pure tag query returns in 20-50ms on a healthy setup. An embedding-based caption search can take 200-500ms depending on index size and whether you're using a local vector store or hitting an API. If your board gets significant traffic, this compounds quickly. I ran into this on my own instance and ended up hybridizing — tag queries go the fast path, caption/natural language queries hit the slower embedding layer only when the tag query returns fewer than a threshold number of results. It's a small optimization but it keeps the board responsive under load.
Where This Actually Fails
Let me be blunt about the limitations because most promotional material won't tell you. Automated captioning introduces systematic biases that human taggers don't. Models trained primarily on anime and illustration datasets will consistently misclassify real human photography, struggle with non-Western art styles, and produce hallucinated tags — things that aren't in the image at all. I've seen "chain necklace" appear on images where the character is clearly wearing a pendant, and "short_hair" tagged on a character with a visible ponytail because the model conflated the concepts. Another hard limit: copyrighted or obscure characters. The models have decent coverage for major franchises but will confidently tag something wrong when the training data is thin. I once spent an hour debugging why a specific indie game character was being tagged as three different established franchises. The model was guessing, and the guesses were wrong in consistent, believable ways. No amount of threshold tweaking fixed it — the only real solution was manual override or a curated character reference dataset. NSFW content classification is also an area where current models underperform relative to expectations. They tend to be either too conservative or too permissive depending on how they were trained, and the variance between models is enormous. If your board serves adult content and relies on automated tagging for classification, you should plan to audit a significant sample regularly. The models will drift, and their accuracy on edge cases degrades over time as new art styles emerge faster than the training data catches up.
A Workflow That Actually Works
Here's what I ended up doing after the trial-and-error phase. New uploads run through the WD tagger at 0.35 threshold by default. Then a second pass runs DeepDanbooru for character and scene metadata. Both tag sets merge, with a conflict resolution rule that prefers the higher-confidence tag. The caption string gets stored separately and only exposed when the user explicitly requests it. Human editors get a dashboard showing the auto-tags with a confidence score, and they can approve, adjust, or reject before the image goes fully public. This cuts the average tagging time per image from roughly 90 seconds (manual) down to about 15 seconds (review and adjust), which is the real value proposition here. The system isn't magic. It's a tool that shifts labor from creation to verification, and that shift matters for the quality of your board. If you treat auto-generated tags as final truth instead of a draft, your search quality will degrade within months as the errors accumulate and compound. But if you build the workflow around human-in-the-loop review, the combination of speed and accuracy is genuinely better than either approach alone. For a working implementation, the most common starting point is the Gelbooru/FurryBooru codebase with the WD-Tagger plugin installed. There are dockerized deployments that package everything together. The configuration files are documented, but the tag filter rules and threshold tuning are where you'll actually spend time. No one publishes good defaults for that because it depends entirely on what your board's content mix looks like. Start conservative, watch the tags coming in, and adjust from there.