What Arcounty data actually is
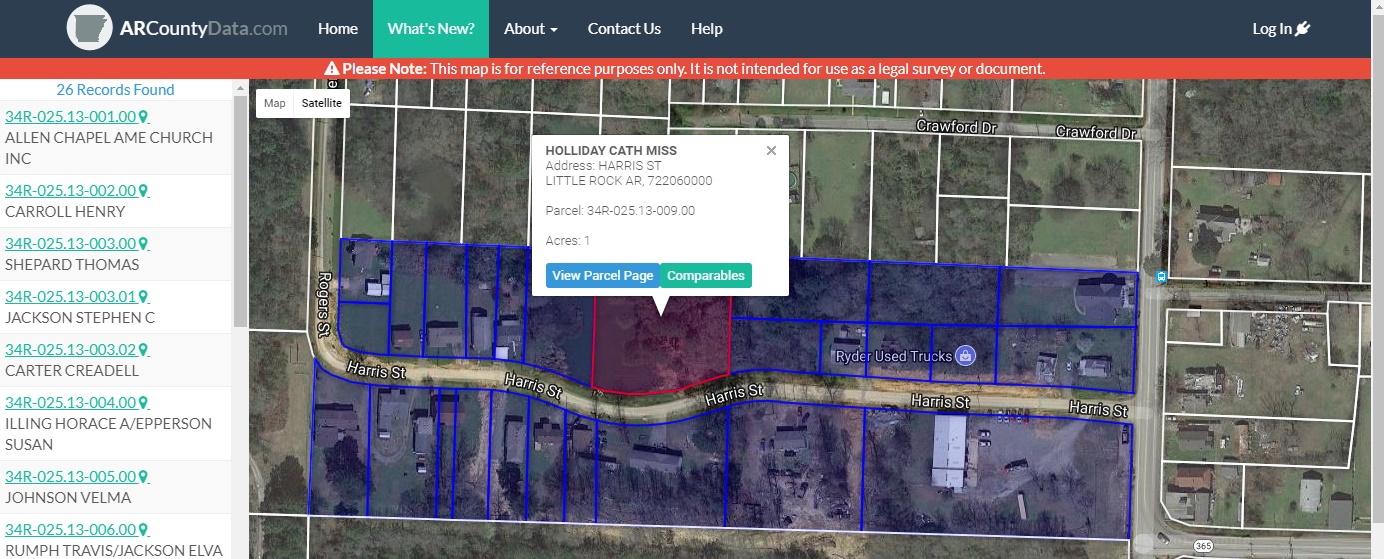
It is not a single product you can download from a vendor portal. Arcounty data refers to the layered geospatial datasets that get compiled at the county level — parcel records, zoning boundaries, utility right-of-way lines, emergency service zones, demographic estimates from the Census ACS releases, transit routes, flood plain maps, and so on. When people talk about the rise of this kind of data, they are talking about a shift that has been happening for about five years where counties have stopped keeping these datasets locked in internal GIS departments and started exposing them through APIs and open data portals. The change was not driven by some grand philosophical commitment to transparency. It was driven by grant requirements. Communities that want CDBG money, hurricane resiliency grants, or federal broadband expansion funding now have to demonstrate data access as part of their applications. Once a few counties figured out that publishing their parcel GIS and zoning shapefiles unlocked millions in federal dollars, every other county started doing the same thing. Now most larger counties have at least a partial data portal, and the smaller ones are catching up because the state agencies that oversee them are pushing for it.
The Rise Of Arcounty Data Unlocking New Insights And Opportunities For Local Governments
The practical effect of this shift is that local governments can now run analyses across multiple dataset layers without waiting for their IT department to spend three weeks extracting and georeferencing files. A planning commissioner can pull parcel ownership records, cross-reference them with zoning designations, overlay a flood risk layer from FEMA, and produce a report in a single afternoon instead of going through the old process of filing a records request, waiting for a CD with outdated shapefiles, and then manually cleaning the data in ArcGIS Desktop. I spent roughly eighteen months working on a project that involved pulling together county-level data from six different jurisdictions to model property tax equity across a metro area. The first two months were entirely consumed by data acquisition. One county had an API that returned results in under two seconds. Another county required a written request submitted via email to their GIS division, with no SLA, and they typically responded within six to eight weeks. Their shapefiles were in NAD 27 datum while the other counties used NAD 83, which meant every time I tried to join the datasets together in QGIS, the parcel boundaries would shift by approximately fifteen meters because someone had not reprojected the coordinate system before publishing. That fifteen-meter drift is enough to move a property line across a zoning boundary and completely invalidate an analysis. The workaround I ended up using was to download the raw survey coordinates from the first county's database and run a Helmert transformation against the NAD 83 control points published by the state plane coordinate system authority. It took me about four hours to write a Python script that handled the reprojection and coordinate adjustment for all the layers. I still had to go back and manually verify about thirty parcels in the final output because the transformation parameters were not exact for that particular township range. Nobody in the county GIS office told me about the datum mismatch until I flagged it during a public comment period.
How the data actually flows
Most county data portals today operate on one of three architectures. The first is a straightforward REST API backed by GeoServer or similar open-source GIS software. You send a GET request with filter parameters and get back GeoJSON or FeatureCollections. This is the cleanest option and it is what you will find from well-funded counties that have invested in modernizing their GIS infrastructure. Response times are usually under three seconds for queries covering a single township, and pagination works reliably. The second architecture is a WFS service, which stands for Web Feature Service. It is an OGC standard that predates REST by roughly fifteen years. Some older county systems still use this, and it works fine if you know how to construct the GetFeature requests with the proper filter expressions. The downside is that WFS does not handle large result sets well. Query a county's entire parcel layer and you will often get a timeout or a truncated response. I once hit this wall trying to pull all residential parcels in a county with a population of about 400,000. The service returned roughly 12,000 features out of an estimated 85,000 and then closed the connection without any error message. The workaround was to break the query into bounding box chunks and process each one separately. The third architecture is the download portal, which is essentially a collection of shapefiles, CSVs, and KML files organized into folders. Some counties organize these by topic — transportation, environment, land use. Others organize them by format. Download portals are still common in smaller counties that do not have the staff to maintain an API. They work, but the data is static. If a parcel splits or a zoning map gets amended, the file on the portal will not update until someone remembers to re-upload it. In my experience, the update frequency on download portals ranges from quarterly to "we will do it when we get around to it," which in practice means whenever a state audit requires current data.
Get the Full Details
What most people miss about quality
The biggest misconception about county data is that if it is published, it is accurate. It is not. Publishing a dataset does not make it current or correct. I have seen parcel layers where the geometry was fine but the ownership field had been copied from a 2019 assessment roll without any of the subsequent transfers being reflected. I have seen zoning layers where the boundary lines did not match the actual ordinance text because the GIS technician who digitized the map made assumptions about where a commercial zone ended and a residential zone began. I have also seen flood plain maps that were imported directly from FEMA without being reprojected to the county's native coordinate system, which creates the kind of spatial offset that makes overlay analysis completely unreliable. There is a counter-intuitive thing about open county data that is worth understanding. The most useful datasets are often the ones that look the least polished. A raw CSV export from a county assessor's database with messy field names and inconsistent date formats is usually more trustworthy than a beautifully rendered web map, because the web map has gone through at least one round of human curation and visual simplification that may have introduced errors. The CSV tells you what the database actually contains. The map tells you what someone wanted you to believe the database contains. Another thing that catches people off guard is how much variation there is in field naming conventions across counties. One county might call a parcel's owner name field "OWN_NAME." Another uses "OWNER." A third uses "PROP_OWNER." If you are building a tool that pulls data from multiple counties, you will spend more time writing a field-mapping layer than you will on the actual data processing. I built a normalization script that maintained a lookup table mapping common field name variants to a standard schema. It covered about forty field types across twelve counties and reduced my data ingestion time from roughly four hours per county to about twenty minutes once the mapping table was complete.
Where the system actually breaks down
County data portals have real limitations, and they are not always obvious until you run into them. The first limitation is that most portals do not provide historical snapshots. If you need to know what a parcel's zoning was in 2015, you are usually out of luck unless the county keeps archived versions of their shapefiles, which very few do. I once needed historical zoning data to support a variance appeal and spent three weeks digging through microfiche records at the county clerk's office because the online portal only showed the current layer. The second limitation is that many counties publish parcel data without including the survey coordinate information. What they publish is often a simplified polygon derived from tax assessor measurements rather than the actual metes and bounds description from the deed. This is fine for most analytical purposes, but if you are doing something that requires legal-grade boundary precision — like designing a utility easement that abuts an existing parcel — the simplified geometry will not hold up. The actual boundary could be tens of feet away from what the portal shows. The third limitation is rate limiting and lack of authentication. Most free county APIs do not require an API key, which sounds great until you are running a batch process that needs to pull hundreds of thousands of records. Without authentication, there is usually no guarantee of uptime or response quality. I once ran an overnight job to pull all permit records from a county API and got rate-limited after about four hundred requests. The job failed at 3 AM and I had to rewrite it with exponential backoff and chunked processing. With an API key, the same operation would likely have completed in under an hour with proper queue management.
When the portals fall short, the alternative is to contact the county GIS department directly and request a data extract. This is slower but often produces higher quality data because the extract comes from the source database rather than from a published layer that may have been simplified for web display. The tradeoff is that you are competing with other requesters. One county I worked with had a stated turnaround time of ten business days for data requests, but the actual turnaround was closer to thirty days during peak seasons. If you need data on a deadline, factor in at least double the stated turnaround time.

Practical steps for working with this data
Start by identifying exactly what datasets you need before you write any code. The most common mistake I see is people pulling everything available and then realizing too late that the fields they actually needed were not included in the published schema. Check the metadata on the data portal first. Metadata is often incomplete or generic, but it will tell you the data's origin date, the coordinate system, the field definitions, and any known issues that the county is aware of. Once you have your list, test each dataset with a small query before committing to a full extraction. Verify the coordinate system by checking a known point against a source you trust. If the county says their data is in State Plane NAD 83 but your verification point is off by more than a meter, something is wrong and you should flag it before proceeding. I have a habit of running a quick spot check on five random features across each layer, comparing the published geometry against what I can see in a trusted basemap or satellite imagery. This catches projection errors and shifted boundaries before they contaminate the entire analysis. Build your pipeline with error handling and logging from the start. County APIs will return incomplete results. Downloads will fail halfway through. Fields will have unexpected null values. I write a validation step into every pipeline that checks for missing geometry, inconsistent field types, and duplicate records. The validation step usually takes about ten percent of the total processing time, but it saves hours of debugging later when you discover that half your records are missing their ownership dates because the source field was named something unexpected.
Document everything. The data portal you are pulling from today may be decommissioned tomorrow. A county may change their API endpoint, drop a dataset, or alter their field structure without any public announcement. I keep a simple README file for each county's data that records the source URL, the last download date, the schema as I received it, and any quirks or workarounds I had to implement. When a county changes their system, this documentation lets me track the difference and adjust my pipeline without starting from scratch. There is no single tool that handles all county data well out of the box. The options range from Python libraries like Geopandas and Requests for programmatic access, to QGIS for manual inspection and cleaning, to commercial platforms like ArcGIS Online for visualization and sharing. The right choice depends on what you are trying to do. If you are running automated analyses across multiple counties, a Python-based pipeline with Geopandas is the most efficient. If you need to visually verify boundaries or explore the data interactively, QGIS is faster. If you need to present findings to stakeholders who are not technical, a published web map in ArcGIS Online or a similar platform is the only thing that will communicate the results clearly. One thing I wish I had understood earlier is that county data is never going to be perfect, and that is fine for most purposes. The goal is not to produce legally defensible boundaries or academically pristine datasets. The goal is to produce analyses that are good enough to inform decisions, and to understand the margin of error so you can communicate it honestly. A parcel layer that is accurate to within five meters is sufficient for most land use planning analyses. It is not sufficient for a property line dispute, but no county-published dataset is designed for that use case anyway. Knowing the difference between those two use cases and matching your data quality expectations to the question you are actually trying to answer is the skill that takes the longest to develop.
The data is getting better every year. More counties are moving to APIs, more are adopting standard schemas, and more are including metadata that is actually useful. The pace of improvement varies wildly from one jurisdiction to the next, so do not assume that what worked with one county will work with the next. Treat each new data source as a fresh problem, verify what you need to verify, document what you learn, and move on. The work is repetitive but the details are never identical.