Accessing Pennsylvania Court Records Through the AOPC System
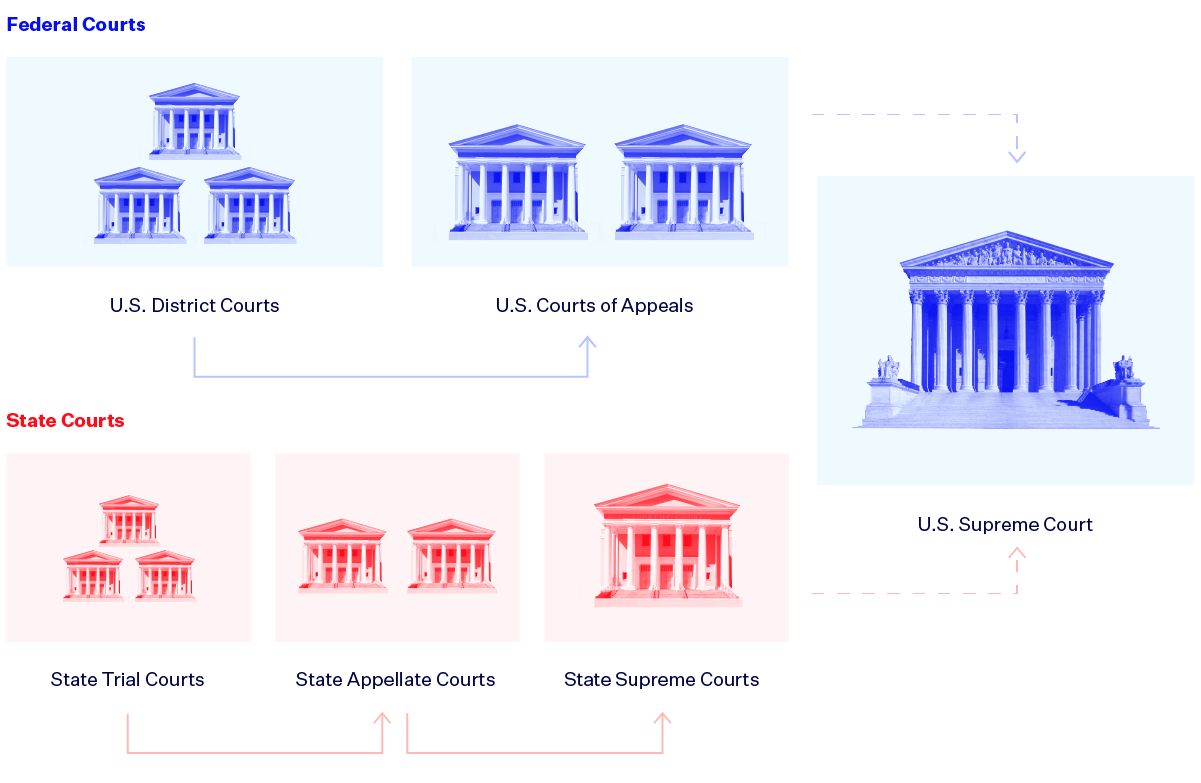
The AOPC is the Administrative Office of the Pennsylvania Courts, and their docket system is the backend that feeds public-facing court record platforms across the state. If you are trying to pull case information for research, litigation support, or compliance work, you are probably running into it whether you meant to or not. The system has been around in various forms since the late 1990s, and the shift toward real-time transparency is something most people in this space noticed happening slowly over the last five years rather than as a single event. Real-time transparency in this context means that docket entries, hearing schedules, and case status updates are posted to public access portals closer to the moment they are generated by the court system, rather than being batched and published days or weeks later. This matters because the gap between when something happens in court and when it becomes discoverable through public records is where a lot of legal risk lives. People who monitor dockets routinely will tell you that a delay of forty-eight hours can change the outcome of a motion, a settlement negotiation, or a compliance filing. The AOPC has been pushing PA-Courts.gov and related interfaces to reflect filings more quickly. Whether it is truly real-time or just faster batch processing depends on the county and the case type. The urban counties like Philadelphia and Allegheny are generally more advanced. Rural counties still lag, sometimes by significant margins. That inconsistency is one of the first things you need to accept before building any kind of automated monitoring system around it.
Here is how I actually pull data from it. I use the PA-Courts.das portal for public access, but when I need bulk queries or scheduled monitoring across multiple counties, I write scripts that hit the searchable endpoints the system exposes. The trick is that the interface changes without much notice. I spent about three weeks last year dealing with a parser that broke because the AOPC restructured their JSON response format between a minor update and a major update. The workaround was to stop relying on response schema assumptions and start treating every field as optional, with fallback logic that falls back to scraping the rendered HTML table only when the API returns incomplete data. It is slower, but it does not break when the backend shifts. If you want to try this yourself, the entry point is the UJS public access portal at ujsportal.pacourts.us. You do not need an account to run basic case searches. You do need an account if you want to set up email alerts or access the full document viewer for certain case types. The free tier will get you docket line items and basic case metadata. Anything deeper, like scanned PDF filings or audio recordings from proceedings, usually requires a pay-per-record fee through the same portal. One thing nobody tells you about the AOPC docket system is that the case number formats vary enough to break naive regex parsers. A civil case in one county might be formatted as CV-2024-012345, while the same type in another county uses 2024CV012345 or even CA-24-012345. I learned this the hard way when I built a script that successfully monitored thirty counties before it started silently dropping cases from three of them because the format mismatch meant zero hits. The fix was a normalization layer that stripped prefixes, reindexed the year portion, and compared against a county-specific format registry I maintain. It added about twenty minutes to initial setup and maybe five seconds per query cycle, but it caught the cases the parser was missing.
Another counter-intuitive detail is that docket transparency is not actually uniform across case types. Criminal dockets tend to update faster than civil ones, and Juvenile and Orphans' Court records are largely sealed or delayed by design. If your project assumes that real-time transparency applies equally everywhere, you will waste time chasing records that the system is explicitly preventing you from seeing. The AOPC publishes a case type access guide on their site, but it is buried in the help section and not always kept fully current. There are also bottlenecks that make the real-time claim harder to live up to. Court clerks do not always enter hearing results the same day, especially in busy metropolitan courts. A trial might conclude on a Thursday, but the official docket entry does not appear until the following Tuesday when the clerk’s office catches up. Third-party aggregators that claim instant updates are often just mirroring the same delayed public feed with a different front end. I have seen two commercial monitoring services report the same case with a two-day gap between their "latest" entries, which turned out to be the same clerk backlog issue. If you need guaranteed timely access rather than best-effort public data, the alternative is to apply for direct PACER-level access for federal cases or to negotiate a data-sharing agreement with the county prothonotary's office for state cases. That path costs more and involves paperwork, but it bypasses the public delay layer entirely. For most people doing routine monitoring or research, the public portal is sufficient. Just do not treat it as instantly real-time. Treat it as near-real-time with a latency window that varies by jurisdiction and case type, and build your workflows around that assumption.
Get the Full Details

The AOPC system is not perfect, and the push toward transparency is real but uneven. It works if you understand where the cracks are and design around them. If you are just starting out, begin with manual searches on PA-Courts.gov, learn the quirks of your target county's docket format, and only then automate anything. Writing a broken automation that misses cases is worse than doing the work by hand once.