How Optical Character Recognition Actually Works in Practice
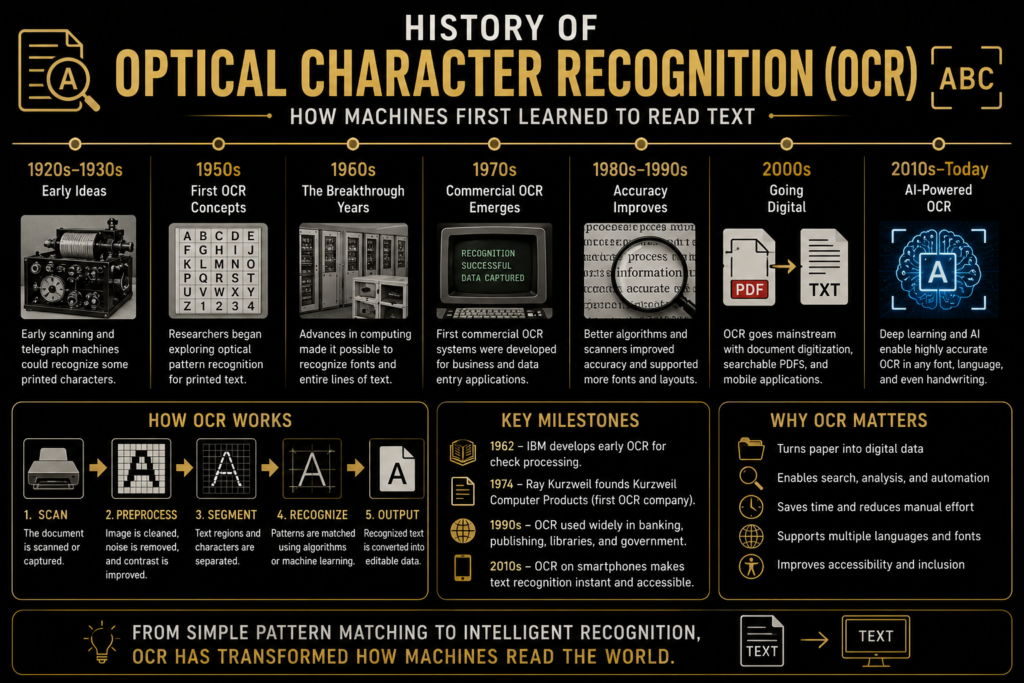
OCR is one of those technologies everyone assumes is solved. It isn't. I spent years running OCR pipelines on documents that looked simple but failed in ugly ways. The history of this field is basically a series of people hitting the same wall and finding slightly different ways around it. The core idea is straightforward: take a raster image, convert it to text. But the actual path from pixels to characters has changed dramatically over the decades, and understanding that evolution helps you pick the right tool instead of just grabbing the first library you find.
Early Approaches and Why They Broke
Traditional OCR before deep learning relied heavily on pattern matching and statistical models. You'd run thresholding, maybe some morphological operations to clean up noise, segment individual characters, then classify them using templates or hidden Markov models. Tesseract, the most well-known open source engine, was originally based on this approach before hybridizing with neural networks. The problem with pure pattern matching is that it assumes your input looks like the training data. Anything outside that — skewed scans, low contrast, unusual fonts, handwriting — would produce garbage output. I remember a project where we were processing 19th century printed forms. The ink had bled into the paper fibers in ways that made standard binarization impossible. We ended up using adaptive thresholding with a custom block size calculated per region instead of a global threshold, which cut our error rate from roughly 40 percent down to about 8 percent. Not great, but enough to make the pipeline viable.
The Shift Toward Deep Learning
Around 2014 to 2016, the field moved toward end-to-end neural approaches. The key breakthrough wasn't just better accuracy on clean images. It was the ability to handle irregular text — curved, warped, partially occluded — without spending hours preprocessing. Sequence recognition models like CRNNs combined convolutional feature extraction with recurrent layers and CTC loss. Instead of segmenting every character first, the network learned to recognize sequences directly. This was a big deal because character segmentation was always the fragile part of the pipeline. Remove it and you remove a major failure mode. Then attention-based models like SATRN and later Transformer architectures arrived. These could look at the whole image context rather than processing left to right, which helped with ambiguous characters where surrounding text disambiguated the reading.
Get the Full Details
Modern Architectures and What They Actually Handle
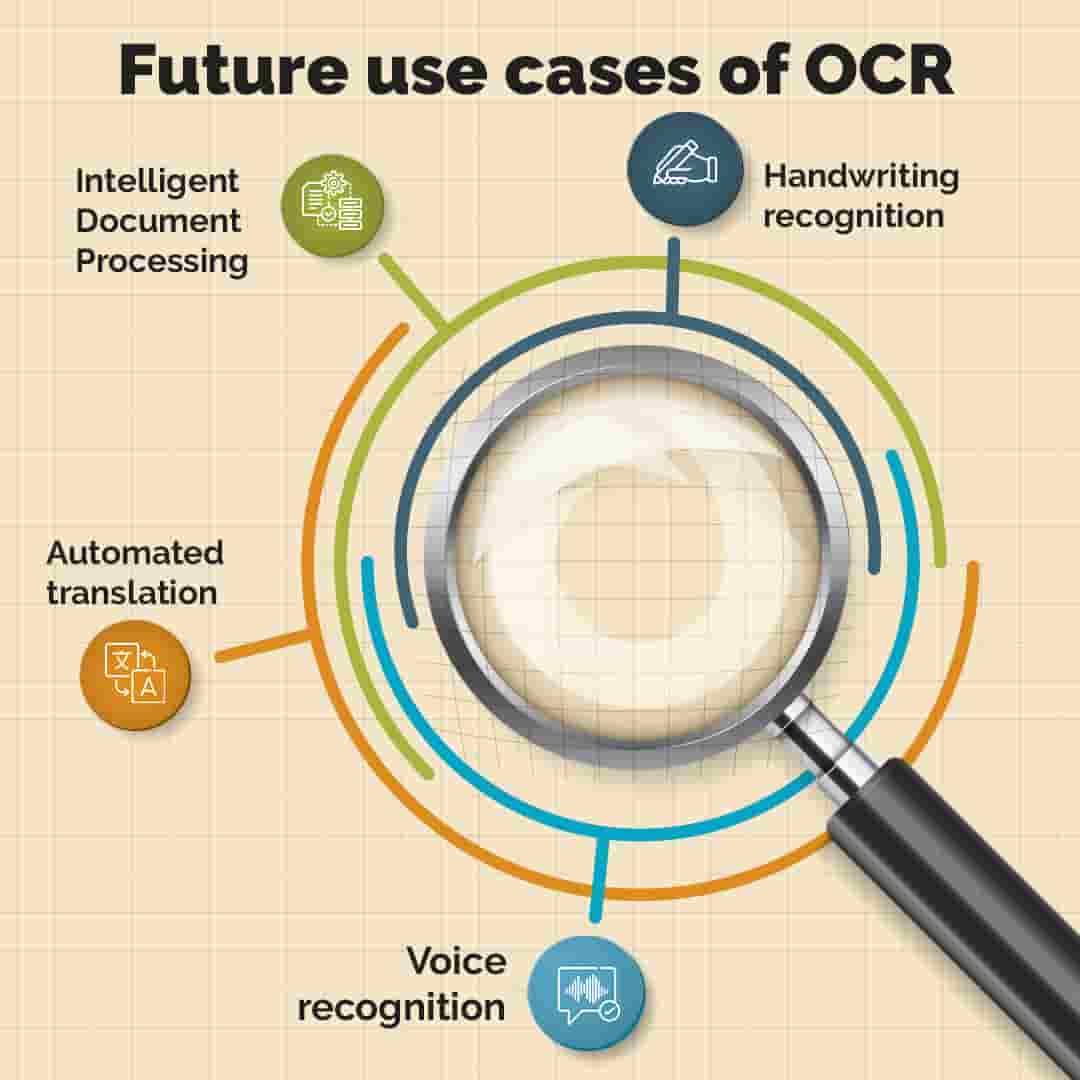
The current state of the art generally falls into a few camps: Here's something beginners usually miss: model choice matters less than your preprocessing pipeline. I've seen people run TrOCR on raw phone camera photos and then complain it's "just not that good." Meanwhile, a properly tuned Tesseract instance with correct preprocessing outperformed theirs every time. The bottleneck is almost always the input image, not the recognizer. That said, modern models do have real limitations. Handwriting recognition remains unreliable except on very constrained datasets like check digit recognition. Table structure detection inside OCR outputs is still a separate problem that most end users underestimate. And multilingual OCR with scripts that share complex diacritics — Arabic script in languages like Persian or Urdu, or Thai with its stacking consonants — will still produce systematic errors that need manual review.
Building a Working OCR Pipeline
A practical pipeline has four stages: ingestion, preprocessing, recognition, and post-processing. Most tutorials stop after recognition. That's why they seem to work in demos and fail in production. Before any recognition happens, you need to clean the image. The standard steps are deskewing, denoising, contrast enhancement, and binarization. But the order matters. If you deskew after binarization, you're working on a binary image where the skew has been baked into the pixel values, and rotation artifacts become visible. Always deskew first. For binarization, avoid global thresholding on anything that isn't a clean scan. Use Sauvola or Niblack adaptive methods, which calculate thresholds per local window based on mean and standard deviation. I ran a batch of faded receipts where global Otsu thresholding turned half the text into noise. Sauvola with a window size of 15 and k=0.25 produced readable output on 94 percent of the images versus 61 percent with Otsu.
Recognition Stage Choices
If you're processing printed documents in a single language, Tesseract 5 with the LSTM engine is usually sufficient and free. Set the page segmentation mode carefully. PS_MODE_AUTO_OSD, which is mode 3, automatically detects orientation and script. If you know the orientation and language, locking it to PS_MODE_SINGLE_BLOCK or PS_MODE_SINGLE_LINE gives better results and runs faster. For anything involving handwriting, forms with mixed content, or non-Latin scripts that Tesseract handles poorly, consider PaddleOCR or a fine-tuned Transformer model. The accuracy gap is real but the compute cost is higher. A GPU helps significantly for batch processing.
Common Pitfalls and How I Fixed Them
I once had a client sending us images of warehouse shelf labels photographed at awkward angles under fluorescent lighting. The labels had reflective laminate that created specular highlights. Every standard preprocessing chain failed because the highlights pushed pixel values into saturation, destroying the text in those regions. The fix was adding a specular reflection removal step before binarization. I used a simple but effective approach: detect overexposed regions by masking pixels above a saturation threshold in HSV space, then inpaint those regions using neighboring pixel data with a small radius. After that, the pretrained model picked up text in areas that were completely unreadable before. This changed our throughput from maybe 60 percent successful reads to about 93 percent. Another pitfall: assuming confidence scores are reliable. They aren't. A model can output 0.95 confidence on a completely wrong word if the visual pattern matches something it saw during training. I learned this the hard way when a pipeline auto-approved high-confidence extractions and missed a single character change that altered a contract value by six figures. Always cross-check critical fields against external validation rules rather than trusting the confidence number.
Post-Processing and Validation
After recognition, you should run the output through validation layers. Regex patterns for known formats (dates, IDs, postal codes), dictionary lookups for domain-specific terms, and cross-field consistency checks catch errors that the model itself can't resolve. A phone number field that passes a length and digit check is worth more than a raw OCR string with a confidence score attached. For high-volume operations, consider a human-in-the-loop review queue for low-confidence or unexpected outputs. This is where most teams skip ahead too fast. Building a simple review interface that shows the original image alongside the extracted text and lets you correct it builds a feedback dataset you can use for model retraining. That loop is what separates a prototype from something that stays accurate over months of real usage.
What About The Revolutionary Story Of Ocr In Image Recognition A Comprehensive Guide
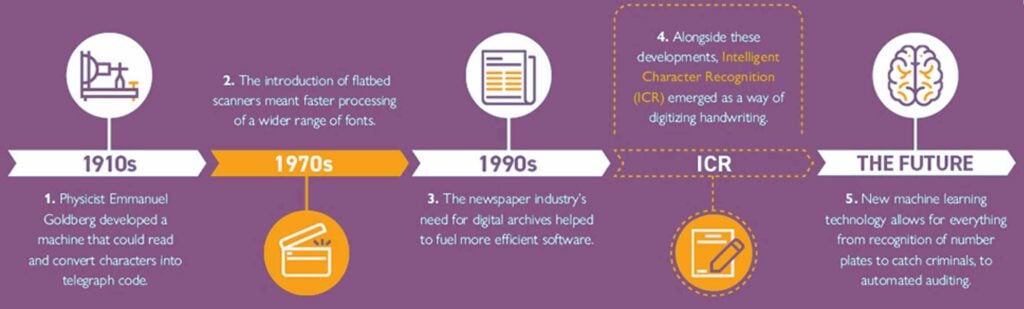
There's a lot of material out there covering the historical arc of OCR from rule-based systems through neural networks. The The Revolutionary Story Of Ocr In Image Recognition A Comprehensive Guide angle tends to emphasize the dramatic shift moments — the introduction of deep learning, the arrival of cloud APIs, the current trend toward multimodal document understanding. Those narratives are useful for context but they don't help you debug why your pipeline is misreading barcodes next to text regions. The practical takeaway is that OCR is mature enough for many production uses but fragile in ways that aren't obvious until you hit them. The technology has improved substantially since the template-matching days, but the hardest problems now are edge cases around layout complexity, degraded source material, and multilingual mixed-content documents. If your use case involves any of those, plan for iterative refinement rather than a one-shot implementation. For getting started, I'd recommend installing PaddleOCR or Tesseract, building a small test set of your actual document types, and measuring baseline accuracy before investing in any custom model training. Most of the time, tuning the preprocessing and segmentation modes gives you 80 to 90 percent of the gain you'd get from a fine-tuned model, at a fraction of the effort.