.jpeg)
What Actually Happens When You Try to Connect Disparate Systems
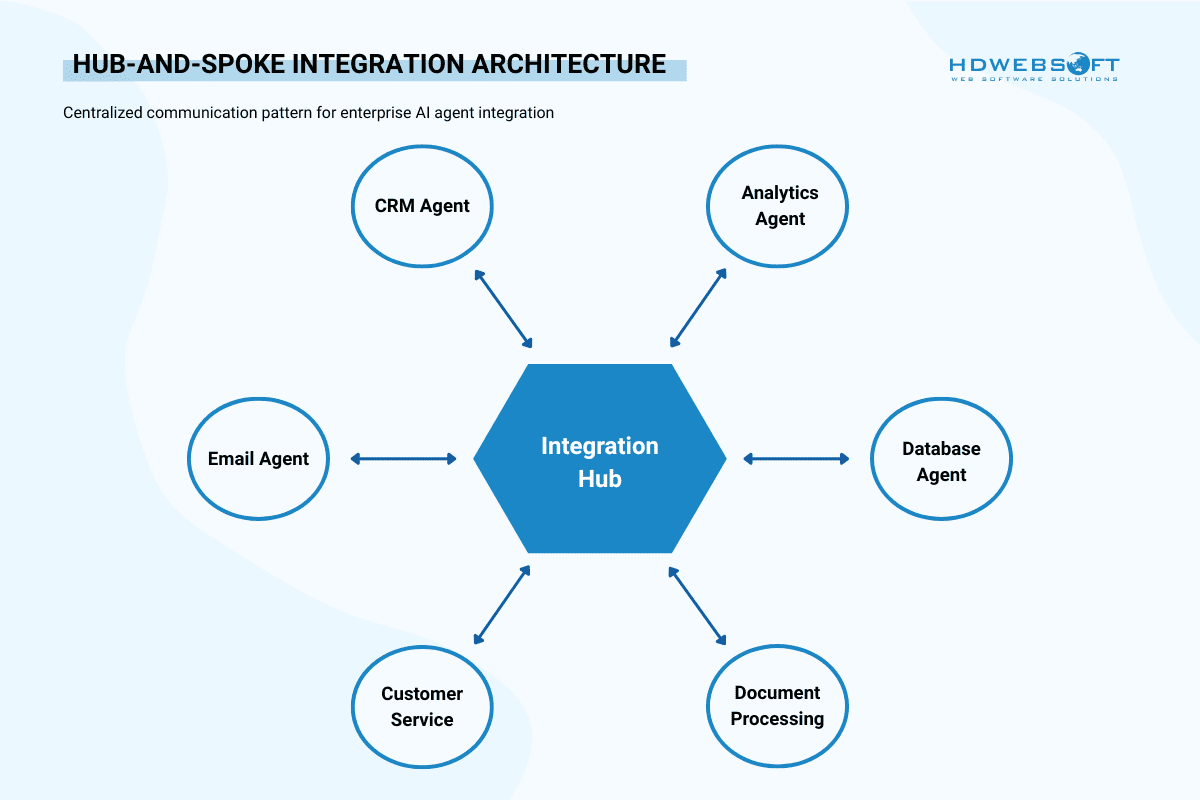
I spent three weeks last year trying to get a legacy CRM to talk to a modern cloud analytics platform. The data formats didn't match, the authentication flows were completely different, and every API endpoint seemed to have its own quirks. What saved me was finding the right middleware approach, which eventually led me to Alie Hub. Alie Hub is essentially an interoperability layer that sits between systems that weren't built to communicate. It handles protocol translation, data format mapping, and authentication bridging so you don't have to write custom glue code for every integration. The basic workflow involves defining your source systems, mapping the fields, setting up the transformation rules, and then letting the hub route the data between them.
The Revolutionary Power Of Alie Hub Unlocking Interoperability In The Digital Age
The core mechanism is a rule-based adapter system. You create adapters for each connected system, and the hub handles the bidirectional translation. ForRESTful APIs, it manages the REST-to-RPC or SOAP translations automatically. For databases, it handles schema differences without requiring you to rewrite your queries. The real value shows up when you have more than two systems involved, because that's when the custom integration hell usually starts. Here's how I typically set up a new integration project. First, I audit every system that needs to connect and document their native data formats and rate limits. Then I configure the adapters in the hub, starting with the most constrained system since that becomes the bottleneck. I map the fields with explicit null-handling rules because nothing breaks faster than an undefined field assumption. After deployment, I monitor the transformation logs for about a week before considering the integration stable. One thing most people miss is that Alie Hub doesn't solve the data quality problem at the source. If your source system is sending duplicate records or malformed dates, the hub will faithfully translate and propagate those issues to every connected system. I learned this the hard way when an inventory sync started flooding our warehouse management system with 400 duplicate SKUs. The fix wasn't in the hub configuration. It was adding deduplication logic at the source layer before the data ever reached the adapter. Now I always add a validation checkpoint in the pipeline, even if it adds a second or two to the sync process.
Another counter-intuitive aspect is authentication handling. The hub supports OAuth2, API keys, and basic auth, but mixing authentication methods across different adapters in the same pipeline can cause unexpected token refresh failures. I had a setup where one adapter was using short-lived OAuth tokens while another was using a static API key. Every time the OAuth token refreshed, the entire pipeline would briefly stall for about 30 seconds while it re-authenticated. The workaround was to stagger the refresh schedules across adapters so they never hit the same moment. The performance characteristics are worth understanding upfront. Under normal conditions, the hub adds approximately 50 to 150 milliseconds of latency per transformation, which is usually acceptable. But when you're dealing with large payloads or complex nested schemas, that latency can spike dramatically. I once saw a single payload transformation take over 4 seconds because the source system was sending deeply nested JSON with 800 fields, most of which mapped to nothing on the destination side. The solution was to implement field-level filtering in the adapter configuration rather than doing a blanket full-schema mapping. That cut the transformation time down to around 200 milliseconds. There are scenarios where Alie Hub simply isn't the right answer. If you're integrating two systems from the same vendor family, they probably already have a native integration path that's faster and more reliable. If your data needs are real-time and sub-100-millisecond, the hub's translation overhead might be too much, and you'd be better off with a direct point-to-point connection. If you only have two systems and one is simple, writing a few hundred lines of integration code might actually be cheaper in the long run than configuring and maintaining a hub layer.
Get the Full Details

The community documentation covers the standard use cases well enough, but the edge cases around schema drift are not well documented. When a source system updates its API and changes a field type without deprecating the old one, the hub will often silently start using the new format while your destination system is still expecting the old one. I set up automated schema comparison checks that run weekly to catch these drifts before they cause production failures. It adds maybe an hour of work per month but has saved me from several painful incident responses. For anyone looking to get started, the download and installation process is straightforward on their official site. You pick the deployment option that matches your infrastructure, pull the container images or install the binaries, and run the initial configuration wizard. The free tier handles up to five connected systems and about 10,000 transformations per day, which covers most small projects. Beyond that, pricing scales with the number of active adapters and throughput requirements. What I wish was clearer in the documentation is the backup and disaster recovery model. The hub maintains its own state about mappings and configurations, and while there's an export function, restoring from a backup after a complete failure isn't as smooth as it could be. I recommend setting up automated daily backups of the hub configuration and testing the restore process at least once per quarter. It took me two hours to properly configure backups after my first crash, but it saved me an entire weekend when the hub went down unexpectedly during a major data migration project.