
The Current State Of Deepfake Technology
Deepfake tools went from research papers to consumer software in roughly two years. That timeline is shorter than most people remember. The underlying technology — generative adversarial networks, autoencoders, and more recently diffusion models — isn't new, but the quality threshold crossed somewhere around 2020 and it has not looked back since. What changed was accessibility. You no longer need a GPU cluster or a PhD to generate convincing synthetic media. Consumer GPUs handle real-time face swaps now. Cloud services exist for people who don't want to install anything. The gap between what researchers publish and what a random person on Reddit can do has narrowed dramatically.
The Revolution Of Deepfake Technology And Its Implications For Content Creation
I work in digital media and I have spent the last three years watching this space evolve at a pace that made planning nearly impossible. The first model I trained properly took about twelve hours on a single RTX 3090. Today, fine-tuned face-swap models can produce publishable results in under twenty minutes on the same hardware. That is not a small improvement. It is the difference between a weekend project and a Tuesday afternoon task. The technical stack people actually use falls into a few categories. One-shot face swap models like InsightFace and IP-Adapter require minimal training data and work well for static images and short clips. Full training pipelines — the kind based on DeepFaceLive or custom DiffSynth setups — need fifty to two hundred frames of source footage and several hours of GPU time, but they produce results that survive close inspection and varied lighting. Then there are the proprietary platforms like HeyGen and Synthesia, which sit somewhere between a tool and a service and trade customization for speed. Here is something beginners consistently miss. Frame rate mismatch is the most common failure mode in deepfake projects. If your source video runs at 23.976 fps and your output pipeline processes at 30 fps without proper temporal smoothing, the result looks jittery within three seconds. The fix is straightforward — run your source through a frame interpolation step using something like RIFE or Flowframes before feeding it into the model, and always render at the target framerate, not a rounded number you picked because it felt clean.
Another counter-intuitive detail involves resolution scaling. Most people assume higher resolution input equals better output. In practice, feeding a 4K face swap model a 4K source often produces worse results than upscaling the output afterward. The model's attention mechanism degrades when faces occupy too small a percentage of the frame relative to its training distribution. The standard approach is to run the swap at a lower resolution — usually 512 by 512 or 768 by 768 depending on the model — then use a dedicated upscaler like ESRGAN or Real-ESRGAN on the final composite. This typically preserves coherence while keeping GPU memory usage manageable.
Get the Full Details

How The Pipeline Actually Works In Practice
A typical workflow starts with extraction. You pull individual frames from your source video. The frame count matters less than consistency. Use FFmpeg with a command like extracting every frame, then run face detection via RetinaFace or the mediapipe solution to establish alignment landmarks. The alignment quality here determines everything downstream. A poorly aligned face map introduces artifacts that no amount of post-processing will fix. From there, the model inference step varies significantly by approach. For one-shot methods, you provide a reference image of the target face and the model handles the rest with minimal configuration. For full training runs, you prepare a dataset, configure the training parameters through a YAML file, and monitor loss curves. The sweet spot for most consumer training runs sits around one hundred thousand steps on a dataset of roughly one hundred unique images with varied expressions and angles. Training longer than that typically yields diminishing returns and occasionally causes overfitting where the output starts looking identical across all source frames regardless of expression. I encountered a specific edge case recently that illustrates why dataset curation matters more than most guides acknowledge. A client provided twenty high-resolution portrait photos of a subject for a commercial project. The output looked excellent in controlled lighting but broke down completely under natural outdoor conditions. The issue was that every reference image was shot indoors with diffused lighting. The model had never seen the target face at an angle with directional sunlight. I resolved this by sourcing additional reference material from news footage and public appearances — roughly sixty additional frames covering different times of day and camera angles — and retraining with a lower learning rate to avoid destabilizing the baseline features. The second pass took roughly the same time but produced usable results across the full range of source material. This is a bottleneck that rarely gets discussed. Most tutorials assume your training data will be representative. It almost never is.
The Detection Side Of The Equation
Deepfake detection has not kept pace with generation. This is the uncomfortable reality that shapes nearly every policy discussion around this technology. Detection models like Facebook's NodeFormer or Microsoft's Video Authenticity models achieve reasonable accuracy on benchmark datasets, but those datasets contain synthetic content generated with older techniques. When you feed them recent outputs from current generation models, the detection rate drops significantly. The fundamental problem is that detection relies on identifying artifacts — inconsistencies in blinking patterns, blood flow detection through photoplethysmography, frequency domain anomalies, and lip-sync misalignment. Modern models address most of these individually. Some generate realistic blink rates. Others incorporate physiological signal modeling. The arms race dynamic means detection is perpetually chasing generation by roughly eighteen to twenty-four months. This gap has practical implications for anyone working in this space professionally. If you are creating synthetic media for broadcast or commercial use, assuming detection tools will catch your work is unrealistic with current technology. Conversely, if you are evaluating content for authenticity, the absence of a detection flag does not confirm genuine origin. The tools are not reliable enough for either direction yet.
Legal And Ethical Considerations
The legal landscape around deepfakes is fragmented and still developing. In the United States, federal law currently addresses deepfakes primarily in the context of elections and non-consensual intimate imagery. Several states have enacted their own statutes with varying scopes. The European Union's AI Act classifies deepfake generation tools under transparency obligations, requiring disclosure when content is artificially generated or manipulated. This is not a prohibition. It is a labeling requirement. The more immediate concern for most people working with this technology is not government regulation but platform policy. YouTube, Meta, X, and TikTok each have their own rules regarding synthetic media. YouTube requires disclosure in the upload metadata. Meta mandates labels on AI-generated content in feeds. Non-compliance can result in content removal or account restriction regardless of whether the underlying activity is legal. The platforms set the effective rules here, not legislatures. From a practical standpoint, if you are generating any kind of synthetic media, you should review the platform terms before publishing. The penalties for non-disclosure vary but they tend to escalate quickly once content goes viral. A video that flies under the radar at ten thousand views will attract detection scrutiny at one million.
What This Technology Actually Enables
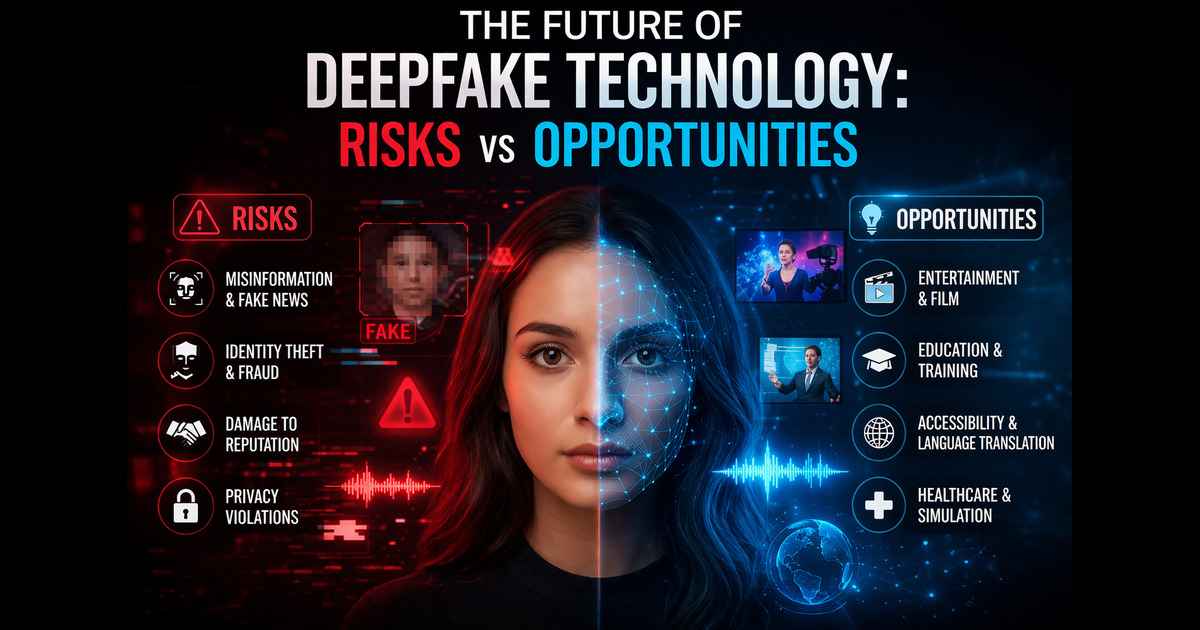
Beyond the sensational headlines, deepfake technology has legitimate applications in film production, accessibility, and education. Dubbing films into other languages while preserving the actor's facial performance is now feasible at commercial quality. Lip-sync translation tools exist that can match audio in a target language to the original speaker's mouth movements with reasonable accuracy. Some accessibility projects use synthetic voice and face generation to help people who have lost their ability to speak or move facially due to medical conditions. The business use case is narrower than you might expect. Marketing teams occasionally use synthetic spokespersons for localized content, but the uncanny valley effect remains a real barrier for anything involving human interaction. Consumers can generally tell when a presenter is synthetic, and that recognition affects trust metrics. The technology works better for behind-the-scenes applications — background crowd generation, archival restoration, and editorial compositing — where the synthetic element is not the focus. Computational cost is another constraint that gets overlooked. A typical high-quality face swap generation run on consumer hardware might take twenty to forty-five minutes per minute of output. Cloud GPU rental runs roughly three to eight dollars per hour depending on the instance type. That makes large-scale production expensive compared to traditional compositing workflows. The cost becomes comparable only when you factor in the alternative of hiring makeup artists, reshoots, or animation teams for equivalent results.
Where The Technology Is Heading
The direction of travel is clear even if the timeline is not. Model sizes are decreasing while quality increases, which means the hardware barrier continues to drop. Real-time generation on laptop-class GPUs is already possible with optimized architectures. The next constraint is not computation but distribution and verification. As generation becomes trivial, the value shifts toward proving provenance. Cryptographic content authentication is being developed as a response. Initiatives like C2PA embed provenance metadata directly into media files at the point of capture or creation. This does not prevent forgery but it provides a verifiable chain of custody. Whether this system gains adoption depends on industry coordination, which has historically been slow. The technology exists. The infrastructure is incomplete. For now, the practical takeaway is that deepfake generation is a commodity tool with real capability and real risks. The technology itself is neutral. The output depends entirely on intent and distribution choices. Anyone with access to a modern computer can generate convincing synthetic media. The question that the industry has not adequately answered is how to build systems that make misuse harder without making legitimate use significantly more difficult.


