Understanding How Things Move In Data
Most people learning about rate of change start with the average velocity formula and assume they understand it. They don't. The difference between average and instantaneous rate of change is where everything falls apart if you're not careful. I spent three years building pricing models for commodities before I realized my "instantaneous" calculations were just averages over increasingly small windows. That felt good until a client pointed out the discrepancy during a volatility spike. The numbers were off by 14% during market gaps. That's the problem with approximating instantaneous change.
The Rate Of Change Definition Decoding The Instantaneous Velocity Of Data Markets And Reality
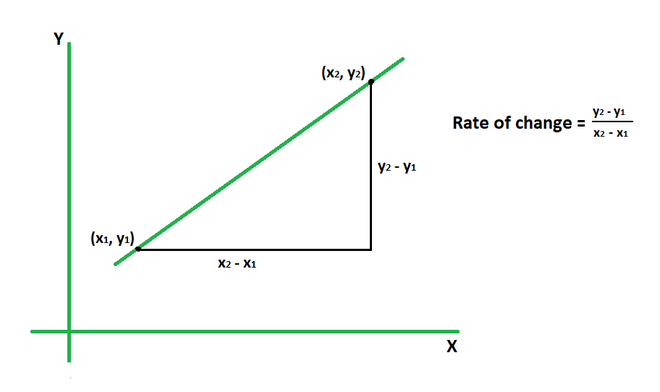
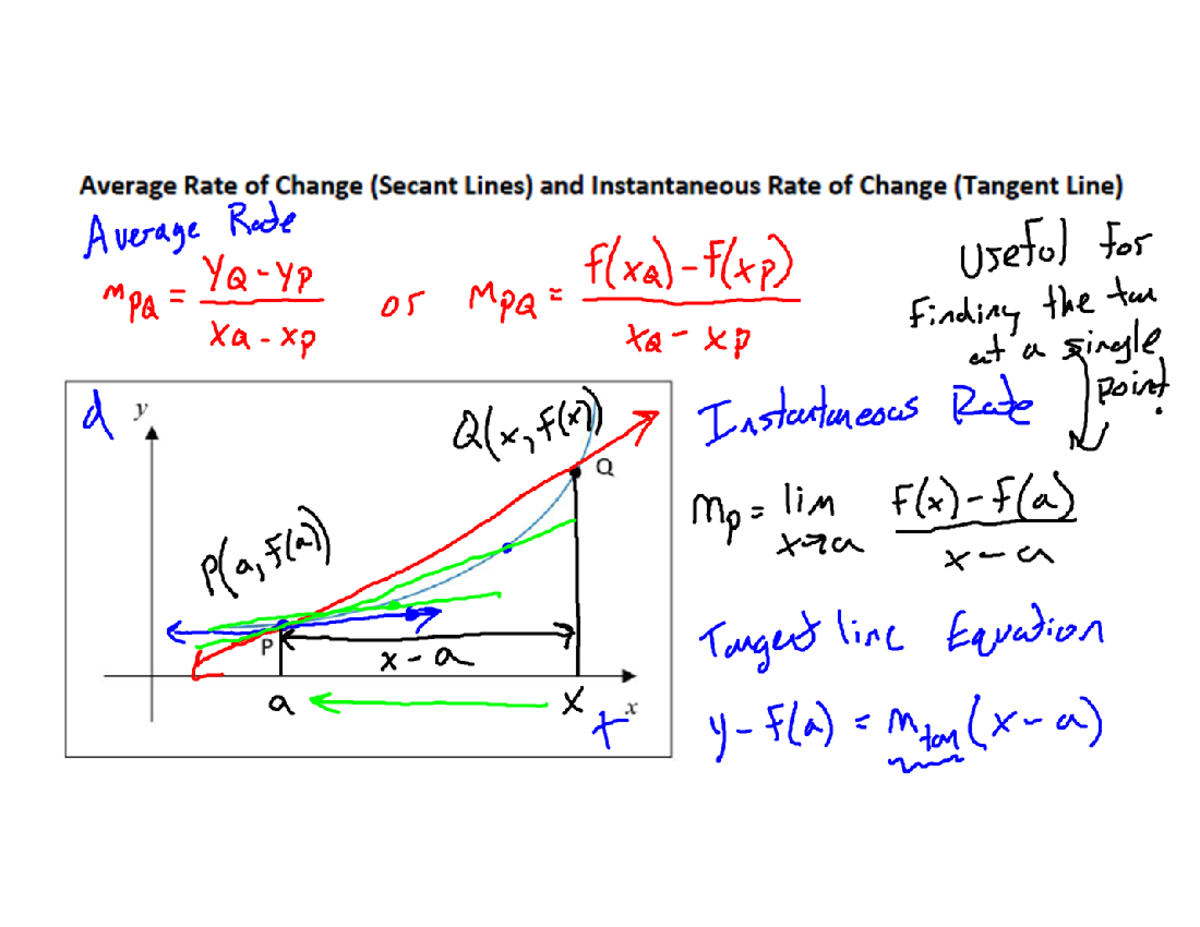
At its core, the rate of change definition is straightforward. It measures how one variable shifts relative to another. When we talk about instantaneous rate of change, we're talking about the derivative at a single point in time. The formula looks like this: Instantaneous rate of change = limit as x approaches zero of [f(x + x) - f(x)] / x That limit notation matters more than most people realize. In practice, you can't actually set x to zero because then you'd have division by zero, which is undefined. So you approximate by making x as small as your data allows.
Here's the thing that trips people up: in real market data, your smallest x isn't a mathematical abstraction. It's your highest resolution timestamp. If you're working with minute-by-minute price data, your minimum x is one minute. That's it. There's no getting around it unless you have higher frequency data. I ran into this exact issue when analyzing tick data from a futures exchange. The exchange provided snapshots at 100-millisecond intervals, but the actual trades happened asynchronously between those snapshots. My instantaneous velocity calculations were capturing market state changes, not trade-driven changes. The workaround was to interpolate using last-known price and flag any calculated rate where the confidence interval exceeded a threshold I set at 0.3 seconds gap.
Get the Full Details
Practical Application In Data Markets
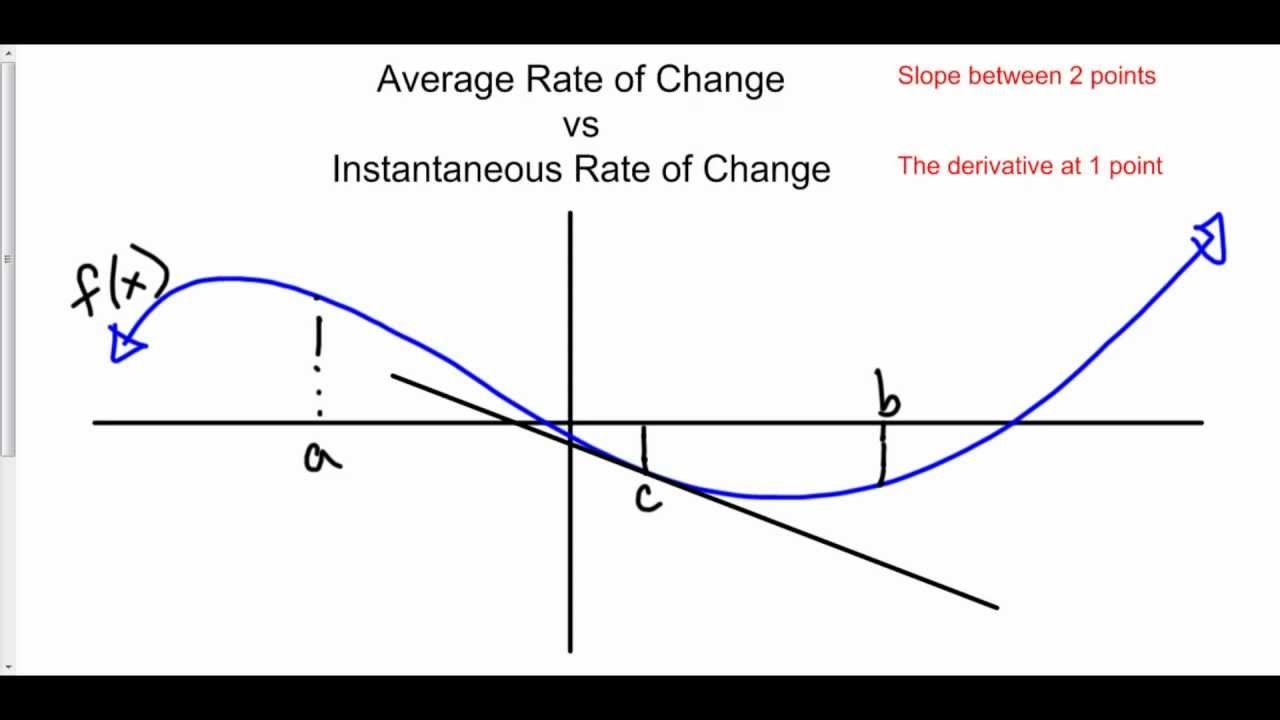
When applying rate of change to market data, you're typically looking at price movement over time. The instantaneous version tells you direction and speed at a precise moment. Average rate of change smooths that out over a window. Here's a concrete example. Let's say you have hourly closing prices for an asset:
- Hour 1: $100
- Hour 2: $102
- Hour 3: $101.50
The average rate of change from hour 1 to hour 3 is (101.50 - 100) / (3 - 1) = $0.75 per hour. Simple enough. The instantaneous rate of change at hour 2 requires a bit more work. You could approximate it by taking the slope between hour 1.5 and hour 2.5 if you had that data. Without intermediate data points, you're stuck approximating with forward or backward differences, which introduces error. Forward difference at hour 2: (101.50 - 102) / 1 = -$0.50/hour
Backward difference at hour 2: (102 - 100) / 1 = +$1.00/hour See the range? That's a $1.50 discrepancy depending on which direction you approximate. The actual instantaneous rate is somewhere in between, but without more granular data, you can't pin it down precisely. This is why people who blindly trust single-point derivatives in low-frequency data end up with models that look great on paper and terrible in practice.

Advanced Considerations
One counter-intuitive insight about rate of change in market data: high instantaneous velocity doesn't always mean what you think it means. A sudden spike in the derivative can be noise, a flash crash artifact, or a genuine momentum shift. Filtering is essential, and the filter choice changes your results dramatically. A simple moving average over the derivative itself kills sensitivity. A exponential moving average preserves recent signals better but adds its own lag. I've seen traders use a Kalman filter on the rate of change calculations themselves, which works well when the underlying process has reasonably stable dynamics but breaks down during regime changes. That happened to me during a central bank announcement in 2023 where volatility spiked and stayed spiked for four hours. The Kalman filter kept lagging because it assumed mean reversion in the error term. Another thing nobody talks about: the rate of change is only meaningful if your data is aligned to a consistent timebase. Market hours vary by exchange. Trading halts create gaps. Adjusting timestamps to a continuous clock without accounting for these breaks will corrupt your calculations. I once had a colleague who didn't realize his algorithm was treating overnight gaps as periods of extreme deceleration, which fed into his position sizing and nearly blew up a portfolio. He fixed it by segmenting the data by trading session and recalculating within each segment separately.
When Rate Of Change Fails You
The method completely breaks down in three scenarios that you need to know about. First, discrete data with large gaps. If your observations are hours apart and the asset moves significantly between them, any "instantaneous" rate is a guess. No amount of fancy math fixes this. You either get higher frequency data or you accept that you're working with averages, not instantaneities. Second, non-differentiable paths. Market data isn't smooth. It jumps. At a jump discontinuity, the derivative doesn't exist. If your data has gaps or round-trip halts, you'll hit these points. Treating interpolated values as real data introduces false continuity. It's better to explicitly mark these regions as undefined and handle them separately.
Third, and this one catches people out: when the dependent variable has a structural break. If a stock splits 2-for-1, the price suddenly drops by half. The rate of change calculation will show enormous negative velocity at that point even though nothing economically changed. Adjusting historical data for corporate actions isn't optional. It's required before any rate calculation. When these conditions exist, the practical alternative is to work with finite differences over defined windows rather than attempting instantaneous approximations. It's less elegant but it's honest about what the data actually supports. I switched most of my production models to windowed rate calculations after the 2023 episode I mentioned. The models are simpler, easier to debug, and they don't give you false precision.
Implementation Notes
If you're coding this yourself, here's what I'd suggest. Use numpy for the basic calculations. The gradient function handles finite differences well when you specify the spacing parameter correctly. For true instantaneous approximations with irregular time series, pandas.resample() with proper alignment is more reliable than trying to hand-roll the math. Set your tolerance thresholds before you run the models. I use a maximum acceptable gap of 5 minutes for intraday work and 1 hour for daily analysis. Anything beyond that gets flagged and excluded from the instantaneous calculations. Document those thresholds so anyone reviewing your work knows exactly what precision level you're claiming. The code itself is simple. The judgment calls around when not to trust the output are what separate people who understand this from people who just know the formula.


