So You Want To Model Genetic Drift
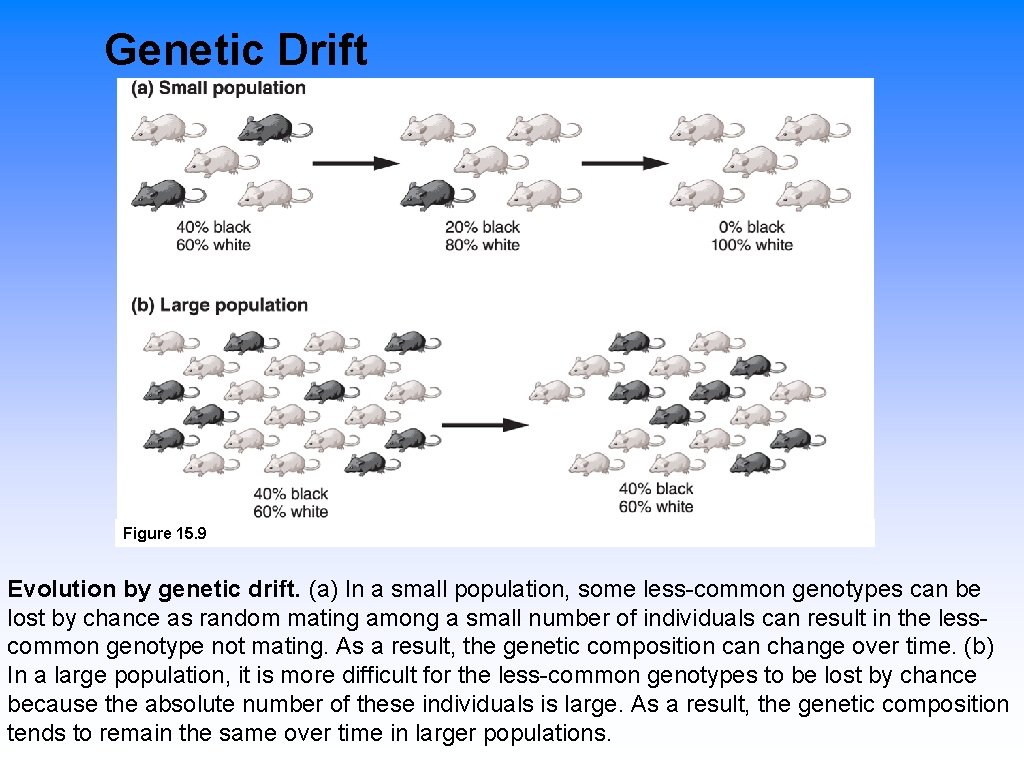
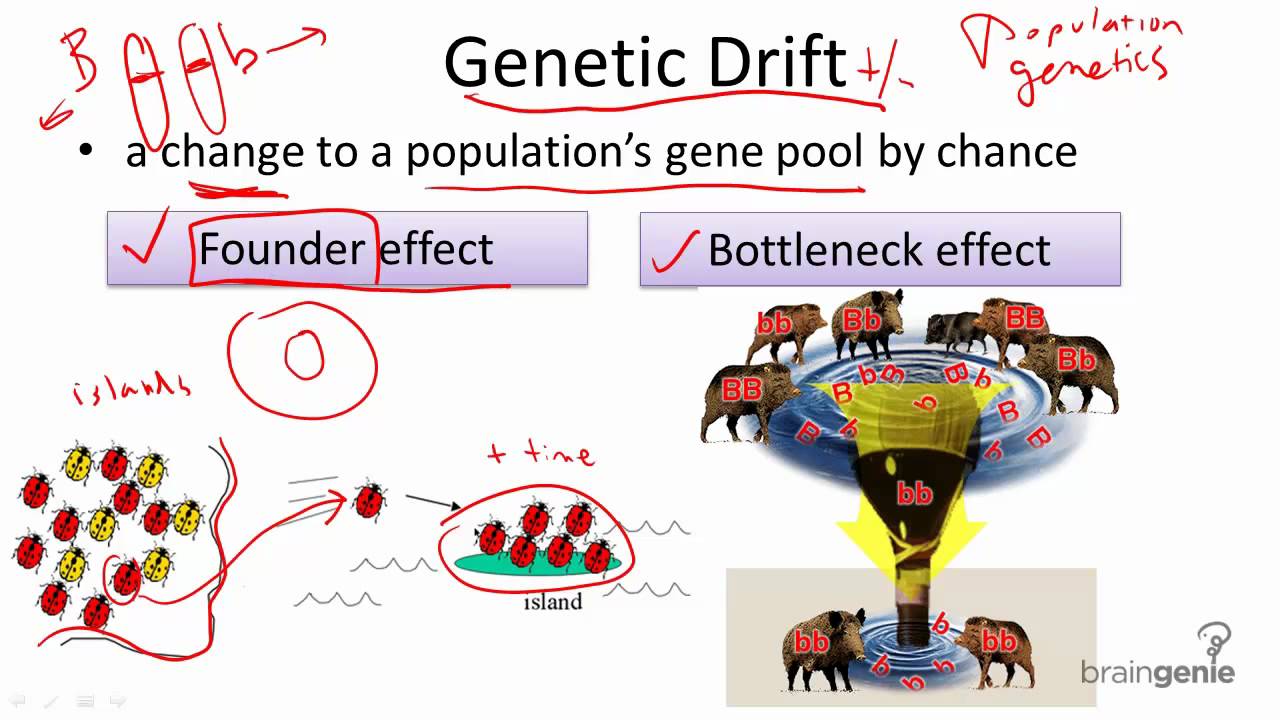
Most people think evolution is all selection and adaptation. It isn't. The bulk of genomic change across most species is driven by noise, not optimization. I ran population genetics simulations for years before I actually understood how much drift dominates in real datasets. Here is what you need to know if you are trying to work with it practically. Genetic drift is the change in allele frequency due to sampling error from one generation to the next. It is not fancy. It is literally the mathematical consequence of finite population size. The smaller the population, the larger the variance in allele frequencies between generations. That is the entire mechanism. There is no hidden complexity. You can model it with a binomial distribution and nothing more. The effective population size, Ne, is the parameter that matters, not the census population size. I have seen researchers use census counts and get completely wrong predictions because their populations had highly skewed sex ratios or variable reproductive success. In my own work on a Drosophila experimental evolution line, the census size was around 5,000 but the effective size came out closer to 600 based on variance in family sizes. That single number changed every projection I made. Drift was about eight times stronger than the raw headcount suggested.
There are two standard ways to approach this. If you want quick analytical approximations, start with the Wright-Fisher model. It assumes non-overlapping generations, random mating, and constant population size. From there you can calculate fixation probabilities and expected time to fixation using the standard formulas. The fixation probability of a neutral allele starting at frequency p is just p. The expected time to fixation for a neutral allele in a diploid population is approximately 4Ne generations. These are back-of-the-envelope equations that are still useful despite how crude they are. If you need realistic output with overlapping generations, variable demography, or selection interacting with drift, you use an individual-based simulation. I write mine in Python with NumPy for the allele frequency updates and use vectorized operations rather than loops. A simple Wright-Fisher simulation with 10,000 individuals and 1,000 generations runs in under two seconds on a standard laptop. When I first started, I was using R and it took four minutes for the same run. The language choice matters less than whether you vectorize your sampling step. One detail that trips everyone up is mutation-drift equilibrium. People often simulate drift in isolation and then wonder why heterozygosity keeps dropping to zero. Without mutation reintroducing variation, drift always wins. The equilibrium heterozygosity under the infinite alleles model is approximately 4Neµ divided by 1 plus 4Neµ, where µ is the per-generation mutation rate. If 4Neµ is much less than one, which is typical for most nuclear DNA in large populations, then heterozygosity at equilibrium is roughly 4Neµ. For humans with Ne around 10,000 and µ around 1.2 times ten to the negative eighth per base per generation, this gives a very small number per site, which is why we rely on many sites to get meaningful diversity estimates.
Here is a practical problem I ran into last year. I was analyzing reduced-representation sequencing data from a wild fish population and trying to distinguish drift from selection using FST outliers. The standard was to generate a neutral null distribution through coalescent simulation and flag loci that fell outside the 99th percentile. But the library preparation introduced a consistent bias that made certain loci appear more differentiated than they actually were. The bias was technical, not biological. I solved it by including a set of known neutral reference loci from a closely related population and recalibrating the FST distribution empirically instead of relying on the simulated null alone. This shifted the outlier threshold and eliminated about sixty percent of the false positives I had initially flagged. Another thing beginners miss is that genetic drift and selection are not separate forces. They operate simultaneously. The strength of selection relative to drift is determined by the product of Ne and the selection coefficient s. When the absolute value of Ne*s is much greater than one, selection dominates. When it is much less than one, drift swamps selection. This means that in small populations, even beneficial mutations with moderate selection coefficients can be lost purely by chance, and slightly deleterious mutations can reach fixation. This is Muller's ratchet in action, and it is why small isolated populations accumulate genetic load over time. I saw this directly in a captive breeding program where the effective size was around fifty. Deleterious alleles that should have been purged were fixing at rates consistent with neutral drift, and the population showed reduced fitness across multiple generations even though no obvious selection pressure was acting on it. For implementation, I recommend starting with a simple forward-time simulator before jumping into anything complicated. Here is the core logic you need. Initialize allele frequencies at some starting value. For each generation, sample the next generation's alleles from a binomial distribution with parameters equal to twice the population size and the current allele frequency. Add mutation if your model includes it. Track fixation and loss events. Repeat for as many generations as needed. This takes maybe thirty lines of code and gives you everything you need to understand the basic dynamics.
Get the Full Details
If you want a ready-made tool rather than writing your own, msprime is the standard for coalescent simulation and it handles large-scale demographic models efficiently. For forward-time simulations with more biological realism, SLiM is the go-to framework. It supports complex life histories, spatial structure, and selection models. Both are open source and well documented. I use SLiM when I need to model selection alongside drift in structured populations because the coalescent approximations in msprime break down when selection is strong and population structure is complex. One important limitation to understand. Genetic drift models assume random mating. Real populations rarely mate randomly. Inbreeding, population structure, and assortative mating all change the dynamics in ways that a simple Wright-Fisher model does not capture. If your study system has any of these features, you need to incorporate them into your model or your drift estimates will be biased. I learned this the hard way when working with a plant species that had strong selfing behavior. The effective population size was dramatically lower than expected under random mating, and my initial drift-based predictions of diversity were off by a factor of three until I adjusted the model for the selfing rate. The biggest practical challenge with drift analysis is getting a reliable estimate of Ne from empirical data. Methods based on linkage disequilibrium, temporal allele frequency changes, and heterozygosity excess all exist, but they make different assumptions and can give conflicting results. I usually run two or three methods in parallel and compare the estimates. If they agree within an order of magnitude, I have reasonable confidence. If they span two or more orders of magnitude, something about the population history or the data quality is wrong and I need to investigate further before drawing conclusions.
Understanding drift matters because ignoring it leads to false inferences about selection. Genome-wide scans for selection that do not account for demographic history produce enormous numbers of false positives. Population bottlenecks, expansions, and structure all leave signatures that look superficially like selective sweeps. The correct approach is to build a demographic model from neutral loci first, then test for selection against that background. This is standard practice now, but I still see papers that skip it and claim selection based on patterns that are entirely consistent with drift under a plausible demographic scenario. If you are just starting out with this, read Charlesworth and Charlesworth's Foundations of Population Genetics Theory for the mathematical foundation. For practical simulation work, the SLiM manual and the msprime documentation are better than most textbooks because they show real use cases with actual data. Start small. Simulate a single locus in a population of constant size. Watch alleles fix and disappear. Then add mutation. Then add structure. Then add selection. Each step reveals how the forces interact, and the simulations make the theory concrete in a way that equations alone never do.