What Happens When Government Services Actually Move in Real Time
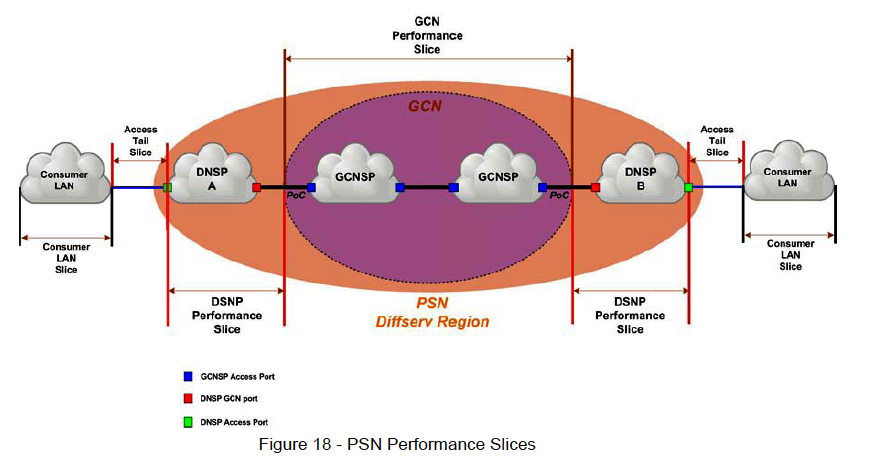
I spent about three years working on a municipal data integration project where the city wanted to replace batch processing with live streaming pipelines. The original plan was straightforward on paper. Route utility outage reports from field workers through a Kafka cluster, push them into a public dashboard within thirty seconds, and auto-generate citizen complaint tickets. What actually happened was slower, messier, and more interesting than the architecture diagram suggested. "PSN" in this context doesn't refer to anything gaming-related. It stands for Public Services Network, which is really just the infrastructure layer that connects government back-office systems to external-facing digital services. The revolution part is simply that these networks stopped being weekly batch updates and started pushing data continuously. That shift changed how people interact with almost everything from transit schedules to benefits applications. Here is how it works in practice. You have event sources — sensors, form submissions, payment processors, GIS updates — all producing data points. Those feed into a streaming platform. Usually Kafka, sometimes Pulsar if the dataset is massive and you need built-in schema enforcement. From there, a stream processor enriches and routes the events to downstream consumers. A citizen-facing app might subscribe to transit delays. A back-office dashboard might subscribe to permit application status changes. A fraud detection model subscribes to benefit payment patterns. Everything happens concurrently. No waiting for end-of-day jobs.
The technical setup looks like this. You provision a message broker cluster with at least three nodes for any production deployment. Create topics with appropriate partitioning — I've seen cities use one partition per municipality district, which gives you parallelism without overcomplicating things. Set up change data capture on your relational databases using something like Debezium so every INSERT, UPDATE, and DELETE becomes an event. Build stream processing jobs in a framework like ksqlDB or Flink to transform raw events into the shapes your applications actually need. Deploy consumer services behind an API gateway with rate limiting and authentication. That's the skeleton. The bone broth is figuring out what falls apart when twelve thousand residents update their address simultaneously during a policy change announcement. I remember one specific incident in 2022 when a new housing subsidy program launched and our subscriber count for the eligibility-check endpoint jumped from roughly four hundred requests per minute to about eighteen thousand in under sixty seconds. The API gateway held. The stream processor lagged by about forty-five seconds on some partitions because we had undersized consumers and a partition skew issue — most events landed on partition three since the geographic key wasn't evenly distributed. We worked around it by switching to a composite key that included a randomizer suffix, which spread the load across all twelve partitions and cut the lag to under three seconds. Took us about six hours to implement. The alternative would have been a support ticket backlog that would have lasted a week. One thing nobody warns you about is the idempotency problem. In batch systems, if a record fails to write, you retry it and the database just updates the same row. In streaming systems, the same event can arrive multiple times due to at-least-once delivery guarantees. If you're processing a benefit claim submission and the event fires twice, you just created a duplicate claim. The fix is straightforward but easy to miss. Every event needs a unique ID, and your downstream processors should check for duplicates before acting. We store event IDs in a Redis cache with a TTL of about twenty-four hours. Check first, process after. Cost is negligible. Saved us from a class-action-level embarrassment.
Another counter-intuitive reality is that real-time doesn't always mean faster for the end user. Sometimes it means more accurate, which is different. A transit app that shows a bus location updated every thirty seconds feels better than one that loads a static schedule refreshed every fifteen minutes. But for something like a licensing application, the real-time part isn't about speed. It's about the applicant seeing their status change the moment a clerk approves it instead of waiting for the next batch run, which might be hours away. The perceptual difference for citizens is significant even if the actual latency improvement is measured in seconds rather than days. There are real downsides to this approach and they're not subtle. Operational complexity increases roughly quadratically compared to batch systems. You need monitoring for consumer lag, producer throughput, schema compatibility, and dead letter queues. Your on-call rotation goes from "check the logs in the morning" to "the payments stream is stuck again." Cost scales with traffic in a way batch processing doesn't — a Kafka cluster running idle at 3 AM still costs money. Schema evolution becomes a genuine engineering problem because every consumer needs to handle changes gracefully, and you can't just push a database migration and move on. Data quality issues surface faster and louder. In a batch system, bad data sits in a staging table until someone notices. In a streaming system, bad data flows directly into your public dashboard and your fraud detection model at the same time. We had a case where a malformed GPS coordinate from a field sensor sent bus locations to the middle of a lake for about four hours before anyone noticed. The workaround was a validation layer that checks schema and value ranges at the edge of the stream, dropping or quarantining anything that looks wrong before it reaches consumers.
Get the Full Details
If you're considering building something like this, here is the order that actually works. Start with the consumers, not the events. Interview the people who will read the data — caseworkers, dispatchers, app users — and map out exactly what they need and how fresh it has to be. Then identify the event sources that can produce that data. Build the streaming pipeline for just one use case first. Get it running, get it monitored, get it to a point where your team can handle an incident at 2 AM without panic. Then add the next use case. Most cities try to do everything at once and end up with twelve half-working pipelines and no one who understands any of them. The tools available today make this substantially easier than it was even five years ago. Managed Kafka services like Confluent Cloud or AWS MSK remove the infrastructure burden. CDC connectors handle database replication without custom code. Stream processing frameworks have matured to the point where a well-written Flink job can handle complex event processing with state management and exactly-once semantics out of the box. The hard part isn't the technology anymore. It's the organizational alignment required to get different departments — IT, operations, policy, frontline staff — to agree on what data matters and how it should flow. For personal daily life, the impact is mostly invisible until it breaks. You notice real-time public service data when your transit app tells you a train is delayed before you reach the platform, when your parking permit renewal confirms instantly instead of generating a five-day processing wait, or when a road closure appears on your navigation app the moment the department of transportation logs it. You don't notice it when it works because the alternative — waiting, calling, showing up to a closed office — is what you remember from before.
The trajectory is clear and it's not going back. More government functions are moving from periodic reports to continuous data streams. The trick isn't building the pipeline. It's building one that survives when the data volume spikes unexpectedly, when a schema change breaks three downstream consumers, and when the person who designed the partitioning strategy leaves for a job at a startup.