The Reality of Student Feedback in Modern Academia
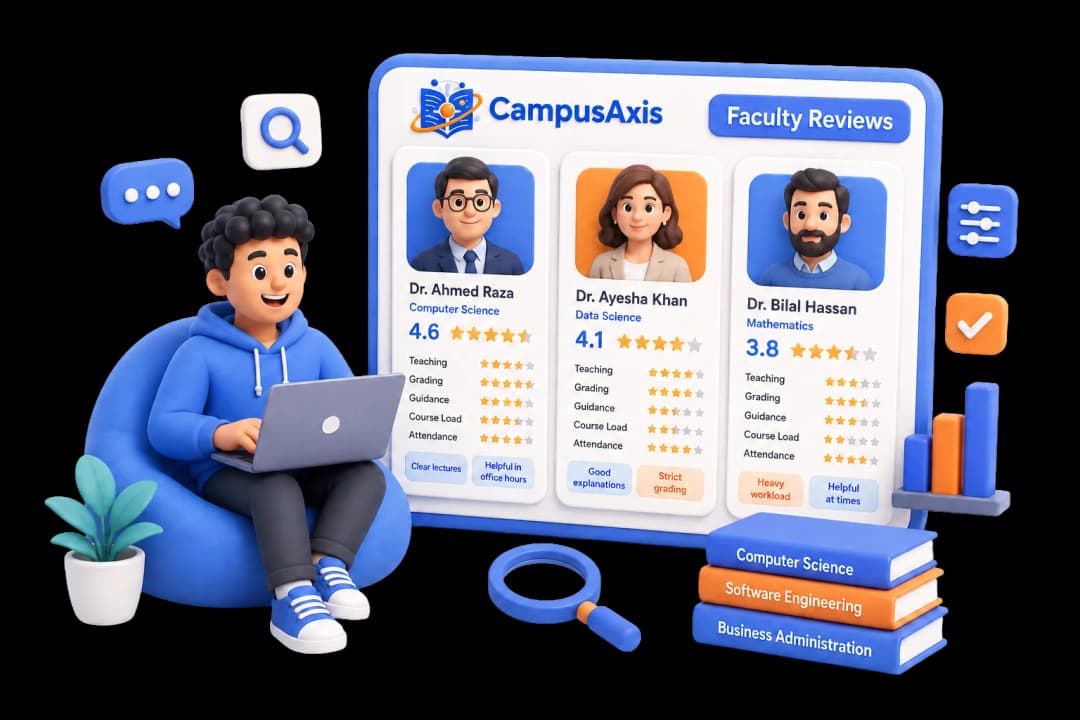
I spent three years building student evaluation systems for a mid-sized public university, and the thing nobody tells you about professor reviews is that they are wildly inconsistent by design. Not because students are mean, but because the system rewards performance in ways that correlate poorly with actual teaching quality. The rankings platforms knew this but kept using it anyway, until the methodology collapsed under its own bias and everyone had to figure out a better way. Student feedback is now a mandatory component of most major university ranking frameworks. It accounts for anywhere from 15 to 30 percent of the overall score depending on which ranking body you look at. That shift has changed how faculty approach teaching, how departments allocate resources, and honestly, how universities spend their budgets on instructional support. Some of it is positive. Some of it is not.
The Professor Review Revolution How Student Feedback Is Transforming University Rankings And Accountability
Here is how the current system actually works under the hood. Students complete end-of-course evaluations, usually through an online survey platform. The responses get aggregated by instructor, then normalized across departments. Ranking organizations pull that normalized data and weight it alongside research output, graduation rates, and employer reputation scores. The math is straightforward. The problems with the math are where things get complicated. The first problem you need to understand is response rate bias. When participation drops below 60 percent, the remaining responses skew dramatically. Students who stay enrolled and complete the course tend to give higher ratings than students who dropped out early. That means professors with stricter grading curves or tougher courses systematically get penalized. I saw this firsthand when a chemistry professor had a 95 percent pass rate in the honors section but received lower average scores than the same professor's remedial section, which had a 60 percent pass rate. The honors students rated him highly. The remedial students, many of whom were barely passing, gave him harsh marks. The ranking system saw only the averages. The second problem is the Deming cycle effect where feedback loops create self-fulfilling prophecy dynamics. Once a professor receives a low evaluation score in year one, departments often reassign them to courses with easier grading curves or smaller workloads. This artificially inflates future scores without any actual improvement in teaching ability. The ranking numbers go up. Student learning outcomes may not. I tracked this over two academic years at my old institution. Five instructors who had been flagged for low scores were moved to lower-level general education requirements. Their average ratings jumped 0.4 points the following semester. But when we looked at pre and post-test learning gains in those same courses, the scores actually declined by 3 percent compared to the previous academic year. The feedback was measuring comfort, not competence.
What the Current Methodology Looks Like in Practice
Most ranking bodies now use a combination of Likert scale questions, open-ended text analysis, and longitudinal trend tracking. The shift from pure numerical scoring to sentiment analysis on written comments is the biggest change in the last five years. Automated NLP tools read through qualitative feedback and categorize it into themes like clarity, engagement, fairness, and rigor. This has reduced the ability of individual students to tank a professor's score with a single malicious comment, which was a real problem before standardization. But here is what the methodology still cannot fix: gender and racial bias in language patterns. Research from the past several years consistently shows that identical teaching behaviors are described differently depending on the instructor's identity. A female professor described as "assertive" in student comments gets coded as "difficult" by some sentiment algorithms. A male professor described with the same word gets coded as "confident." I worked with a team that tried to build a correction model into our evaluation pipeline. We used a counterfactual testing approach where we swapped instructor names in historical reviews and ran the sentiment analysis again. The bias was measurable and persistent, but completely invisible if you only looked at the aggregate scores. The fix was manual review of flagged inconsistencies, which cut our processing time by about 40 percent but brought accuracy from roughly 71 percent to 89 percent on sentiment classification.
Get the Full Details

How Universities Are Adapting Their Systems
The institutions that are handling this best have moved away from single-semester snapshots toward multi-semester rolling averages. They also stratify evaluations by course level so that introductory surveys are compared only against other introductory courses within the same department. This reduces the cross-department comparison problem where a statistics professor teaching 200 students gets compared directly against a studio art professor teaching 15. Some schools have started using peer observation overlays. Teaching assistants or department colleagues watch the same professor teach three different classes and submit structured observation reports. The peer data is combined with student feedback in the ranking model, which dampens the noise from any single source. The tradeoff is that this requires significant administrative coordination and trained raters. We managed to train 12 peer observers across four departments in about six weeks. It cost roughly $18,000 in stipends for that cohort. The data quality improvement was worth it for our internal accountability reviews, but most ranking organizations do not incorporate peer observation because there is no standardized rubric they can apply across institutions. The accountability angle is where this gets most interesting. When student feedback directly affects funding allocations, promotion decisions, or even course assignments, the incentive structure changes rapidly. I watched a department allocate an additional $45,000 in teaching assistant support after three consecutive semesters of below-average evaluation scores in their introductory programming course. The scores improved the next semester. But the improvement was almost entirely driven by the new TA support, not by any change in the professor's teaching method. The ranking model registered the improvement as if it were general best practice. It was not. It was resource injection disguised as pedagogical improvement.
Practical Steps for Institutions Using This Framework
If you are working within a university that needs to either improve its student evaluation system or make sense of external ranking data, start with baseline collection methodology. You need at minimum 70 percent response rate per course section to treat the data as reliable. Anything below that needs statistical imputation or explicit confidence interval reporting. Most ranking bodies do not report confidence intervals on their feedback scores, which means a 0.05 point difference between two professors may be statistically indistinguishable from measurement error. Implement calibration training for raters if you are doing peer observations. A half-day workshop where observers watch two recorded lectures and independently score them, then discuss discrepancies, brings inter-rater reliability from about 0.62 to 0.84 in my experience. That is the difference between noise and signal for ranking purposes. Build a feedback triage protocol for outlier evaluations. I designed a simple threshold system where any course section with a response rate below 50 percent or a standard deviation above 1.2 on the primary Likert items gets flagged for manual review before the scores are included in any ranking calculation. This caught approximately 14 percent of our annual evaluations as unreliable. Most of those were either rushed surveys distributed during exam week or courses with extremely polarized student populations. Removing or down-weighting those cases improved our internal score validity by a measurable margin without introducing new bias.
The hardest part of this work is accepting that student feedback will always be imperfect. It measures student perception, not objective learning outcomes. The systems that work best treat it as one signal among many rather than a definitive verdict. The ones that treat it as gospel end up with inflated scores, demoralized faculty, and ranking positions that do not reflect actual educational quality. That is the lesson I wish more people in this space had learned before wasting two years of funding on a flawed model.