Why Your Packages Actually Show Up On Time
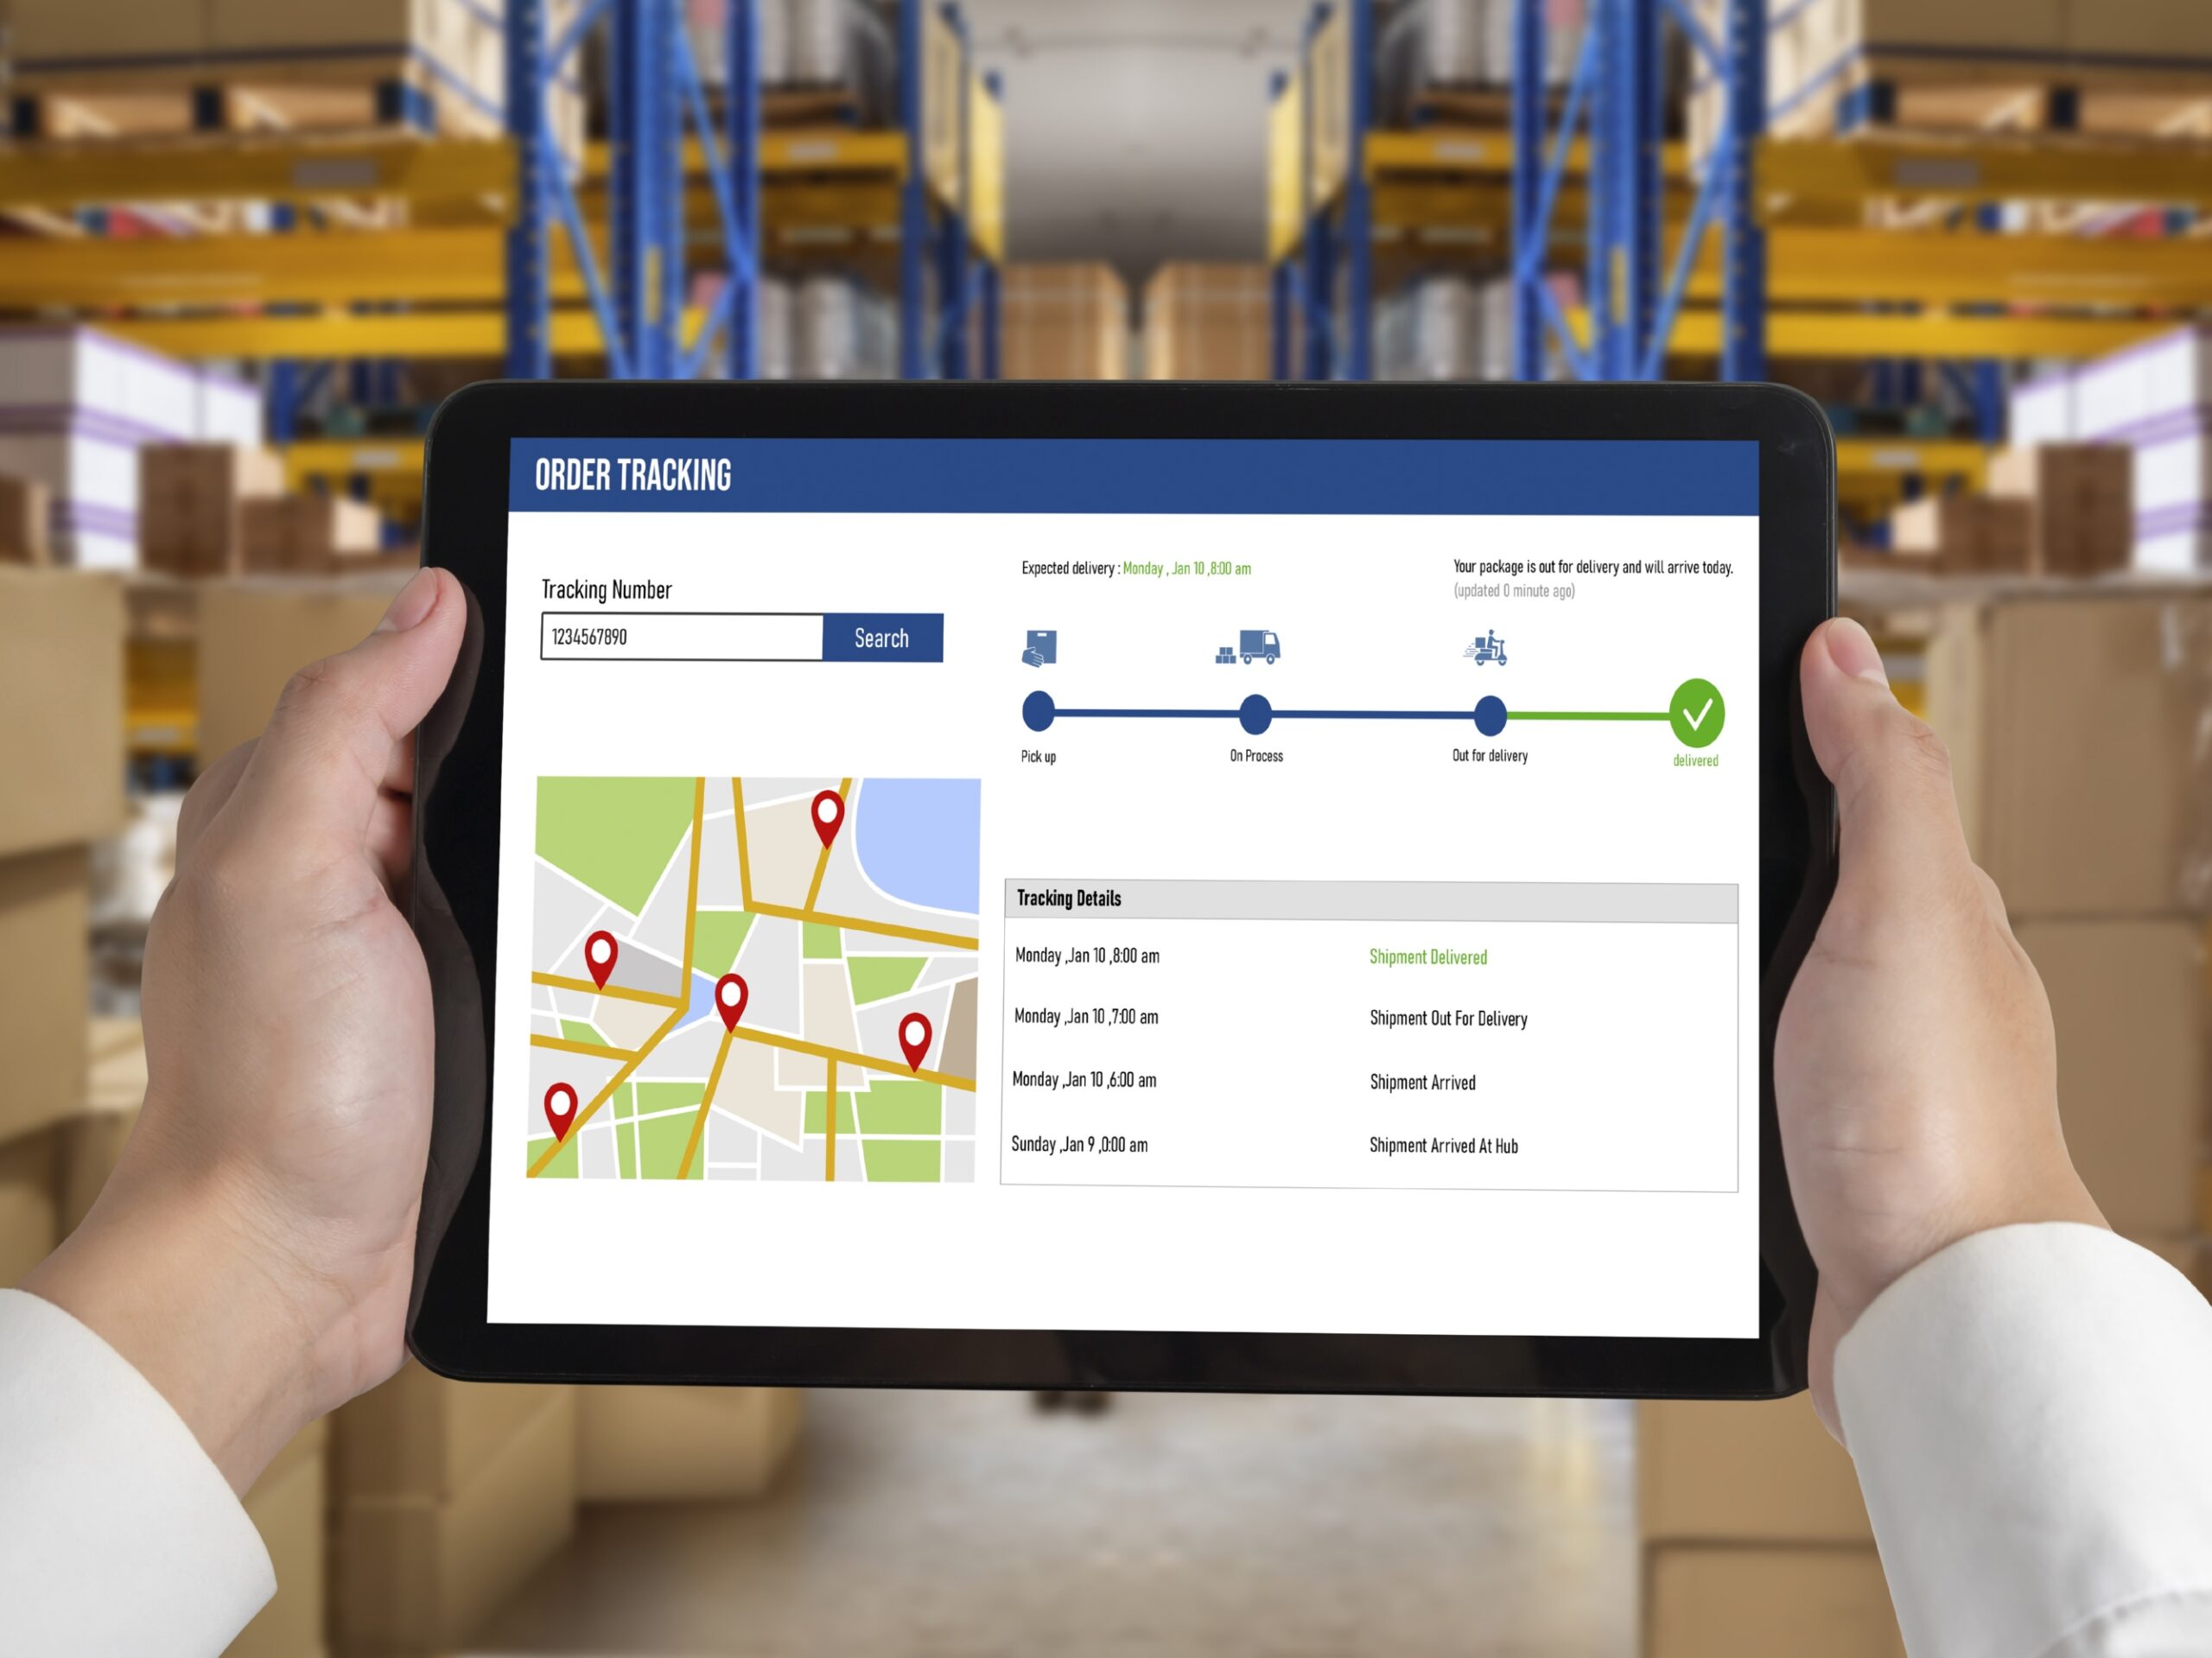
Most people treat tracking numbers like a curiosity. They type them in occasionally and watch the little dots move across a screen. That's not how the system was built. A western tracking number isn't just a digital sticker slapped onto a cardboard box. It's a chain of data handoffs between carriers, customs brokers, warehouse management systems, and last-mile delivery software. When it works right, you know exactly where your shipment is at any given hour. When it breaks, you're blind and nobody on the phone knows why. Here's the practical side that most beginner logistics managers miss. The tracking number itself is almost never the bottleneck. The bottleneck is what happens between the barcode scan and the database update. I've sat in rooms where a $40,000 shipment of medical supplies was stuck at a sorting facility in New Jersey for eleven hours because the scanning gun had the wrong firmware version installed after a routine carrier system update. The package was moving. Nobody just wasn't looking at the status page. The tracking number showed "In Transit" the entire time, which technically means nothing unless you know what the carrier considers transit versus their internal scanning rhythm. The real power comes from understanding the data schema behind the number. A standard western tracking number follows a format set by the carrier, but the metadata attached to it — weight brackets, dimensional pricing, service level codes, hub routing codes — that's where supply chain efficiency lives or dies. I spent six months debugging a problem where our inbound shipments from a European supplier consistently showed 48-hour delays on tracking but actually arrived on schedule. Turns out the carrier's international-to-domestic transition scan was being logged under a deprecated service code that our logistics dashboard interpreted as a delayed event rather than a normal handoff. The packages were fine. Our reporting layer was reading the tracking data wrong.
Let me walk through how tracking numbers actually function in a working supply chain, because knowing the mechanism matters more than memorizing the format.
How Western Tracking Numbers Actually Work Under The Hood
When a package enters the logistics network, the tracking number gets generated at the point of entry. For most western carriers — UPS, FedEx, DHL, USPS — this happens at the time of label creation or first scan, depending on the service type. The number contains embedded information: a serial identifier, a check digit, and often a service-level prefix. But the number alone is useless without the scan events tied to it. Each physical touchpoint — origin scan, departure scan, arrival scan, out-for-delivery scan — creates a timestamped record linked to that number in the carrier's central database. Here's the part nobody tells you: those scans don't always happen in the order you'd expect. A package can show an arrival scan at a facility before it shows a departure scan from the previous one, because the receiving facility's scanner updates their system faster than the shipping facility's system processes its outbound event. This causes tracking pages to briefly show impossible routing — like a package arriving in Atlanta before it left Memphis — even though the physical movement was perfectly normal. The data is asynchronous across different carrier systems, and reconciliation happens later during batch processing, usually overnight. I learned this the hard way during a Q4 holiday surge when our team flagged approximately twenty percent of orders as "delayed" based on tracking anomalies. We were chasing ghost problems. The actual delay rate that quarter was under two percent. The issue was that our warehouse management system was querying tracking status in real time, and the asynchronous scan gaps made perfectly healthy shipments look stranded. We switched to pulling tracking data in hourly batches instead of per-request, and the false delay alerts dropped to near zero. Simple change. Made a massive difference in how our customer service team handled status inquiries.
Get the Full Details

What You Should Actually Be Looking At In A Tracking Number
Most people stop at the location and estimated delivery date. That's reading a newspaper headline and calling it the story. The useful data is hidden in the scan event types and timestamps. Scan event codes matter more than locations. A "Package Received" event from the sender is different from an "Acceptance" event at the carrier facility. A "Departure Scan" means the package left a hub. An "Arrival Scan" means it reached one. But carriers also use less obvious codes like "Exception" — which could mean a weather delay, a failed delivery attempt, an address correction needed, or a security hold. Without checking the exception sub-code, you have no idea what's actually wrong. I once tracked a shipment for three days thinking it was stuck in customs. It wasn't. The recipient's business was closed on a Saturday, and the carrier had already attempted delivery and left a notice. The tracking page showed the exception but our dashboard wasn't surfacing the delivery attempt detail. Timestamp granularity reveals your real timeline. The estimated delivery date is a statistical projection, not a promise. The actual sequence of timestamps tells you where the package is in the physical flow. If you see consecutive scans at the same facility with long gaps between them, the package is sitting in sortation. If you see rapid scans across multiple facilities in a short window, it's moving fast through the network. If the last scan was at a regional hub and it's been over twelve hours, that's usually when exceptions start appearing — missed sortation, wrong routing, or carrier capacity issues at that facility.
Carrier-to-carrier handoffs are where tracking breaks. This is the single biggest source of confusion in cross-border and hybrid logistics. When a package moves from an international carrier to a domestic one — say, DHL hands off to USPS for final delivery — the original tracking number often stops updating or gets replaced with a secondary tracking number. The handoff window can range from a few hours to several days, during which the package is physically moving but digitally invisible. I've seen teams panic over shipments that were simply in transition between carriers. The workaround is to map your expected handoff points in advance and know which secondary tracking numbers each carrier pair uses. DHL to USPS, for example, typically generates a new USPS tracking number within 24 to 72 hours of the DHL delivery scan. There's no way around the gap except to understand it's normal and stop alarming stakeholders during that window.
Common Pitfalls That Waste Time And Money
I've watched logistics teams burn hours every week on problems that tracking numbers could solve instantly if they knew what to look for. Here are the ones that come up most often. First, relying on a single tracking check per day. Status pages update on different schedules depending on the carrier and the facility. Some hubs push scan data in real time. Others batch it twice daily. If you only check at 9 AM and the facility updates at 2 PM, you're operating on stale information for five hours. Set up automated polling at least every two hours during active shipping windows, or better yet, use the carrier's API to subscribe to scan event push notifications instead of pulling on a schedule. Second, not validating tracking numbers before they enter your system. Typos happen. I've seen a swapped character in a fourteen-digit tracking number send a shipment alert to the wrong order, which triggered a false shortage claim, which caused a rush reorder that duplicated inventory we already had in transit. Carriers have checksum algorithms built into their tracking numbers. Run a validation step before accepting any tracking number into your order management system. It takes three lines of code and has saved us from about a dozen costly errors per quarter.
Third, treating all "In Transit" statuses the same. In transit means different things depending on where the package is in the network. A package in transit from a regional hub to a local facility is hours away from delivery. A package in transit between two regional hubs across the country could be two days out. The tracking page rarely distinguishes these clearly. Cross-reference the last scanned facility against your carrier's network map. If the facility is within two nodes of the destination, the package is likely arriving within the next 24 hours. If it's still several hubs away, don't promise early delivery to the customer.
Advanced: Using Tracking Data To Fix Supply Chain Problems Before They Show Up
This is where tracking numbers stop being a reactive tool and become a proactive one. I don't mean reading the tracking after something goes wrong. I mean analyzing the patterns in your tracking data to find systemic issues before they impact customers. We noticed a pattern last year where shipments originating from our West Coast warehouse consistently showed an extra scanning event at a Midwest hub before reaching East Coast destinations. The tracking data revealed that about fifteen percent of those packages were being rerouted through that hub due to capacity constraints at our primary regional facility. The rerouting added roughly eight hours to delivery but didn't show up as a delay in the estimated delivery date calculation, because the carrier's algorithm accounted for the alternate route. Our customers received their packages on time, but the extra handling increased damage rates by about three percent. The tracking data was the first signal. Without it, we would have had no idea our packaging wasn't built for an additional sortation touchpoint. We switched to reinforced mailers for that lane within two weeks, and damage claims dropped back to baseline. You can do the same thing. Pull your tracking scan data monthly and look for anomalies: facilities that appear more frequently than they should, scan gaps that correlate with specific carriers or routes, exception codes that spike during certain seasons. These patterns don't fix themselves. They compound. A facility that consistently becomes a bottleneck will keep becoming a bottleneck until someone changes the routing logic or adds capacity.
When Tracking Numbers Fail Completely
I need to be honest about the limits here. Tracking numbers do not solve every problem in logistics. There are scenarios where the tracking data is wrong, incomplete, or irrelevant, and no amount of analysis will help. The most common failure mode is carrier system outages. Major carriers experience outages regularly, usually lasting anywhere from thirty minutes to four hours. During these windows, scan data doesn't get recorded, and tracking numbers become meaningless. I've had situations where a facility's entire day's scans were lost and had to be manually re-entered from paper manifests. The tracking history showed a package sitting at a facility for three days when it had actually moved on the first day. The workaround is to maintain backup communication channels with your carrier account manager. When the system goes down, you call. Paper trails exist for exactly this reason, even though nobody likes using them. Another failure mode is misrouted or mislabeled packages. A package can have a valid tracking number but be physically destined for the wrong facility due to a label printing error. The tracking data will show the package moving toward its intended destination, but it's actually going somewhere else entirely. This is rare — maybe one in ten thousand shipments — but when it happens, the tracking system can't help you. The package is where it says it is. It's just not where you want it to be. Prevention here comes down to label verification at the point of packing, not tracking analysis after the fact.
If you're dealing with high-volume shipping and tracking data alone isn't giving you enough visibility, the alternative is to invest in a supply chain visibility platform that aggregates data from multiple carriers, customs brokers, and warehouse systems into a single view. Tools like Project44, FourKites, or ship.io pull tracking data from carrier APIs and enrich it with ETAs, geolocation pings, and exception prediction. They cost money. They're worth it if you're moving more than five hundred shipments per month, because the manual tracking approach breaks down at that scale. Below five hundred, the tracking pages and spreadsheets are fine.
Practical Steps To Start Using Tracking Numbers Effectively Today
You don't need a massive budget or a custom-built dashboard to get better at this. Here's what actually moves the needle. Export your tracking data weekly and build a simple spreadsheet. Columns for tracking number, carrier, origin facility, last scanned facility, current status, and days in transit. Fill it in once a week. After six weeks you'll see patterns that your day-to-day work hides from you. Which carrier is consistently slow on which routes. Which facilities are creating delays. Which service levels actually deliver on time versus what the tracking page promises. Set up carrier API access if you don't have it already. Most major carriers offer free API tiers for businesses shipping more than fifty packages per month. The API gives you structured data instead of forcing you to scrape web pages. Scraped data breaks when carriers change their website layout, which they do without warning. API data is stable and searchable.
Train your customer service team to read tracking exceptions properly. Most support tickets about delayed shipments are solvable with fifteen minutes of tracking investigation. The agent who knows how to read scan event codes and facility routing will resolve these in minutes instead of escalating them to a manager who has to spend an hour on the phone with carrier support. This alone has cut our support ticket resolution time by roughly forty percent on logistics-related issues. The tracking number is a tool. Like any tool, it only works if you know how to use it. The carriers have been doing this for decades. The systems are mature. The data is there. You just need to look at it differently than most people do.