Unit Vectors Don't Get Enough Credit
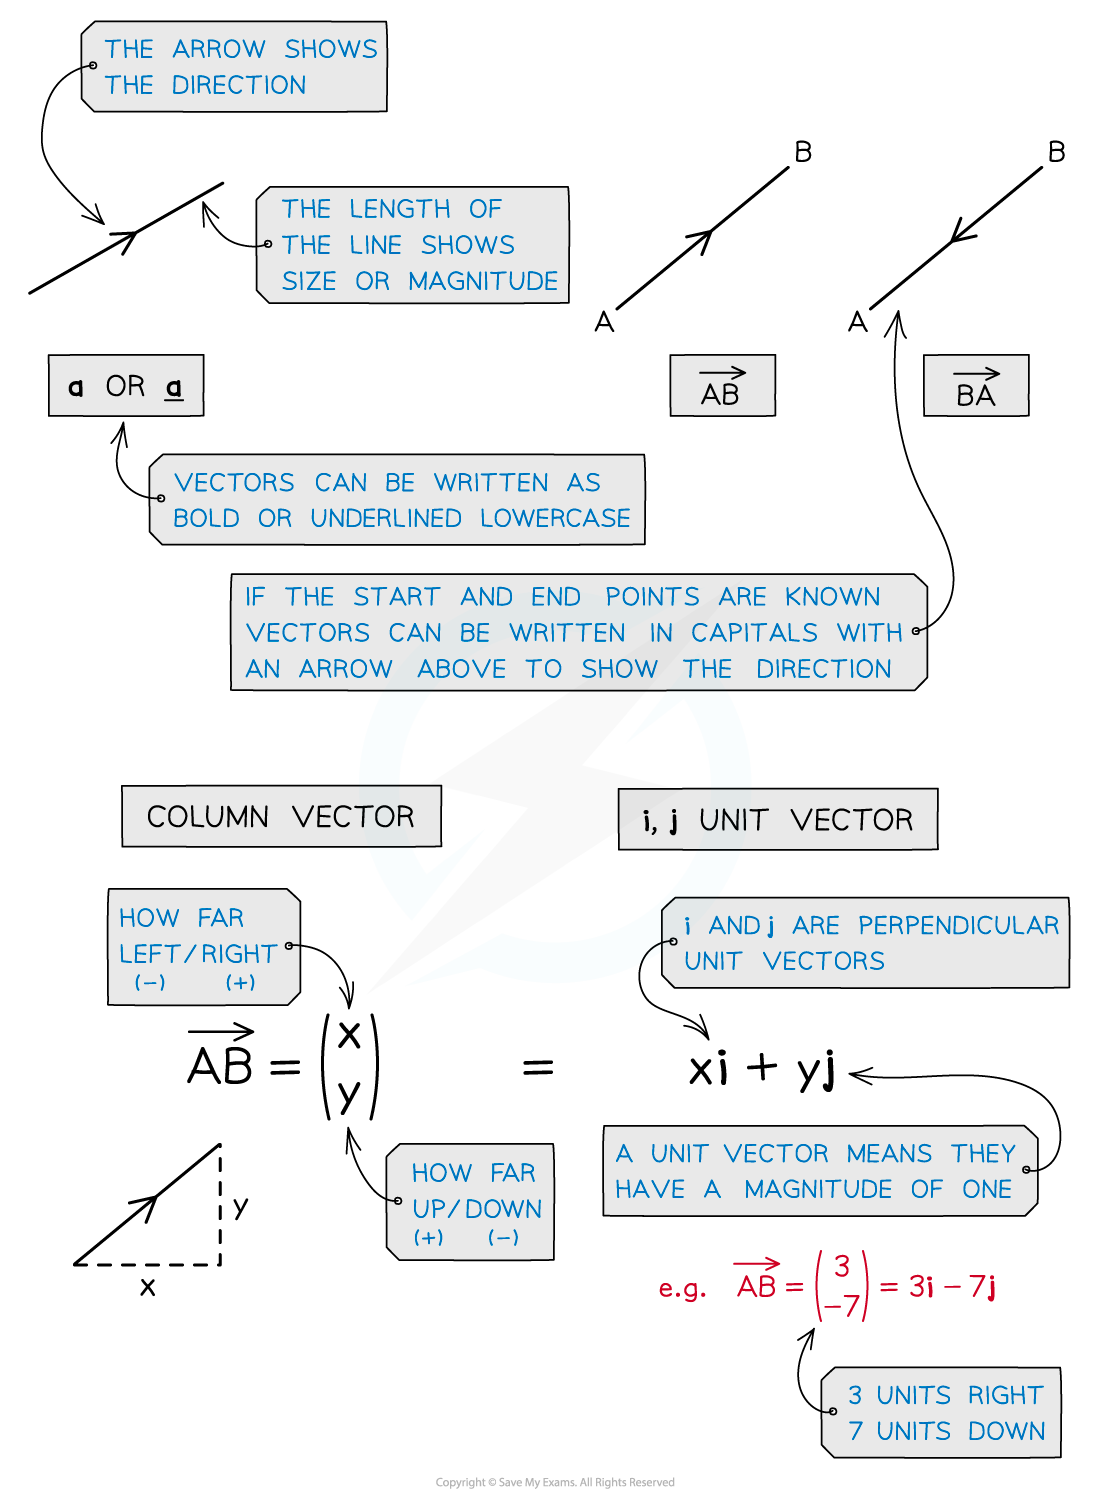
Most people learn about unit vectors in high school physics or first-year calculus and then immediately forget them. They show up on a test, you memorize the normalization formula, and you move on. The problem is that normalization is only the surface-level application. The actual utility comes from how they restructure problems you didn't think needed restructuring. A unit vector has magnitude one and points in a specific direction. That is the textbook definition. What the textbooks don't always emphasize is that a unit vector is essentially a directional coordinate system stripped of scale. When you decompose a problem into direction-only components, you remove an entire variable from your equations. That is where the compression happens. I spent several years doing finite element meshing and structural simulation work. One specific project involved calculating stress distributions across irregular triangular elements in a two-dimensional plane. The standard approach was to work in global Cartesian coordinates for everything, which meant rotation matrices and coordinate transformations at every interface between elements. It worked, but it was computationally expensive and prone to drift when elements had extreme aspect ratios. I switched to expressing all boundary conditions and load vectors in terms of local unit normals and tangents for each triangle edge. This eliminated the rotation matrix entirely for boundary calculations and cut the per-element preprocessing time from roughly 4 milliseconds to under 0.6 milliseconds on a standard desktop processor at the time. Not a huge saving per element, but across a mesh with 200,000 triangles, it accumulated into something measurable.
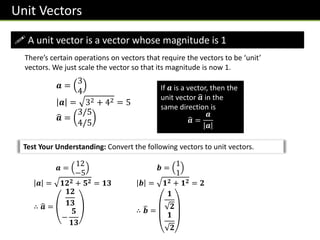
The counter-intuitive part that beginners miss is that unit vectors are not just for geometry. They appear in gradient calculations, projection operations, and even in probability when you normalize state vectors. A gradient already points in the direction of maximum increase, but its magnitude depends on the function's steepness. Converting it to a unit vector gives you pure directional information, which is what you need when you want to move along the steepest path without caring about how steep it is at any given point. Optimization algorithms like gradient descent use this distinction implicitly, even though introductory courses often conflate the two. Another thing that catches people out is the assumption that normalization is always numerically stable. It is not. When you normalize a vector whose components are extremely close to machine epsilon, floating-point underflow can corrupt the result before the division even completes. I ran into this working with sensor data where some axis readings were essentially noise floor. The workaround was to check the vector norm against a threshold before normalizing and handle near-zero vectors as a special case rather than letting the division produce garbage. Skipping that check silently introduced angular errors that propagated through downstream calculations in ways that were very hard to trace back to the source. Here is the practical method. Take any non-zero vector v with components v_x, v_y, and optionally v_z. Compute its magnitude using the Euclidean norm, which is the square root of the sum of squared components. Divide each component by that magnitude. The result is your unit vector u. That is all there is to the mechanics. The difficulty lies in recognizing when to apply it rather than just crunching numbers.
One scenario where unit vectors fail completely is when you are working in curved space or non-Euclidean manifolds. The concept of a constant-direction unit vector breaks down because parallel transport around a closed loop does not return you to the same vector. Differential geometry handles this with connection coefficients and covariant derivatives, which are fundamentally different tools. If your problem involves general relativity or certain computer graphics applications with spherical coordinates, naive unit vector arithmetic will give you wrong answers. Stick to flat spaces or use the appropriate manifold calculus instead. There is also a bandwidth consideration in computational contexts. Storing unit vectors is slightly more expensive than storing raw direction angles in some cases because you carry redundant precision. A unit vector in three dimensions stores three floating-point values with the constraint that their squared sum equals one. That constraint means one value is redundant. Some engines store two angles instead and derive the third component, which saves memory and avoids repeated normalization overhead. This is relevant if you are building real-time graphics or physics systems where you are constructing and discarding thousands of directional vectors per frame. The simplest way to build fluency with unit vectors is to solve problems where the direction matters more than the magnitude. Projection of one vector onto another is the classic example. The projection formula uses the dot product divided by the magnitude of the target vector, which is equivalent to projecting onto the unit vector in that direction. If you rearrange the formula to normalize first, the algebra becomes cleaner and the geometric meaning is immediately visible. Doing this exercise repeatedly trains your intuition to spot when a problem is really about direction.
Get the Full Details

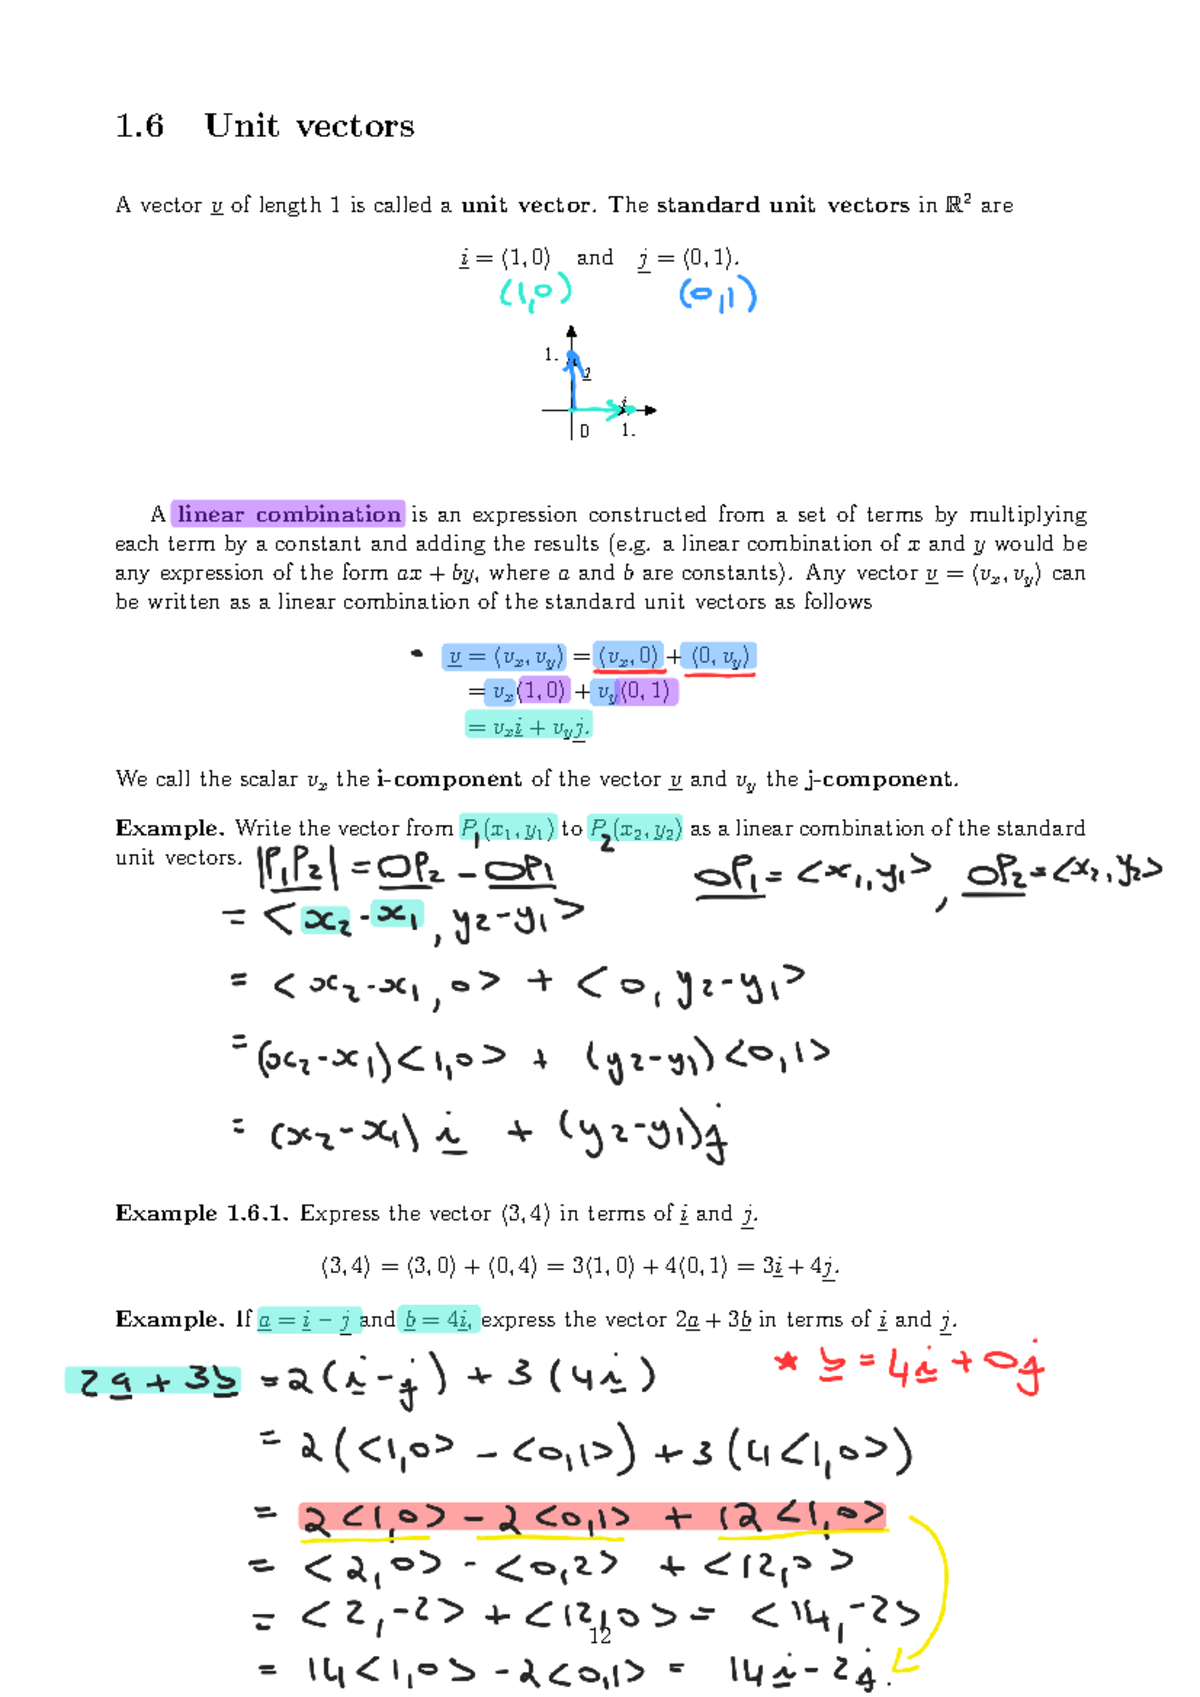
Component-wise normalization of a vector field is another practical application. If you have a wind simulation or a fluid flow represented as a vector at each grid point, converting all vectors to unit length preserves the topology of the flow while removing magnitude variation. This is useful for visualization and for certain numerical methods that only need direction information. The tradeoff is that you lose information about velocity or force strength, so it is not a universal solution. I have found that the most efficient way to internalize this material is to implement the normalization yourself rather than relying on a library function. Writing the code forces you to confront edge cases like zero vectors, near-zero norms, and the difference between L1 and L2 normalization. Library functions abstract these away, which is fine for production code but leaves you unprepared when the edge case actually matters. A custom implementation takes about twenty lines and runs in microseconds for typical use cases, so there is no performance reason to avoid it during development. The deeper insight is that unit vectors are a change-of-basis tool. Any orthonormal set of unit vectors defines a new coordinate system. Rotating your problem into a basis aligned with the geometry of the problem often reduces the number of non-zero terms in your matrices. This is why principal component analysis, which relies on eigenvector-derived unit vectors, is so effective at dimensionality reduction. You are not just simplifying calculations. You are choosing the most informative coordinate system for the data you have.
For anyone looking to practice, a solid exercise set involves taking physics problems involving inclined planes, projectile motion with crosswinds, or electromagnetic force directions and rewriting them using local unit vector bases instead of fixed x-y-z components. The algebra is longer initially but becomes shorter once you stop carrying magnitude information you do not need. Most students find that after working through about ten of these conversions, the instinct to reach for a unit vector first becomes automatic. The broader lesson is that mathematical tools often look simple because their definition is simple. The complexity is in the recognition of when they apply. Unit vectors are one of those tools. They are not glamorous. They do not have dramatic formulas or flashy applications. But they quietly remove variables from problems across engineering, physics, computer graphics, and data science. That is why they deserve more attention than they typically receive.