Why Basic Statistics Still Matter When You're Wading Through Messy Data
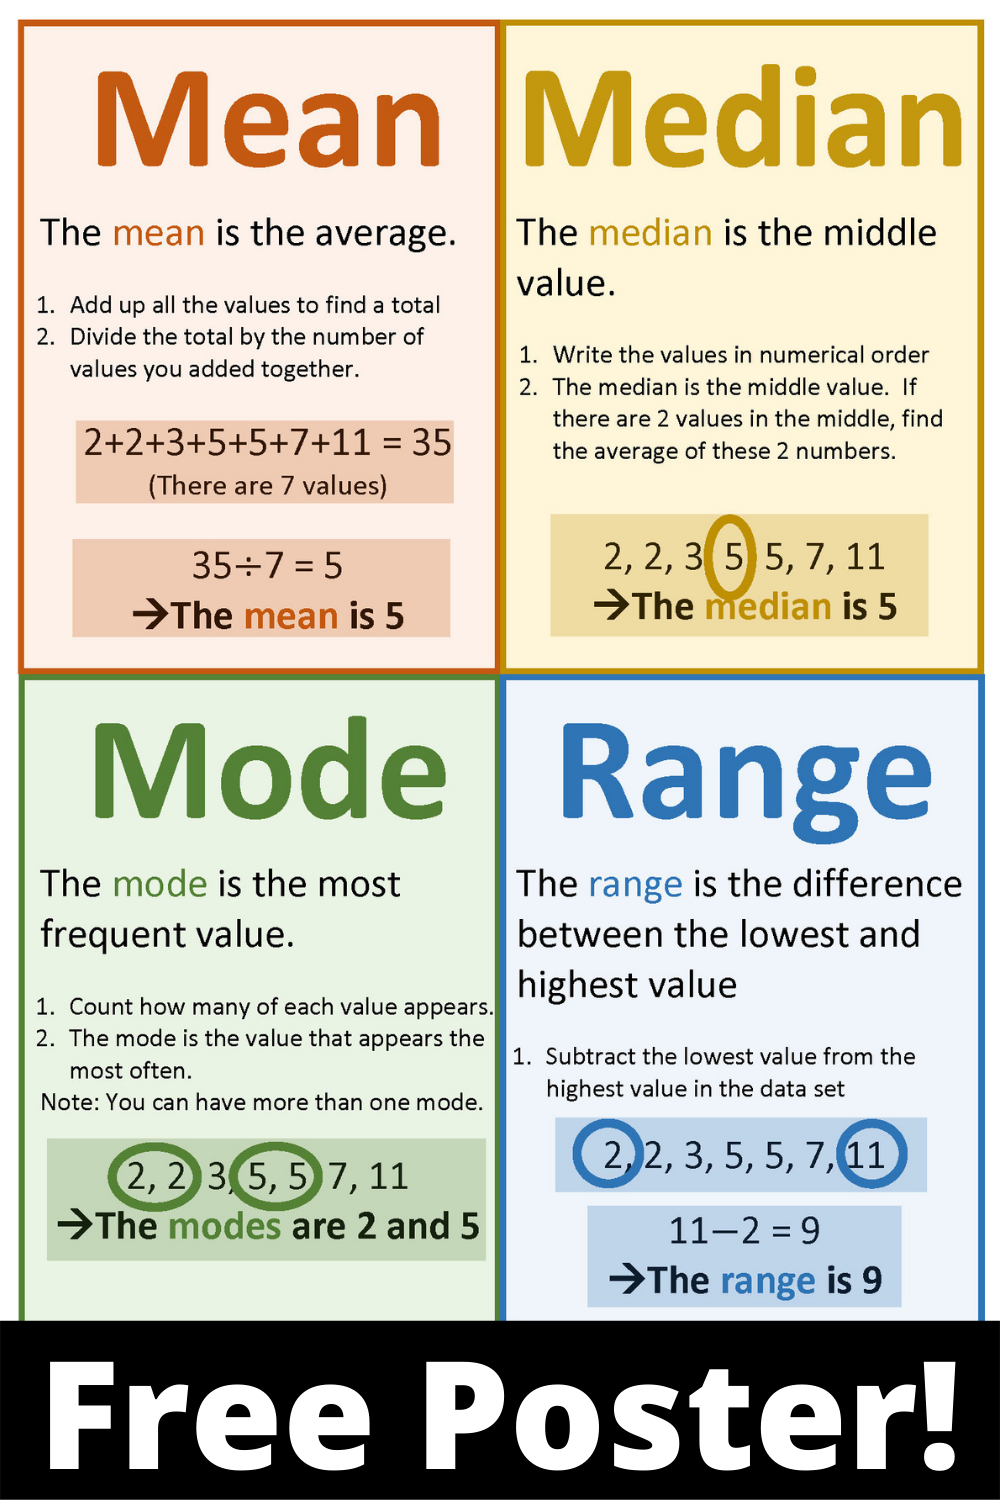
I spent years cleaning datasets where the first person to look at the numbers would just grab the mean and call it a day. That habit ruins more reports than anything else I've seen. The mean median mode and range unlocking data insights is less about the math itself and more about knowing which number to trust when your data is behaving badly. Let's get the definitions out of the way, but not in the order most textbooks do. Start with range because it's the only thing that tells you whether your dataset is tight enough to trust any of the other numbers. Range is simply the difference between the highest and lowest values. That's it. If your data spans from 3 to 147, the range is 144. Wide range doesn't automatically mean bad data, but it does mean you should be skeptical of the mean before you even calculate it. I once worked on a logistics project where delivery times had a range of 2 to 380 days. The mean came out to about 45 days. That number was useless. Nobody ships in 45 days. The median was 8 days. The mode was 3 days. The range told me immediately that the distribution was completely skewed and the mean would mislead anyone who read the report.
Mean is the arithmetic average. Sum all values, divide by the count. It's sensitive to every single value in the dataset, which is both its strength and its weakness. Median is the middle value when data is ordered. Half the values sit above it, half below. It doesn't care how extreme your outliers are. Mode is the most frequently occurring value. A dataset can have no mode, one mode, or multiple modes. In continuous data, you often have to bin values first to find a meaningful mode.
Here's the thing most people skip: these four numbers aren't competing answers. They're different lenses on the same distribution, and they're supposed to disagree. When they all point at roughly the same spot, your data is fairly symmetric and you have a clean story. When they spread apart, that spread is the actual insight. I found that a quick comparison between mean and median within the first thirty seconds of looking at new data usually tells me whether I need to dig deeper or move on. If the mean is more than ten percent away from the median, I flag skewness before running any further analysis. This catches problems early and saves hours of wasted modeling later. Pitfall one: people treat the mean as the default summary statistic and never justify that choice. In income data, household size data, or response time data, the mean will systematically overstate the typical experience. The median is almost always the better headline number in those cases.
Get the Full Details

Pitfall two: ignoring the mode entirely. In categorical or discrete data, the mode is often the most useful number. If you're analyzing customer ticket categories and the mode is "billing problem" at forty percent of all tickets, that tells you where to focus resources. The mean and median don't apply to categories, but the mode does. Pitfall three: assuming range is robust. It isn't. Range depends only on two values. A single data entry error can blow up your range and make the rest of the dataset look more volatile than it actually is. I learned this the hard way when a single extra zero in a spreadsheet turned a normal range of 12–89 into 12–890. I caught it by cross-checking against the interquartile range, which stayed completely unaffected. When I need to present these numbers to stakeholders, I don't just list them. I show how they relate. A short note like "mean is 62, median is 41, mode is 28, range is 0 to 310" makes the skew obvious without requiring a histogram. The gap between mean and median does the heavy lifting.
One advanced nuance that rarely gets covered: in moderately skewed distributions, there's an approximate relationship where mean minus median is roughly one-third of the distance from median to the tail. It's not a formula you should memorize, but keeping it in mind helps you sanity-check whether your calculations are in the right ballpark. If your mean and median are nearly identical but your range is enormous, something is wrong with your data cleaning process. Range has a practical use beyond just being a quick volatility check. In quality control and manufacturing, range is often calculated across subgroups rather than across the full dataset. The average range across subgroups gives you a stable estimate of process variability that's easier to compute than standard deviation and works fine for control charts. That's a different technique than what we're discussing here, but it shows why range deserves more respect than it gets. If you want to calculate these quickly in practice, spreadsheet software handles all four in one pass. In Excel, =AVERAGE(), =MEDIAN(), =MODE.SNGL(), and =MAX()-MIN() cover the basics. If you're doing this repeatedly across multiple columns, a simple VBA macro or Python script with pandas will cut the work from manual entry to a single click.
The real takeaway is this: don't let any single number stand in for your dataset. The mean median mode and range unlocking data insights only works when you use them together. One without the others is just a factoid. All four together tell you whether your data is honest, skewed, multimodal, or corrupted.