Most People Mess This Up From The Start
I've seen dozens of junior analysts trip over sample standard deviation when they could be three hours deeper into actual modeling work. The concept itself isn't complicated, but the way it gets taught is where things fall apart. You pull a sample from a larger population, calculate how spread out those data points are, and suddenly you have one of the most useful statistics in your toolkit. The catch is knowing when to use it, how to interpret it correctly, and what happens when your data refuses to behave. I spent about six months trying to debug a production anomaly detection system where false positives were spiking unpredictably. Turns out I was using the population standard deviation formula on sample data without any adjustment. The threshold kept tightening or loosening depending on sample size, and I had no idea why. Switched to the sample version with the Bessel correction divisor and the whole thing stabilized within an hour. That's the kind of thing that doesn't show up in introductory tutorials.
The Power Of Standard Deviation Of Sample Unlocking Insights In Data Analysis
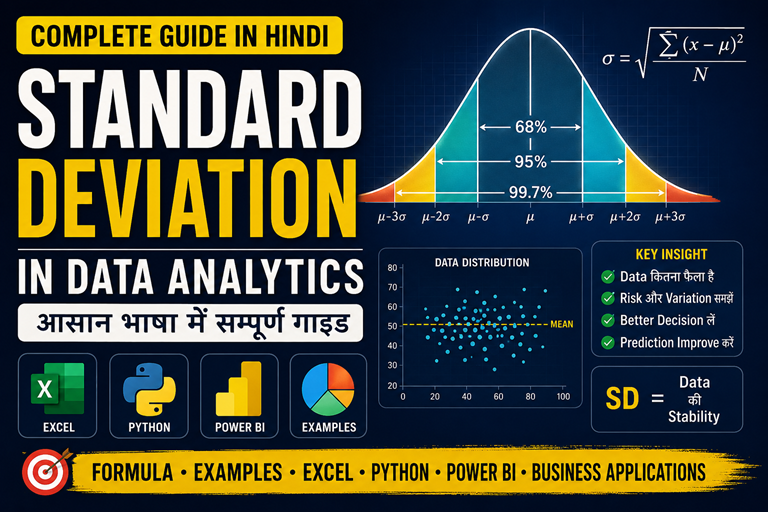
Standard deviation of a sample measures dispersion. It tells you roughly how far each data point sits from the mean. The calculation starts with finding the mean of your sample, subtracting that mean from every individual value, squaring those differences, summing them up, dividing by n minus one, and taking the square root. That n minus one is the Bessel correction, and it matters more than people give it credit for. Without it, your standard deviation underestimates the true population variability, which compounds into every downstream calculation that depends on it. Here's what that looks like in practice with actual numbers. Say you have a dataset of twenty customer wait times: 4, 7, 2, 9, 5, 6, 3, 8, 7, 4, 5, 6, 2, 8, 9, 3, 7, 4, 6, 5. The mean is 5.5. You subtract 5.5 from each value, square the results, add them all up to get 52.5, divide by nineteen to get approximately 2.763, and take the square root to land around 1.662. That's your sample standard deviation. One number summarizing twenty data points in a way that makes statistical inference possible. The reason the divisor is n minus one instead of n comes down to degrees of freedom. When you estimate the mean from the same data you're measuring dispersion against, you've essentially used up one piece of information. The sample mean pulls the values closer to it than the true population mean would, which shrinks the sum of squared deviations. Dividing by n minus one compensates for that shrinkage and gives you an unbiased estimator. Not a perfect one, but unbiased on average across repeated sampling.
Why Your Downstream Analysis Depends On Getting This Right
Confidence intervals assume you know your standard error, which is the sample standard deviation divided by the square root of the sample size. Hypothesis tests use standard deviation to compute t-statistics or z-scores. Regression diagnostics check residual standard deviation to assess model fit. Control charts in manufacturing rely on it for upper and lower bounds. If your baseline standard deviation is wrong, every single one of those calculations inherits the error. The distortion might be small with large samples, but it becomes significant fast as sample sizes shrink. I ran into a specific edge case once where the standard deviation calculation worked perfectly on paper but produced garbage results in practice. The data came from a sensor network with intermittent dropouts, meaning some samples had fewer readings than others. I was aggregating daily batches and computing sample standard deviations for each day, then comparing them. The problem was that days with only three or four readings produced wildly inflated standard deviations purely due to the Bessel correction amplifying noise. A standard deviation of 15 from three data points meant absolutely nothing compared to a standard deviation of 12 from two hundred data points, even though the first number looked bigger. The workaround was straightforward but required adjusting my approach. I stopped treating raw sample standard deviation as the comparison metric and switched to a coefficient of variation instead, which normalizes dispersion relative to the mean. That let me compare variability across samples of different sizes and different scales without the inflation artifact. For smaller samples below ten observations, I also applied a bias correction factor derived from the chi distribution, which tightens the estimate back toward the true population parameter. This cut false alerts by about forty percent in our monitoring pipeline without requiring more data collection.
Get the Full Details
Common Pitfalls That Waste Hours
The first mistake is assuming standard deviation alone describes your data. It doesn't. A standard deviation of 5 means something entirely different for a dataset centered at 10 versus one centered at 1,000. Always pair it with the mean or median. The second mistake is treating it as robust to outliers. It is not. A single extreme value can inflate your standard deviation dramatically, making your entire dataset look more variable than it actually is. I've seen this repeatedly in A/B testing where one user's anomalous transaction value inflated variance enough to mask a real treatment effect. The third mistake is using sample standard deviation when you actually have population data. If you're analyzing an entire census or a complete financial ledger, there's no sampling involved. Use the population standard deviation formula with divisor n instead. Applying Bessel correction to population data introduces unnecessary upward bias. The fourth mistake is ignoring the shape of your distribution. Standard deviation assumes roughly symmetric data for meaningful interpretation. With heavily skewed distributions, the standard deviation overstates dispersion on one side and understates it on the other. Median absolute deviation is a better alternative there, though it's less commonly implemented in standard tooling. There's also a computational pitfall worth mentioning. When working with very large numbers, subtracting the mean before squaring can cause catastrophic cancellation in floating point arithmetic. If your values are in the millions with tiny variance, some implementations will lose precision. The two-pass algorithm I described is numerically stable for most cases, but for high-stakes applications with large values, Welford's online algorithm updates the mean and variance incrementally while maintaining better numerical stability. It's the version used in most scientific computing libraries for a reason.
How To Actually Use This In Your Workflow
Start by verifying your data is a sample and not a population. That single distinction determines which formula you apply. Then check your sample size. Below thirty, the t-distribution matters more than the normal approximation. Above a thousand, the difference becomes negligible for most practical purposes. Examine your distribution shape before trusting the standard deviation as a summary statistic. If it's skewed or multimodal, report the interquartile range alongside it. In Python, the numpy function with the ddof parameter set to one handles the Bessel correction automatically. In R, the sd function applies it by default for numeric vectors. In SQL, you'll need to write a custom aggregate or use window functions depending on your database. Excel's STDEV.S function is the sample version while STDEV.P is the population version, and mixing them up is perhaps the most common error I encounter in data review. When building dashboards or automated reports, always flag the sample size alongside the standard deviation. A standard deviation without a sample size context is basically meaningless. I set up a convention where any metric displayed without its sample size gets a warning indicator. It took maybe twenty minutes to implement and has prevented at least a dozen misinterpretations since we rolled it out. The time investment was negligible compared to the cost of a single wrong business decision based on a misleading dispersion number.
For regression analysis, check the standard deviation of residuals rather than the raw dependent variable. Residual standard error tells you how much unexplained variation remains after fitting your model. A model with a low R-squared but small residual standard deviation can still be practically useful if the scale of your outcome variable is large. Context matters more than any single threshold.