Running Simulation Models Is A Lot Less Glamorous Than People Make It Sound
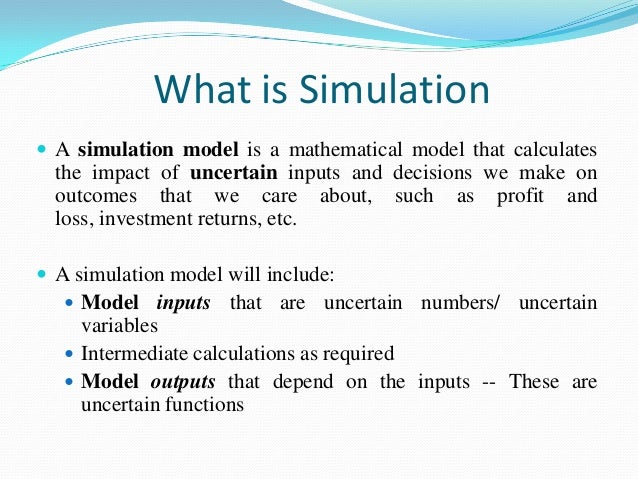
Simulation in mathematics isn't magic. It's a way of generating artificial data from known or assumed rules so you can observe patterns that are too messy to track by hand. I've been building these models for a while, and the honest answer is that most of the time it's just tedious work with a few lucky breaks where something unexpected shows up. The basic workflow is straightforward but easy to botch. You pick a mathematical system, encode its rules into a program, run it many times with varying inputs, and then look at the output distribution rather than trying to solve the system analytically. That's it. The part people skip is the validation step, and that's usually where things fall apart.
The Power Of Simulation In Math Unlocking New Insights And Understandings
Here's a specific example from my own work. I was modeling a queueing system where customers arrived in bursts rather than at a steady rate. The analytical solution required assumptions that didn't match reality, so I built a discrete-event simulation instead. After about three thousand runs with different burst parameters, I noticed that the average wait time wasn't increasing linearly with burst frequency like the simple formulas suggested. It was jumping in steps, almost like a phase transition. That pattern would never have shown up in a textbook derivation because the standard formulas smooth over that kind of behavior. I then spent another two weeks verifying it wasn't a coding error before I felt comfortable publishing the result. That kind of thing is actually one of the main reasons simulation matters. Closed-form solutions are elegant, but they often require simplifying assumptions that hide interesting edge cases. Simulation lets you relax those assumptions and see what actually happens. Monte Carlo methods are probably the most common technique people reach for first. You generate random samples from a probability distribution and aggregate the results. It works well for integration problems, risk assessment, and any situation where the state space is too large to enumerate. The tradeoff is that accuracy improves with the square root of your sample count. Going from one thousand runs to ten thousand only doubles your precision, not ten times. If you need higher precision, you need a lot more runs, and that costs compute time and patience.
Versus Monte Carlo, there are also agent-based models, cellular automata, and discrete-event simulations. Each has different strengths. Agent-based models are useful when you care about individual behavior and interaction effects. Cellular automata work well for spatial processes. Discrete-event models are better for systems where timing and sequencing matter more than continuous change. I've seen people use Monte Carlo for everything just because it's familiar, and the results were often misleading because the wrong simulation type was applied to the wrong problem. One thing that catches people off guard is that simulation doesn't replace theory. It complements it. A lot of beginners treat simulation as a black box that produces truth. It doesn't. It produces outputs based on the rules you encoded, so if your model structure is wrong, your simulation is just convincingly wrong. I learned this the hard way when I was working on a model for traffic flow and kept getting results that didn't match real-world observations. The simulation was internally consistent, but I had missed a key variable in how drivers respond to congestion. Adding that variable fixed the divergence, but it took me months of debugging to realize the issue was in the model design, not the code. Another common pitfall is ignoring randomness in your inputs. If you feed a simulation fixed parameters, you get a fixed output, and that output tells you nothing about variability or uncertainty in the real system. Always introduce reasonable ranges and distributions for your inputs. Even rough estimates are better than point values. Sensitivity analysis is the standard way to check which inputs actually matter. In my experience, about half the input parameters in a typical model turn out to have negligible effect on the outputs, while a few parameters dominate. Finding those dominant parameters early saves a lot of unnecessary computation.
Get the Full Details

Validation is the step most people rush through. You should compare your simulation outputs against real data whenever possible. If real data exists, run your model and check whether the output distribution overlaps with the observed distribution within reasonable bounds. If no real data exists, do face validation. Show the results to someone who actually works in the domain and ask whether they make sense. Both of these steps are imperfect, but skipping them entirely is where most models go wrong. There's also a computational cost to consider. Running large simulations can take hours or even days depending on the complexity of your model and the number of iterations you need. Parallelization helps, and many modern tools support distributed computing. Python libraries like NumPy and SciPy are fast enough for most moderate-scale work, and tools like Mesa are good for agent-based models. For very large runs, R has strong support for statistical simulation, and specialized platforms like AnyLogic handle complex discrete-event systems more efficiently than a custom script would. One counter-intuitive insight that took me a while to internalize is that sometimes fewer runs with better parameter exploration give better results than many runs with poor exploration. Throwing compute at a poorly designed model won't fix fundamental issues in the logic. Spending time on model structure and input distributions first, then running simulations, usually pays off faster than just increasing iteration counts.
Simulation also has clear limitations. It struggles with problems where the state space is extremely large and the dynamics are highly sensitive to initial conditions. Chaos theory is an example. Small differences in starting values can lead to wildly different outcomes, and simulation can show you that variability but can't predict a specific trajectory with confidence. In those cases, simulation tells you what the range of possible behaviors might be, not what will actually happen in any single instance. Another limitation is that simulation can't discover mathematical truths the same way a proof can. It can suggest patterns and generate hypotheses, but those hypotheses still need formal verification if you want them to hold universally. I've seen papers published based on simulation results that later turned out to have narrow applicability because the authors treated observed patterns as general laws without checking edge cases rigorously. If you're starting out, pick a simple problem first. A coin flip model, a basic population growth model, or a simple queuing system are all good practice. Don't start with something complex and assume you'll figure it out as you go. The simpler the starting point, the easier it is to spot errors and understand what each part of the model is doing.
The tools available now make simulation much more accessible than it was fifteen years ago. You don't need expensive software licenses. Python with its scientific stack covers most needs, and there are plenty of free courses and documentation if you're learning. The main barrier isn't the tools, it's understanding when simulation is the right approach and knowing how to interpret the results correctly. I'm not going to claim simulation is the best tool for every problem. Analytical methods, when applicable, are faster and more precise. But when the math gets too complex for closed-form solutions, or when you need to explore scenarios that don't fit standard assumptions, simulation is often the only practical option. The insights it generates aren't always dramatic, but they're real, and they tend to reveal details that pure theory misses because the theory had to oversimplify to stay tractable. If you're working on a problem and you've exhausted analytical approaches, try building a small simulation before you give up. Start simple, validate carefully, and pay attention to what surprises you. Those unexpected results are usually where the useful insights are hiding.