What Actually Happens When You Look At NMQ Data
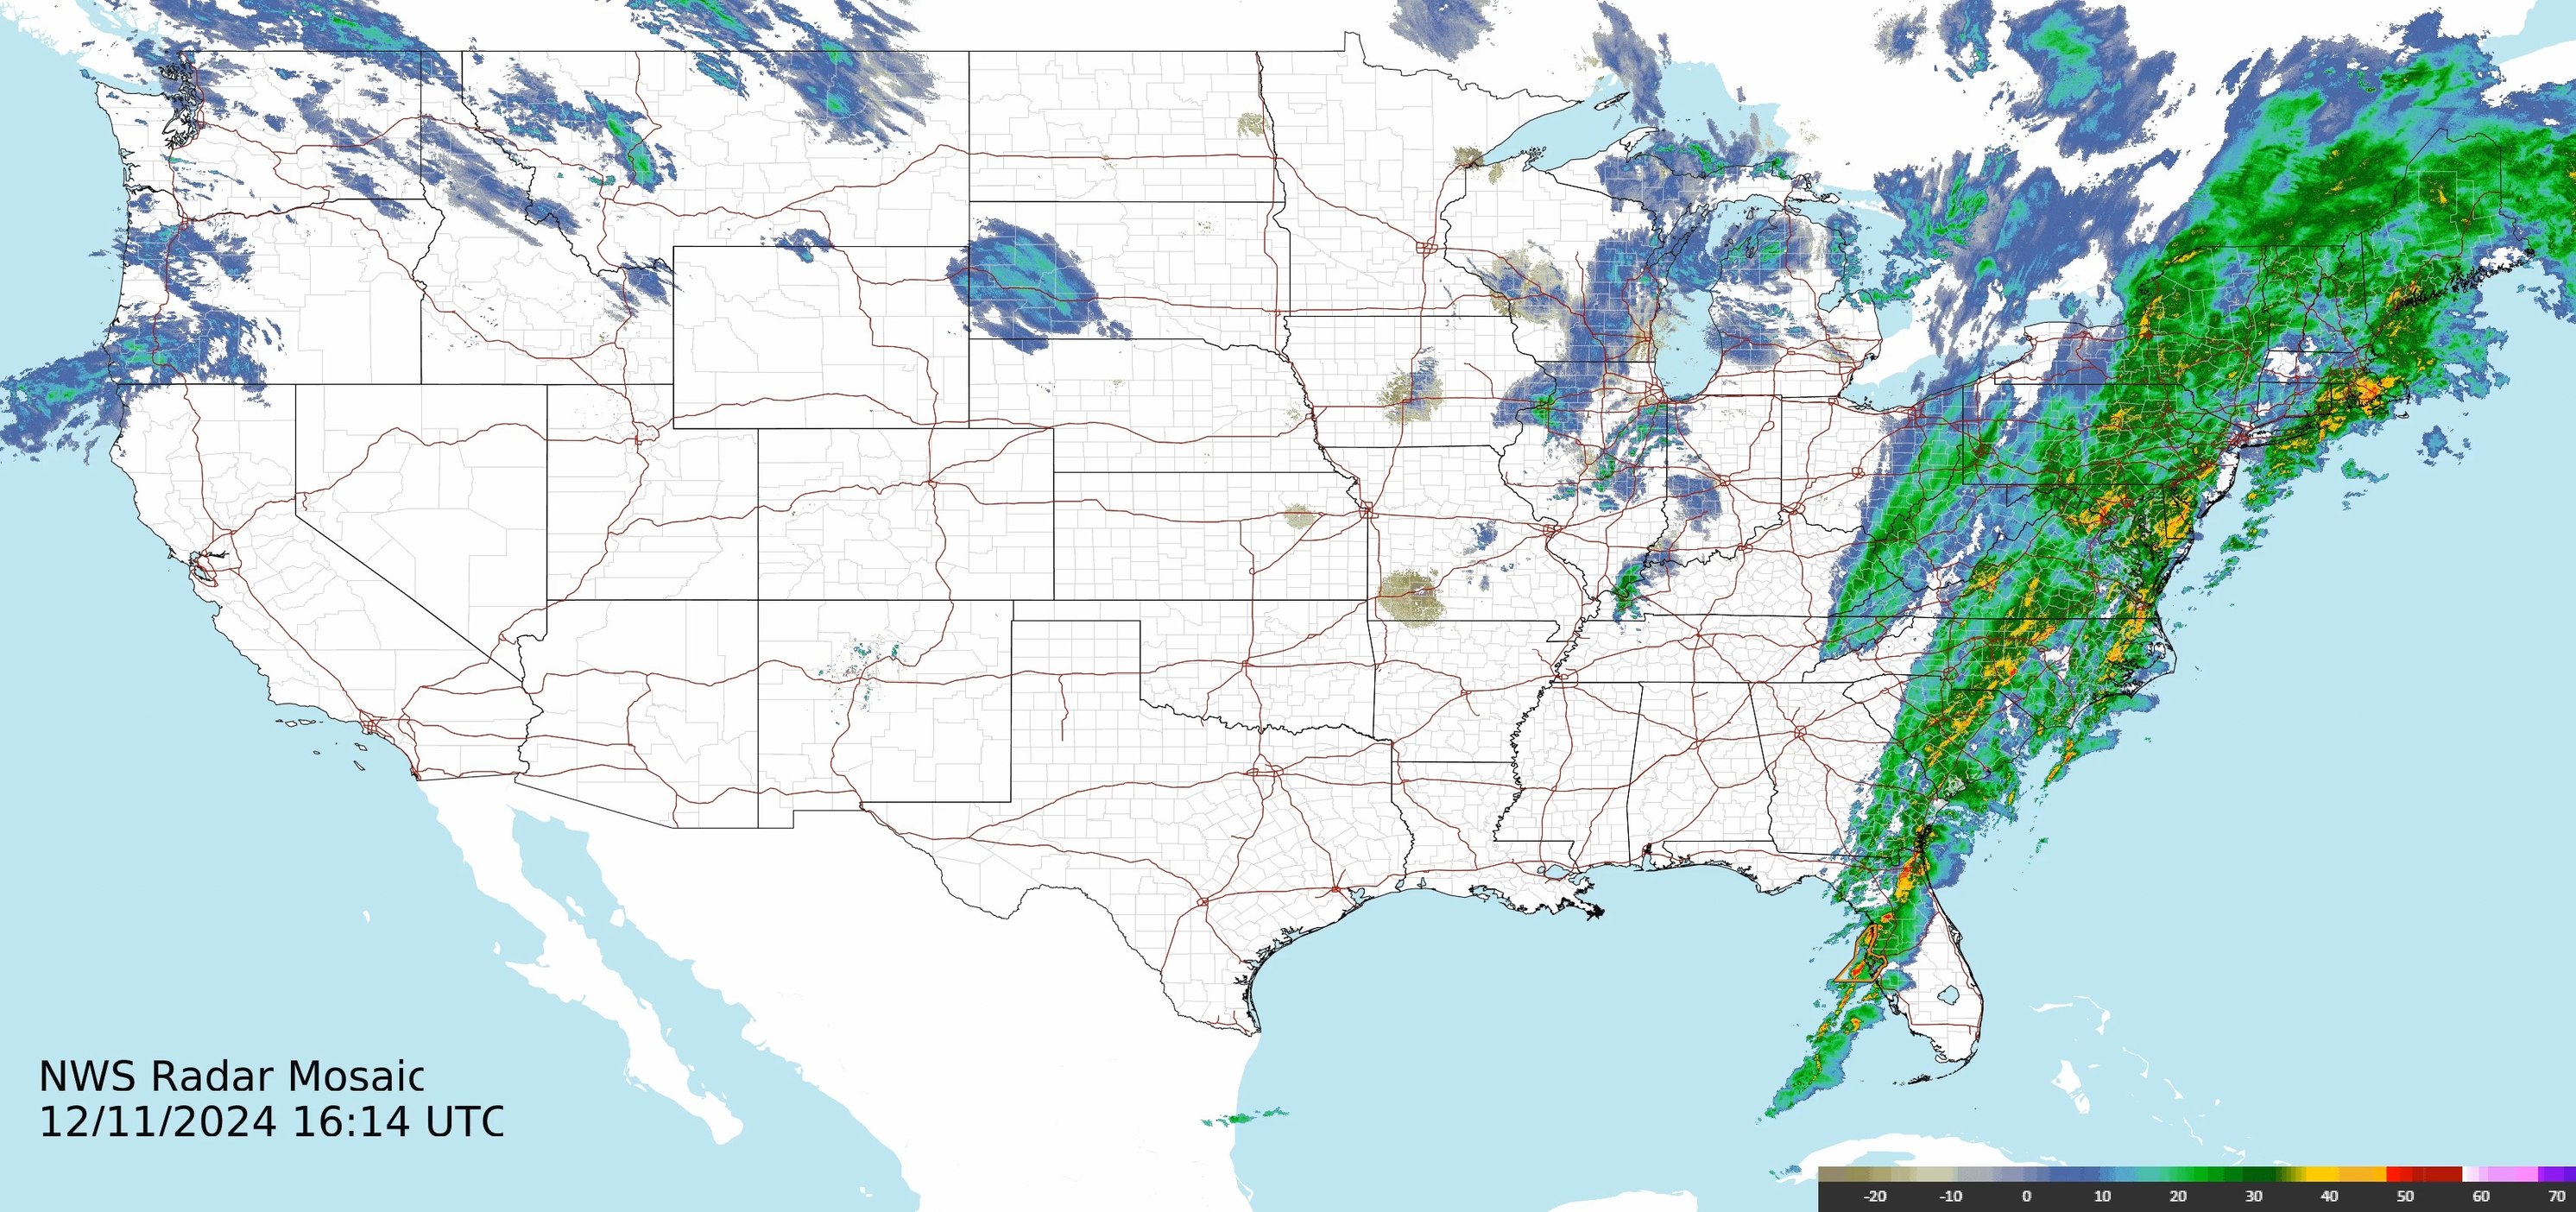
The National Multi-Sensor Mosaic (NMQ) is the product that runs the show for operational forecasters now. It took over as the default reflectivity mosaic from the old WSR-88D single-site displays around 2014 when the NWS finally pushed it out to the river forecast centers and national centers. Before that you were stitching together individual radar sites yourself or relying on whatever the local office served up, which was a mess because each site had different calibration drift and clutter issues. NMQ fixed a lot of that by ingesting data from multiple sources and doing quality control before presenting it. The system pulls from the NEXRAD Level II volume coverage patterns across the country plus satellite-derived precipitation estimates and rain gauge networks where they exist. The output is gridded at roughly 1x1 kilometer resolution in the CONUS and updates about every two to three minutes for reflectivity. That update cadence is why things started feeling different once we got used to it. You stop looking at a single radar blade and start seeing coherent storm evolution across county lines instead of trying to mentally interpolate between sites that have huge gaps in coverage out past 150 kilometers anyway.
The Power Of Radar National Mosaic Transforming Weather Forecasting
Here is the practical difference it makes. When you are tracking a squall line moving through central Illinois at 2 AM and you only have one WSR-88D site to work with, that line disappears into the clutter zone and you are guessing about intensity based on a few scattered echoes. With NMQ you see the whole line, the rear inflow jet signature, the bow echo development, and you can actually call the severity of it five minutes before it hits your community instead of reacting to what you hear on the radio. That is the real transformation. Not hype. Just better situational awareness that used to require a team of people manually merging data. I remember one specific night back in April 2016 when a training line pushed through western Kentucky and the local NEXRAD at Paducah was completely blinded by ground clutter because of the hilly terrain. The raw reflectivity showed nothing above 20 dBZ in the affected area. I pulled up the NMQ composite and saw well-defined 55 to 60 dBZ echoes right where the line should have been. What was happening is that the composite algorithm was using the nearest precipitation estimate from the next site over plus the satellite-derived IR data to fill in the gap, while the raw single-site data was just garbage in that zone. I called it in as severe and the line produced 70 mph winds about twenty minutes later. If I had only trusted the raw NEXRAD output I would have had nothing to go on. That is the kind of edge case you run into constantly. Beam blockage is the most common one. Mountains, tall hills, even dense urban structures can partially or fully obscure the radar beam. NMQ handles it by blending in data from adjacent sites and satellite products, but it is not perfect. When you are in a deep valley or right behind a ridge, the mosaic can smooth over real intensity because it is averaging across multiple sources. The reflectivity values come out lower than what a clear-site radar would show. I learned early to cross-reference with mesonet data and surface observations when the NMQ values look suspiciously tame in terrain-shadowed areas. A quick check against nearby rain gauges and wind reports usually tells you whether the mosaic is under-reporting or the storm is genuinely weak.
How The Data Actually Gets Built
The processing chain starts with Level II data from each WSR-88D site. Those raw scans go through the NMQ quality control flagging pipeline where it checks for anomalous propagation, ground clutter, insect returns, and beam blocking. Anything flagged gets either corrected using neighboring site data or masked out entirely if there is no valid data available. Then the National Centers for Environmental Prediction handles the merging with their Multi-Radar Multi-Sensor system, which produces the final mosaic you see on weather apps and forecast dashboards. There are a few important technical details that matter if you are actually using this for decision making. The reflectivity composite is a maximum echo composite, meaning it takes the highest reflectivity value found at any altitude within each grid cell. That is useful for seeing the strongest parts of storms but it also means you can have false high values when the beam is overshooting the actual precipitation core at long ranges. Beyond about 200 kilometers the radar beam is several kilometers above the ground. A storm that looks like it has 70 dBZ echoes at that range might actually be producing much lighter precipitation at the surface because the beam is sampling the upper part of the cloud rather than the rain shaft below. Another thing beginners consistently miss is the time lag. NMQ data is not truly real-time. There is a processing delay that ranges from about 2 to 5 minutes depending on the data path and current load. During fast-moving severe weather events that delay is noticeable if you are watching storms evolve second by second on a live feed. I got caught out on this during a Derecho event in 2020. The mosaic showed the leading gust front moving through Ohio at a certain speed based on the latest available composite, but by the time that composite was rendered the actual front had already pushed another fifteen kilometers east. I adjusted my callout times by building in that lag and it made a real difference in how accurate our warnings ended up being.
Get the Full Details
Where It Falls Apart
NMQ is not a silver bullet. In winter precipitation scenarios it struggles significantly. The algorithm is optimized for convective reflectivity detection and struggles to differentiate between light snow, drizzle, and freezing rain. The composite tend to under-represent stratiform precipitation because the reflectivity values are naturally low and the quality control flags often discard those weak returns as noise. If you are forecasting winter storms in the northern tier, you still need to rely heavily on the Model-based precipitation type overlays and the HRDAS products instead of trusting the mosaic alone. There is also the issue of bright band contamination. When the radar beam intersects the melting layer, you get artificially elevated reflectivity values that do not correspond to actual precipitation intensity at the ground. This happens frequently in the 100 to 150 kilometer range from any given site during steady rain events. The composite does apply some bright band correction but it is not foolproof, especially when the melting layer altitude varies across the merge zone between two radar sites. You will see these artifacts most clearly as diffuse bands of 40 to 50 dBZ that move smoothly across the mosaic without any actual storm structure behind them. They look like real weather but they are just melted snowflakes creating false echoes. For anyone who wants to access the data directly, the NMQ product is available through the National Weather Service data servers and the NOAA Climate Data Store. The Level III format that most forecast software reads is distributed via the National Data Assembly servers. You can also pull the raw Level II data from the National Severe Storms Laboratory archives if you want to dig into the unmerged single-site data for comparison. The SPC and NCEI both host the data freely. There is no paywall. What you need is basic Python or MATLAB skills to process it properly or access through the existing forecast decision support tools that already ingest it.
The bottom line is that NMQ changed how we operate from a reactive posture to a more predictive one, but it requires understanding its blind spots. The terrain shadowing, the range-related beam overshooting, the winter precipitation gaps, and the processing lag are all real limitations. The forecasters who get the most out of it are the ones who treat the mosaic as one input among several rather than the final answer. Cross-reference it with surface observations, check the individual site data when something looks off, and account for the time delay in fast-moving systems. That is how you actually use it without getting burned by the gaps.