Empiricism In Practice
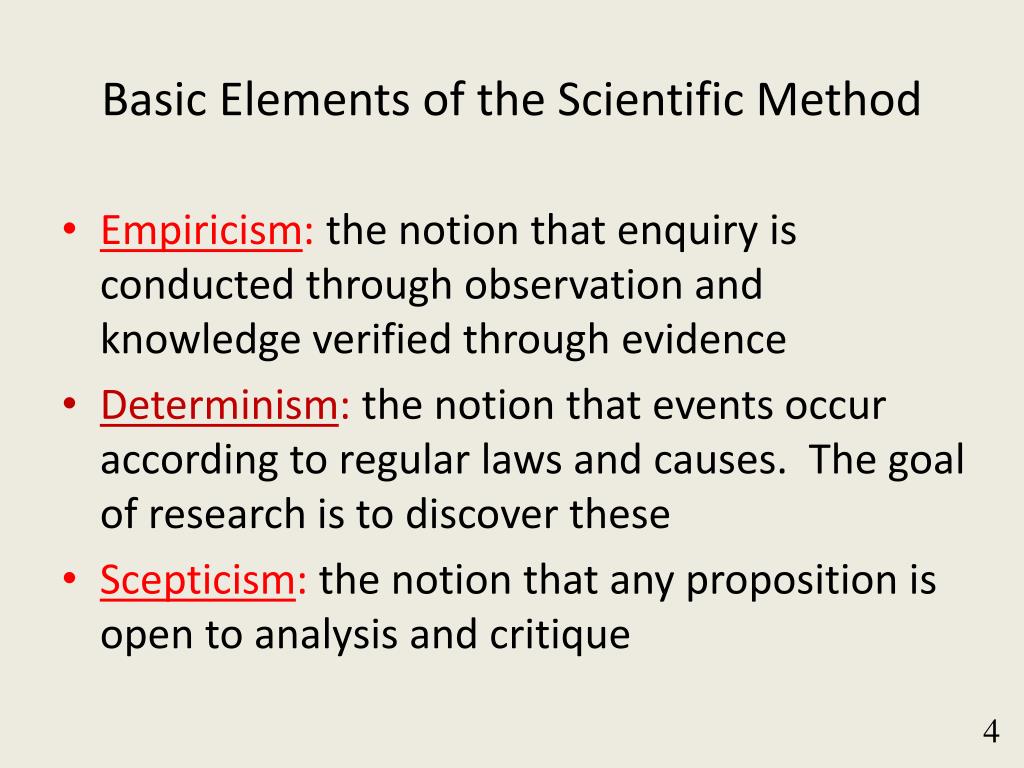
Most people learn empiricism as a philosophical concept. I learned it by watching a production pipeline fail because someone assumed a measurement tool was calibrated correctly. The assumption cost us three weeks of rework on a sensor fusion project. That's how it works in practice: you trust what you can measure, and you stop trusting everything else until it produces data. The scientific method is basically a formal system for extracting reliable claims from observation. Empiricism is the part that says observations come first. Not theory, not elegant models, not what makes sense intuitively. You gather evidence before you commit to a conclusion, and you revise the conclusion when the evidence changes. This isn't a grand statement about the nature of knowledge. It's a working discipline that keeps you from embarrassing yourself.
The Power Of Empiricism Why Its The Backbone Of The Scientific Method
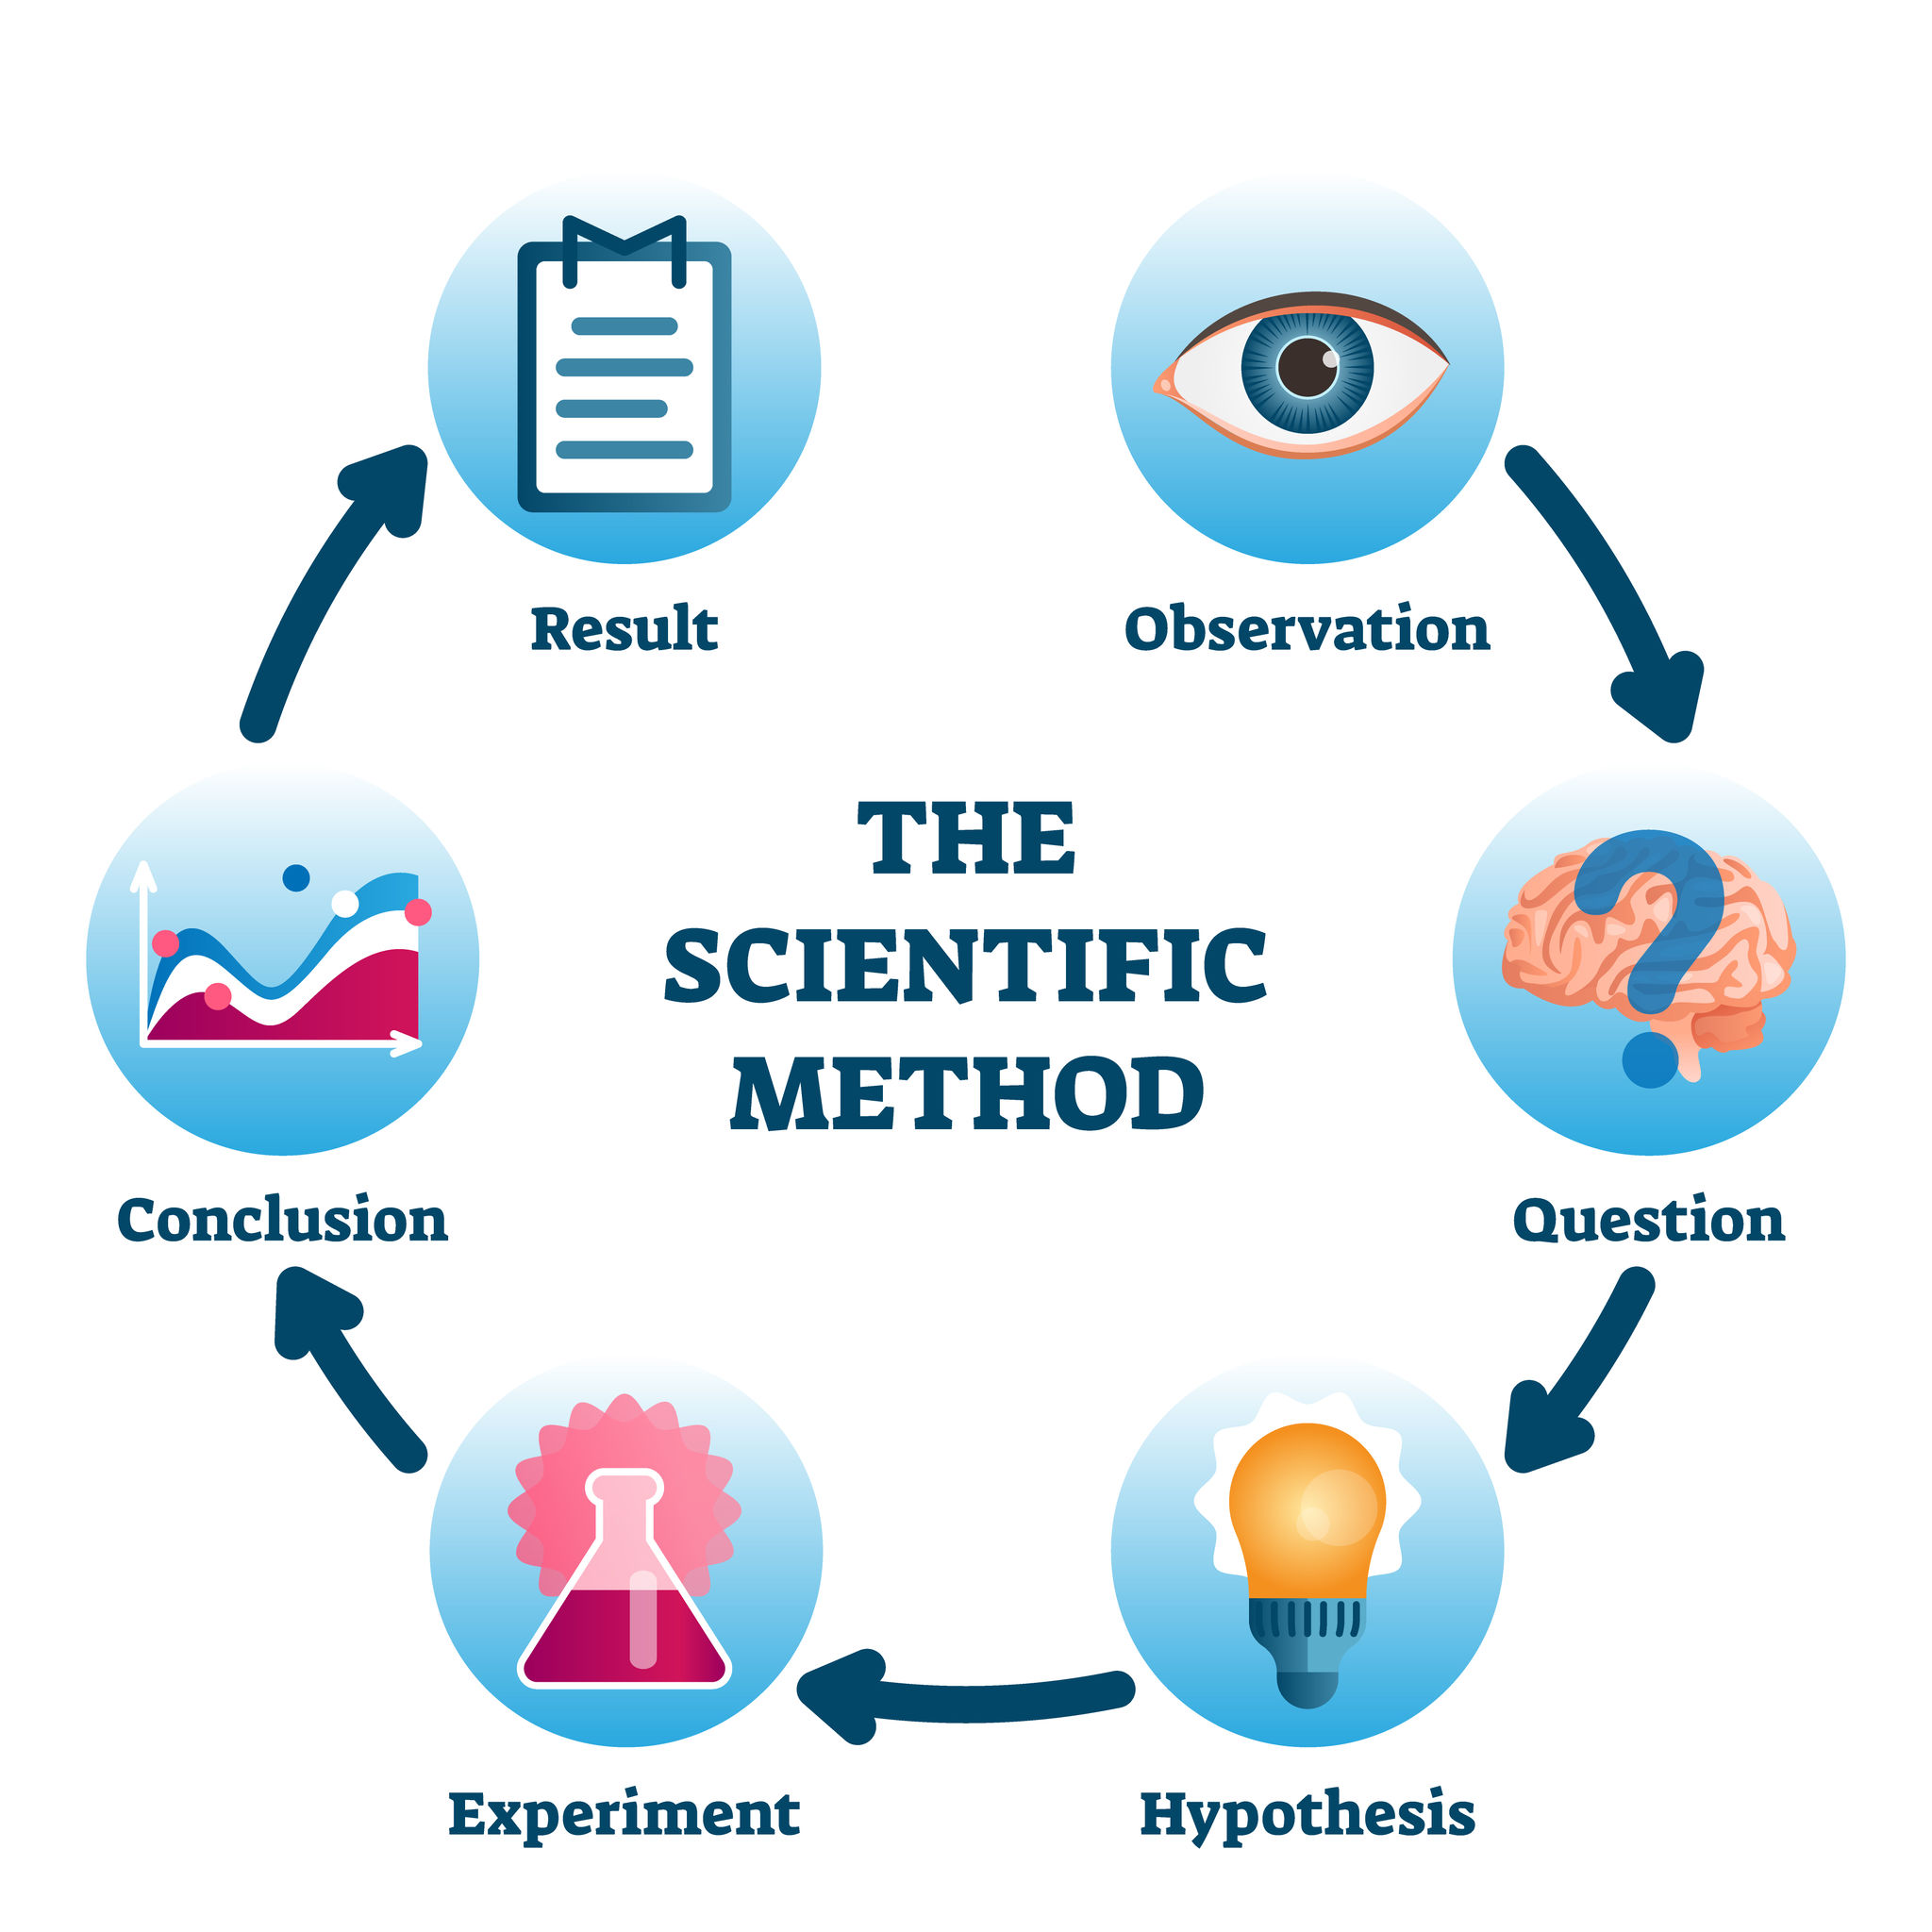
Here is the method as it actually gets used, not as it appears in a textbook. You observe something. You define a question about it. You generate a hypothesis that makes a specific, falsifiable prediction. You design an experiment or data collection process that could prove that prediction wrong. You run it. You analyze the results. You accept, reject, or refine the hypothesis. Then you repeat. The repetition is the part people gloss over. A single data point is noise. You need enough observations to separate signal from whatever random variation your setup introduces. Sample size depends entirely on your domain. In controlled lab work with low variance, maybe twelve trials are enough. In field work with environmental drift, you might need hundreds before the trend stabilizes.
I ran into this when testing a new battery charging algorithm for electric vehicle prototypes. The lab results looked perfect across five cycles. When we deployed the same firmware on actual vehicles, the thermal throttling patterns were completely different because real-world ambient temperature swings and driving patterns changed the charge curve behavior in ways our static test rig never captured. I had to go back and redesign the test protocol to include randomized drive cycles and environmental chamber sweeps. The fix wasn't theoretical. We just hadn't collected the right kind of empirical data before declaring victory. Hypothesis falsifiability is where most beginners break down. A hypothesis needs to make a prediction that could actually be wrong. "This approach might improve performance under certain conditions" is not falsifiable. "This approach will reduce cycle time by at least eight percent in the target workload" is. You can measure eight percent. You can fail to measure it. That distinction matters more than people realize. One counter-intuitive thing about empirical work: strong evidence often comes from experiments designed to fail, not to succeed. When you build a test whose only purpose is to try to disprove your hypothesis, you filter out confirmation bias by design. You're not looking for proof that you're right. You're looking for proof that you could be wrong. If you can't find it after thorough testing, you have something more reliable than confirmation.
Get the Full Details

Another thing that trips people up is confusing correlation with the kind of empirical support causation actually requires. You can observe that two variables move together all day long without having any evidence that one causes the other. The scientific method handles this through controlled experimentation where you isolate variables. When you can change one factor while holding everything else constant and the outcome shifts, that's when you start earning the word causal. The limitations are worth stating plainly because nobody does it adequately. Empiricism fails when the phenomenon you're studying cannot be measured with sufficient precision. Quantum mechanics pushes this to its limits. You can observe particle behavior statistically across many trials, but individual events resist clean empirical description in classical terms. Empiricism also struggles with slow-moving or large-scale systems. Climate data spans decades. Good empiricism still needs that much time. There is no shortcut around it.
Another failure mode is measurement itself altering the system. In software engineering, this shows up constantly. Monitoring a production service adds latency. Adding logging changes memory profiles. Your empirical tool becomes part of the environment you're trying to study. The workaround is usually instrumentation in non-production environments first, then careful sampling in production with statistical correction factors applied afterward. I spent a week tracking down a bug where our telemetry framework was silently dropping packets during peak load. The dropped packets made our empirical data look cleaner than reality. We had been drawing conclusions from incomplete observations because the observation tool was degrading the thing we were observing. The fix involved switching to async logging with buffered writes and validating data completeness at the collection layer before any analysis started. This saved us from making product decisions based on misleading measurements. When pure empiricism hits a wall, Bayesian reasoning provides a practical bridge. Instead of demanding absolute proof before acting, you assign prior probabilities and update them as evidence accumulates. This doesn't replace careful observation. It gives you a structured way to make decisions when observations are incomplete or coming in slowly. Clinical trials use this approach routinely because waiting for absolute certainty before releasing medical knowledge would be irresponsible.
The practical workflow I recommend looks like this. Start by writing down exactly what you can measure. Define your units, your acceptable error bounds, and your data collection frequency. If you cannot specify these, you do not yet have an empirical question. Then build a baseline measurement before you introduce any intervention. Without a baseline, you have nothing to compare your results against. Next, collect data in repeating cycles, not single attempts. Randomize order where possible to control for confounding variables. Finally, document every deviation from your protocol because anomalies in your procedure often matter more than anomalies in your results. This process takes time. A proper empirical study in my experience usually runs anywhere from two weeks for straightforward validation work to six to eight months for complex systems with multiple interacting variables. The timeline scales with the complexity of what you're studying and the quality of your measurement infrastructure. Budget accordingly.
Peer review exists for a reason. Even when you follow every step correctly, human error enters at every stage. Data entry mistakes, selection bias in sample choices, p-hacking when you run too many tests without correction, and publication bias where only positive results get shared. These are structural problems, not individual failures. The remedy is transparent methodology documentation and independent replication, which is why open-source research practices have gained traction in the last decade. If you are implementing this approach in a professional setting, the single most useful thing you can do is establish a culture where null results are treated as valuable data rather than failures. An experiment that proves a hypothesis wrong is still useful. The alternative is continuing down a path that costs more time and resources than a well-conducted failed experiment would have cost upfront. The math almost always favors the honest empirical approach, even when it feels uncomfortable in the moment.