Getting Dirb Working Properly
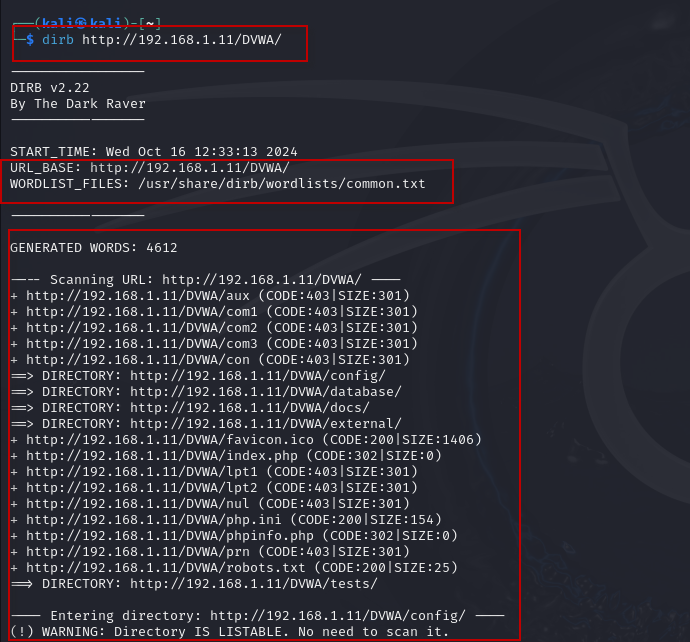
Dirb comes preinstalled on Kali Linux, so unless you removed it or are running a minimal install, you already have it. The binary is called dirb. I've seen people waste twenty minutes trying to install it via apt when it's literally there on the desktop. The basic command structure is simple. You point it at a target URL and give it wordlists. Default wordlists live in /usr/share/dirb/wordlists/. Here's the standard run: dirb http://target-site.com /usr/share/dirb/wordlists/common.txt
That scans the root path using the common wordlist. It outputs found directories and files with their HTTP status codes. 200 means the resource exists. 403 is a directory that's there but locked down. 404 means nothing found at that path. 301 and 302 are redirects that sometimes point to interesting paths.
The Power Of Dirb Unlocking Web Directory Scanner Capabilities In Kali Linux
The real value isn't in running the default scan. Anyone can do that. The power comes from understanding what each flag actually controls and how to tune it for different scenarios. Let me walk through the flags that matter. -X .ext lets you append extensions to your wordlist entries. If your wordlist has "admin" but the actual file is "admin.php" or "admin.asp", this flag handles that without needing a separate wordlist for every extension. Useful for PHP-based sites. -E .ext does the opposite. It takes the extensions you specify and appends them as separate scan targets alongside your wordlist entries. This catches edge cases where the directory name alone returns a 404 but adding an extension like .html reveals a hidden page.
Get the Full Details
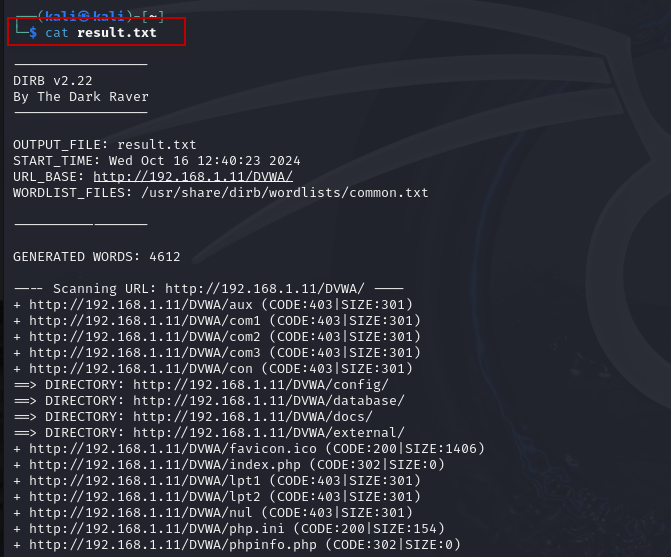
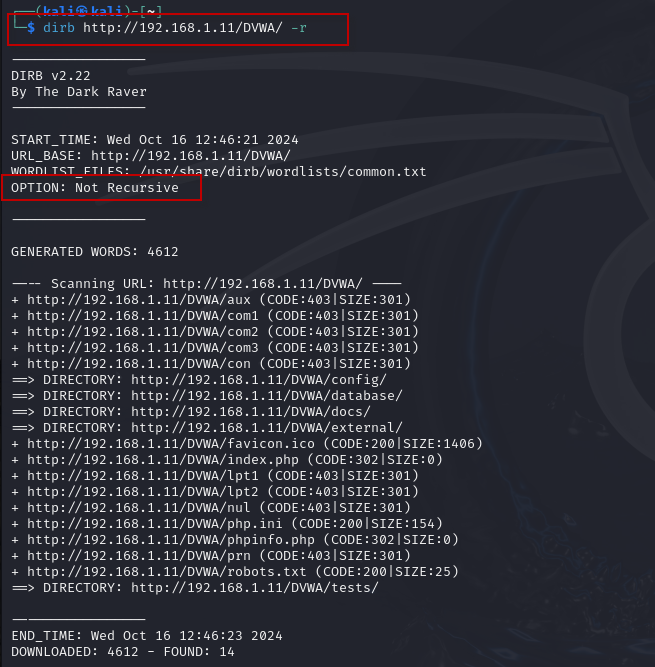
-r follows redirects. Without this, dirb stops at the redirect response and doesn't resolve the final destination. For sites that use redirect chains or load balancers, this is essential. It adds time though, usually 2-3x longer depending on how many redirects the site throws at you. -k sends custom headers. I use this constantly for authentication and user-agent spoofing. Some modern applications block default dirb user-agent strings or require session cookies to return meaningful responses. -C status_codes filters which HTTP status codes dirb reports. By default it shows everything. In noisy environments, narrowing this to just 200, 301, 302, and 403 cuts the output dramatically and makes review faster.
Common Pitfalls
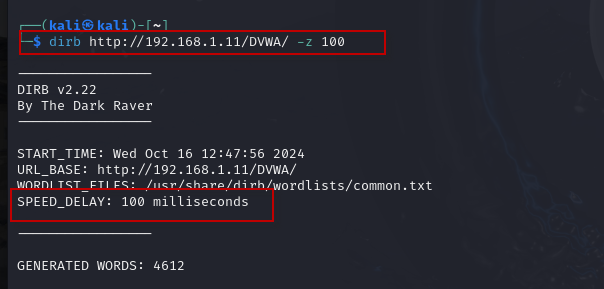
Dirb sends requests sequentially by default. That's slow. On a medium-sized wordlist against a responsive server, a full scan can take 45 minutes to over an hour. The tool doesn't have native multi-threading like dirbuster or gobuster do. You'll wait. Period. Another issue: large wordlists without rate limiting will get your IP blocked. Most WAFs and fail2ban setups catch rapid sequential requests. Use the -w flag to add delays between requests. A two-second delay turns a 15-minute scan into roughly 45 minutes, but you're less likely to get blocked. Worth the tradeoff on most engagements. False positives from 403 responses are a real problem. A 403 doesn't always mean a directory exists. Some servers return 403 for any malformed or unlisted path as a security measure. I once spent an afternoon chasing forty-three 403 responses on a WordPress site, only to find that half of them were the server's generic error page, not actual directories. Running a quick manual check with curl against the 403 paths confirmed which were real. Spend five minutes validating before you spend five hours exploring.
My Experience With A Specific Edge Case
I was scanning a legacy application last year where the server returned 200 for nearly every path, including completely fake ones. The application had a custom error handler that rendered a generic page with a 200 status code regardless of whether the resource existed. Dirb reported hundreds of "found" directories, all false positives. The only way to distinguish real from fake was checking response sizes and content hashes. I wrote a quick Python script to compare response bodies against a known 404 template and filter out matches. Cut the results from two hundred entries down to eleven legitimate paths in about thirty seconds. This isn't a dirb feature. It's a limitation of the tool and the scenario. Just be aware of it. The default common.txt wordlist contains roughly 4,700 entries. It's fine for quick recon but misses a lot. The big_names.txt list goes to about 23,000. For thorough work, combine wordlists. I typically run dirb with common.txt first, then re-run with big_names.txt against any paths that looked promising during the initial scan. This layered approach is faster than running one massive wordlist from the start because you can adjust your strategy based on early findings. For specialized targets, custom wordlists beat generic ones every time. If you know the application stack, tailor your list. PHP sites need .php, .php5, .phtml entries. ASP.NET needs .aspx, .ashx, .asmx. Node.js apps often expose routes through JavaScript files rather than traditional directory structures. Adjusting your wordlist to the technology saves time and catches things generic lists miss.

When Dirb Isn't The Right Tool
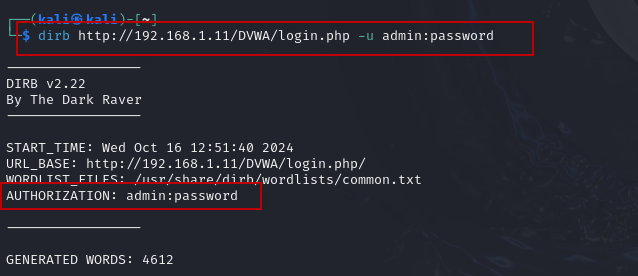
If you need speed, use gobuster or ffuf instead. Gobuster uses Go and hits directories significantly faster, especially with its concurrent execution. FFUF takes fuzzing to another level with its wordlist filtering and rate limiting built in. Dirb is stable and reliable but it's old. The codebase hasn't seen major updates in years. It works, but it's not the fastest option available. For authenticated scans where you need to bypass login walls, dirb's -k header flag gets you partway there, but tools like burp suite's intruder or arjun give you more control over session handling and parameter fuzzing. Dirb isn't designed for authentication-heavy workflows. Run the defaults first. Understand what the output means. Then tune the flags and wordlists based on what you're actually seeing. The tool does what you tell it to do, and most of the time the bottleneck is the wordlist and the flags, not the scanner itself.