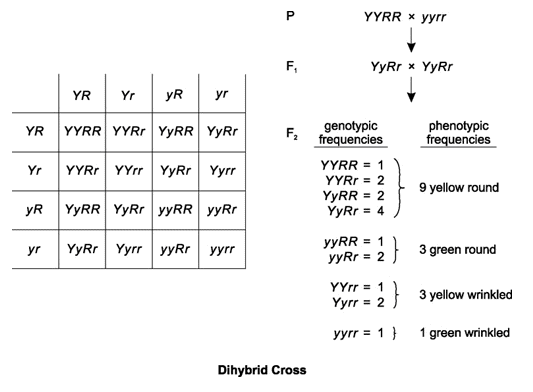
Setting Up a Dihybrid Cross That Actually Works
A dihybrid cross tracks two traits simultaneously instead of obsessing over one. You set up a 16-box Punnett square, map out the gametes from each parent, and count phenotypes. The standard 9:3:3:1 ratio is what most textbooks shove down your throat, but the reality is messier. I spent years doing these by hand before automating anything, and I still run into edge cases that break the textbook model. The core mechanism is independent assortment. Two genes on different chromosomes separate into gametes independently of each other. A heterozygous parent with genotype AaBb produces four types of gametes — AB, Ab, aB, and ab — each with equal probability. When you cross two AaBb parents, the 16 possible combinations produce the classic ratios. Dominant traits show up when at least one copy is present. Recessive traits require two copies. Here is where beginners routinely trip up. The 9:3:3:1 ratio assumes both genes are fully dominant and unlinked. Real organisms do not always cooperate. I once worked with a line of Arabidopsis where two supposedly independent genes were actually about 12 centimorgans apart on the same chromosome. The observed ratio came out closer to 10.5:1.8:1.8:2.1 instead of 9:3:3:1. Running a chi-square test on that data flagged the deviation immediately. The workaround was to calculate recombination frequency directly rather than assuming independent assortment. Once I treated it as a linkage problem, the expected ratios matched the observed data within acceptable margins.
Step-by-Step Methodology
Start by identifying the parental genotypes. Make sure both parents are heterozygous for the two traits you are tracking. Write out the possible gametes for each parent. Place one parent's gametes across the top and the other's down the side. Fill in all 16 boxes by combining the alleles. Count the phenotypic classes. Compare your results to the expected ratio using a chi-square test if you have real data to validate. Most people skip the gamete listing step and jump straight to filling boxes. That is faster but prone to errors. I always write the gametes first. It takes about 30 seconds extra and catches mistakes before they compound through the whole square. A single missed gamete type ruins every result below it.
Advanced Cases Where the Standard Model Breaks
Epistasis changes everything. When one gene masks the expression of another, the phenotypic ratio shifts completely. A classic example is the 9:7 ratio in sweet pea flower color where two dominant alleles at different loci are both required for pigment production. Cross two dihybrids and you get 9 colored to 7 white, not the standard 9:3:3:1. I dealt with this in a maize breeding project where the expected yellow kernel ratio collapsed into something closer to 12:3:1 because of a suppressor gene I had not accounted for initially. Running the cross with only one gene in mind gave wildly incorrect predictions. Another common issue is incomplete dominance. Heterozygotes show an intermediate phenotype rather than expressing the dominant trait fully. Snapdragons are the textbook case. A cross between red and white flowered plants produces pink offspring. When you run a dihybrid cross with incomplete dominance at both loci, you get 18 distinct genotypic classes instead of 9 phenotypic classes. The math works but the bookkeeping gets heavy fast.
Get the Full Details

When Dihybrid Crosses Fail You
These crosses assume large sample sizes. With fewer than 50 offspring, random sampling variation makes the observed ratios look noisy even when the underlying genetics are perfectly Mendelian. A sample of 20 might show 4:2:2:1 instead of 9:3:3:1 and a novice could mistake that for linkage or epistasis when it is just bad luck. Always aim for at least 100 progeny if you want meaningful statistical power. The method also does not handle sex-linked traits without modification. If one of your genes is on the X chromosome, the gamete probabilities differ between male and female parents. The Punnett square approach still works but you need separate squares for each sex or you combine them carefully accounting for the different inheritance patterns. I have seen people apply a standard dihybrid cross to an X-linked gene and wonder why their predicted ratios never matched reality.
Practical Tips That Actually Help
Use color coding when filling in squares. Different colors for different allele combinations reduce visual fatigue and catch transcription errors. I switched from pencil to digital spreadsheets a few years ago and cut my setup time from about five minutes per cross to under a minute. The spreadsheet also calculates expected and observed ratios automatically. The trade-off is you lose the tactile sense of the square. Some people find that writing it out by hand builds better intuition for the underlying mechanics. Keep a running log of every cross you run. Write down the parental genotypes, the observed phenotypes, the sample size, and whether the chi-square test passed. These logs become invaluable when you are trying to figure out why a later cross produced unexpected results. I once traced a weird ratio back to a mislabeled parent from three generations earlier. Without detailed records that would have been nearly impossible to track down. The method itself is reliable within its assumptions. The problem is almost always that the assumptions do not hold in practice. Genes link, traits interact, samples are small, and chromosomes do not always behave the way textbook examples suggest. Recognizing those failures early saves a lot of wasted time trying to force data into a model that was never going to fit.