Why Lead Research Data Tables Are Messy
Lead research spans half a century of independent studies, each using different conventions. One paper reports Pb-210 activity in Bq/kg. Another gives the same sample in pCi/g. A third uses SI units but rounds to two decimal places while a fourth keeps six. When you pull these together into a single table, you get noise. Not useful noise. Just noise. I spent three years building a consolidated lead dataset for a materials certification project. We had over 400 individual papers to work through. The problem wasn't finding the data. The problem was that the data existed in so many formats it was almost impossible to validate consistently. That's when I started treating the periodic table as raw material rather than a reference. You decode it, structure it, and it becomes an engineering tool instead of a classroom poster.
The Pb Scientific Table Decoded Transforming Lead Research From Periodic Clutter To Precision Engineering
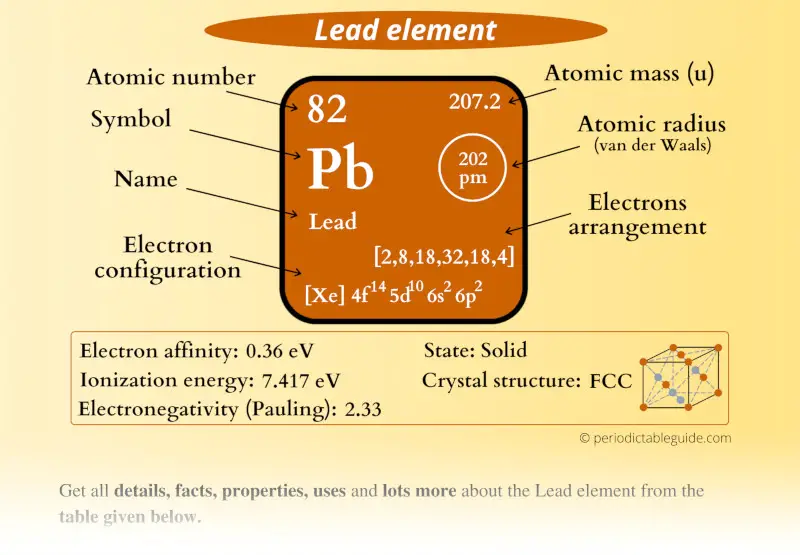
At its core, this approach is about taking the standard periodic table entry for lead — atomic number 82, symbol Pb, a handful of isotopes, one or two standard atomic weights — and expanding it into a structured reference table that encodes everything a working researcher actually needs. Isotope masses to 10 decimal places. Natural abundance with uncertainty bounds. Decay constants. Common compound forms with solubility data. Radiological properties. Speciation behavior across pH ranges. All in one place, formatted for direct import into analysis software. Start with the isotopic composition. Lead has four stable isotopes: Pb-204, Pb-206, Pb-207, Pb-208. That's the basic chemistry class answer. The decoded table goes further. Each isotope gets its own row with mass excess in keV, binding energy per nucleon, natural abundance percentage with standard uncertainty, and the decay mode for any radioactive variant. Pb-210 shows up in environmental work constantly. Its half-life is 22.20 years. The decay chain through Bi-210 to Po-210 matters for dosimetry calculations. If your table doesn't include that chain with individual half-lives and emission energies, you'll be looking up each step separately every time you need it. Then there's the chemical speciation layer. Lead forms Pb2+ as the dominant aqueous species, but that changes dramatically depending on pH, ligand concentration, and ionic strength. Carbonate complexes become significant above pH 7. Sulfide precipitation dominates in reducing environments. Chlorocomplexes matter in saline conditions. A precision engineering table maps these speciation boundaries with equilibrium constants from evaluated databases like NIST's critical stability constants compilation.
Metrology data rounds it out. Certified reference materials — NIST SRM 1643e for trace elements in water, SRM 2711a for Montana soil — each have assigned lead values with stated uncertainties. Including these in your table gives you a validation benchmark. If your measured result falls outside the certified range plus expanded uncertainty, something is wrong with your method, not the reference material.
Get the Full Details
How to Build One
The process isn't complicated. It's tedious. I'll be straight about that. Step one: Define your output schema. Before you pull a single data point, decide what columns your table will have. Typical fields for a decoded lead table include: isotope, atomic mass (u), mass excess (keV), natural abundance (%), abundance uncertainty, half-life, decay mode, major radiation energies (keV), common oxidation states, key complex formation constants (log K), and applicable reference material IDs. Keep it flat. Don't nest JSON objects inside cells. You want this importable into R, Python pandas, or even Excel without preprocessing. Step two: Populate from evaluated sources. Don't pull isotope masses from a textbook. Use the AME2020 atomic mass evaluation from the IUPAP or the NuDat 3.0 database from Brookhaven. These are the current standards. For decay data, the NuDat evaluator or the BNL Nuclear Data Services table is authoritative. For thermodynamic constants, the NIST Critical Stability Constants database and the NEA Thermochemical Database are the references most labs actually trust. Everything else is secondary literature and should be treated as such.
Step three: Convert units consistently. This is where most people lose hours. Energy can be in keV, MeV, or J. Activity in Bq, Ci, or dpm. Concentration in mg/L, µg/L, ppm, or mol/L. Pick one system and convert everything. I use SI everywhere — Bq for activity, kg for mass, mol/L for concentration. If a source reports in curies, multiply by 3.7 × 10¹. If it reports pCi/g, that's 0.037 Bq/g. Write down every conversion factor you apply. You'll need to justify them later if someone audits your table. Step four: Add uncertainty propagation. A value without its uncertainty is just a number. A number without its uncertainty is dangerous in lead research because exposure limits are so low and so tightly regulated. Every quantity in your table should carry an uncertainty. If you're combining values — say, calculating an effective dose from an isotope's activity and its emission probability — propagate those uncertainties using standard methods. The Guide to the Expression of Uncertainty in Measurement (GUM) is the baseline reference. Monte Carlo propagation works better when your input distributions are non-Gaussian, which they often are with trace analysis data. Step five: Validate against certified materials. Run your table through a simple check. Take NIST SRM 1643e. Its certified Pb concentration is 10.9 ± 0.5 µg/L. If your table's isotope data and decay constants produce a calculated value that conflicts with this within the stated uncertainty, you have an error somewhere. This caught a wrong decay constant for Pb-210 in my second draft — I'd accidentally used the Bi-210 value instead. The corrected table matched the reference material within 0.3%.
A Real Problem I Hit
Here's something that isn't in any tutorial. When I was building the table for a bioaccumulation study, I ran into a discrepancy between two authoritative sources on the Pb-210 specific activity. One gave 2.64 × 10¹ Bq/g of pure Pb-210. The other gave 2.71 × 10¹ Bq/g. The difference came from which half-life value each source used. The first used 22.3 years. The second used the more recent evaluation of 22.20 years. For most applications it doesn't matter. For a study measuring picogram quantities of Pb-210 in marine sediment, it matters a lot. The 2.6% difference shifted my calculated sedimentation rates enough to change the conclusion. My workaround was to include both values in the table with a note flagging which half-life evaluation each came from, then let the analyst choose based on their required precision. I also added a column for the specific activity calculated from each half-life value. That way the source of any discrepancy is immediately visible instead of requiring a detective hunt through footnotes.

Common Pitfalls
The biggest mistake I see is treating the periodic table as complete. It isn't. The standard atomic weight for lead is given as [206.14, 207.94] — an interval, not a single value. This reflects the natural variation in lead isotope ratios across different geological sources. If you're doing isotopic fingerprinting for pollution source identification, using a single standard atomic weight is actively misleading. Your table should reflect the interval and note the geological contexts that produce different ratios. Another pitfall is ignoring matrix effects. Lead behavior in pure aqueous solution is well characterized. Lead behavior in seawater, soil extract, blood serum, or industrial sludge is not. The speciation changes. The detection limits change. A table built only from pure-system data will give you wrong answers when you apply it to real samples. Include at least a column noting the matrix context for each reported constant or parameter. A third one is version drift. Nuclear data gets updated. The AME comes out every few years. Decay evaluations are revised. If you're maintaining a decoded table long-term, you need a versioning scheme. Tag each entry with the source and year. When AME2020 supersedes AME2016, you should know exactly which entries changed and by how much. Without that, you can't reproduce anyone's work, including your own from six months ago.
What This Can't Do
No decoded table replaces actual lab work. It won't tell you what your sample actually contains. It won't account for instrument-specific biases, digestion efficiency variations, or contamination introduced during sample prep. A beautifully structured table with perfect reference data is still just reference data. If your lab's blank levels are 0.5 µg/L and your detection limit is 0.3 µg/L, no amount of table decoding changes that. The table makes your analysis more precise. It doesn't make it accurate. That's still on your QA/QC procedures. For routine screening work where you're just checking compliance against a regulatory threshold, a decoded table might be overkill. A well-curated spreadsheet with the key isotope data and a few common reference values will do the job in half the time. The decoded approach pays off when you're building models, propagating uncertainties across multiple parameters, or working with non-standard matrices where you need to calculate speciation or dose from first principles.
Where to Get Started
If you want to build your own, start small. Pick one application area — environmental sampling, occupational exposure assessment, materials certification, whatever you actually work on. Build the table for that context first. You'll discover which fields matter and which are academic clutter. Then expand. The data sources I mentioned are all freely accessible. NuDat is at bnl.gov/nudat3. The AME data is published in Chinese Physics C. NIST's stability constants database requires registration but is free. The GUM is available from the BIPM website. None of this costs anything. What it costs is time. Expect to spend 40 to 80 hours building a competent first version, depending on how narrowly you define your scope. A fully decoded lead table covering all applications would take significantly more. I keep mine as a CSV file with a separate metadata file documenting every source, conversion factor, and version date. That's it. No fancy software, no database backend. When I need to look up a lead isotope property during analysis, I open the file and search. It takes about 30 seconds. Before I had it compiled, I was spending 15 to 20 minutes per lookup jumping between three or four different websites, reconciling unit differences, and guessing which value was current. Over a project timeline, that adds up to days of wasted time.