Understanding Time Zone Coordination in Distributed Systems
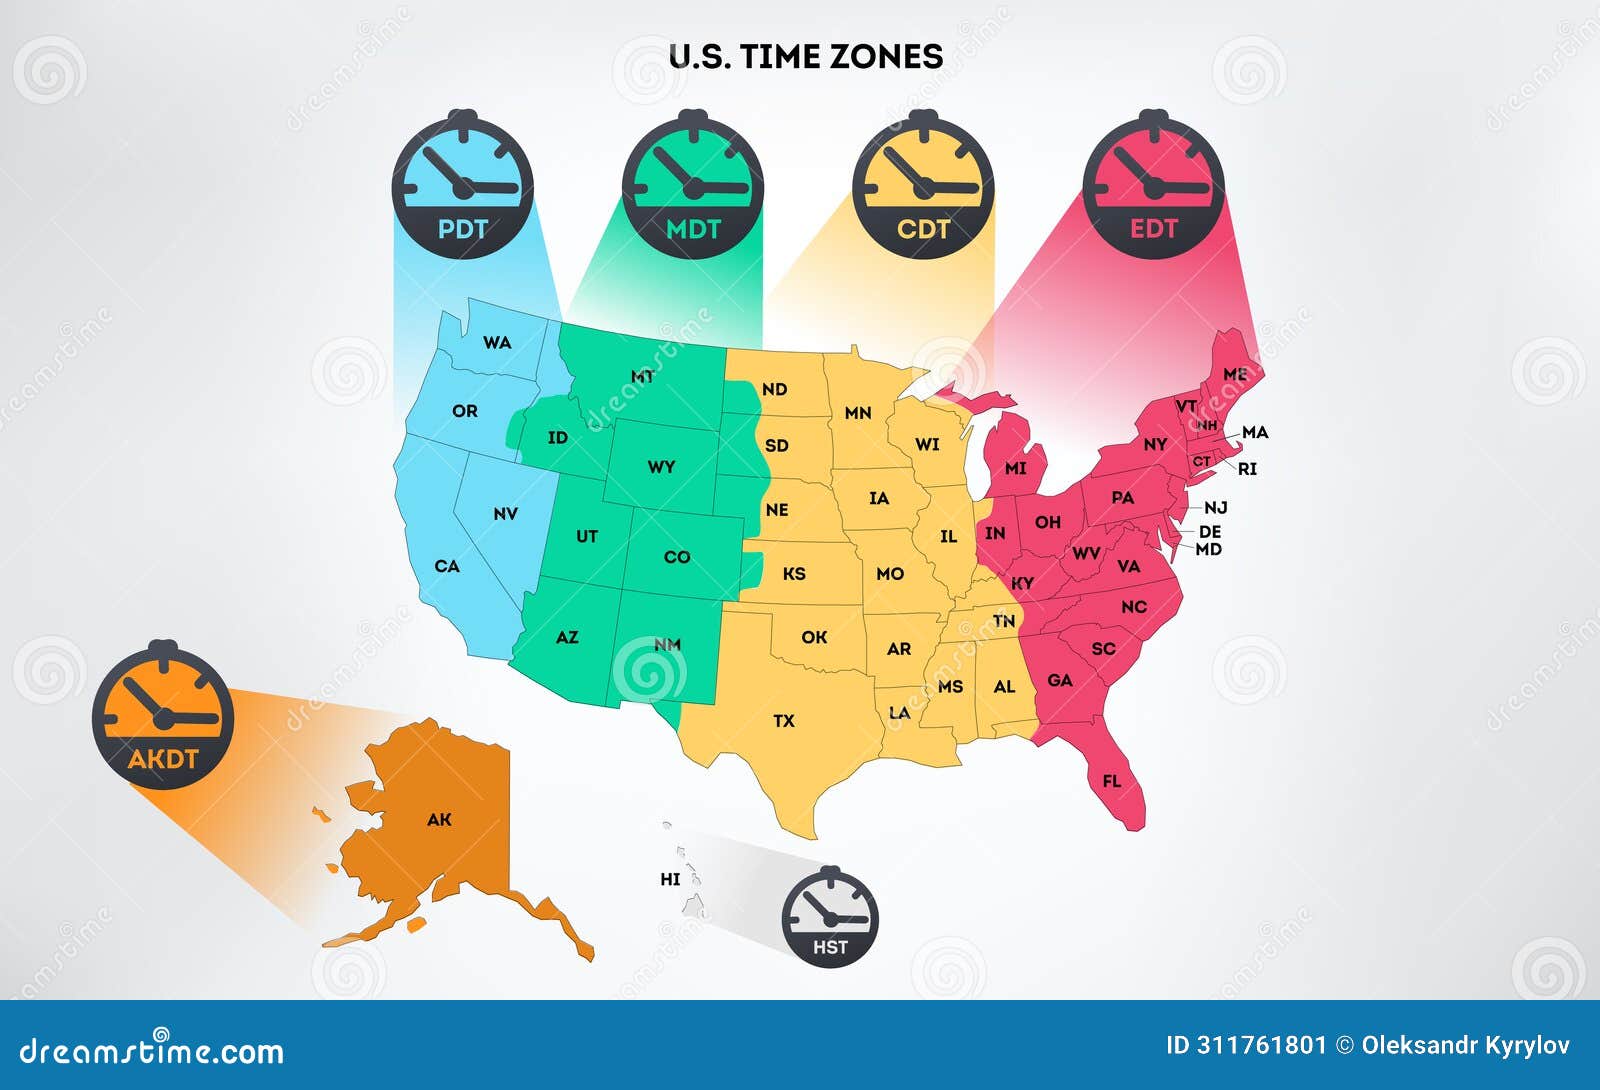
I spent three years debugging why our deployment pipeline kept failing at 3 AM Pacific time, and the root cause wasn't code. It was a cascading misunderstanding of how UTC offsets, daylight saving transitions, and server configurations interact across geographically distributed teams. The lesson: time zones aren't a minor detail. They're the invisible architecture that holds or breaks any system touching multiple regions. San Francisco operates on Pacific Time (PT), which switches between PST (UTC-8) and PDT (UTC-7) roughly twice a year. That switch happens on the second Sunday of March and the first Sunday of November. Most developers learn this the hard way—usually when their cron jobs run at the wrong local time and their users get confused. The city itself doesn't control the clock, but the ecosystem built there heavily depends on accurate time handling because the pace of innovation cycles moves fast enough that any timing mismatch compounds into real business impact. Here's what actually happens in practice. You build a system where a backend service in Oregon processes events, a database replica sits in Singapore, and the dev team monitors alerts from Portland. If you store timestamps as naive local times instead of UTC with explicit offsets, your cross-region aggregation breaks during DST transitions. I once had a reporting dashboard that showed negative durations for four hours because a query subtracted PDT timestamps from PST timestamps without normalizing. Took me two days to find it. The fix was using ISO 8601 format everywhere and converting at the boundary, not at the source.
How to Handle Time Zones Correctly in Your Projects
Start by making UTC your internal standard. Every timestamp that touches your database, API, or logs should carry an offset or be in UTC. When you need to display time to users, convert at the presentation layer using their stored timezone preference. This is the simplest rule and the one most people violate. In JavaScript, the new Date object stores time internally as UTC milliseconds but displays in local browser time by default. If you call date.getTime() you get a consistent value. If you call date.getHours() you get whatever the browser's timezone happens to be. I've seen production bugs where comparing two Date objects created on different machines in different timezones returned unexpected results because someone used value-of comparison on objects rather than their millisecond timestamps. In Python, datetime objects without timezone info are called "naive" and timezone-aware objects carry that context. Mixing them raises errors in Python 3.11+. The warning is there for a reason. I encountered a situation where a Celery task scheduled via crontab ran at 9 AM UTC but was documented as "9 AM Pacific" in the ticketing system. The deployment happened at 4 PM Pacific instead of 9 AM. Everyone assumed the timezone was understood. It wasn't. The task was configured with timezone='America/Los_Angeles' in the Celery beat config, but the cron expression itself was evaluated in UTC before that timezone override applied. Fix was switching to explicit schedule objects instead of raw cron strings.
Common Pitfalls That Will Cost You Time
DST is the biggest trap. The spring-forward transition skips an hour. The fall-back repeats an hour. Any system that schedules work based on wall-clock time will misfire during these windows unless it explicitly accounts for them. The US observes DST. Most of the world does not. If your user base is global, assume only a fraction of your users will follow the same calendar adjustments. Database timezones are another quiet failure point. PostgreSQL stores timestamps without timezone info as naive UTC if the server is configured that way, but timestamp with timezone converts to the session's timezone on output. If your application connects to the database and the session timezone is unset or inherited from the OS, you might be writing and reading back different representations of the same instant. MySQL behaves differently—it stores DATETIME as naive values and TIMESTAMP in UTC but converts to the connection timezone on retrieval. These differences matter when you migrate between systems or connect from services running on different OS images. I ran into a case where Docker containers running the same image had different timezone configurations because one build stage copied a local /etc/timezone file and another didn't. The container orchestration platform didn't set TZ uniformly across pods. Two services processing the same event stream disagreed on whether an event happened at 11:59 PM or 12:59 AM. The discrepancy went unnoticed for six weeks because logs were filtered by local time strings rather than epoch seconds.
Get the Full Details
What Works in Practice
Use named timezone identifiers, not fixed offsets. America/Los_Angeles is better than UTC-8 because it encodes the DST rules automatically. Fixed offsets don't adjust when the region changes its policy. I've seen teams hardcode -08:00 and then spend a month patching code every time a territory changed its DST rules, which happens more often than you'd expect. Store everything in microseconds since the Unix epoch. This gives you a single integer that no timezone can misinterpret. Convert to human-readable formats only when pushing data out to APIs or UIs. For internal communication between services, epoch integers eliminate ambiguity. The tradeoff is readability in logs, which is why many teams use epoch for computation and human-readable strings only for debugging output. When you must work with calendar dates—like "the last day of the month" or "the third Friday"—use a library that understands the timezone context of that date. dateutil in Python, java.time in Java, and moment-timezone or the native Intl API in JavaScript all handle these operations correctly when given an explicit timezone. Without one, they default to the host environment's timezone, which is a deployment-dependent behavior that changes when you move from dev to staging to production.
There's no universal solution that handles every edge case. Some legacy systems export timestamps as strings in formats like "MM/DD/YYYY HH:mm:ss" without any timezone indicator. You can't reliably parse those without additional context. In those cases, the workaround is usually to trace the data back to its origin and insert timezone metadata at the ingestion point rather than trying to guess it from the content. Time zone handling will always require more attention than developers want to give it. The systems that get it right do so by treating timezone as a first-class concern from day one, not as an afterthought patched in before launch. The cost of getting it wrong scales with the number of regions you serve. The cost of getting it right is a few extra lines of configuration and a discipline of never storing naive timestamps in persistent storage.