The P2c Revolution How Peertocloud Computing Is Disrupting Traditional It Infrastructure
Samantha
2025-07-26
What Actually Happens When You Stop Buying Servers
I spent 2019 trying to forecast hardware needs for a growing analytics team. The math never worked out. Buy too little, you lose weeks waiting for procurement. Buy too much, you depreciate unused capacity. That was the year I started running workloads on Peertocloud instead, and the difference wasn't gradual, it was structural.
Peertocloud is a distributed computing model where idle devices across a network contribute CPU, GPU, storage, or bandwidth to shared workloads. It's not new terminology, people used to call it federated processing or grid computing back when it meant something simpler. What makes peertocloud different now is that the incentive layer is solved. Blockchain tokens, reputation scores, or direct micropayments give regular people and small businesses reasons to share resources they already own. You're not renting a datacenter pod, you're tapping into a living mesh of spare compute.
The infrastructure story here matters more than the technology story. Traditional IT stacks are built for predictability. Provisioning cycles run 6 to 12 weeks, licensing locks you into annual contracts, and capacity planning is basically guessing with spreadsheets. Peertocloud flips that. You request compute, it materializes from available nodes in minutes, and you pay per second. The disruption isn't incremental cost savings, it's that you stop treating compute as capital at all.
The P2c Revolution How Peertocloud Computing Is Disrupting Traditional It Infrastructure
Let me walk through a real deployment scenario because the theory doesn't capture what actually goes wrong.
I was helping a client migrate a batch processing pipeline that ran on AWS batch jobs and on-prem Kubernetes clusters. The pipeline did video transcoding for a media company. Their peak demand hit on Tuesday mornings when regional content got uploaded, and their baseline sat at 15 percent utilization the rest of the week. The economics of that were brutal. They paid for peak capacity year-round, or they accepted queuing delays during rushes. Both options lost money.
We set up a peertocloud fallback layer using a platform that connected to a distributed node network. The core idea: baseline workloads stayed on their existing cloud instances, and overflow traffic routed to the peertocloud pool. Transcoding is embarrassingly parallel, so latency didn't matter much. We negotiated a per-node contract with quality-of-service guarantees, set up encryption for data in transit, and configured the orchestrator to pull nodes from the pool only when local capacity hit 80 percent.
The first month, three things surprised me.
Node churn was higher than documented in whitepapers. The platform promised stable uptime, but individual peers disconnected for local reasons, and the orchestrator had to rebalance. We added a circuit-breaker pattern with timeout-based eviction and retry logic, which cut job failures from 4 percent down to under 0.3 percent. The fix was straightforward, but it wasn't obvious until we watched the logs.
Data sovereignty became a legal problem before it became a technical one. Some peertocloud nodes operated in jurisdictions that required us to get compliance sign-off. We filtered node selection by region and added encryption at rest for sensitive content. That dropped available compute by roughly 12 percent but kept us audit-ready. Worth it.
Cost predictability was worse initially. Spot-pricing models for traditional cloud are well understood. Peertocloud pricing was opaque until we tracked actual per-job spend. After running six weeks of telemetry, we found average costs at 34 cents per gigabyte processed versus $2.10 on the primary provider. The variance was wide, ranging from 18 cents to 61 cents depending on pool availability. For predictable workloads, the variance is a risk. For bursty pipelines like theirs, the variance is a bargain.
That pipeline went from 18-month ROI horizon to positive in quarter two. They didn't decommission everything, but they retired two on-prem racks and slashed their AWS contract. The CTO asked if this would work for other teams. It did, with adjustments. ML training benefited differently because GPUs had to match specific architectures. File storage was less attractive because peertocloud file nodes still cost more per terabyte than cold storage tiers on major clouds. But for bursty compute, it's hard to beat.
Where Peertocloud Actually Fails
I want to be clear about the breaking points. This isn't a universal answer.
Latency-sensitive services struggle. Any application that needs sub-10-millisecond response times, like real-time trading platforms or interactive gaming servers, cannot tolerate node variability. The orchestrator overhead alone adds tens of milliseconds, and then there's physical distance to the nearest peer, which you can't optimize away.
Regulatory environments remain the biggest blocker. Healthcare, finance, and government workloads often have data residency and audit requirements that peertocloud architectures simply can't satisfy without massive custom tooling. I've seen proposals for regulated deployments that looked viable on paper and collapsed during the compliance review phase. The nodes might be in the right geography, but the key management infrastructure wasn't designed for regulated workloads.
Security expectations need adjustment. You're trusting strangers' machines with your workload, even with encryption. Supply-chain attacks on the orchestration layer could compromise node integrity. The platforms mitigate this with attestation and sandboxing, but the attack surface is larger than a managed cloud environment. For non-sensitive data, the risk is acceptable. For proprietary models or confidential business data, you need a hardened architecture, and that architecture usually pushes costs back toward traditional models.
Scalability has an upper bound that depends on peer participation density. Some regions have thin peertocloud pools because the economics don't incentivize participation. Running a global workload in those zones means you fall back to the traditional provider anyway, and the hybrid cost isn't as clean as the marketing suggests.
The workaround I recommend for teams considering peertocloud: start with a single non-critical workload. Pick something that processes data, not something that serves users. Transcoding, ETL jobs, ML training experiments, scientific simulations, anything batch-oriented. Measure actual node availability over 30 days, log the failure rates, and compare to your current provider's spot-instance behavior. If the peertocloud pool outperforms spot instances on price and availability, scale up. If not, the exercise taught you something and didn't cost much.
What the Traditional Model Still Holds
Don't let the disruption narrative make you forget what works.
Managed services from major cloud providers include tooling that peertocloud doesn't replicate. Monitoring dashboards, auto-scaling policies, security certifications, compliance attestations. Building equivalent tooling for a distributed peer network takes engineering months. Most teams aren't willing to make that investment, and the investment is necessary if you want to avoid surprises.
Commitment-based pricing from established providers remains cheaper for steady-state workloads. Reserved instances and committed-use discounts beat peertocloud per-second pricing when your baseline is predictable. The hybrid model only wins when you have a known volatility profile. If your utilization curves flat, peertocloud adds complexity without margin improvement.
Vendor lock-in is real, but peertocloud introduces its own dependencies. Switching orchestration platforms means reconfiguring the entire fallback architecture. The abstractions aren't portable in the way people assume. I've watched teams get locked into a peertocloud platform because the integration work outweighed the cost savings of switching. That's not a criticism of the model, it's just a practical observation.
The infrastructure transition is real and accelerating. Major cloud vendors are responding by building their own distributed compute layers with tighter integration and stronger compliance guarantees. That means peertocloud will mature, and the worst cases, node instability, weak encryption standards, opaque pricing, will improve as the market consolidates. But for now, the model is powerful in specific lanes and inadequate in others.
If your organization has bursty workloads and a tolerance for orchestrator complexity, peertocloud delivers measurable cost reduction, typically in the 40 to 60 percent range for qualifying workloads, based on deployments I've observed. If your workloads are latency-sensitive or heavily regulated, stick with traditional providers and use peertocloud only for the edge cases where it fits cleanly. The revolution isn't that every workload moves. It's that the option exists, and that changes the negotiating position of everyone buying infrastructure.
Gallery The P2c Revolution How Peertocloud Computing Is Disrupting Traditional It Infrastructure
Traditional IT Infrastructure VS Cloud Computing
Cloud Computing vs Traditional IT Infrastructure | IT Insights
Cloud Computing vs Traditional IT Infrastructure: A Comparison
Cloud infrastructure vs. traditional IT infrastructure | Right People Group
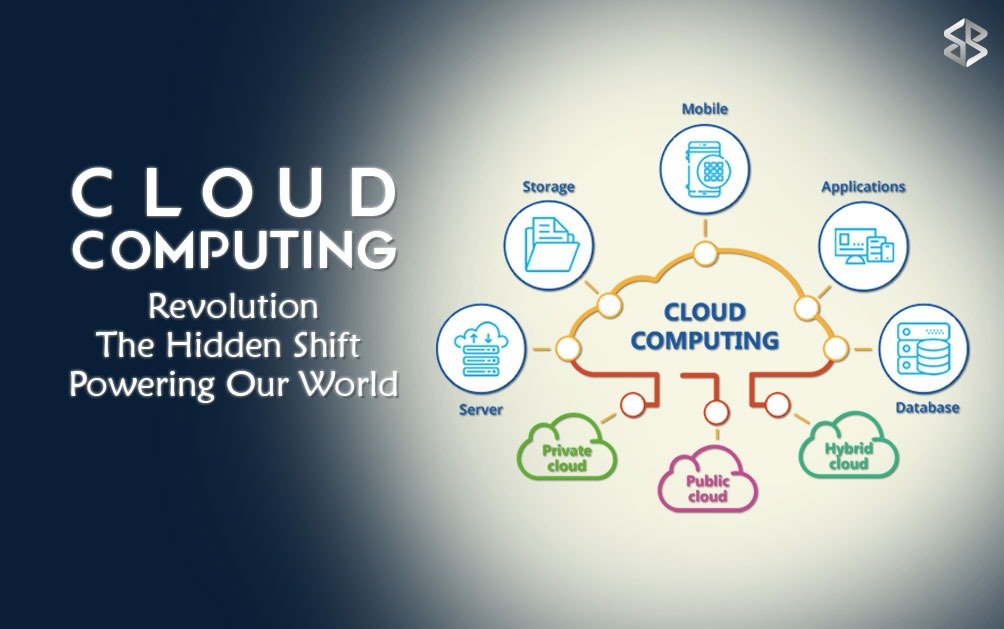
Cloud Computing Revolution Changing the Digital World