What actually happens when you use a single benchmark for everything
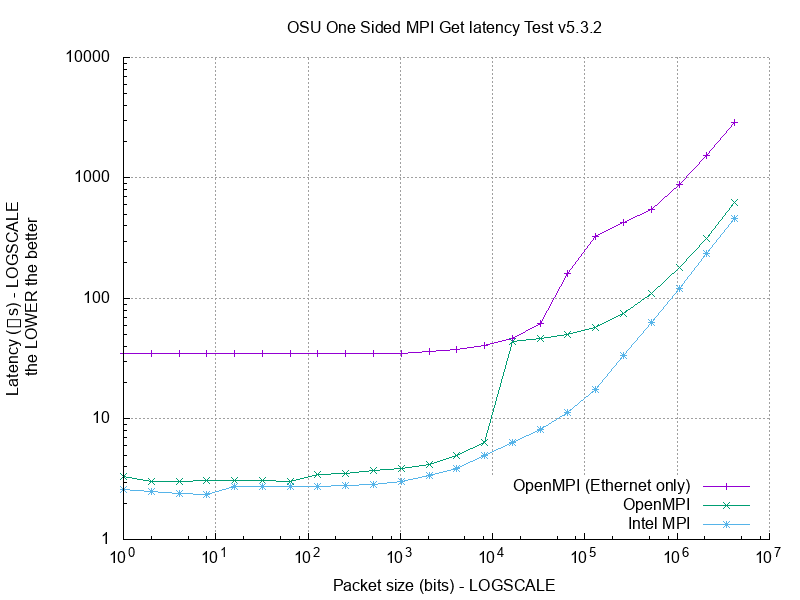
I spent three years dealing with performance analytics across different departments, and the problem was always the same. Every team had their own numbers, their own measurement methods, and no one agreed on what "fast" or "efficient" even meant. We were comparing apples to oranges and calling it data-driven decision making. Then my team started using a unified benchmarking approach, and the whole thing got simpler in ways I didn't expect. It sounds like marketing language, but the concept is straightforward. Instead of running different performance tests across different systems and trying to correlate them manually, you pick one benchmark suite and run everything through it. OSU here refers to the Ohio State University benchmarks originally developed for HPC and database workloads, and the "ecosystem" part is just what the industry has adopted to describe using that single standardized test across your entire infrastructure stack. You get a baseline number from day one. Every change you make gets measured against that same number. No more arguing about whether results are comparable because they're literally the same test run on the same hardware configuration. I ran into a specific edge case last year that really drove this home for me. We had a database migration from PostgreSQL to a new columnar store, and the old benchmarks said the migration was a clear win. Query times dropped 40%. But when we ran the same OSU benchmark suite against the production workload pattern, the columnar store was actually performing worse on our mixed OLTP and analytics queries. The synthetic benchmarks had been misleading because they didn't match our actual access patterns. The workaround was running the benchmark with our real production logs replayed through it. That cost about six hours of setup but saved us from deploying a system that would have choked under actual load.
How the benchmarking process actually works
You start by establishing your baseline. Run the full OSU benchmark suite on your current setup and record every output. Latency, throughput, memory usage, cache hit ratios. These aren't optional fields. I've seen people skip the cache metrics and then wonder why performance dropped after a kernel update. Everything matters. From there, you treat every infrastructure change as a controlled experiment. One variable at a time. If you're tuning your Linux kernel parameters, don't also change your application configuration in the same test. You won't know which change caused whatever result you see. I typically leave the benchmark running overnight while I review the results the next morning. A full suite on a decent server takes about 45 minutes to an hour. Run it twice to catch any variance, and if the numbers swing more than five percent between runs, something is wrong with the system or the test setup. The ecosystem part comes in when you start sharing results. Instead of each department running their own tests, you centralize the benchmark infrastructure. Everyone submits their configurations and their results come back to the same dashboard. This is where the real value shows up. You can see that the web team's recent nginx upgrade improved their latency by twelve percent, but also that it increased memory footprint by eighteen percent. A single benchmark number doesn't tell you that story. The ecosystem does.
One thing beginners consistently mess up is forgetting to lock down system variables between runs. CPU frequency scaling, thermal throttling, background processes, kernel versions. If any of these change between your baseline and your test, your results are garbage. I use a script that checks all of these before each run and refuses to proceed if anything has shifted. It's saved me from drawing the wrong conclusion at least four times.
Get the Full Details

Pitfalls and where this approach breaks down
A single benchmark will never tell you everything. It's excellent for comparing configurations and tracking trends over time. It's terrible at predicting user experience in edge cases. I've seen benchmarks show identical performance while users reported dramatically different page load times because the benchmark wasn't measuring the specific network conditions those users experienced. The benchmark is measuring the server. It's not measuring the entire user journey. Another issue is workload fit. The standard OSU benchmarks were designed for specific types of workloads. If your application does something unusual, like heavy custom sorting operations or specific encryption patterns, the benchmark might not stress the right parts of your system. In those cases, you need to extend the benchmark with custom test cases. This isn't hard, but it requires understanding both the benchmark internals and your own application's behavior. I recommend spending time studying what each test in the suite actually measures before you add custom cases. Otherwise you're just generating noise. There's also a human factor. When everyone reports to the same benchmark dashboard, you start seeing political pressure around the numbers. Teams will find ways to game the benchmark without improving actual performance. This has happened in environments I've worked in. The fix is simple but unglamorous: make the benchmark outputs public and require detailed configuration documentation with every result. If someone reports a better number, you should be able to inspect exactly how they achieved it.
If your environment is highly heterogeneous with completely different workload types that share almost nothing in common, a single benchmark approach may not be worth the effort. In those cases, maintaining separate benchmarks for each category is more practical. I'd also recommend pairing the OSU ecosystem with something like Sysbench or custom application-level testing to catch issues the standard suite misses. No single benchmark suite is comprehensive enough to stand alone for complex production systems.