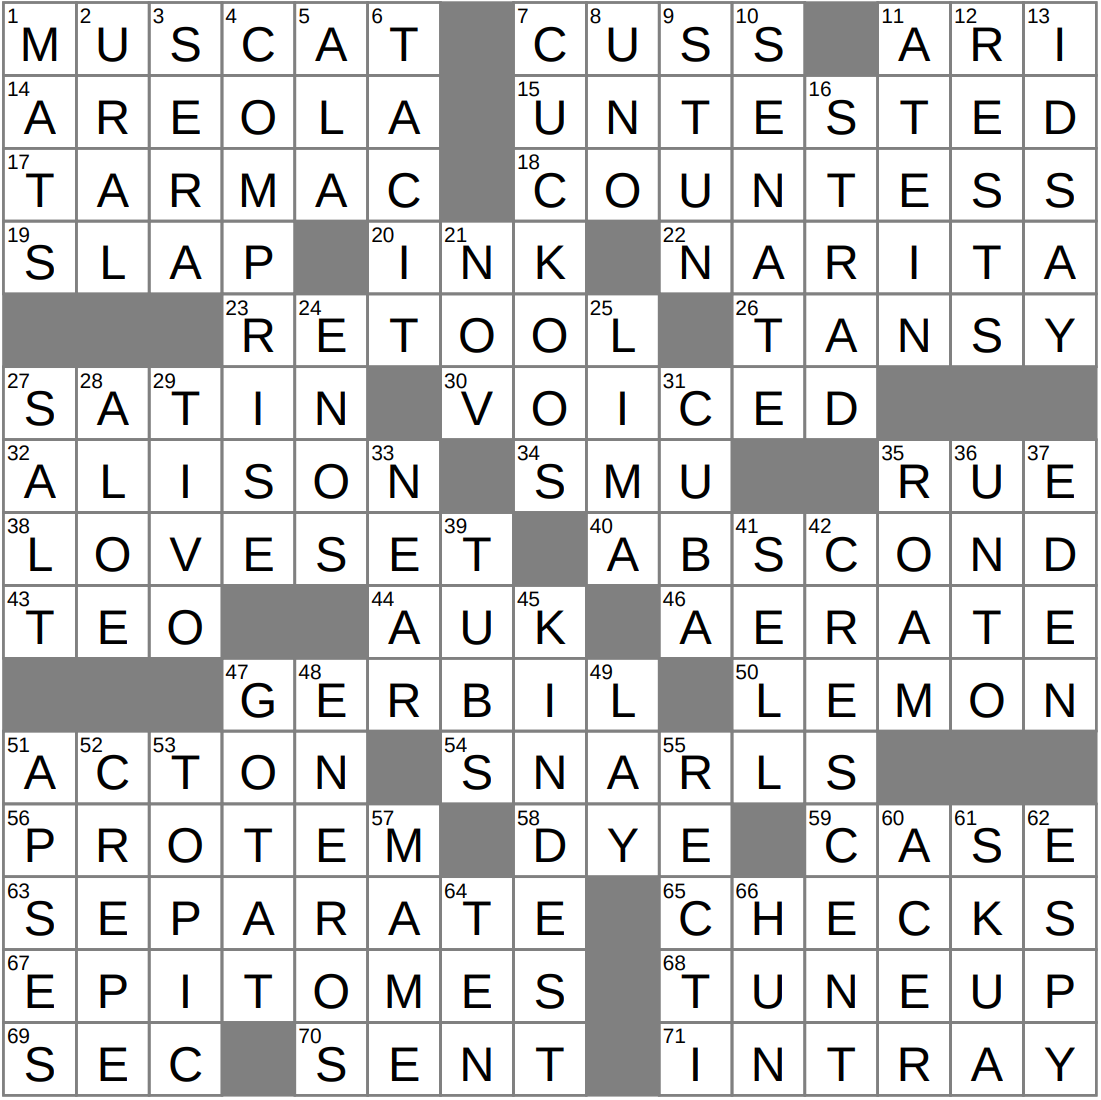Why People Actually Use The NYT Crossword Archive
The New York Times crosswords have been published since February 15, 1942. Before that, the puzzle appeared in other newspapers. The Times acquired the rights and kept running them daily. Today the archive stretches from that first Tuesday in 1942 through every puzzle published since. That is roughly 84 years of content, though the digitized versions are uneven in quality across the decades. Most people who dig into the archive are not doing it for fun. They are chasing specific clues they encountered in a puzzle they could not solve. Or they are analyzing constructor patterns. Or they are studying how vocabulary has shifted over time. The archive does all of those things, but it is not designed as an academic research tool. It is designed for solvers. That matters when you start working with it.
The Nyt Crossword Archive Charting A Century Of American Wit And Vocabulary
The phrase sounds like a headline or a marketing blurb, but it captures something real. The crossword archive is a record of how American English has changed. Clues that would have been common in 1955 are gone now. Words like DANIEL BOONE'S HOME or OLD HOME STATE appeared regularly. Clue styles have shifted from straightforward to intentionally misdirecting. Constructors have introduced more thematic complexity over the decades. You can see all of that if you know where to look and how to parse the data. I spent several months pulling crossword data for a personal project last year. I wanted to understand how clue difficulty correlates with publication day of the week. Monday puzzles are traditionally easier. Sunday is the big one. But the middle-of-the-week puzzles have their own rhythm. The archive helped me see patterns I would have missed otherwise. It also exposed me to a lot of frustrating edge cases.
How to Access the Archive
The official route is the New York Times website. They host a searchable archive for subscribers. Non-subscribers get limited access. The free tier typically shows you a handful of recent puzzles and basic metadata. Full access requires a subscription, which changes price periodically. As of my last check, it was around $16 per month for digital-only access. That covers everything from 1942 forward, including all past Sunday puzzles. There are also third-party sites that aggregate crossword data. Sites like MetaFace, Baffler, and Cruciverb offer varying degrees of archive access. Some are subscription-based. Others are free but rely on community maintenance. The quality varies significantly between them. I tend to use the NYT site for primary research because their data is the source of truth. Third-party sites are useful for quick lookups or when the official site is down. One problem I hit repeatedly: the archive search on the NYT site sometimes returns duplicate entries for the same puzzle. This happens because puzzles are tagged with multiple dates due to holidays, special editions, or editorial scheduling. If you search for a specific date range, you may get the same puzzle listed twice. My workaround was to use the puzzle's unique identifier, usually found in the URL or page metadata, rather than relying solely on date-based searches. Each puzzle has a consistent internal ID that does not change, even if the publication date shifts.
Get the Full Details

What Makes the Archive Useful Beyond Solving
The most obvious use is solving. You get stuck on a clue, you search the archive, you find the answer. Simple. But the archive is richer than that. It is a dataset. Researchers have used it to study language evolution, cultural references, and even economic trends embedded in clue construction. For example, clues about brands, products, and pop culture shift over decades. A clue referencing a TV show from 1970 will not appear in the same form in 2024. Clues about technology have changed dramatically since the internet era began. You can trace that trajectory by browsing puzzles from different decades. The archive makes this possible if you know how to filter by date. Another use case is constructor analysis. Certain names appear repeatedly. Will Shortz has been the editor since 1993, and his influence is visible in the puzzle style. Before him, Martin Naydokin and Eugene T. Maleska shaped the paper for decades. Constructors like Jack Bell, Emily Cox, and Henry Rathvon have distinctive approaches. If you want to understand puzzle construction, the archive lets you compare styles across constructors and eras.
Common Pitfalls When Using the Archive
First, do not assume the archive is complete. Some early puzzles, particularly from the 1940s and 1950s, have gaps. The Times lost or destroyed some files. Weathered physical copies did not survive well. You will notice missing dates when searching. This is not a technical glitch. It is a historical reality. Second, be aware that the digital versions are not always accurate transcriptions. The Times invested in scanning and OCR processing, but errors exist. Typos in clues, incorrect grid fillings, and misattributed constructors occasionally slip through. I encountered a puzzle from 1958 where the published answer did not match the grid. I had to cross-reference with a physical copy I found at a local library. This is rare, but it happens. Always verify if a result seems wrong. Third, the search interface is not intuitive. The NYT archive uses a dated search system that can be slow and unintuitive. Boolean operators work, but the syntax is not always clear. Pagination is limited. If you are pulling large datasets, you will need to chunk your queries. I learned this the hard way after a single search attempt timed out after I tried to pull 2,000 puzzles at once. Breaking the request into 200-puzzle batches resolved the issue.
A Practical Workflow for Serious Researchers
If you are doing something substantial with the archive, here is a routine that works: Step one: Define your scope. Are you looking at a specific decade? A particular constructor? A theme type? Narrow your focus before you start searching. The broader your query, the more noise you will deal with. Step two: Use the NYT subscription site for accuracy. Pull data in manageable batches. Save each batch as a CSV file. I use Google Sheets for initial parsing because it handles large datasets reasonably well. Excel works too, but it slows down past about 50,000 rows.

Step three: Cross-reference with third-party sites for verification. If a clue or answer looks off, check MetaFace or Cruciverb. These sites often have community corrections that catch errors the Times misses. Step four: Document your findings. Keep notes on anomalies. The archive is not perfectly curated, and your notes will help others who come after you.
Why This Matters Now
The crossword community has grown significantly in recent years. More people are solving, discussing, and analyzing puzzles online. The archive is a foundational resource for that community. It is not glamorous. It is not easy to navigate. But it is essential if you want to understand the puzzle as a cultural artifact, not just a pastime. I will say this bluntly: the NYT archive is not perfect. It has gaps, errors, and interface issues. But it is the single most comprehensive collection of American crossword history available. For anyone serious about the craft, it is indispensable. Just go in with realistic expectations. It is a tool, not a treasure chest. You have to know how to use it.