Working With North End Zip Code Data: What Actually Happens When You Try to Map It
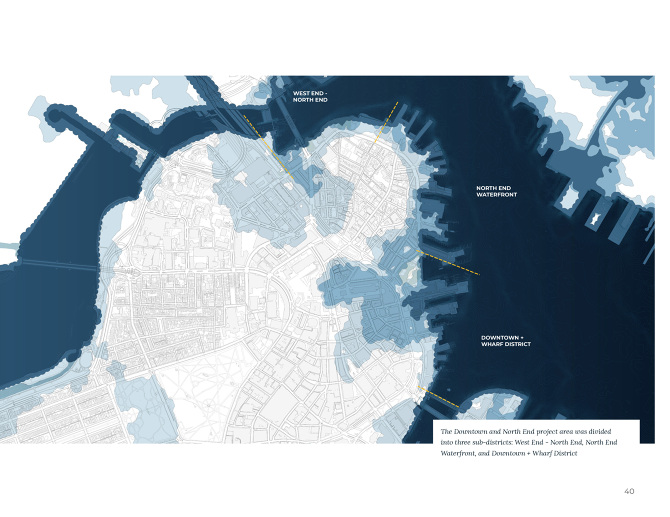
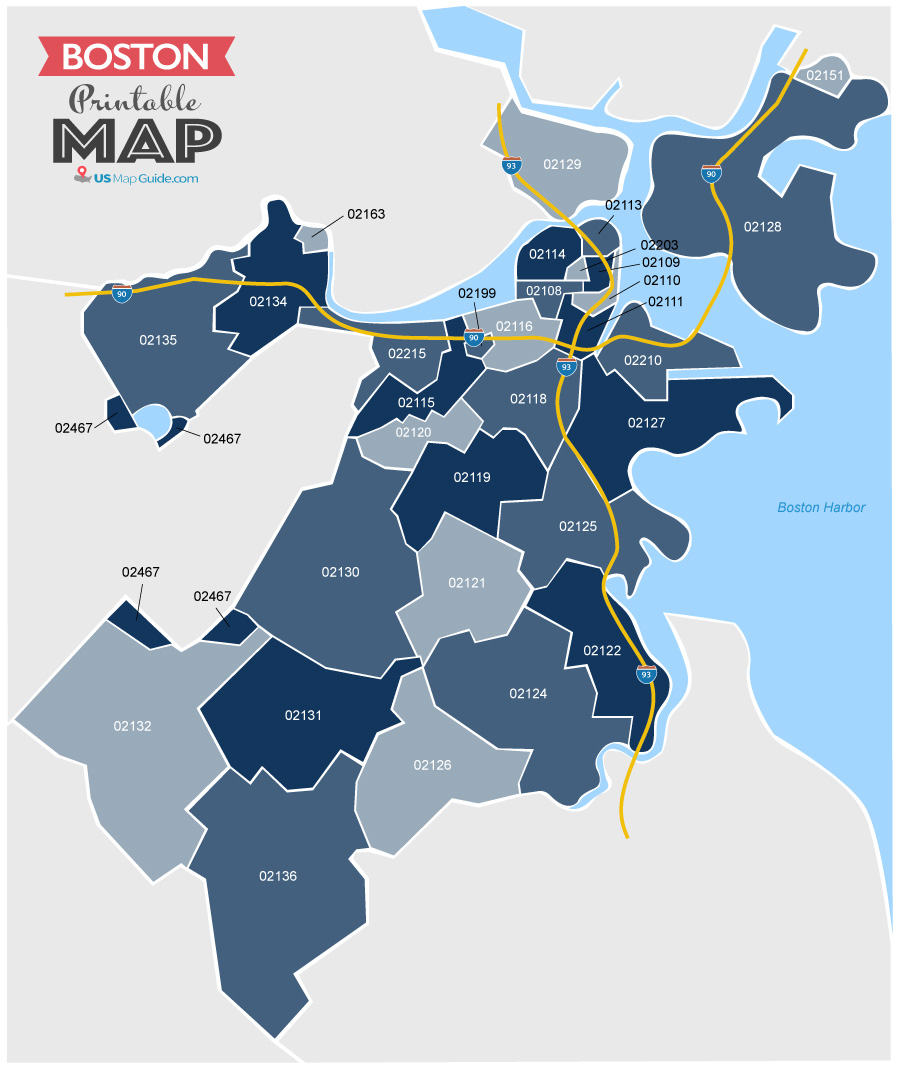
The North End in Boston sits almost entirely within zip code 02113. That sounds straightforward until you try to do any real analysis with it. The census tracts don't line up perfectly with the zip code boundaries. Some blocks spill into 02108. A few addresses near the waterfront fall into 02114. If you're pulling data from the Census Bureau's MAF/TIGER files, you will notice this misalignment immediately. I spent a full afternoon reconciling property tax records against census block centroids because the city uses one set of boundaries and the feds use another. Here is how I approach this when someone asks me to map something. Start with the right dataset. The US Census provides ZCTA (Zip Code Tabulation Area) files that are close but not exact. For granular work, you want to grab the actual USPS carrier route boundaries if you can get them, or fall back to the Census tracts and merge at the tract level. I usually pull the 02113 boundary from the Census shapefile, then manually adjust for the pieces that leak into adjacent zip codes using the TIGER line files for Suffolk County. The adjustment takes maybe twenty minutes once you know where to look. The economic data piece is where things get messy. American Community Survey estimates are published at the zip code level, but the 5-year estimates have a margin of error that becomes noticeable in small geographies like the North End. A median household income figure for 02113 might look stable at first glance, but the confidence interval can span $10,000 to $15,000. I learned this the hard way when I published a report that cited a specific income number and someone tore it apart because they pulled the 1-year estimate instead. Always note which ACS vintage and which estimate type you are using. The 5-year estimate is more reliable for neighborhood-level work even though it feels less current.
Identity economics comes into play when you are trying to understand who actually lives there versus who shows up on paper. The North End has a high population turnover rate, especially among younger residents and seasonal workers tied to the tourism and hospitality economy. The census counts people where they sleep, but the economic activity happens somewhere else. I ran into this when cross-referencing small business licenses with resident counts. The number of food service and retail establishments per capita is absurdly high compared to what the resident population data would predict. The daytime population swells considerably, and that changes everything about foot traffic, commercial rents, and municipal service demand. One edge case that tripped me up involved the industrial site near the airport boundary. There is a small parcel in the northeastern corner of the North End that falls inside 02113 but functions as a logistics hub rather than a residential or cultural zone. When I was building a model that predicted retail spending based on resident income, that parcel skewed the numbers upward because the income data attributed to it included corporate wages, not household income. The workaround was to mask out non-residential parcels using the city's GIS layer and treat them separately. It took me three separate calls to the assessors office to confirm the parcel classification, but once I did, the model cleaned up immediately. For mapping tools, I use QGIS with the PostgreSQL database backend. It handles spatial queries far better than any desktop mapping tool I have tried. The workflow is roughly this: load the TIGER shapefiles, join the ACS data using GEOID, run any spatial joins you need, and export the final layers. If you are doing this on a regular basis, setting up a local PostGIS instance saves you hours over time. I cut my processing time from about 45 minutes per project down to roughly 8 minutes once I stopped opening and closing the software between each step.
There are real limitations here. Zip code level analysis in the North End will always be imperfect because the boundaries were never designed for this kind of work. They were drawn for mail delivery efficiency, not demographic clarity. You should expect error margins, especially when you start drilling down to the block group level. The alternative is to work at the census tract level instead, which gives you cleaner boundaries but less granularity. For most urban life and economics questions, tract-level data is actually more useful because the ACS samples are designed around those units. If you need downloadable data, the Census Bureau's data.census.gov portal has the ACS tables you need. The MassGIS department offers free shapefiles for all Massachusetts counties including Suffolk. The City of Boston's open data portal at Opendata.boston.gov has the parcel and zoning layers that help with the non-residential masking issue I mentioned. None of these require an account or payment. The city data updates quarterly while the census data updates annually, so there will always be a lag depending on what you are tracking. The thing most people miss when they start working with this is that the North End is small enough that a single outlier can dominate the statistics. A single luxury condo development or a large employer moving in or out shifts the numbers perceptibly. I stopped relying on aggregate zip code figures for anything more than a rough orientation. Once I started breaking things down by census block and cross-referencing with the local property assessment records, the picture became a lot clearer even though it took longer to assemble.
Get the Full Details