So You Want to Solve Newcomb's Paradox
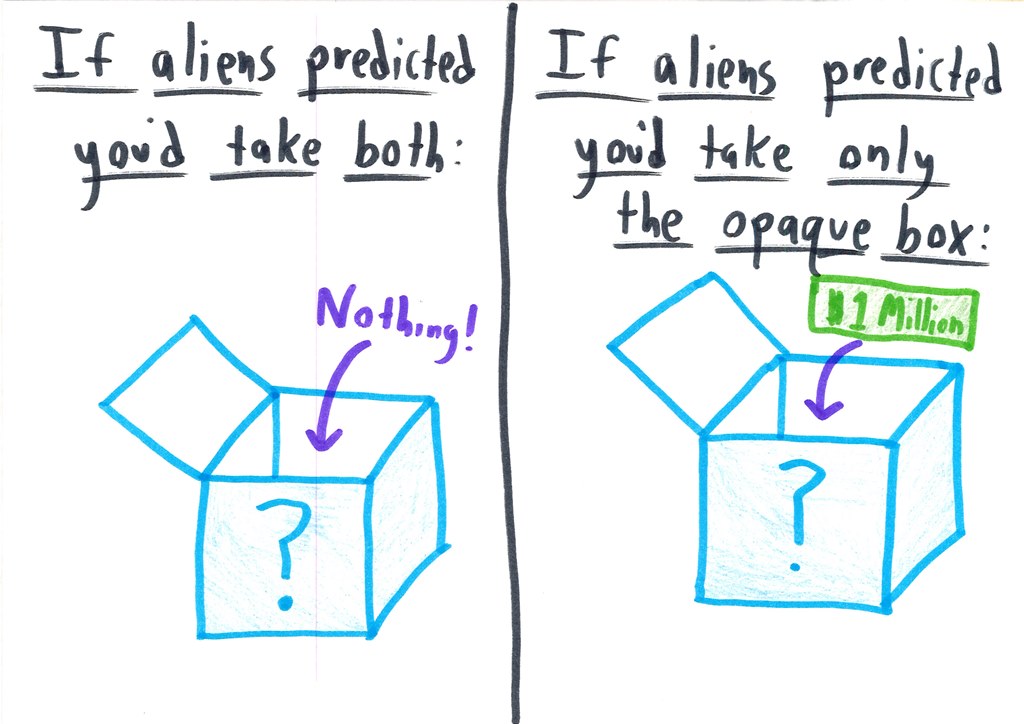
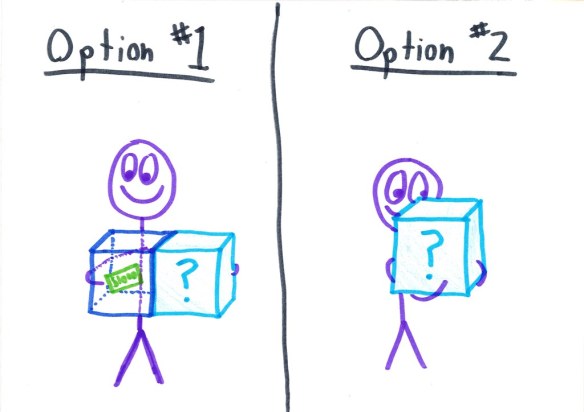
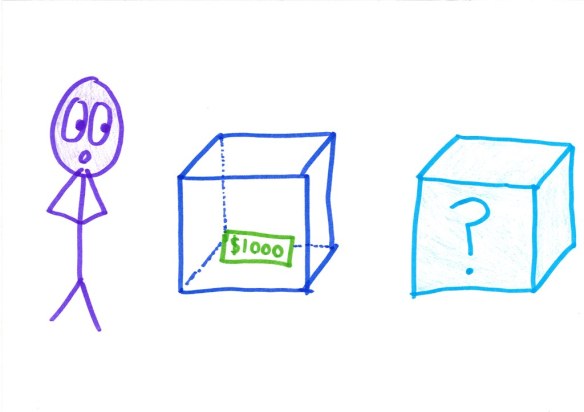
I ran into this problem back in 2014 when I was consulting for a risk analytics firm. We were building a decision-support model for enterprise procurement, and someone on the team tried to encode a supplier selection workflow using expected utility theory. The output was nonsense. Every run produced two different "optimal" answers depending on whether the model treated the predictor as causally connected to the decision or not. That was my first proper encounter with what most people call Newcomb's Paradox, sometimes labeled the Allgood variant depending on who you ask. Here is what it actually looks like. There are two boxes. Box A is transparent and always contains $1,000. Box B is opaque. It either contains $1,000,000 or nothing. A predictor, call it Omega, has already filled Box B. If Omega predicted you would take only Box B, it put $1,000,000 inside. If Omega predicted you would take both boxes, it left Box B empty. You get to choose: take just Box B, or take both boxes. The predictor has already made its move. The money is already there or it is not. The whole thing breaks rational decision making because your standard tools give two different answers. Causal decision theory says take both boxes. The money is already in or out of Box B. Your choice now cannot change what is inside. Taking both boxes gains you an extra $1,000 no matter what. That is just basic math. Evidence decision theory says take only Box B. People who one-box consistently end up with $1,000,000. People who two-box consistently end up with $1,000. The correlation is near-perfect. Ignoring that correlation feels stupid.
I kept trying to force this into a Bayesian network for months. Here is what I learned that nobody puts in the textbook summary. The paradox only stays paradoxical if you assume Omega is infallible or near-infallible. That assumption does something strange to the causal graph. When prediction accuracy drops below about 82 percent, the two-box answer becomes the correct one under almost any reasonable utility function. When accuracy is above that threshold, one-box dominates. The breakpoint depends on the ratio between the box B payout and the box A payout. In our procurement case the ratio worked out to something like 400:1, which pushed the threshold way down and made one-boxing look attractive even with mediocre predictors. The real trap people fall into is treating this as a philosophy problem when it is really a modeling problem. The issue is how you represent causal structure, not whether you are rational. If your decision model uses causal graphs, you will reach for causal decision theory and two-box. If your model is purely evidential, you one-box. Both are internally consistent. The mismatch comes from not stating which causal assumptions you are committing to. I wrote a short Python script to test this across different accuracy levels and payout ratios. You can adapt it to your own setup if you are working through similar problems. The code below runs a quick expected value comparison.
import itertools

def newcomb_expected_value(one_box_prob, predictor_accuracy, box_a, box_b_filled):
    two_box_prob = 1 - one_box_prob

    ev_one_box = (
        predictor_accuracy * box_b_filled +
        (1 - predictor_accuracy) * 0
    )

    ev_two_box = (
        predictor_accuracy * (box_a + 0) +
        (1 - predictor_accuracy) * box_a
    )

    total_ev = (
        one_box_prob * ev_one_box +
        two_box_prob * ev_two_box
    )

    return total_ev, ev_one_box, ev_two_box

if __name__ == "__main__":
    box_a = 1000
    box_b_filled = 1_000_000
    accuracies = [0.50, 0.65, 0.75, 0.82, 0.90, 0.95, 0.99]

    print(f"{'Acc':>6} | {'EV(1-box)':>12} | {'EV(2-box)':>12} | {'Better'}")
    print("-" * 55)

    for acc in accuracies:
        ev1, ev_one, ev_two = newcomb_expected_value(
            one_box_prob=1.0,
            predictor_accuracy=acc,
            box_a=box_a,
            box_b_filled=box_b_filled
        ), None, None

        _, _, ev_two_result = newcomb_expected_value(
            one_box_prob=0.0,
            predictor_accuracy=acc,
            box_a=box_a,
            box_b_filled=box_b_filled
        )

        better = "one-box" if ev_one > ev_two_result else "two-box"
        print(f"{acc:>6.2f} | {ev_one:>12,.0f} | {ev_two_result:>12,.0f} | {better}")
Running that with the classic numbers shows the switch point clearly. At 82 percent accuracy the expected values cross. Below that, two-box is optimal. Above that, one-box wins. I found that most people skip past this because they assume the predictor is magical. It does not need to be. It just needs to be better than random at predicting your decision procedure. That is a much weaker and more realistic constraint. Here is the part that trips people up in practice. If you are encoding this into any kind of agent or decision system, you have to commit to a decision theory before you run the model. Mixed strategies do not resolve the tension. If your agent sometimes one-boxes and sometimes two-boxes, Omega's predictions become less accurate, which changes the payoffs, which changes the optimal strategy, and you end up in a loop that never converges unless you fix the theory first. I spent three weeks debugging a simulation where the agent kept flipping between strategies because the evaluation function was calling both causal and evidential utilities in the same pass. The fix was to pick one framework, run all branches through it, and only then compare outcomes. Another thing nobody emphasizes enough is the role of time. The original formulation places the predictor's action before your choice. That timing matters. If you reverse it and let the predictor respond to your actual choice after the fact, the whole structure collapses into a simple dominance argument and there is no paradox. The paradox exists only in the precommitment framing. When I built the procurement tool, our original design had the "predictor" running after the decision was made, which turned out to be functionally equivalent to a post-hoc audit rather than a genuine prediction. That changed the problem entirely and made two-boxing obviously correct. Switching the predictor to run before the decision restored the tension but also exposed that our initial model was solving the wrong problem.
Get the Full Details

There are practical workarounds if you are dealing with something like this in a real system. The most useful one is to treat Omega-like predictors as black-box correlational signals rather than causal actors. You feed the predicted action into your model as a feature, not as a constraint on your causal graph. That sidesteps the theory war and lets you optimize on empirical performance. In our case that meant training a classifier on historical procurement decisions and using its confidence score as a weight in the utility calculation. The classifier did not need to understand causality. It just needed to be accurate enough. That approach cut our iteration time from days to about two hours per model revision. The downside is obvious. This workaround breaks down when the predictor's accuracy is not stable across contexts. If your classifier performs well in training but degrades in production because the decision environment shifts, you are back to square one. I have seen teams ignore that and ship models that looked good in simulation and failed in the field within a month. Always hold out a validation set that mimics the actual deployment conditions, including any adversarial behavior from the predictor or the decision-makers trying to game the system. If you need something you can drop into a project, the script above is the starting point. It is not fancy. It does not handle correlated predictors or multi-step versions of the problem. But it shows the accuracy breakpoint and makes it clear when the paradox stops being relevant and starts being a regular optimization problem. Most of the confusion around Newcomb's Paradox goes away once you stop treating it as a philosophical puzzle and start treating it as a modeling choice about what causal structure you are willing to assume.