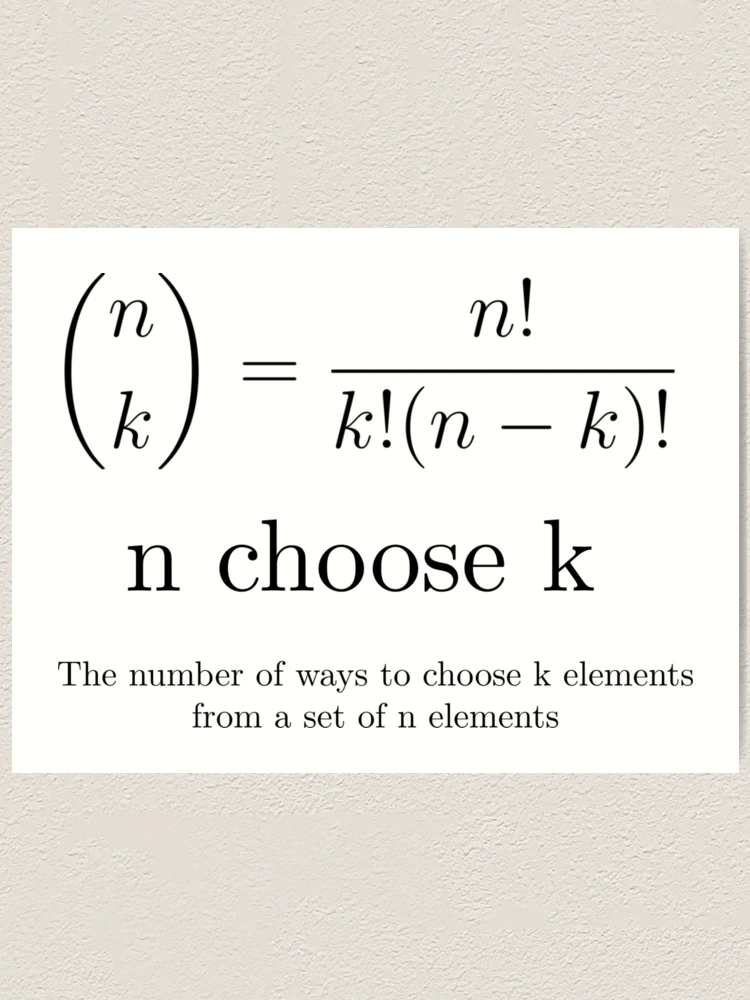
Counting without losing your mind
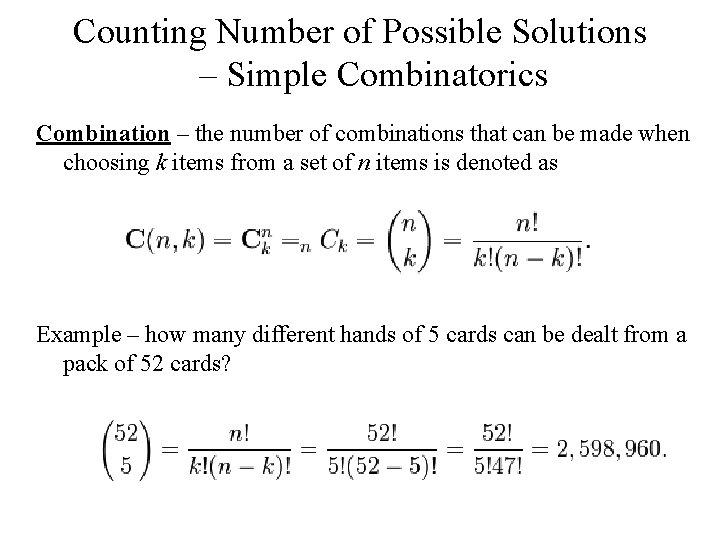
The N Choose K Formula How Combinatorics Unlocks The Secrets Of Counting Possibilities is one of those concepts that sounds like college math fluff until you actually need it and realize everything else is worse. You pick K items from a set of N where order doesn't matter. That's it. The formula is C(N,K) = N! / (K! * (N-K)!). I've seen people overcomplicate this for years. I'm not going to do that here. The factorial notation scares beginners. It shouldn't. Factorials are just multiplication chains. 5! = 5*4*3*2*1. That's all. The formula collapses nicely when you work it out by hand instead of plugging into a calculator blindly. Take C(7,3). You get 7! / (3! * 4!). Expand the top: 7*6*5*4*3*2*1. Expand the bottom: 3*2*1 * 4*3*2*1. Cancel the 4! on both sides and you're left with 7*6*5 / 3*2*1 = 35. Done. No calculator needed. This shortcut matters when N gets large and your calculator throws overflow errors. I ran into this exact problem last year working on a probability model for a logistics system. We needed to calculate combinations for N=52, K=8. Any standard calculator just returned infinity or error. I switched to logarithmic computation: ln(C(N,K)) = ln(N!) - ln(K!) - ln((N-K)!). Using Stirling's approximation for the factorials when numbers got above 100 kept things stable. Worked perfectly. Saves you from needing arbitrary precision libraries for most real-world cases.
When order matters versus when it doesn't
Here's where things get murky for people. The N Choose K formula specifically handles combinations where order is irrelevant. If you're picking a committee of 3 people from 10, it doesn't matter if Alice gets picked first or third. Same committee either way. But if you're arranging a podium finish with gold silver and bronze from the same 10 runners, order absolutely matters and you'd use permutations instead: P(N,K) = N! / (N-K)!. The distinction isn't always obvious in word problems. I once spent two hours debugging a script that gave wrong lottery odds because the problem statement used ambiguous language. "How many ways can 5 numbers be selected from 49?" Could mean either combinations or permutations depending on whether the lottery cares about draw order. Turned out to be combinations. Always clarify with whoever wrote the problem. Assuming costs time.
Edge cases that bite people
C(N,0) = 1. C(N,N) = 1. These feel trivial until you're coding a recursive solution and forget the base cases. Then your program hangs or returns garbage. C(N,1) = N and C(N,N-1) = N. Also trivial on paper. Not so much when you're implementing this inside a dynamic programming routine and your bounds checking is sloppy. One off-by-one error and you're combinatorially exploding. There's also the symmetry property: C(N,K) = C(N,N-K). This isn't just a neat fact. It's a practical optimization. If you need C(20,15), compute C(20,5) instead. Smaller numbers, less chance of overflow, same result. I use this all the time in competitive programming settings where intermediate values can hit 64-bit integer limits even though the final answer fits comfortably.
Get the Full Details

Real applications that aren't textbook examples
Probability theory uses combinations constantly. Hypergeometric distributions, binomial distributions, occupancy problems. If you're dealing with sampling without replacement from a finite population, you're using combinations whether you know it or not. I calculate acceptance probabilities for quality control checks this way. Pick 5 widgets from a batch of 100, 12 are defective. Probability that exactly 2 of your sample are bad? C(12,2) * C(88,3) / C(100,5). That's roughly 0.238. Standard stuff. Computer science loves combinations too. Subset generation, hash collision analysis, testing frameworks that need to cover all pairs of inputs. Pairwise testing in software QA uses combinatorial covering arrays to reduce test cases from exponential to manageable. You can't test all possible input combinations for anything nontrivial. But you can often guarantee every pair of parameters gets exercised with a fraction of the full combinatorial space. That's the practical power here.
What the formula can't do for you
N Choose K only works when you're selecting distinct items from a single pool without replacement. If you have repeated items, or if you can pick the same item multiple times, the formula breaks. You need multiset coefficients for that: C(N+K-1, K). And if order matters with repetition allowed, it's N^K entirely different thing. Don't try to force the basic formula into these scenarios. I've seen it happen. People get confident and apply the wrong tool because the numbers look familiar. Another hard limit: computational cost. Calculating exact values for large N with moderate K gets expensive fast. C(1000,500) is an astronomically large number. You can store it with big integer arithmetic but it takes meaningful memory and time. For probability calculations where you only need relative likelihoods, working with logarithms or staying in floating point with careful normalization is usually better than computing the raw combination value. This matters in Bayesian statistics where you're juggling dozens of these terms simultaneously. There's also no closed form for sums of combinations in most useful configurations. Things like sum of C(n,k) for k from 0 to n equal 2^n is clean. But weighted sums or sums with constraints on k usually need recursive approaches or generating functions. Don't expect the formula to hand you answers to harder problems without additional machinery.
Quick reference for implementation
Written as code, a safe iterative implementation avoids large intermediate factorials entirely: result = 1
for i in range(k):
result = result * (n - i) // (i + 1) This keeps values small at each step. Integer division works because each intermediate result is guaranteed to be a whole number. I wrote this in Python for a genetics project where we counted genotype combinations. Runs fast, no overflow issues even for N in the hundreds. If you're in C or Java, use long integers and watch for the edge case where K equals 0 or N, since the loop won't execute and you need to return 1 explicitly.

The Pascal triangle relationship C(N,K) = C(N-1,K-1) + C(N-1,K) gives you a DP approach that's O(N*K) time and space. Fine for small tables. Not great if you just need one value and N is large. Memoization helps if you need many queries but the pattern of K values is irregular.
Common mistakes to avoid
Confusing 0.5^N with combinatorial probabilities is probably the most frequent error I see. Flipping a coin 20 times and getting exactly 10 heads is C(20,10) * 0.5^20, which is about 0.176. Not 0.5^20. The combination coefficient accounts for all the different orders that produce the same count. Skip it and your probability is off by a factor of 184,756. That's not a typo. Another one: treating combinations as ordered selections in conditional probability. If you pick cards from a deck one at a time, the probability of getting exactly 2 aces in 5 draws doesn't change if you imagine the draws happening simultaneously. The combination framework handles this correctly because it counts unordered subsets. But people sometimes second-guess themselves and overcomplicate with sequential probability trees when combinations would be faster and equally correct. The N Choose K formula stays relevant because counting problems don't disappear. They just get bigger and more constrained. Learning to apply it correctly and knowing when it stops being the right tool saves more time than memorizing extensions you'll rarely use.