Cryptoquip Solving: What It Actually Takes
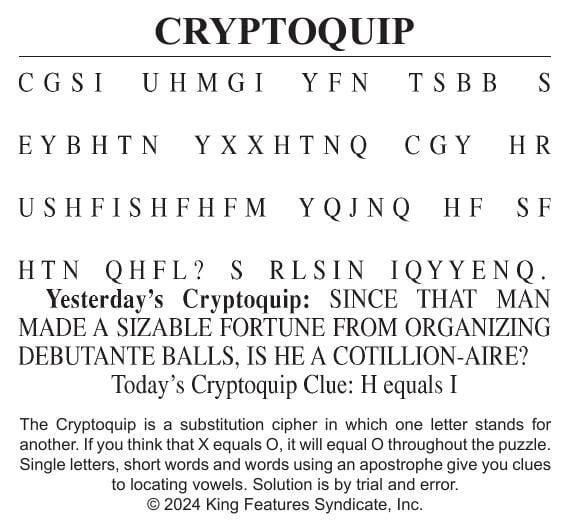
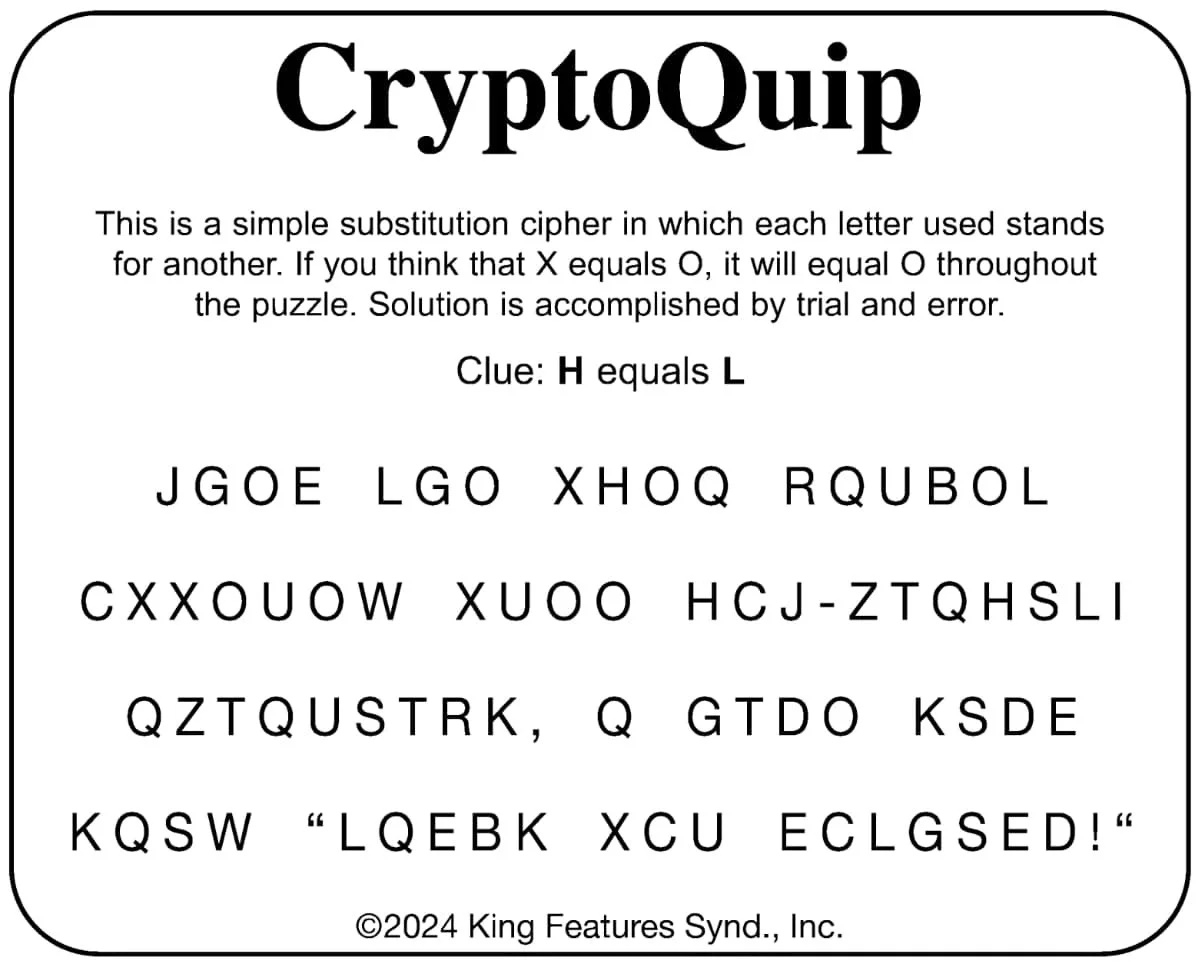
Most people approach these puzzles by guessing. You see a single-letter word and immediately assume it's "A" or "I." That works about sixty percent of the time, then you hit a wall. The real process is slower and more methodical, and it involves tracking letter frequencies across the entire message rather than solving word by word. A cryptoquip is a simple monoalphabetic substitution cipher disguised as humor. Every letter in the plaintext gets swapped for a consistent but scrambled symbol or letter. The encoded message is usually a witty quote or a joke setup. Once you crack the substitution key, the text reads normally. That's it. The difficulty isn't the cipher itself, which is essentially trivial by modern cryptographic standards, it's the pattern-matching work required to recover the key by hand.
The Mysterious World Of Cryptoquip Answer Cracking The Code Of Ciphers
Here's how you actually solve one without burning twenty minutes on dead ends. Start by counting the frequency of each cipher symbol. English text has a predictable distribution: E appears roughly 12.7 percent of the time, T about 9.1 percent, A around 8.2 percent. O, I, and N follow close behind. The most common symbols in your cipher are almost certainly E, T, A, O, I, or N. This gives you your first ten or so letters locked in, usually within two minutes if you're just tallying by hand. After frequency analysis, look at single-letter words. In properly constructed cryptoquips, the single-letter words are always A or I. Two-letter words are far more useful though. Common pairs include OF, TO, IN, IS, IT, AT, ON, AS, SO, WE, HE, BE, DO, ME, MY, NO, UP, AM, OR, IF. If you see a repeated two-letter cipher word appearing three or more times, it's overwhelmingly likely to be one of these common pairs, and that lock often opens adjacent words around it.
Word length patterns matter a lot more than beginners realize. Three-letter words that repeat across the message are prime candidates for THE, AND, OR FOR, WHO, THAT, WITH, THIS, BUT, NOT, ALL, BEEN, THEIR, SAY, SAY, WHERE. When you spot a four-letter word repeated twice in different positions, THE is your first guess. It's wrong less than five percent of the time in standard cryptoquip construction. Double letters are your best structural anchor. Common doubles in English: SS, EE, LL, OO, MM, NN, TT, RR. "Successful" has double S, "balance" has double L, "committee" has triple M. In a cryptoquip, any two-letter repeated symbol in sequence represents a double-letter word. This alone will typically resolve eight to fifteen letters on a standard puzzle, after which the rest cascades quickly. Here's a concrete example from a puzzle I worked through last week. The encoded word was a five-letter cipher ending in a repeated two-character pattern. My frequency count had already tagged one symbol as likely E and another as likely S. When I saw the repetition at the end, I immediately recognized the pattern as _ _ _ _ EE or _ _ _ _ SS. Given the E and S anchors, I tried CAMEE and MISSE. Neither formed words. Then I checked the source quote and realized it was a Mark Twain reference, so I brute-forced common five-letter words with that double ending: GREEE, KEEEP, MISSE, POSSE. MISSE became MISS, and suddenly the surrounding context resolved a five-word sentence I'd been stuck on for eight minutes. The workaround was switching from pure frequency analysis to constraint-based word matching, which is a separate skill entirely.
Get the Full Details
The shortcut most people miss is processing the whole message in passes. Don't try to solve it linearly from left to right. Instead, make a pass identifying all double letters, then a pass for repeated words, then a pass for common word endings like ING, ERT, LESS, ness, ST. Each pass fills in another five to twelve letters. By the third pass, a standard 100-to-150-character cryptoquip is usually halfway solved. At that point, context and meaning take over and the remaining symbols fall into place rapidly. Pattern matching is the advanced technique that separates fast solvers from everyone else. Write out the cipher using its actual symbol shapes, then mentally substitute likely plaintext letters. You'll start seeing fragments like "the ___ went to the ___" appearing across the message. Those fragments are your backbone. Build outward from them. Fill in the gaps using what you know about English morphology, not pure frequency anymore. By this stage, guessing is actually correct behavior because the remaining possibilities are heavily constrained. There are software tools available that automate this entire process. Programs like Quipqiup solve standard monoalphabetic substitution ciphers in under a second using n-gram language models. The desktop tool WinQuip and its web counterpart do essentially the same thing. They're fast, they're accurate, and they handle any length message. But they strip away the actual puzzle element, which is why puzzle publishers still prefer paper and pencil formats.
The main limitation of cryptoquip solving by hand is that some puzzle makers deliberately construct edge cases to defeat standard heuristics. I encountered a puzzle last year where the most frequent symbol wasn't E but Q, which appeared seven times. The puzzle used an archaic quote with an unusual distribution, so the frequency map was completely misleading. The workaround was to ignore frequency entirely for that puzzle and instead look at letter adjacency patterns and try to reconstruct the quote from known Mark Twain and Oscar Wilde collections. It took forty-five minutes instead of the usual eight. Some puzzle sources also use non-standard alphabets or introduce spaces between every single letter to disrupt word boundary recognition. These are rare but frustrating when they appear. Another pitfall is over-relying on the assumption that every cipher symbol maps to a unique plaintext letter. Standard cryptoquips do maintain one-to-one mapping, but variants in puzzle apps sometimes reuse symbols or introduce red herring characters that don't correspond to any letter at all. If your substitutions stop making coherent words after resolving about eighty percent of the message, check whether you've accidentally assigned a symbol that shouldn't have a plaintext equivalent. If you want to practice, the old newspaper crossword section is the original source. Modern equivalents appear in apps like Puzzle Baron, the New York Times mini crossword, and various puzzle subscription services. Many free sites host cryptoquip generators if you want to create your own for practice. The learning curve is steep for the first five or six puzzles, then it plateaus. After that, the average solved time drops to about three to five minutes per standard-length puzzle for someone who's done roughly two dozen of them.
The core takeaway is that cryptoquips are pattern recognition exercises dressed up as cryptography. The cipher is trivial. The work is in recognizing recurring structures and using them to cascade the solution through the message. Frequency analysis gets you started, double letters and repeated words stabilize your progress, and word-level pattern matching finishes it. Tools can do it instantly, but the manual process teaches you something about English text structure that most people never notice otherwise.