Where DNA Lives Inside Your Cells
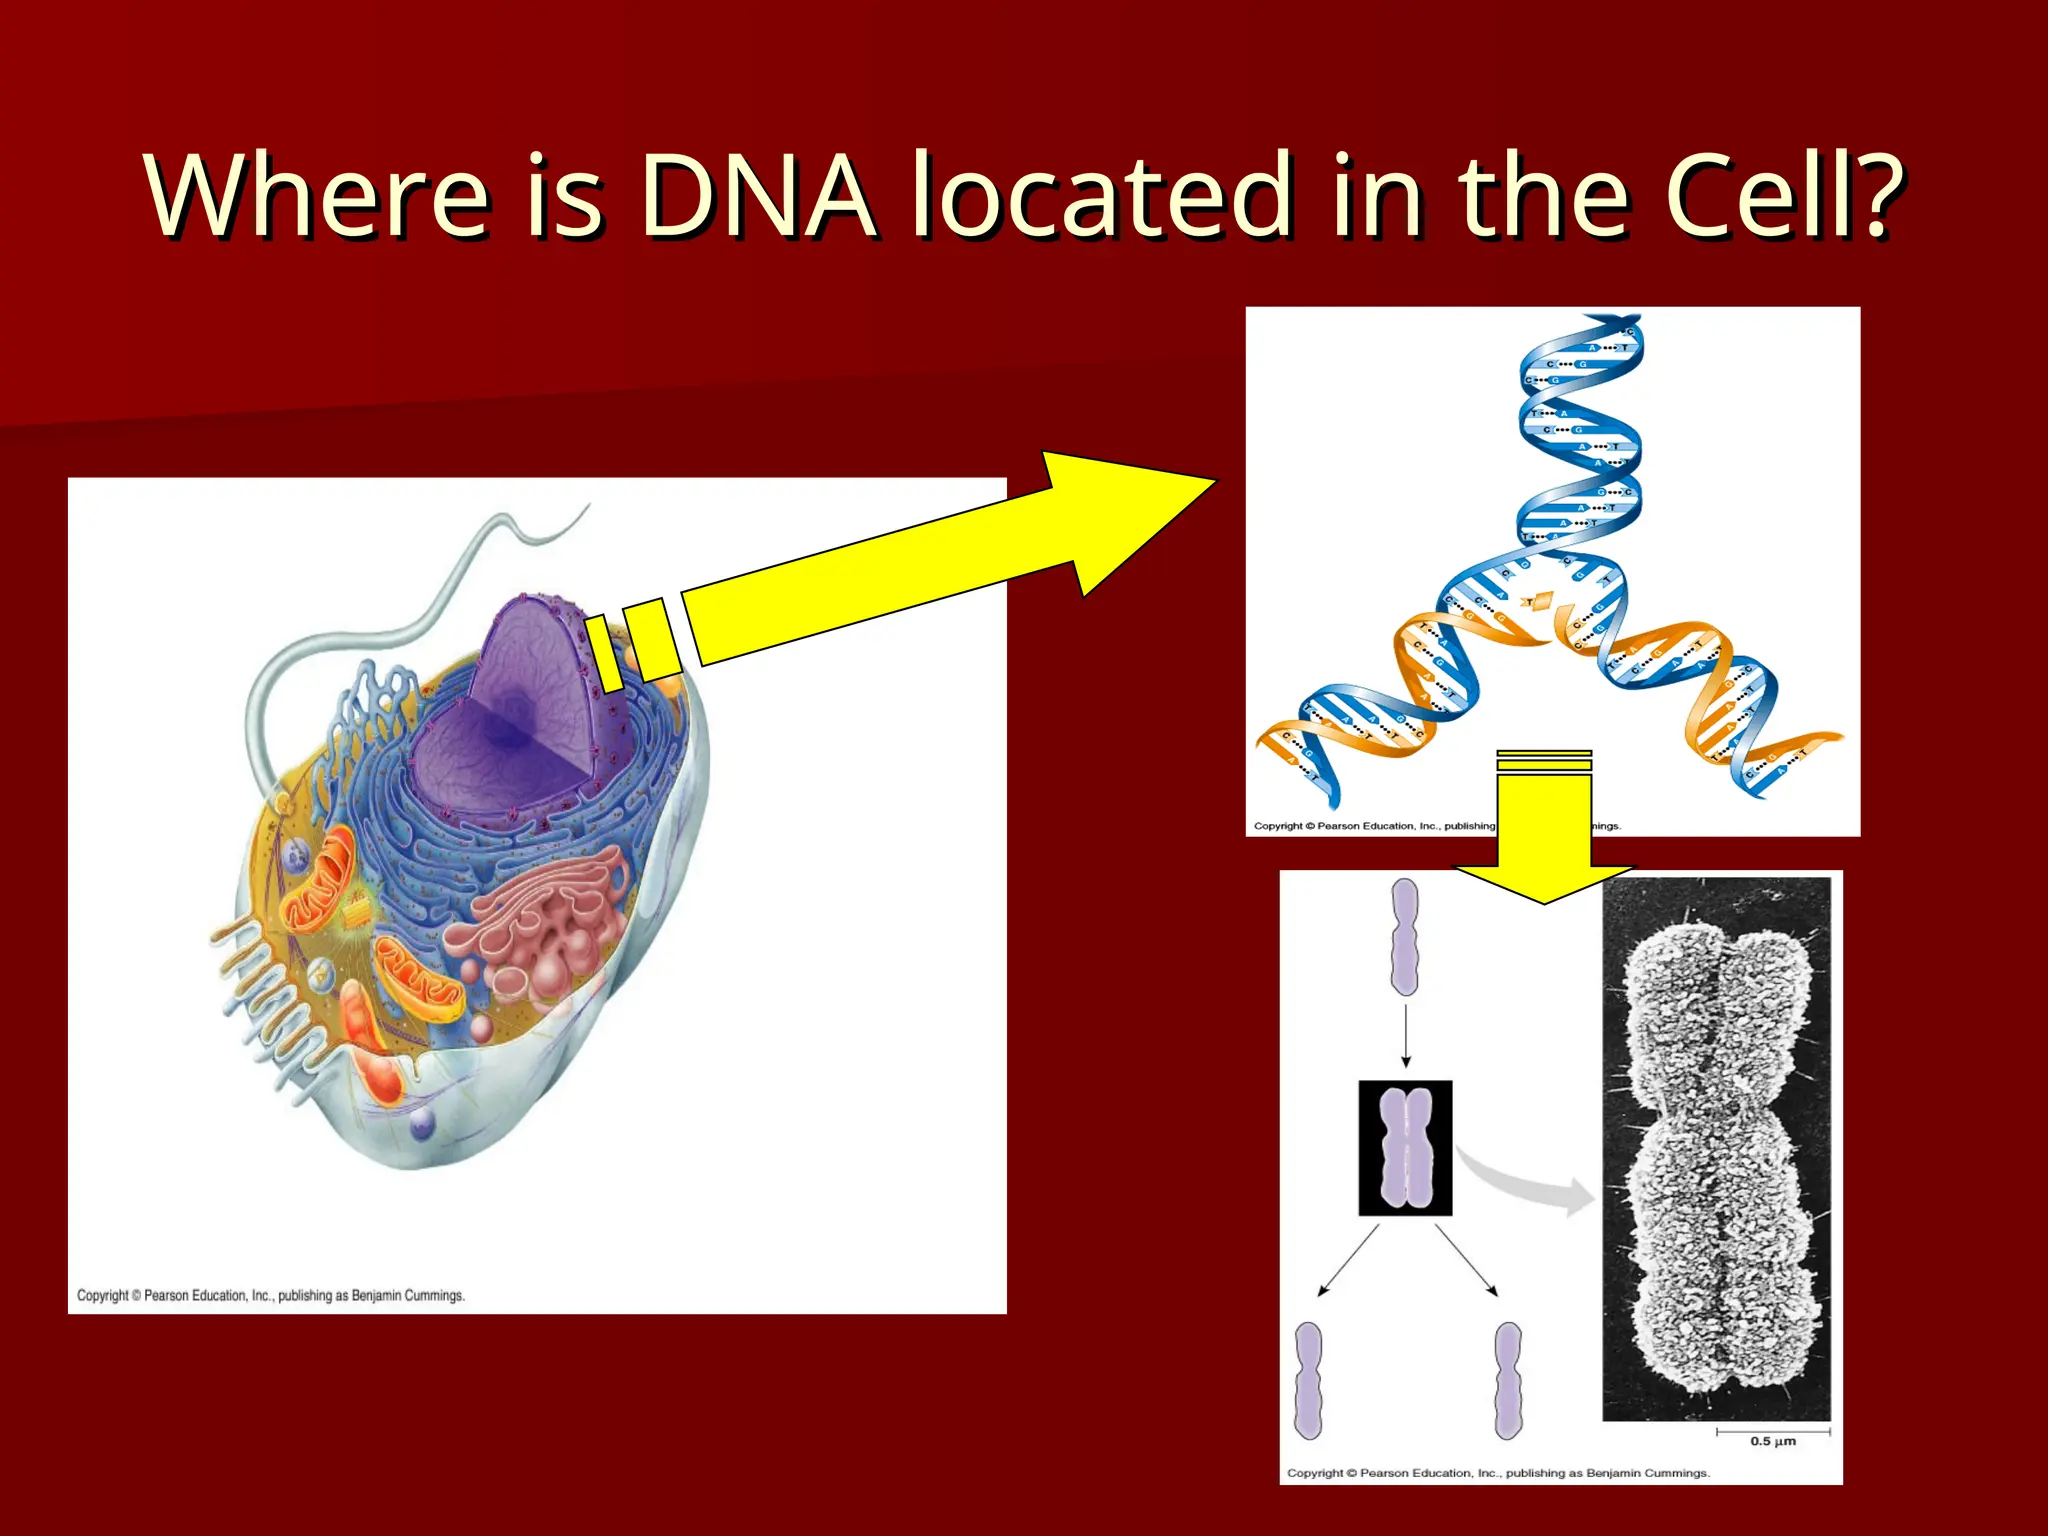
DNA is mostly tucked away in the nucleus, wrapped around proteins called histones to fit inside that tiny space. That's the textbook answer. The reality is messier. A small amount of DNA also lives in your mitochondria, the energy-producing organelles, and that mitochondrial DNA comes entirely from your mother. I spent a few years working with cell fractionation protocols, and one thing stuck with me: getting clean nuclear DNA without mitochondrial contamination is harder than people expect. If your lysate isn't handled right, the mitochondria rupture and their circular genomes pile into your prep, throwing off downstream results like PCR or sequencing. The nucleus holds the bulk of your genomic DNA, organized into 46 chromosomes in humans. That's roughly three billion base pairs per set. Each chromosome is a single, enormously long molecule of double-stranded DNA wound around nucleosomes. Without that packaging, the DNA from one cell would stretch about two meters. It wouldn't fit in a nucleus that's only six micrometers across.Outside the nucleus, things change. Mitochondrial DNA is circular, about 16,500 base pairs, and exists in multiple copies per mitochondrion. A single cell can contain hundreds of mitochondria, meaning thousands of copies of that small genome floating around. That redundancy matters for certain analyses. If you're doing whole-genome sequencing and your library prep pulls in mitochondrial reads, they can consume a significant portion of your sequencing depth. I once ran a project where mitochondrial contamination ate up nearly forty percent of the data because the nuclei weren't properly pelleted during isolation. Switching to a sucrose gradient centrifugation step instead of simple centrifugation solved it. Understanding how DNA works starts with its structure. It's a double helix made of four nucleotide bases: adenine, thymine, guanine, and cytosine. Adenine pairs with thymine. Guanine pairs with cytosine. Those pairings hold the two strands together. The sequence of those bases along the strand is what encodes information, and the mechanism for reading and copying that information is surprisingly straightforward once you strip away the marketing language. DNA replication happens during the S phase of the cell cycle. The enzyme helicase unwinds the double helix at the origin of replication, creating a replication fork. Single-strand binding proteins keep the strands separated. DNA polymerase then adds complementary nucleotides to each template strand. Because polymerase only works in the five-prime to three-prime direction, one strand is synthesized continuously as the leading strand, and the other in short fragments called Okazaki fragments on the lagging strand. Primase lays down RNA primers to get things started, and ligase seals the nicks between fragments.
The trick most people miss is that replication isn't perfectly accurate. DNA polymerase has a proofreading function that catches most mismatches, but the error rate still sits around one mistake per billion bases copied. That sounds good until you multiply it across three billion bases and trillions of cells. Most errors get caught by mismatch repair systems after replication, but some slip through. That's how mutations accumulate over time, and it's also why cancer happens when the wrong genes get damaged in the right combination. Gene expression is the next step. DNA gets transcribed into RNA. RNA polymerase binds to a promoter region upstream of a gene, unwinds a short stretch of DNA, and builds a complementary RNA strand using uracil instead of thymine. That RNA then goes through processing in eukaryotes. Introns get spliced out. A five-prime cap and a poly-A tail get added. The mature mRNA exits the nucleus and gets translated by ribosomes in the cytoplasm. Translation reads the mRNA in codons, three-base units that each specify an amino acid. Transfer RNAs bring the correct amino acids to the ribosome based on codon-anticodon pairing. The ribosome forms peptide bonds between amino acids, building a polypeptide chain that folds into a functional protein. This is where the central dogma comes from: DNA makes RNA makes protein. It's not always that clean. Reverse transcription happens in retroviruses. Non-coding RNAs like microRNAs and long non-coding RNAs regulate gene expression without becoming proteins. The dogma is a useful framework, not an absolute rule.
Epigenetics adds another layer that beginner textbooks often gloss over. DNA methylation and histone modification can turn genes on or off without changing the underlying sequence. A skin cell and a neuron have the same DNA. They look different because different genes are expressed, and epigenetic marks control that expression. These marks can be influenced by environment, diet, stress, and age. They can even be passed to daughter cells during division, and in rare cases, inherited across generations. One counter-intuitive thing about DNA location is that it's not always static. During cell division, the nuclear envelope breaks down and chromosomes condense into their classic X-shape. After division, the envelope reforms around each set of chromosomes. Some genes move to the nuclear periphery or cluster in transcription factories. Chromosome conformation capture techniques like Hi-C have shown that the genome is organized into topologically associating domains, and the 3D folding pattern matters for which genes get accessed by transcription machinery. The linear sequence isn't the whole story. When people ask about the mysterious realm of DNA, they're usually looking for something more dramatic than what actually exists. There's no mystery in the mechanics. The chemistry is well understood. Base pairing follows predictable rules. Enzymes do their jobs with reasonable fidelity. The complexity comes from scale and regulation, not from unknown processes. What makes DNA genuinely difficult to work with isn't any lack of understanding. It's that biological samples are messy, degraded, and variable. DNA degrades quickly outside controlled conditions. Shearing forces during pipetting or vortexing can fragment long molecules. Contaminants like phenol, ethanol residue, or genomic DNA in RNA preps can ruin experiments.
Get the Full Details

I once spent three weeks troubleshooting a CRISPR experiment where the editing efficiency kept failing. The guide RNA sequences were correct. The Cas9 was active. The cells were healthy. It turned out the plasmid prep had residual endotoxin from the bacterial culture, and that was reducing cell viability just enough to knock down transfection efficiency. Ultra-pure plasmid prep kits solved it. The problem wasn't in the science. It was in the preparation. Sequencing technology has made DNA much more accessible. Sanger sequencing reads individual genes accurately but is slow and expensive for large projects. Next-generation sequencing platforms like Illumina can read billions of short fragments in parallel. Third-generation long-read technologies from companies like Oxford Nanopore and Pacific Biosciences read much longer stretches, which helps with repetitive regions and structural variants that short reads struggle to resolve. Each technology has tradeoffs. Short reads are cheaper and more accurate per base. Long reads cover more ground but have higher error rates, though that's improving fast. The practical takeaway is that DNA is everywhere in your cells, concentrated in the nucleus but also present in mitochondria, and its behavior depends on context. Location matters. Packaging matters. Epigenetic state matters. The sequence matters most, but the sequence alone doesn't tell you what a cell is doing at any given moment. Understanding DNA means understanding all of those layers together, not just memorizing the structure of the double helix.