Understanding How Genes Actually Talk To Each Other
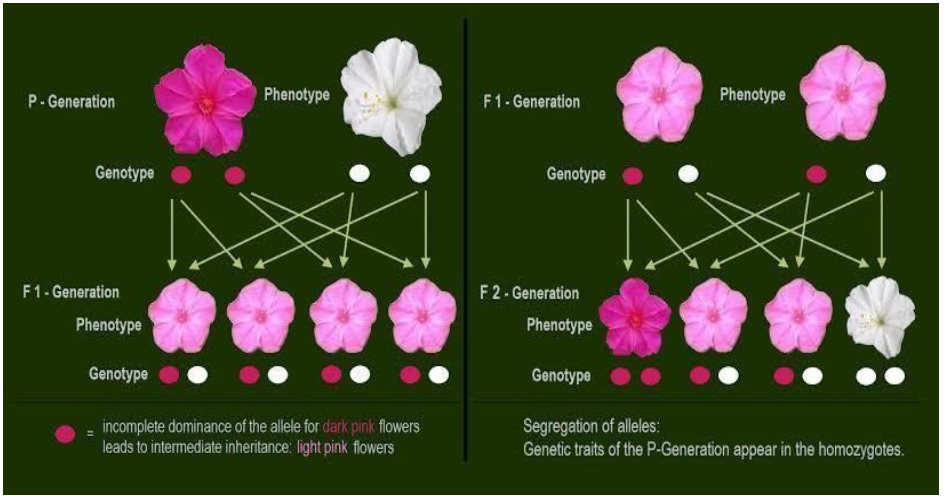
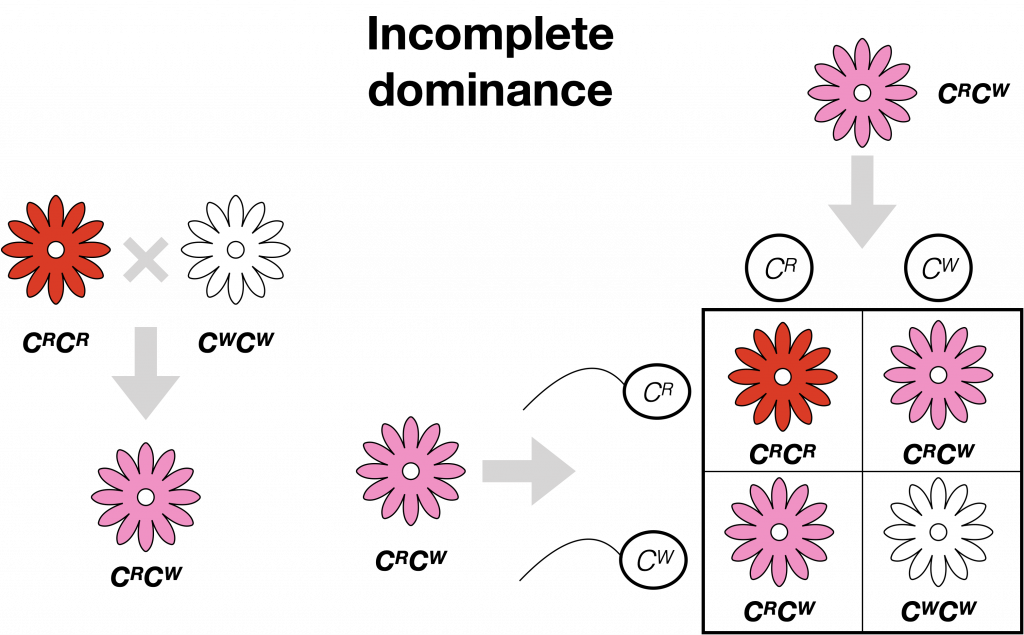
Mendel's textbook examples make inheritance look clean. You get dominant, you get recessive, the Punnett square resolves into 3:1 ratios and everyone goes home happy. That simplicity evaporates the moment you look at anything other than pea plant height or seed color. Real organisms don't read from that chapter. Incomplete dominance is one of the first cracks in the facade. It's not some exotic edge case you only find in specialist journals. It shows up constantly if you're actually tracking phenotypes across generations instead of just memorizing genotype notation. The short version: neither allele fully dominates the other, so the heterozygote lands somewhere in between. Classic example is snapdragons where red crossed with white gives pink, not red. But the real world gets messier than that diagram on slide three of your intro biology lecture.
The Mysteries Of Incomplete Dominance Unraveling The Complexity Of Genes And Traits
Here's what nobody tells you when they first introduce the concept. Incomplete dominance isn't really about dominance at all. It's about dosage. Two copies of the functional allele produce twice the protein product of one copy, and if that protein product is rate-limiting for pigment synthesis, you get intermediate coloration. The phenotype is literally quantitative. Calling it "incomplete dominance" frames it as a deviation from a norm that never actually existed in the first place. Most undergraduate courses present complete dominance as the default and everything else as an exception. That's backwards. Quantitative gene action is the baseline. Complete dominance is the rare mutation where having one extra copy of a gene product makes zero difference to the phenotype. I ran into this head-on about four years ago working on a breeding project with certain ornamental plant varieties. I was tracking flower color across three generations and the F2 ratios looked nothing like what incomplete dominance theory predicted. Instead of clean 1:2:1 segregation, I was getting a continuous spectrum of hues with what looked like environmental noise inflating the variance. The problem wasn't the genetics. It was that I was treating a single-gene trait as if it was isolated, when in reality the pigment pathway had at least two modifier loci acting epistatically, plus temperature sensitivity in the enzymatic step that converts the precursor to the colored compound. The workaround was straightforward once I stopped trying to force the data into Mendelian boxes. I ran an ANOVA on the phenotypic variance with temperature as a fixed effect and found that the heritability estimate dropped from 0.85 at controlled temperatures to 0.42 under field conditions. The genetic architecture was stable. The environment was just masking it. I switched to growing conditions that minimized thermal variation and the segregation ratios resolved properly. Took me six weeks and a revised experimental design, but the data finally behaved.
There are a few practical complications that trip people up regularly. One is assuming incomplete dominance means equal blending. It doesn't. The heterozygous phenotype can sit closer to one homozygote than the other depending on enzyme kinetics, protein stability, and whether the pathway has threshold effects. A 60-40 split isn't unusual and it's still incomplete dominance. Another issue is distinguishing incomplete dominance from codominance. They're not the same thing and students routinely conflate them. In codominance, both alleles are expressed simultaneously and visibly, like blood type AB where both A and B antigens appear on red blood cells. In incomplete dominance, you get a blended or intermediate phenotype because neither allele produces enough product to reach the full threshold of the dominant phenotype. Same category of inheritance error, different molecular mechanism. Polygenic traits complicate this further. Most commercially interesting characteristics—flower color intensity, fruit size, yield—involve multiple genes with incomplete dominance at several loci. The phenotypic distribution becomes continuous, which is why quantitative trait locus mapping exists as a whole field. If you're doing selective breeding or genetic counseling and you see continuous variation, stop thinking about single-gene incomplete dominance and start thinking about additive polygenic effects. The math is different. The predictions are different. Using Mendelian notation for a polygenic trait will give you answers that look precise and are completely wrong. Another thing that causes problems in practice is penetrance. Even when you've correctly identified incomplete dominance at a locus, reduced penetrance means some individuals with the expected genotype don't show the predicted phenotype at all. This is especially common with traits influenced by developmental noise or stochastic gene expression. You'll see healthy-looking individuals in your F2 generation that genetically should express the intermediate phenotype but don't, and you'll waste time looking for hidden modifiers when the real issue is just biological variability. Running larger sample sizes usually exposes this, but you need to know what you're looking for first.
Get the Full Details

For anyone actually working with these systems rather than just studying them for an exam, the useful takeaway is to treat incomplete dominance as a starting hypothesis, not a conclusion. Verify it with backcrosses and testcrosses. Check for environmental interactions. Run the numbers through a chi-square test before you commit to any inheritance model. The ratios that look close enough on paper often fall apart under statistical scrutiny, and catching that early saves you from building an entire project on a misidentified mechanism. There's also the question of molecular evidence. Phenotypic ratios alone can't distinguish incomplete dominance from other modes like partial dominance or even certain types of epistasis. Modern practice involves genotyping the individuals and correlating genotype with phenotype directly. If you have access to PCR-based markers or sequencing, genotype your samples and look at the correlation. It takes more effort upfront but eliminates entire classes of ambiguity that pedigree analysis alone can't resolve. I switched to this approach after burning two semesters on projects where the phenotypic data was misleading due to environmental confounding. One more practical note about documentation. When you're reporting incomplete dominance, include the actual phenotypic measurements, not just categories. "Pink" is useless without a reference scale. Report color values, enzyme activity levels, or whatever quantitative measure you're using. Future researchers need to know what intermediate actually means in your system, and self-consistency across experiments depends on it. Vague categorical descriptions are why so many textbook examples don't replicate when you try them in real lab conditions.