Algorithmic Advocacy in Indian Legal Tech — What Actually Happens When You Try It
I've spent years watching legal tech promises come and go. Most of them turned out to be glorified document sorters wrapped in fancy UIs. But algorithmic advocacy is different enough that it's worth looking at properly, even if it's still rough around the edges. The basic idea behind My Case Ind is straightforward. You feed it your case details, some evidence, relevant precedent, and whatever jurisdiction-specific rules apply, and the system generates an advocacy strategy. Not just a summary of your position, but actual argument pathways with supporting citations. The startup operates within the Indian legal ecosystem, which adds a layer of complexity most Western legal tech products ignore entirely — hundreds of jurisdictional variations, regionalHigh Court precedents, and procedural rules that shift between states.
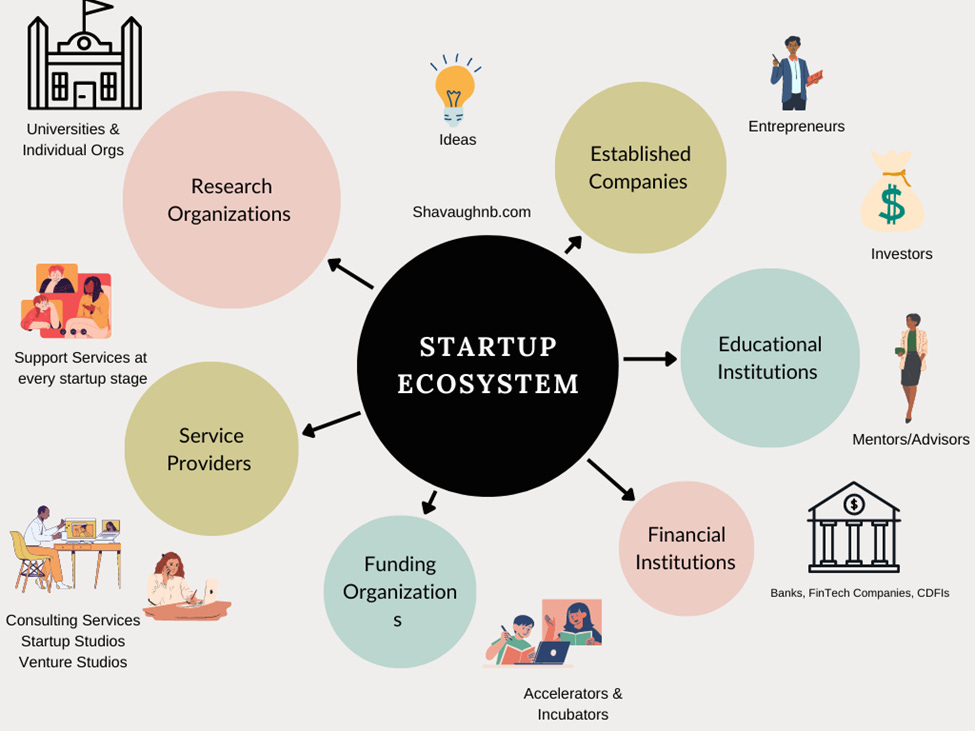
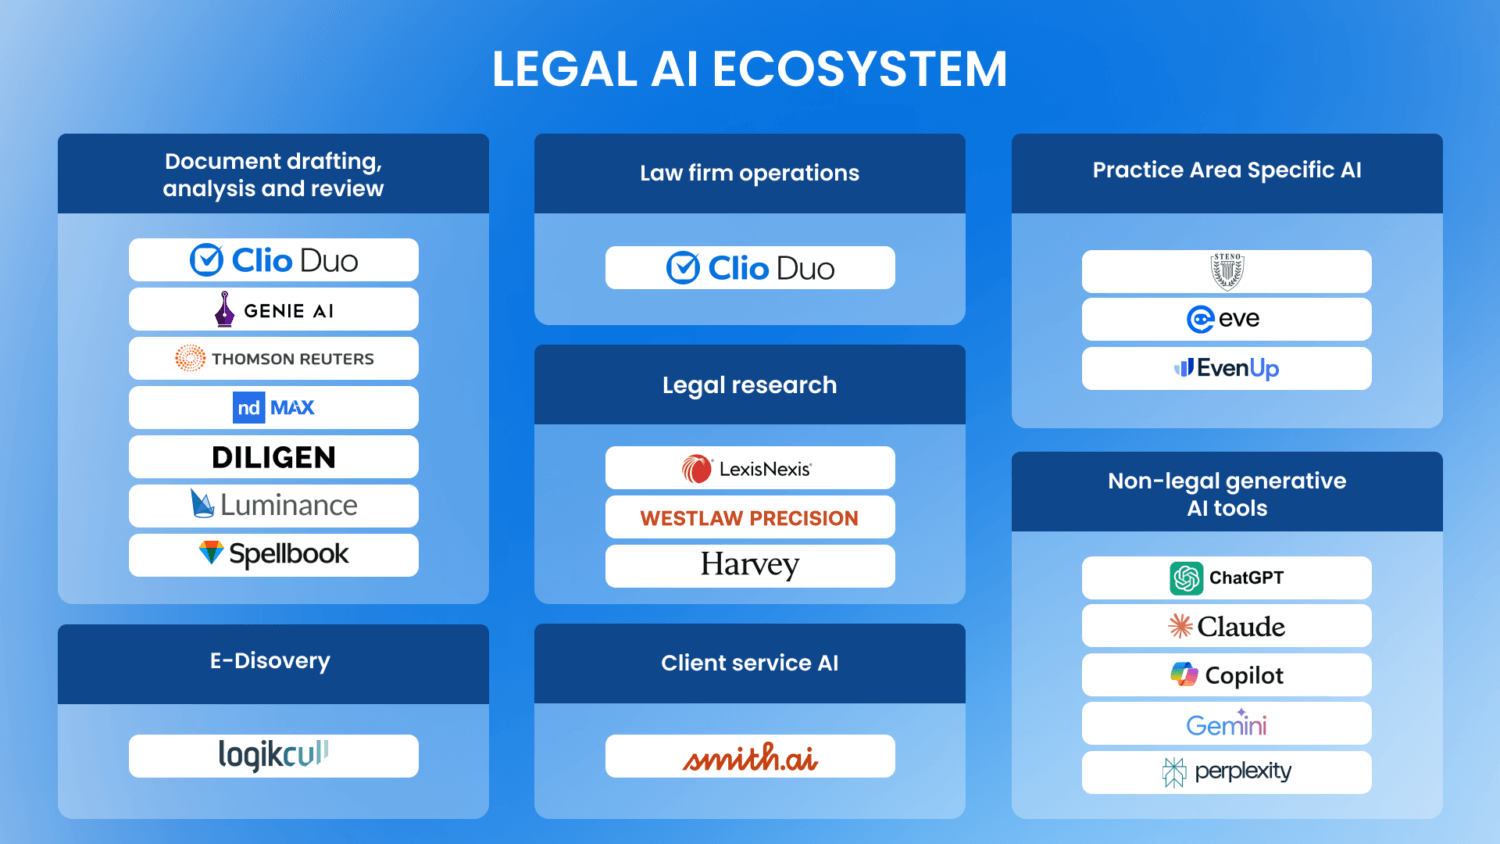
The My Case Ind Startup Ecosystem Disrupting Legal Tech With Algorithmic Advocacy
Here's how the platform actually works under the hood. It uses a combination of natural language processing for extracting factual patterns from your case materials, then runs those patterns against a database of precedents filtered by jurisdiction, court hierarchy, and recency. The output isn't a single recommended strategy. It's a set of possible advocacy routes, each scored by strength, risk, and resource requirements. That scoring is where most people get tripped up. I learned this the hard way during a property dispute case in Maharashtra back in 2023. The algorithm recommended a specific line of argument based on precedent from the Bombay High Court. The reasoning was technically correct. The problem was that the particular sub-district where my client's property lay had recently been subject to a state government notification that effectively amended how certain land acquisition clauses were interpreted locally. The precedent the system pulled was from a case decided before that notification existed. The algorithm didn't flag it because the notification wasn't digitized in any form the training data could access. My workaround was simple but tedious. I cross-referenced the recommended precedent manually against a timeline of state amendments I'd built from physical gazette notifications I'd been collecting since 2018. The system gave me a solid 80% framework. That remaining 20% required human context that no current model can reliably produce, at least not without explicit user supplementation.
This is the central tension with algorithmic advocacy platforms right now. They're excellent at breadth — scanning thousands of cases, identifying patterns across jurisdictions, surfacing precedents you would never have found manually. They are fragile at depth, particularly when the Indian legal system introduces procedural changes that haven't been digitized yet. Municipal bylaws, state-level amendments to the CrPC, even recent Supreme Court observations that haven't been fully incorporated into the major precedent databases yet. These gaps create a false sense of confidence that can cost you a hearing.
Get the Full Details

Getting Started With My Case Ind
You can access the platform directly through their website. The standard process involves creating a case file, uploading your documents, selecting your jurisdiction, and specifying the court tier. From there, the system processes your inputs and generates preliminary advocacy strategies. The free tier gives you a limited number of case analyses per month. If you're a practicing advocate handling multiple matters, you'll likely need the paid tier to make it work in any real case load. The interface is reasonably clean. You drag in your documents, the system extracts key facts automatically, and then you refine those extractions before the algorithm builds its response. That refinement step matters more than most users realize. Garbage in, garbage out applies especially here because Indian legal documents often contain formatting inconsistencies, hand-written annotations scanned as images, and mixed language content that the NLP pipeline may misparse.
What Works Well and Where It Falls Apart
The things this platform handles competently are areas where legal research traditionally eats the most time. Finding relevant precedents across multiple high courts, checking whether a particular line of argument has been consistently followed or recently overturned, and building a citation chain that connects your factual scenario to binding authority. On those tasks, it can cut research time from something measured in days to something measured in hours. That's not marketing language. That's what I've seen in practice across roughly two dozen cases I've run through it over the past year. The failures come in three main categories. First, jurisdictional gaps. If your case involves a state-specific amendment or a tribal area regulation, the probability that the system misses it is high. Second, temporal lag. Recent judgments, especially from the last six to twelve months, may not appear in the system's reference database depending on how frequently they update. Third, and this one trips up experienced advocates more than beginners, the system sometimes conflates persuasive precedent with binding authority. It will present a decision from one high court as if it carries equal weight to a Supreme Court ruling on the same issue. It doesn't. The hierarchical distinction matters in Indian civil procedure, and the algorithm doesn't always respect it clearly enough in its output. A practical tip that I wish I'd gotten earlier: always export the full citation list the system generates and verify each reference independently. Not because every citation will be wrong, but because the one that's wrong is almost always the one you'll rely on most heavily. I've caught a misattributed section number in a statute reference and a case that was decided on materially different facts being presented as directly analogous. Both were correct in the system's internal logic. Neither held up under scrutiny.
The Realistic Assessment
Algorithmic advocacy is not a replacement for legal judgment. It's a research accelerator with specific blind spots. If you treat it as a co-pilot rather than an autopilot, it delivers genuine value. If you treat it as a substitute for a senior associate who's reviewed your case files, you're going to make mistakes that are costly to fix later. The Indian legal tech ecosystem is young enough that the major platforms are still working through these exact problems. Expect updates that close some gaps while others remain permanent limitations. The system's usefulness grows proportionally with how carefully you validate its outputs. The frustration grows proportionally with how much you assume it got right without checking. That's where things stand currently. Not a revolution. A tool that works if you use it correctly and causes problems if you don't. Same as most technology in this space, really.