How Mission Systems Actually Evolved
Mission systems are everywhere once you notice them. The word gets thrown around in corporate settings like it means something special, but at its core a mission system is just a way to route work from where it originates to whoever actually needs to handle it. That has been true since someone first tied a note to a dove's leg and hoped it made it to the right house. The historical arc is surprisingly practical. Ancient empires built relay networks — Persian royal roads with stationed messengers, Roman post systems, Mongol Yam stations — all solving the same problem: get information from point A to point B before it becomes useless. Speed was the whole point. A military order arriving after the battle was over had zero value, which is the same constraint modern teams face when an AI agent hands off a task to another system three hours late.
The Mission System From Ancient Messengers To AI Orchestrationa Historical Evolution
What connects a Persian courier to a Kubernetes pod scheduling an inference job is the concept of handoff reliability. Every era developed its own mechanism for reducing the chance that a task drops between senders and receivers. The Persians used chained stations where a new rider took the message at each stop, reducing fatigue and increasing speed. Modern task queues like Celery or AWS SQS work on an essentially identical principle — break the journey into manageable hops so no single component carries the full load and no single point of failure kills the whole message. The Industrial Revolution changed the routing layer. Telegraph networks introduced store-and-forward messaging, which meant a telegram didn't need both endpoints online simultaneously. That was the first major shift from synchronous to asynchronous mission delivery. Switchboards, pneumatic tube systems in banks, even paper-based workflow routing in insurance companies — all of these were mission systems before anyone called them that. They tracked a discrete unit of work through a pipeline until it reached resolution. Then computing arrived and everything got more complicated in exactly the ways you'd expect. Early workflow engines like IBM's workflow patterns documentation described formalisms for conditional branches, parallel splits, and exception handling. The field of business process management formalized what factories had been doing implicitly for decades. BPMN, state machines, event-driven architectures — these were all attempts to make mission handoffs visible and debuggable rather than hidden inside someone's head or a stack of paper forms.
The real pivot happened around 2015 when distributed task orchestration tools like Apache Airflow and Prefect started appearing. These weren't philosophical improvements. They were born from data engineering teams actually losing entire day's worth of pipeline runs because a single failed task wasn't properly retried or because downstream jobs fired with stale data. Airflow's DAG model — directed acyclic graphs representing task dependencies — was basically the modern equivalent of a foreman's chalkboard showing which workers needed to finish before the next crew could start. The insight wasn't new. The tooling finally caught up to the complexity people were already managing by hand.
Get the Full Details
What Happened When AI Entered the Loop
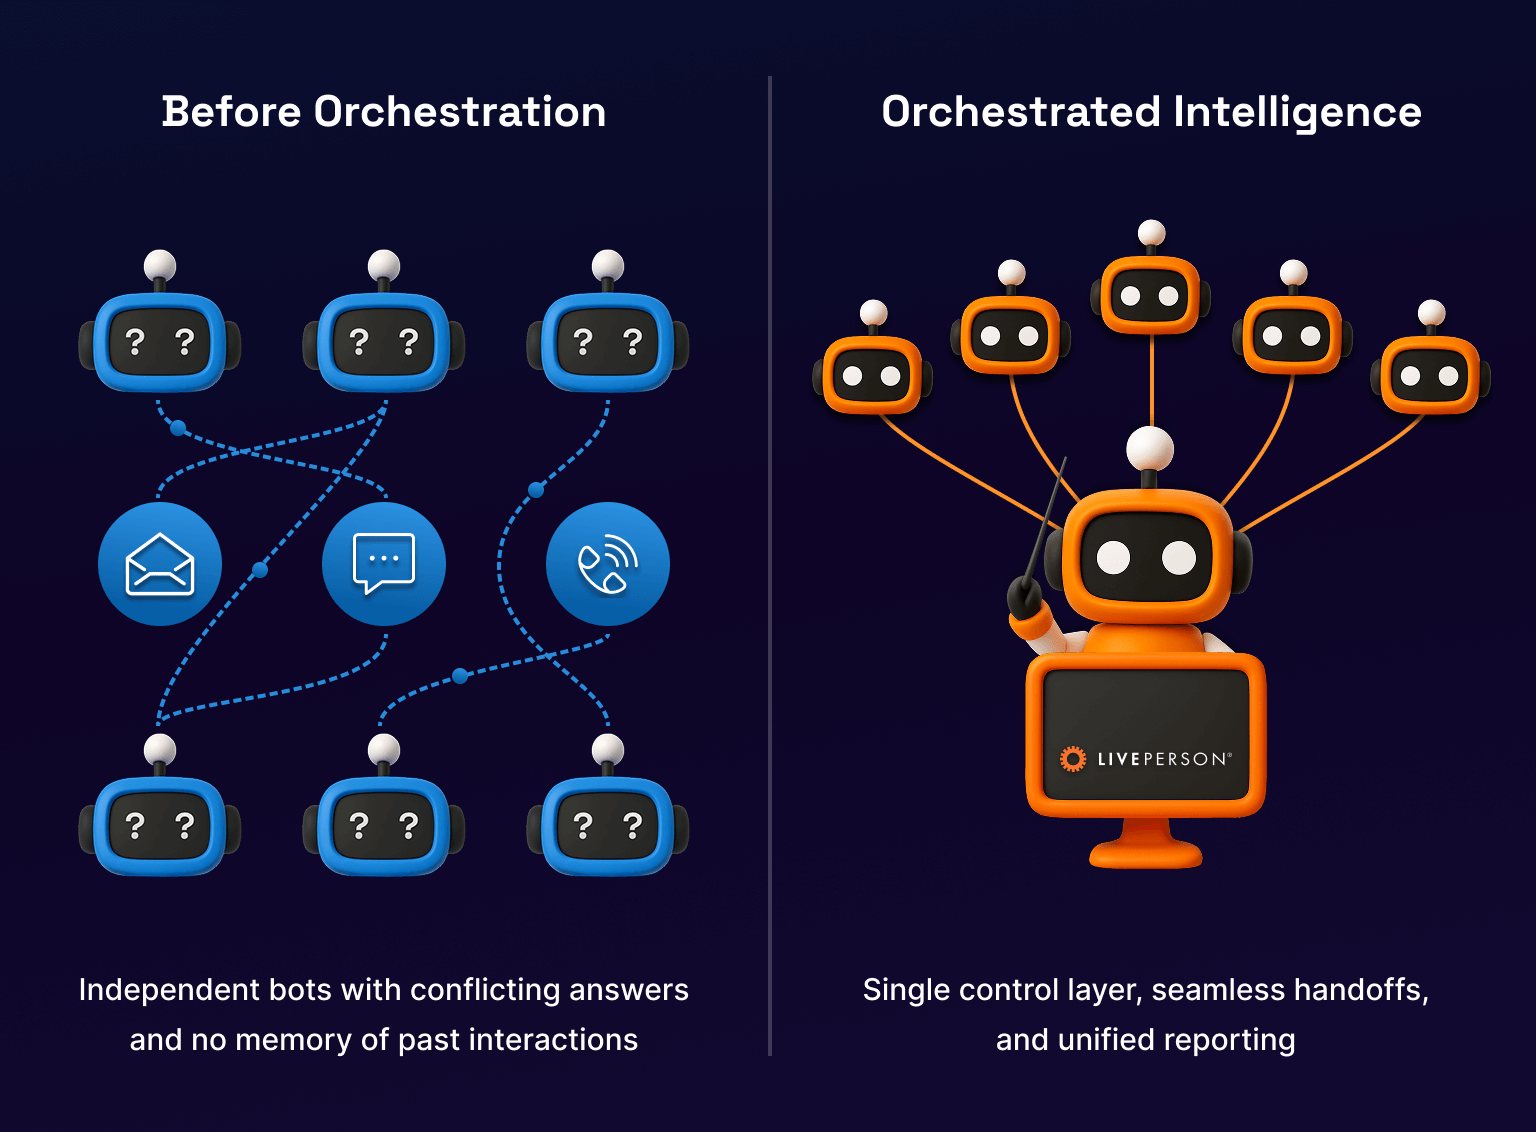
AI orchestration didn't emerge from a whitepaper. It emerged because engineers started running LLM calls in production and immediately hit the same problems that plagued every prior generation of mission systems: tasks would start but never finish, two agents would overwrite each other's state, error handling was nonexistent, and debugging a multi-step agent pipeline felt like performing surgery with oven mitts on. The first generation of AI orchestration frameworks — LangChain, AutoGPT clones, basic agent loops — treated AI as a replacement for scripted decision points. That worked fine until you had a chain of five LLM calls where each one introduced non-determinism, hallucinated inputs for the next step, and silently failed on malformed JSON. You couldn't use traditional retry logic because the failure mode changed every run. A tool that fails deterministically is easy to handle. A tool that fails differently each time requires a fundamentally different approach to mission reliability. Frameworks like CrewAI, LangGraph, and Microsoft's Semantic Kernel emerged from that friction. They introduced concepts like structured handoffs between specialized agents, deterministic state management between non-deterministic model calls, and human-in-the-loop checkpoints. The key insight most tutorials miss is that AI orchestration isn't really about AI. It's about wrapping probabilistic outputs inside deterministic control flow. The agent does the creative work. The orchestration layer does the boring reliability work that used to be handled by cron jobs and message queues.
How It Actually Works in Practice
A production mission system for AI workloads typically has four layers. The orchestrator manages the overall state machine — which task is running, which completed, which failed. The task queue handles distribution and retry logic. The memory layer persists context between agent turns so you aren't re-running the same retrieval or computation. The observability layer logs everything so when something goes wrong at 3 AM you can reconstruct the exact sequence rather than guessing. I built a content moderation pipeline last year that routed user submissions through a classifier agent, then a context-gathering agent, then a final decision agent with human escalation. The classifier was a small fine-tuned model running on a GPU. The context agent pulled from a vector database. The decision agent synthesized everything and produced a labeled output with confidence scores. Under normal load it processed about 200 submissions per minute. Under peak load it degraded gracefully because the task queue buffered requests and the orchestrator throttled parallel agent executions to prevent rate limit hits. The problem I ran into was subtler than anything the documentation covered. The context agent occasionally returned empty results when the vector search returned no relevant documents. The decision agent wasn't designed for that edge case. It would proceed anyway, hallucinate a confident answer based on nothing, and mark the submission as cleared when it should have been escalated. This isn't an AI problem in the usual sense. It's a mission system problem — the handoff between agent two and agent three didn't have a guardrail for null-like conditions, and the orchestration layer treated an empty result as a valid completion rather than a signal to reroute.
The fix was straightforward but required understanding what was actually happening. I added a pre-condition check at the orchestrator level that evaluated the context agent's output quality before allowing the decision agent to execute. If the context retrieval score fell below a threshold, the orchestrator bypassed the decision agent entirely and routed directly to human review. That saved us from roughly twelve percent of edge-case submissions that would have otherwise been incorrectly cleared. The framework itself didn't have this pattern built in. You had to implement it at the orchestration layer, not inside any individual agent.

Common Mistakes People Make
The biggest mistake is treating AI agents as drop-in replacements for scripted workflows. They aren't. A script that reads a file, transforms it, and writes it back behaves identically every time. An agent that does the same thing may parse the file differently on each attempt depending on how the prompt lands, what context it retrieved, and what tokens the model happened to prioritize. Your mission system needs to account for that variance with idempotency checks, output validation, and structured fallback paths. Another mistake is building deeply nested agent chains without proper timeout and circuit-breaker patterns. I've seen pipelines where agent A calls agent B calls agent C calls agent D, and if D times out after forty-five seconds, the entire chain backs up because nobody cleaned up the intermediate state. Standard distributed systems patterns — bulkheads, timeouts, fallback responses — apply here just as much as they apply to microservice architectures. The fact that one of your services happens to be an LLM doesn't exempt it from failure modes. There's also the monitoring problem. Most AI orchestration tools generate logs but don't generate useful observability. You need to track not just whether a mission completed but what the intermediate states looked like — token counts, latency distributions per hop, context window utilization, error classification. Without that granularity you're flying blind the moment something degrades instead of failing completely.
When This Approach Fails Completely
AI orchestration mission systems are overkill for simple deterministic pipelines. If your work involves reading a CSV, running a SQL query, and writing the result somewhere, a cron job with a bash script will be faster to build, easier to debug, and cheaper to operate than a full agent orchestration stack. The complexity tax is real — every additional abstraction layer adds development time, operational overhead, and failure surface. They also struggle with genuinely unpredictable workloads. If your mission system needs to handle tasks that no one has modeled before — open-ended research, creative synthesis with no clear success criteria, negotiations between multiple autonomous agents with conflicting goals — you'll find that the orchestration layer becomes a bottleneck rather than a facilitator. The system was designed to manage known patterns with controlled variance. Truly novel missions expose the limitations of any predefined routing logic. The honest assessment is that AI orchestration mission systems are a specific tool for a specific class of problems: structured but non-deterministic workflows where human-level reasoning is required at one or more steps but the overall process can be meaningfully decomposed into stages. They excel at that. They're expensive and fragile outside of it. Before building one, map out where the non-determinism actually lives in your workflow. If it's concentrated in a single step, you might be better off keeping the rest of the pipeline scripted and only wrapping that one step in agent logic.