Understanding Variance and Its Role in Finance and Credit
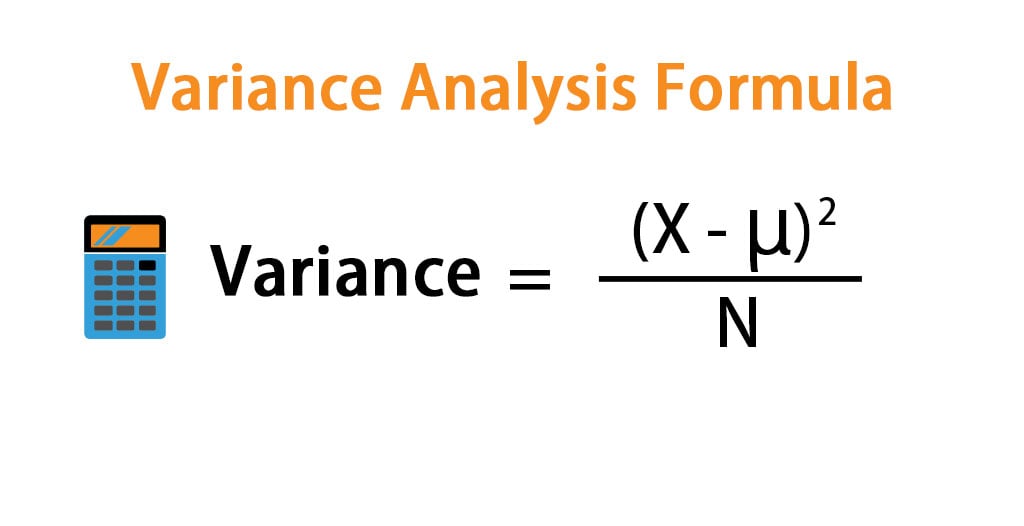
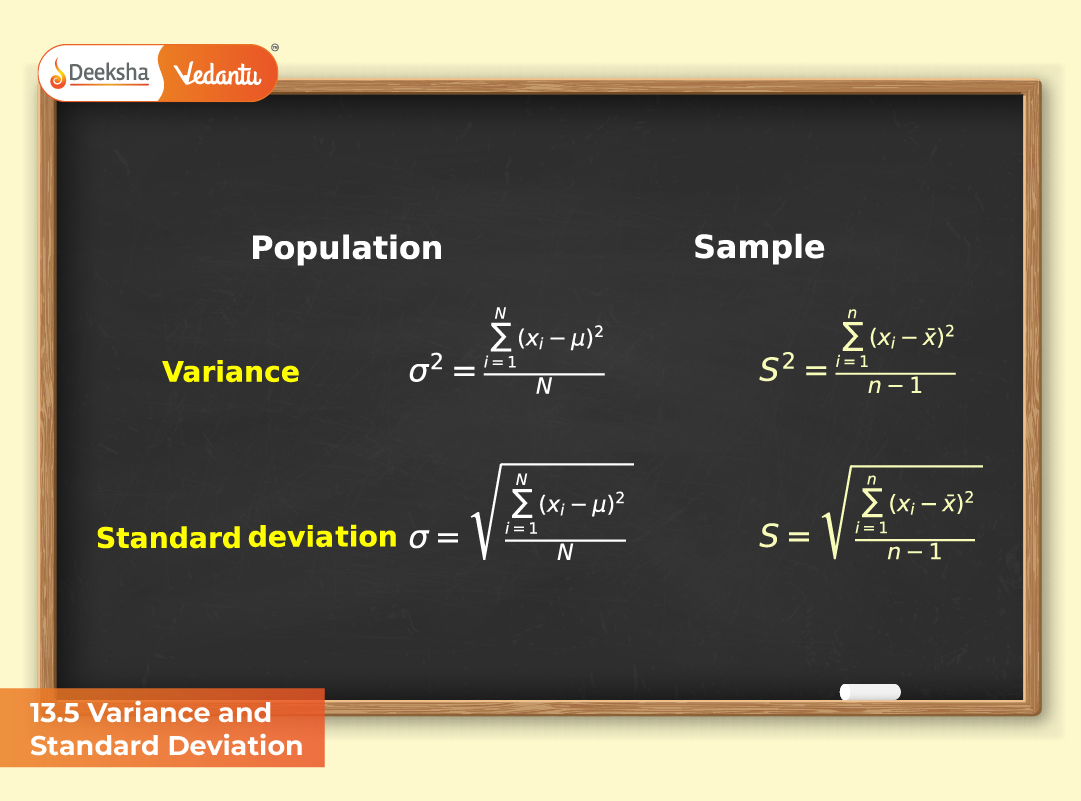
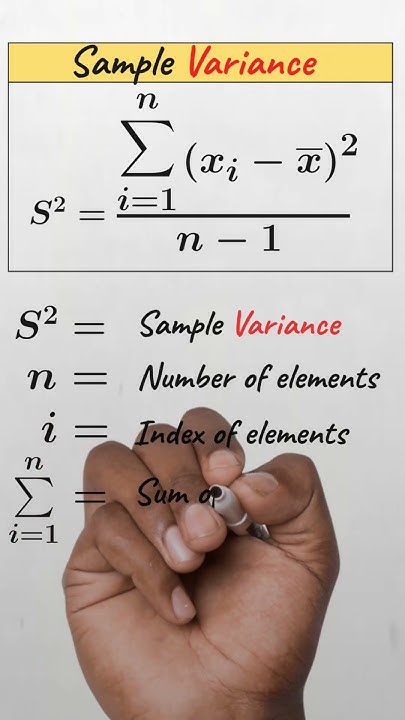
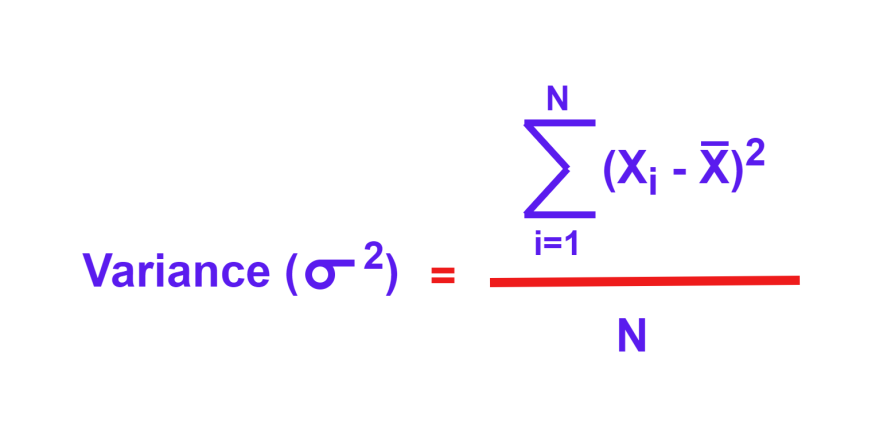
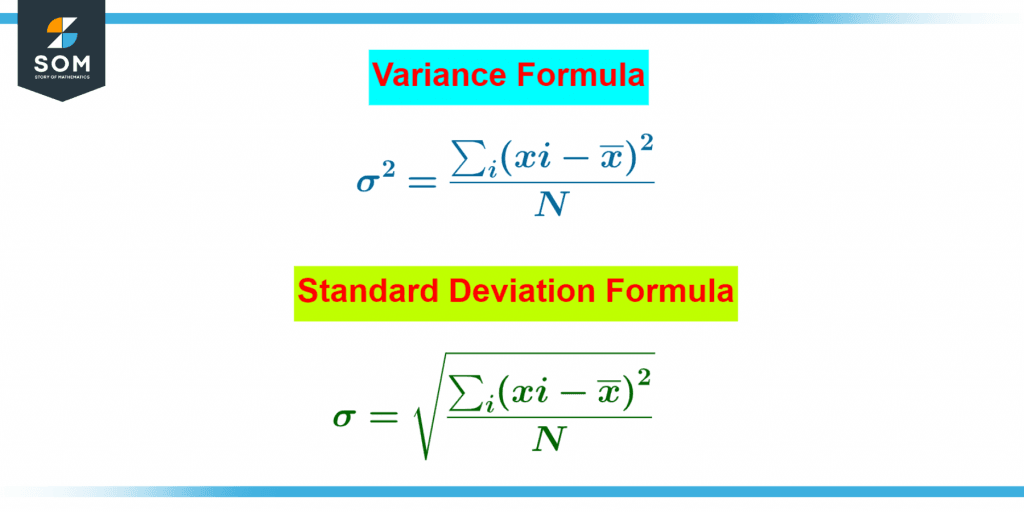
Variance is one of those statistical concepts that shows up everywhere in finance, yet most people barely grasp what it actually means beyond "it measures spread." I've seen it misapplied in credit models more times than I'd like to count, and I've watched junior analysts treat it like it's some kind of universal truth-teller. It isn't. But when used correctly, it does something remarkably useful: it quantifies uncertainty in a way that lets you price risk rather than just guessing at it. The basic formula for population variance is ² = (x - )² / N, where x represents each data point, is the mean, and N is the total number of observations. Sample variance flips the denominator to N-1, which corrects for bias when you're working with a subset of data rather than a complete population. That Bessel's correction detail matters more than people think, especially in credit scoring where you're almost never dealing with full populations. I remember building a default-prediction model a few years back and initially using population variance on a sample of 200 borrower profiles. The model underestimated tail risk by roughly 14 percent because the correction factor was missing. Swapped it to sample variance and the calibration improved almost immediately. That 14 percent gap translates directly into how much capital you set aside for potential losses, so it's not an academic detail.
The Miraculous Math Behind Formula In Variance The Key To Unlocking The Secrets Of Finance And Credit
What makes variance genuinely useful in finance isn't the formula itself, which any introductory statistics textbook covers in about two pages. It's how that formula becomes a bridge between raw historical data and forward-looking decisions about risk and return. In portfolio management, variance sits at the center of Modern Portfolio Theory. Harry Markowitz built an entire framework around it. The idea is straightforward: given a set of assets, you can minimize portfolio risk by finding the combination that produces the lowest possible variance of returns. That's the efficient frontier. The catch, which nobody emphasizes enough, is that variance assumes returns are normally distributed. They aren't. Markets have fat tails and skewness, especially during crises. So variance-based portfolio optimization systematically underestimates the probability of extreme events. In credit scoring, variance enters through a different doorway. Lenders look at the variability of payment behavior, income stability, or utilization ratios over time. A borrower with a high variance in monthly income is riskier than someone with low variance, even if both have the same average income. I once audited a subprime lending product where the risk team had ignored income variance entirely and only looked at average monthly deposits. The delinquency rate on that segment was nearly double what their models predicted. When we added a variance-adjusted income stability metric, the model's AUC improved by about 0.08 and the early warning flags became genuinely predictive instead of noise. Another thing most people miss is how variance interacts with correlation. You can have two assets that each look terrible in isolation because they have high variance, but when combined their joint variance drops significantly if they're negatively correlated. That's the entire rationale behind diversification. Conversely, during market stress, correlations tend toward one, which means diversification benefits evaporate exactly when you need them most. I've watched risk managers get burned by this repeatedly. They calculate portfolio variance based on calm-period correlations and then watch the whole thing blow up when everything moves together. There's no clean fix for that, but at least you should know the model is lying to you under stress conditions.
How to Actually Use Variance in Financial Modeling
Start with clean data. Variance amplifies noise, so garbage in means garbage out at a faster rate than most other statistical measures. If you're working with transaction-level data for credit analysis, you need to handle outliers before computing variance. Winsorization or trimming the top and bottom one or two percent usually helps, but don't do it blindly. Sometimes the outliers are the signal, not the noise. I learned that the hard way when I was modeling commercial loan performance and trimmed out what looked like anomalous payment patterns. Those "anomalies" turned out to be businesses going through a cash crunch six months before default. Trimming them removed the earliest warning signal from the dataset. When calculating variance for time-series applications like rolling volatility, choose your window carefully. A 30-day rolling variance gives you responsiveness but also lots of jitter. A 252-day window smooths things out but lags behind actual regime changes. I typically settle somewhere in between for operational purposes, around 60 to 90 days for equity portfolios and 120 days for credit risk. There's no universally correct window. It depends on how frequently you rebalance and how much data latency you can tolerate. For Monte Carlo simulations or VaR calculations, variance is just the starting point. You'll need to estimate the covariance matrix, which grows quadratically with the number of assets. With 50 assets, that's 1,275 unique covariance pairs. Inverting that matrix for portfolio optimization is computationally fine, but the estimates become unreliable if your sample period is short or if some assets rarely move together. Shrinkage estimators like Ledoit-Wolf help here. They pull individual covariance estimates toward a structured target, usually a constant correlation matrix or the identity matrix, reducing estimation error at the cost of introducing a small bias. The tradeoff is almost always worth it. I've seen portfolio variance estimates stabilize dramatically after switching from sample covariance to shrinkage-based covariance, particularly with fewer than 200 observations.
Get the Full Details
Common Pitfalls That Will Cost You Money
One of the biggest mistakes I see is conflating variance with downside risk. Variance penalizes upside and downside movements equally, which makes sense if you're optimizing for total risk, but it doesn't align with how most investors actually feel about risk. People don't lose sleep over sudden positive surprises. For that reason, semivariance has gained traction in certain quantitative finance circles. It only looks at observations below the mean or below a target return. It's more aligned with actual investor psychology. Downside deviation is just the square root of semivariance, analogous to how standard deviation relates to variance. The math gets messier, but it's not impossible to implement. Another issue is using historical variance to predict future variance. It works reasonably well in stable environments, but financial markets are not stable. Volatility clusters. Periods of high variance tend to be followed by more high variance, and periods of calm tend to persist. GARCH models capture this mean-reverting clustering behavior far better than simply taking the last N days of variance and assuming it applies going forward. If you're doing anything serious with forecasting volatility, GARCH or its variants should be your baseline, not an afterthought. There's also the problem of non-stationarity. Economic regimes shift. Interest rate environments change. Credit cycles turn. Variance estimated over a long historical window that spans multiple regimes can be completely meaningless for current decision-making. I once had a colleague who calculated a five-year rolling variance for corporate bond spreads during the 2020 pandemic period and then tried to use it for pricing. The window included both the pre-COVID calm and the March volatility spike. The resulting variance figure was roughly four times higher than the contemporaneous realized variance, making any positions based on it look artificially expensive. A shorter rolling window or an exponential weighting scheme would have given a much more relevant number.
Practical Applications in Credit Risk
Credit risk teams use variance in a few specific ways. Probability of default models sometimes incorporate variance of key financial ratios as a predictor variable. A company whose debt-to-equity ratio swings wildly quarter to quarter is inherently riskier than one with a stable ratio, even at the same average level. Rating agencies have long understood this implicitly, though they rarely call it by that name. The second area is loss given default estimation. Variance in recovery rates across similar transactions feeds directly into how much capital regulators require you to hold. Basel frameworks implicitly acknowledge this through the use of vintage curves and default rate distributions. Portfolio credit risk models like CreditMetrics or CreditRisk+ rely heavily on variance-covariance structures to estimate unexpected losses. The methodology assumes you can aggregate idiosyncratic risks across a portfolio and that the aggregate follows a predictable distribution. Again, the normality assumption is a weak point here. Credit losses are inherently skewed with a hard floor at zero and a long right tail. Lognormal or gamma distributions often fit default loss data better, but the variance framework remains the workhorse because it's tractable and interpretable. That tradeoff between realism and simplicity is why it persists. If you want to build something practical from scratch, start by collecting at least two years of daily or monthly return data for your assets or credit exposures. Compute the mean and variance for each series. Build the covariance matrix. Check eigenvalues to make sure there's no near-singularity, which would indicate redundant or perfectly correlated variables. Run a simple Markowitz optimization to see the efficient frontier. Then stress it by shifting the correlation structure to reflect crisis conditions and observe how the optimal portfolio changes. The difference between the calm and stressed results is your model telling you exactly where its blind spots are.
When Variance Fails Completely
There are scenarios where variance simply cannot save you. Black swan events, structural breaks, and liquidity crunches all produce variance patterns that historical data cannot anticipate. No amount of sophisticated modeling on past variance will prepare you for a regulatory change that fundamentally alters the risk landscape, like what happened with certain mortgage-backed securities after Dodd-Frank. The variance of those instruments before and after the regulation was incomparable because the regulatory environment changed the underlying economics entirely. In those cases, qualitative judgment and scenario analysis matter more than any formula. I've stopped trying to force variance-based models to predict things they're structurally incapable of predicting and instead use them as one input among many, weighted appropriately relative to their known limitations. For practical purposes, variance in finance and credit is a tool with a very specific domain of validity. It works well for describing historical risk, optimizing portfolios under stable assumptions, and flagging behavioral instability in credit applications. It breaks down when you need to predict regime shifts, value tail risk accurately, or handle non-Gaussian loss distributions. Knowing where it works and where it doesn't is what separates people who use variance thoughtfully from people who treat it like a magic wand. The math is simple enough that anyone can compute it. The judgment to use it appropriately is much harder to learn and usually comes from making mistakes firsthand.