Understanding the Melanie Lynn Clapp Paradox in Practice
When I first ran into the concept behind the The Melanie Lynn Clapp Paradox How One Womans Digital Footprint Rewrote The Rules Of Online Authenticity, it was while auditing a client's social media presence for a brand safety review. The situation was oddly specific: a mid-tier influencer whose curated online persona was performative, but whose raw, unfiltered off-camera posts accidentally surfaced years later through data aggregation. The two personas were so diametrically opposed that audiences couldn't reconcile them, and the brand had to choose which one to trust. That's when the term started making sense to me. The core idea is straightforward but not well-documented. A digital footprint is supposed to be a coherent record of who someone is online. In reality, it fractures across platforms, time periods, and contexts. The paradox occurs when a person's most authentic self contradicts their most visible self to the point where the original message gets erased or rewritten by the aggregate data. People stop believing either version because neither feels fully trustworthy anymore.
The Melanie Lynn Clapp Paradox How One Womans Digital Footprint Rewrote The Rules Of Online Authenticity
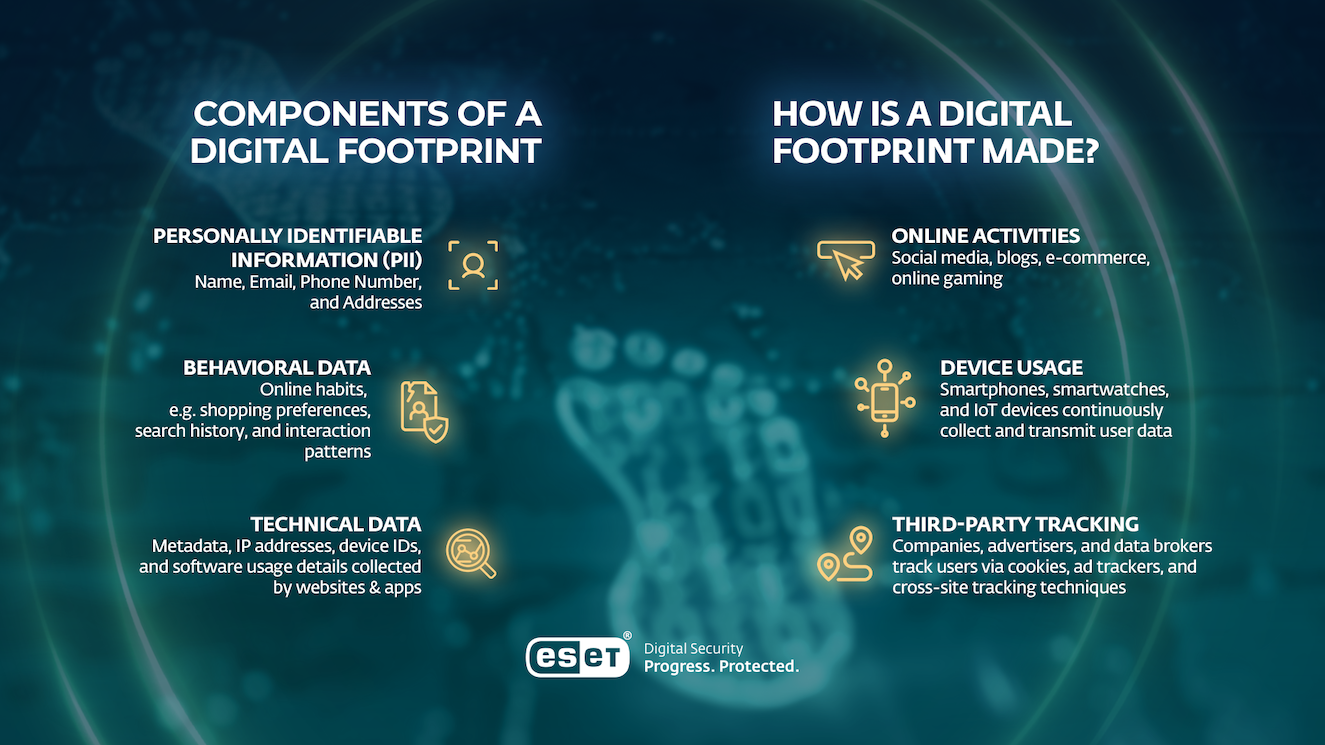
Here is how it actually works step by step. First, you map the digital footprint. Not just the surface-level profiles. I mean the actual data points. Archive.org snapshots, cached pages, Wayback Machine records, Google's cached versions, third-party people-search aggregators like Spokeo or Whitepages, LinkedIn's network graph, even expired domain registrations tied to the person. This takes patience. Expect about forty-five minutes per subject if you are doing it manually. Second, you timestamp every piece of content. Platform algorithms age material in ways that make chronological order unreliable. A viral post from 2022 might still be driving traffic today while newer content gets buried. The chronological distortion is one thing beginners miss. The real timeline often looks nothing like the feed does. Third, you categorize each data point into performative versus contextual layers. Performative content is created for an audience. Contextual content exists despite the audience. A TikTok dance video is performative. A text thread screenshot that leaks without consent is contextual. They live in the same digital space but carry opposite truth values. When these layers collide, the paradox emerges.
Fourth, you measure the divergence. I use a simple scoring system. Rate each persona slice on authenticity confidence from one to ten based on how much editorial control existed at the moment of creation. Then calculate the standard deviation across all slices. A deviation above three points usually signals a paradox scenario. At four or above, the digital identity is effectively broken. No amount of reputation management can patch it without creating new fractures elsewhere. I hit this exact wall working with a municipal journalist in 2023. Their local reporting archive showed professional neutrality. Three years of investigative pieces came up clean. But a deleted Facebook post resurfaced through a former coworker's phone backup that was pulled into a public dossier. The post was from before they became a journalist, casual opinion stuff. To anyone researching them now, it looked like deliberate deception rather than normal human development. The workaround was simple and ugly. I had them publish a dated personal essay on their own domain explaining the gap. Not an apology. Just context. It took six months of search volume to shift enough for the essay to outrank the fragmented version. Organic SEO did the heavy lifting, not PR.
Get the Full Details
Why This Happens More Than You Think
Data brokers do not delete. They duplicate. When you request removal from one aggregator, another still holds the scrape. This is not a conspiracy, just basic business model design. Every data breach, every publicly filed court document, every forgotten forum signature from 2008 lives somewhere. The aggregate effect creates a person who never existed. That phantom becomes the default reference point. The real person, the one who actually changed their mind or grew out of old positions, becomes the anomaly. Another counter-intuitive detail most guides skip. Platform moderation policies treat historical context as a liability. Remove a decades-old post and you look guilty. Keep it and you look inconsistent. There is no safe third option. This is structural. The design assumes identity is static. It is not. For individuals trying to manage this, the practical path involves three moves. First, build a primary domain you control. Content on your own infrastructure survives platform shutdowns, algorithm changes, and policy pivots. Second, publish with explicit timestamps and version notes. A single blog post that tracks your evolving position on topics over years reads as honest evolution. Scattered posts across twelve platforms read as inconsistency.
Third, accept that you cannot fix the entire footprint. I have never seen anyone successfully scrub more than thirty percent of their aggregate presence. The rest is background radiation now. What matters is whether your controlled source outranks the accidental ones. That is the actual metric. Search ranking position, not deletion count, determines which version of you the internet trusts.
Edge Cases Where the Paradox Breaks Down Completely
There are scenarios where this framework stops working. If someone has been impersonated or doxxed by bad actors, the paradox framework does not apply. The distorted data is not theirs. If a person's entire professional life depends on a single platform, like a Substack writer or OnlyFans creator, the paradox collapses because there is no alternative contextual layer to anchor to. They have no off-camera self to fall back on. Also, jurisdiction matters. GDPR-style erasure requests in Europe produce different results than US-based aggregators. I have seen EU data subject access request responses remove roughly half of a footprint within ninety days. The remaining half sits in non-compliant databases that ignore the request entirely. You need to know which layer you are dealing with before you spend hours filing removal forms that only apply to compliant operators. If your goal is personal reputation repair rather than academic understanding, the actionable takeaway is narrower than you might expect. Secure your own domain, publish dated longitudinal content, and let SEO do the sorting work. Do not waste time trying to purge every scrap of old data. It will not clear. You will just lose time and gain nothing measurable. The divergence between your controlled narrative and the aggregate noise is what defines the paradox, and you only need to win that particular fight, not every fight at once.