How to Identify What You're Actually Measuring in an Experiment
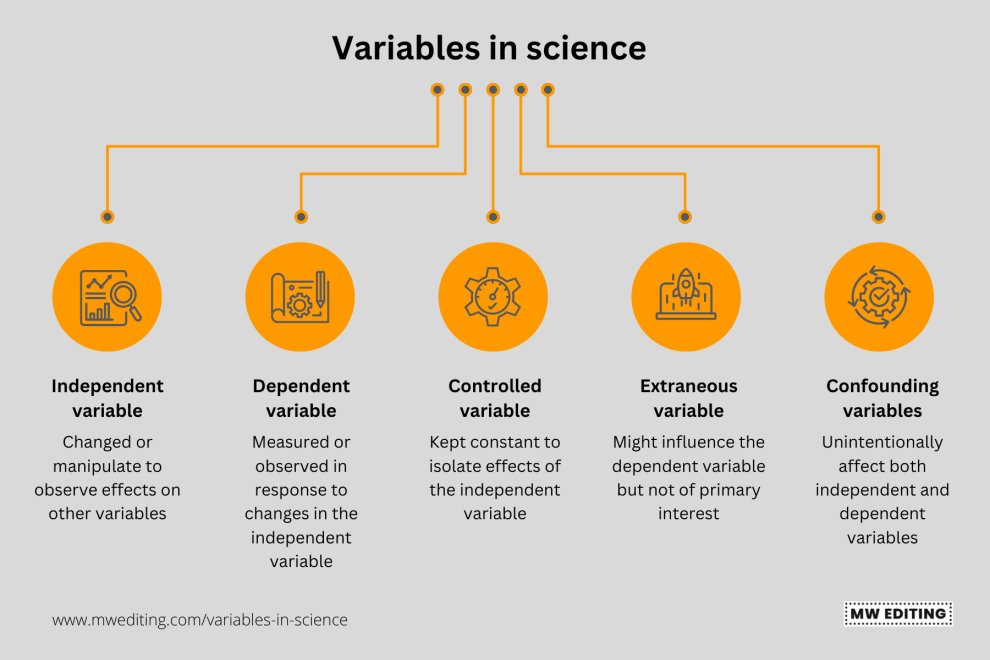
Most people get confused about dependent variables because textbooks describe them in abstract terms. They say "the variable you measure" but don't explain why that matters or what happens when you mess it up. Let me walk you through how this actually works in practice.When I was designing a study on soil pH effects on plant growth about three years ago, I made a mistake that cost me two months of work. I thought I was measuring plant height as my dependent variable. My independent variable was soil pH levels. But when I analyzed the data, I realized my height measurements were completely unreliable because the seedlings were leaning toward the light source, not growing upward. What I thought was my dependent variable was actually contaminated by an uncontrolled factor. The fix was simple but painful — I rotated the trays every 48 hours and started measuring biomass instead of height. Dry weight gave me data I could actually trust. A dependent variable is the outcome you track. It depends on whatever you change in your experiment. If you vary the temperature and measure reaction rate, the reaction rate is your dependent variable. That's the basic definition. But the practical reality is messier. In a well-designed experiment, you have one independent variable and one or more dependent variables. The independent variable is what you manipulate. The dependent variable is what responds. You record the dependent variable's values across different conditions and look for patterns. Statistical tests then determine whether those patterns are real or just noise.
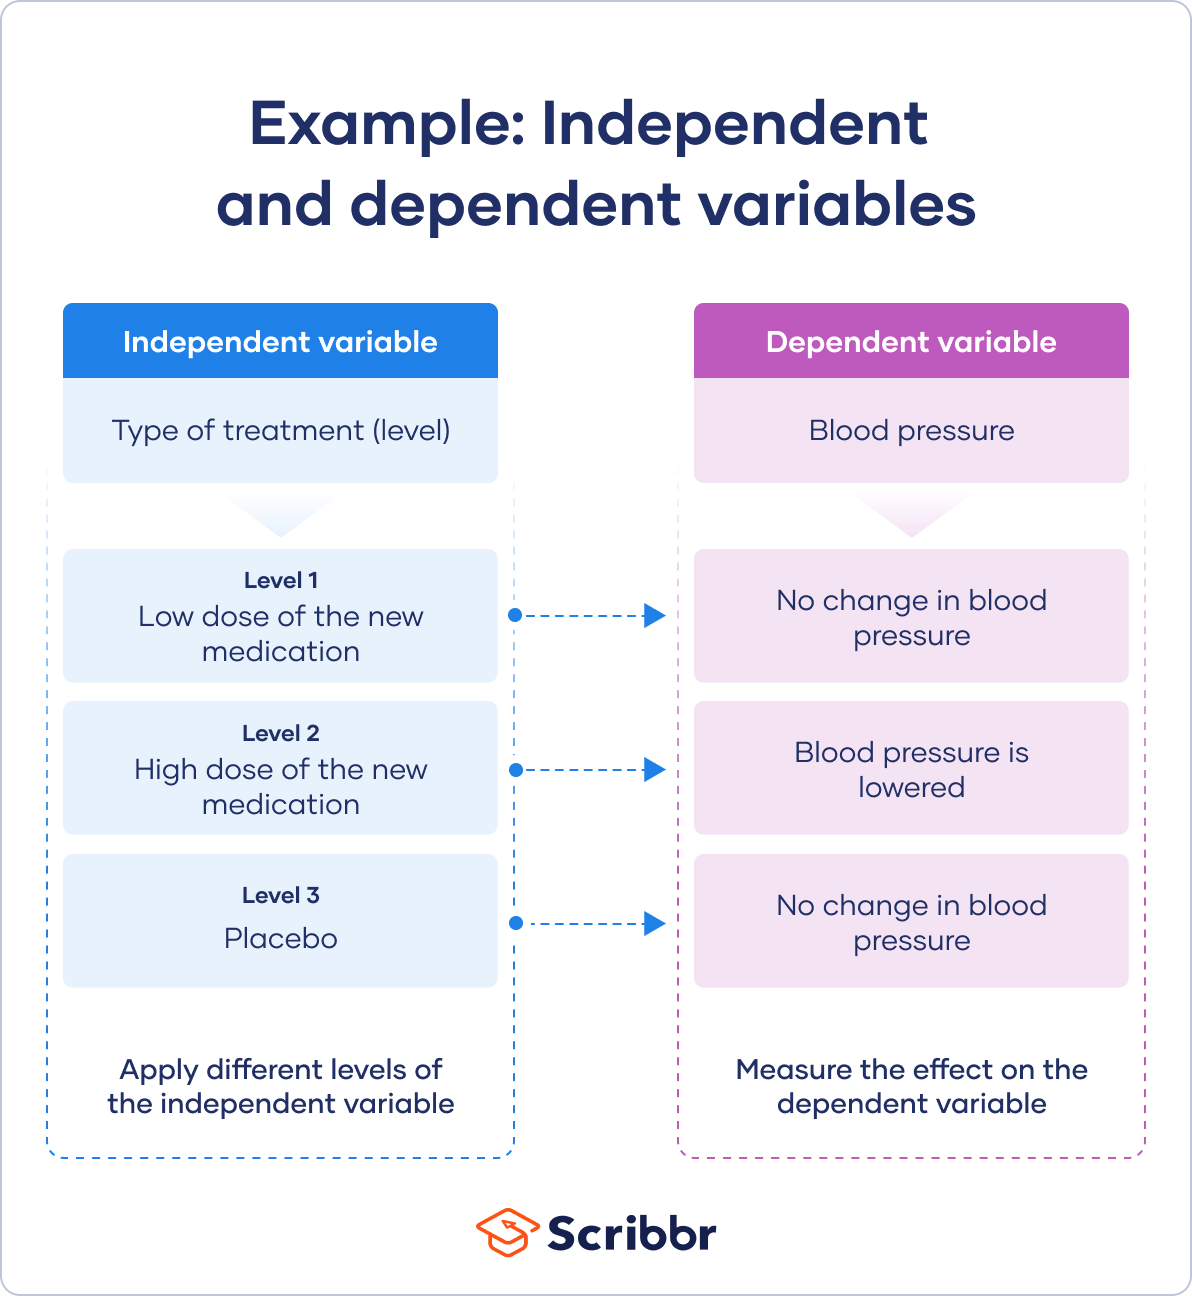
Here's something most guides skip: dependent variables can interact with each other. If you're studying drug dosage (independent variable) and measuring both blood pressure and heart rate (two dependent variables), those two outcomes are correlated. Changes in blood pressure affect heart rate. Treating them as independent measures in your analysis will inflate your false positive rate. You need multivariate methods like MANOVA instead of running separate t-tests. I learned this the hard way when a colleague published results that fell apart under scrutiny because he ran three separate ANOVAs on correlated dependent variables. The choice of dependent variable also determines your statistical power. A continuous dependent variable like mass in grams gives you more analytical flexibility than a categorical one like alive or dead. With continuous data you can use parametric tests, calculate effect sizes precisely, and detect smaller differences. With binary data you need larger sample sizes to achieve the same power. When I design experiments now, I prioritize dependent variables that are continuous and measurable on a fine scale. It doesn't always work — some phenomena are inherently categorical — but when you can measure on a ratio scale instead of a nominal one, your analysis gets significantly stronger.
Setting Up Your Dependent Variable Properly
Before you run any experiment, write down exactly what your dependent variable is and how you'll measure it. I mean specifically. "Plant growth" is not sufficient. You need "dry biomass in grams after 14 days at 25°C." The more precise your operational definition, the less ambiguity there is when you collect data or when someone reviews your methodology later. Consider your measurement instrument's precision limits. A standard lab balance reads to 0.01 grams. If your dependent variable is something that changes by 0.005 grams per condition, you're going to drown in noise. I once designed an assay where the expected effect size was smaller than the instrument's resolution. The data looked flat across all conditions because the device couldn't detect the difference. Switching to a microbalance that reads to 0.0001 grams revealed the pattern immediately. Always match your measurement tool to the scale of your expected effect. Blinding matters too. If you're measuring something subjective — like rating pain levels or behavioral scores — and the person collecting the data knows which condition each subject is in, you introduce observer bias. It's subtle but real. In my lab we use coded identifiers so the person recording data never knows the group assignment until after collection is complete. This adds maybe 10 minutes to the workflow but prevents a class of errors that can't be fixed retroactively.
Get the Full Details

Another thing nobody talks about enough: your dependent variable should be measured at consistent intervals. If you measure one subject at 24 hours and another at 36 hours, the time difference becomes a confounding variable. I've seen this happen in busy labs where participants roll in at different times and researchers adjust measurement schedules to fit. The resulting data looks fine on the surface but introduces systematic error. Standardize your measurement timing or account for it statistically.
Common Mistakes That Ruin Dependent Variable Data
The biggest mistake is reversing the relationship. People sometimes treat the independent variable as if it's the outcome. This happens when your manipulation isn't actually what you think it is. In a teaching intervention study, for example, the researcher might assign students to different methods (independent variable) and measure test scores (dependent variable). But if some students received extra tutoring outside the study, the test score is no longer cleanly dependent on the teaching method. You've lost control of your causal chain. Always verify that your independent variable is the thing you actually think it is. A second mistake is measuring the wrong thing entirely. You might have a solid theoretical framework but pick a dependent variable that doesn't actually capture your construct. If you're studying "stress" and you measure heart rate, you're getting a physiological correlate, not stress itself. Heart rate changes with exercise, caffeine, temperature, and dozens of other factors. A better dependent variable might be a validated self-report scale administered under controlled conditions, or cortisol levels from saliva samples. The dependent variable needs to actually map onto the phenomenon you claim to be studying. There's also the problem of regressing to the mean. If you select subjects based on extreme initial scores on your dependent variable and then measure them again, the second measurement will tend to be closer to the average regardless of any intervention. This is a statistical artifact, not a real effect. I see this constantly in education research where students with low baseline scores show "improvement" after a program, but the improvement is partly just natural statistical movement. Always include a control group measured at the same time points to account for this.
When Dependent Variables Don't Behave
Sometimes your dependent variable violates the assumptions of standard statistical tests. Non-normal distributions, outliers, heteroscedasticity — these happen. If your data isn't normally distributed, you can use non-parametric alternatives like the Mann-Whitney U test instead of a t-test. If variances differ across groups, Welch's correction handles that. The point is that the existence of messy data doesn't invalidate your dependent variable — it just means you need the right analytical tool. There are cases where no clean dependent variable exists. In exploratory research, especially in fields like ecology or anthropology, you might be observing systems with too many interacting factors to isolate a single outcome. In those situations, you can still publish meaningful work by using descriptive statistics, visualization, and hypothesis-generating language rather than claiming causal relationships. Don't force a dependent variable framework onto research questions that don't fit it. Another limitation worth noting: dependent variables only tell you what happened, not why. They give you correlation and prediction, not mechanism. If you need to understand causation, you need additional experimental designs — randomized controlled trials, mechanistic studies, or computational models — not just a well-chosen dependent variable. I've seen researchers treat a statistically significant dependent variable result as proof of a theoretical claim. It isn't. It's evidence that needs triangulation from other methods.