Reading Manga Online: How Mangakakalot and Similar Sites Changed Everything
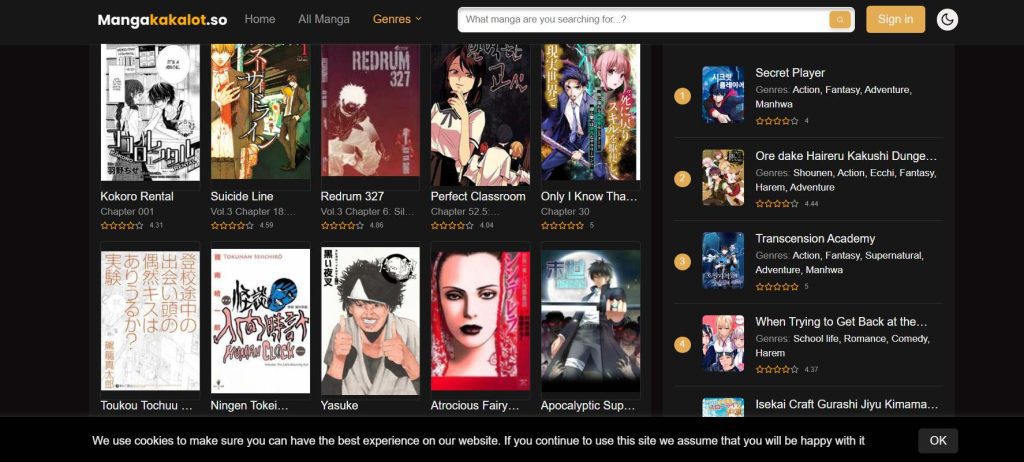
I stumbled onto Mangakakalot around 2013 when I was trying to catch up on Bleach and couldn't afford tankobon volumes yet. The site was already running, already cluttered with ads, already exactly the kind of place that felt like you were trespassing but nobody was going to stop you. It's still running in some form today, and the ecosystem around it has only gotten more complicated. What started as a handful of fan-translation aggregators in the mid-2000s has grown into an entire underground infrastructure. Mangakakalot itself is just one node in a network that includes sites like MangaDex, Tachiyomi mirrors, raw aggregator boards, and a dozen copycat domains that pop up and die within months. The core model hasn't changed: someone scans chapters from Japanese releases, translates them, uploads the pages, and the site compiles everything into a readable viewer. The difference now is scale and automation. The technical side is straightforward enough. These sites typically run on custom CMS platforms built around image hosting. Pages are stored as individual JPGs or PNGs, loaded sequentially through JavaScript viewers that preload adjacent chapters. Some operate on their own CDNs. Most rely on third-party image hosts like Imgur, RZCloud, or various Asian file-hosting services, which is why broken images and dead links are a constant problem. When an image host changes its terms or gets taken down, entire series lose chapters overnight.
I've maintained personal libraries tracking down missing chapters across these sites, and let me tell you, it's a full-time hobby if you're serious about it. There's a reason why people use tools like Tachiyomi with extensions rather than browsing directly — the sites themselves are unreliable by design. They rotate domains constantly to stay ahead of takedowns. The URL you bookmarked today might point to a parking page next month.
How the Ecosystem Actually Works
Behind the scenes, most of these sites pull from the same source pool. Scanner groups release chapters on their own boards or Telegram channels, and the aggregation sites scrape or manually copy them. The translation quality varies enormously depending on who did the work. Some groups are professional-grade with typesetting that rivals official releases. Others are one person working through chapters at 2 AM with machine translation and zero proofreading. You can usually tell within the first three pages. The business model is almost entirely ad-driven. Pop-ups, redirect chains, and display ads fund the hosting costs. This is also why these sites are terrible for your device — ad networks serving traffic from gray-market sites are some of the most aggressive on the internet. I've seen legitimate security software flag these pages, and honestly, it's not always wrong to be cautious. Malvertising has been a real problem on sites like this for years. One thing people don't realize is how much of the content on these sites isn't even original scanning work. A significant portion cycles through the same pool of leaks. A chapter drops on one site, gets mirrored to ten others within hours, and by the time it reaches the smaller aggregators it's already been compressed multiple times. The visual quality degrades with each re-upload. If you care about image quality, you're better off finding the original scanlator's release page rather than going through an aggregator.
Get the Full Details
Practical Problems and Workarounds
The biggest frustration I've run into repeatedly is series that get abandoned mid-run. A manga starts getting updated weekly, then suddenly the uploads stop. On official platforms this is obvious — the series page shows the gap. On aggregator sites, the chapter list just stops at whatever volume was last uploaded, and there's no indication whether the series ended, the scanlation group disbanded, or the site lost access to the source material. My workaround for this is cross-referencing. I check multiple sources and also look at the Japanese release schedule directly when possible. If Weekly Shonen Jump chapters are dropping on a known schedule and the aggregator hasn't updated in six weeks, something is wrong. Sometimes it's a legal pressure event — Kodansha and Shueisha have been increasingly aggressive about domain seizures since 2020. In those cases the content sometimes reappears on a new domain months later, but you have no way of knowing which one. Another issue is region blocking. Many of these sites restrict access based on IP geolocation. I've had clients who needed access to specific titles that were blocked in their country, and the usual workaround involves VPN routing through regions where the site is accessible. This adds latency and sometimes breaks image loading entirely because the CDN routes differently for VPN traffic. Not ideal, but functional when you need something urgently.
What This Space Is Losing
The community side of online manga reading has changed dramatically. Early forums like MangaForum and MyAnimeList discussion boards had real human curation. People recommended scanlation groups, reported broken links, and maintained quality standards. Most of that has moved to Discord servers and Reddit communities, which are faster but less searchable and much more ephemeral. When a server gets banned or modded out, months of recommendations disappear with it. MangaDex came as a partial solution with its community-driven metadata and reporting system, but even it faces constant pressure. The site has been subjected to DDoS attacks and legal threats that forced temporary shutdowns. The infrastructure sustaining free online manga is fragile by nature, and that fragility is likely to get worse, not better, as enforcement tightens.
What Actually Works Day to Day
If you're going to use these sites regularly, there are a few things that make the difference between tolerable and miserable. A good ad blocker is non-negotiable — uBlock Origin set to aggressive mode will save you from most of the redirect chains and pop-ups. Running the browser in a dedicated profile or container isolates cookies and tracking. And using a reader app with extension support like Tachiyomi or its forks gives you significantly more control over which sources you pull from and how content is cached locally. For actual reading quality, nothing beats having the physical volumes or official digital copies when available. These sites serve a purpose — discovery, accessibility for people who can't afford subscriptions, catching up on series before official licenses land — but they're inherently unstable. Content disappears. Links rot. The sites themselves vanish. Building a habit around them is reasonable. Building a strategy around them is not.