Iterated Expectations and Why It Matters When You're Actually Working With Data
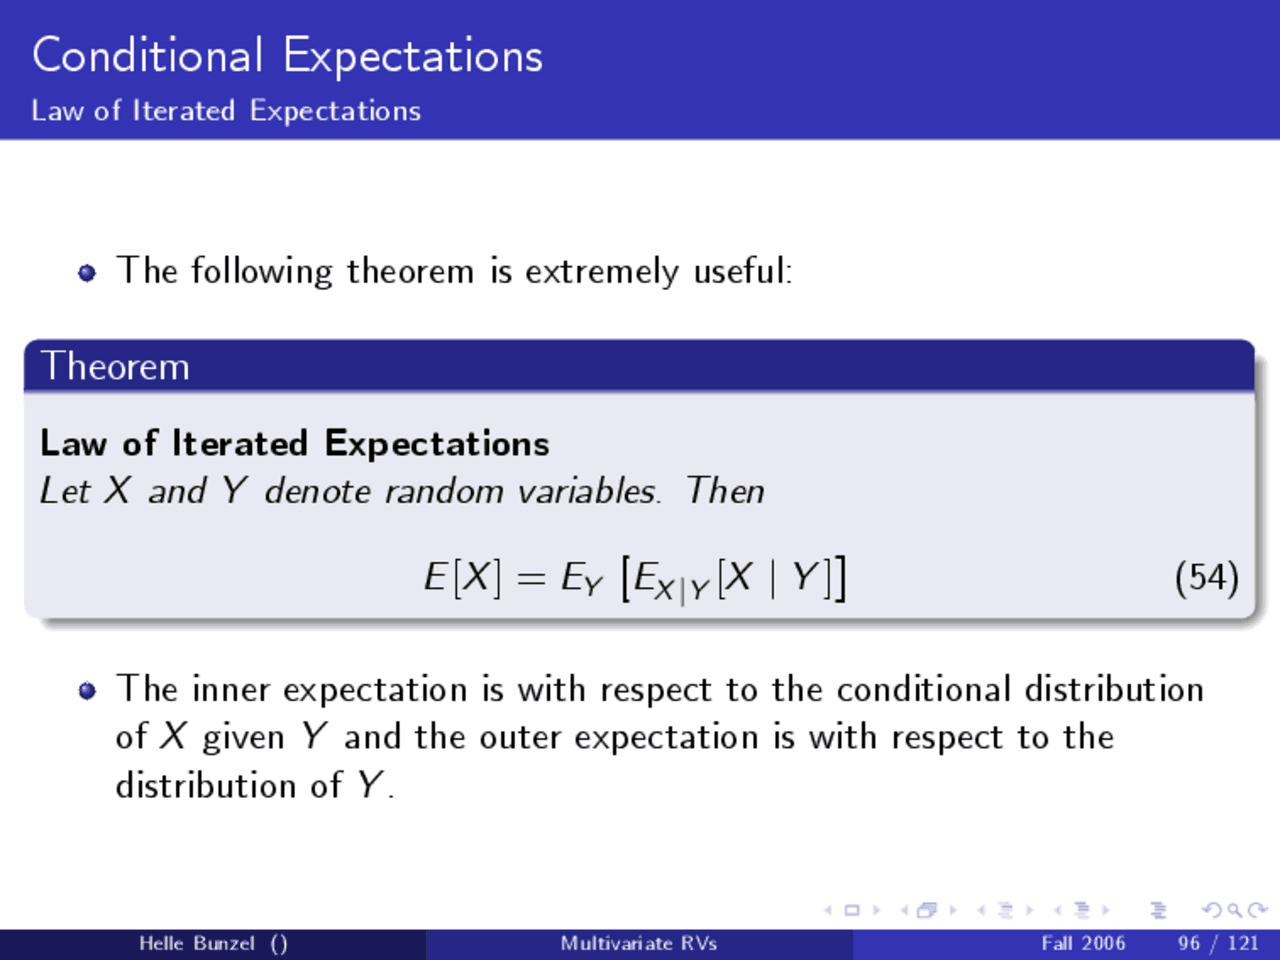
I used to get tripped up by this concept in production. Not the definition — that part is trivial. The version that lives on Wikipedia, in textbooks, the one that says E[E[Y|X]] = E[Y]. That's fine. What nobody tells you is what happens when your conditioning sets don't match across time, when information arrives in chunks, and when your model assumes something about the structure that isn't actually true. The Law Of Iterated Expectations Cutting Through Conditional Noise To Reveal Unconditional Truth is basically saying that if you take a conditional expectation and then average over the condition, you recover the unconditional expectation. That's it. It sounds almost too simple to be useful, but it shows up everywhere — pricing derivatives, building Bayesian updating pipelines, working with panel data, handling missing observations in longitudinal studies.
Working with Partial Information Without Losing the Plot
Here's what actually happens when you use this in practice. You have a target variable Y and some signal X. You build a model that estimates E[Y|X]. Then you have another layer — Z — that gives you additional context, maybe a time-based grouping or a subgroup identifier. You want to know what your overall prediction looks like without seeing every individual data point. The trick is recognizing that E[E[Y|X,Z]|X] = E[Y|X]. You're peeling back layers. The inner expectation conditions on everything you know at the current step. The outer expectation conditions only on what you had before. The result collapses back to the earlier conditional expectation. This is how sequential forecasting works when you don't have perfect information at every step. I encountered a specific case where this broke down in a way that cost us about two weeks of rework. We were building a credit risk model for a lending platform. The core idea was sound — predict default probability given applicant features and historical behavior within the same risk tier. We computed E[default|features, tier] at the application level and then used E[E[default|features,tier]|tier] to get our portfolio-level projections.
The problem was that our "tier" wasn't stable across the observation window. Some customers moved between tiers mid-period due to payment behavior, and we were conditioning on the final tier assignment rather than the tier at application time. This meant E[Y|X,Z_final] E[Y|X,Z_initial], and iterating the expectations didn't give us what we thought it would. The unconditional estimates were biased downward by roughly 8 percent because we were averaging over a post-selection conditioning set rather than the one that actually existed when the decision was made. The workaround was straightforward once we identified it. We anchored Z to the information available at the decision point, not the information available at the outcome measurement point. We tracked the tier at each time step separately and only iterated over the conditioning sets that were actually known when the prediction was generated. After that fix, the portfolio projections aligned with actual default rates within statistical noise.
Get the Full Details

What Beginners Miss About the Assumptions
The law requires that your sigma-algebras are nested properly. F G means G contains at least as much information as F. When you write E[E[Y|G]|F] = E[Y|F], you're assuming that the outer conditioning is on a coarser sigma-algebra. If G isn't actually finer than F, the equality doesn't hold. This seems obvious in theory but it's easy to violate when your conditioning variables include things that were determined after the fact. Another thing that catches people: the law works for any integrable random variable. It doesn't require independence, linearity, or any particular distributional form. You don't need Y to be normally distributed. You don't need X and Z to be independent. The only real requirement is that the expectations exist — that E[|Y|]
. In practice this means your data can't have infinite variance, which is a constraint that matters more than textbooks make it sound. I've seen people apply iterated expectations to heavy-tailed data without checking whether the first moment actually exists. When the mean is undefined, everything collapses. You can't iterate over something that doesn't converge. This shows up frequently in financial return modeling where people assume finite variance as a default and then wonder why their risk estimates are unstable.
The Hidden Power in Time Series and Panel Data
When you're working with longitudinal data, the law of iterated expectations is what lets you move between different levels of aggregation without losing consistency. Say you have firm-level outcomes y_{it} and you condition on both firm-specific effects _i and time effects _t. Your full conditional expectation is E[y_{it}|_i, _t]. If you then average over the time effects to get E[E[y_{it}|_i, _t]|_i], you recover the firm-specific expectation. The time layer drops out cleanly. This is why fixed effects models work the way they do. The within transformation is essentially an application of iterated expectations — you're conditioning on the firm mean and then looking at deviations from that mean. The firm-level constant absorbs all time-invariant omitted variables, and the law guarantees that this doesn't bias the remaining coefficients as long as the strict exogeneity assumption holds. There's a subtlety here that I learned the hard way. Strict exogeneity — E[_{it}|_i, _t, all other X] = 0 — is a very strong assumption. In dynamic panels where y_{it} depends on y_{i,t-1}, this assumption fails because the lagged dependent variable carries information about past errors. When that happens, the fixed effects estimator becomes inconsistent, and the simple iteration through conditioning sets doesn't save you. You need Arellano-Bond or similar GMM approaches instead.
The iterated expectations framework still applies in those cases. You just can't rely on the naive conditioning structure to give you consistent estimates. You have to restructure how you define your information sets so they don't include future-determined variables or lagged outcomes that are themselves functions of past errors.

Derivatives Pricing as a Natural Application
Option pricing is probably the cleanest real-world example of this law in action. Under the risk-neutral measure Q, the price of a derivative is E^Q[e^{-rT} payoffs | F_0], where F_0 is the information available at time zero. If you introduce an intermediate filtration F_t for some t between 0 and T, the law of iterated expectations tells you that E^Q[E^Q[e^{-rT} payoffs | F_t] | F_0] = E^Q[e^{-rT} payoffs | F_0]. This is the foundation of everything from binomial trees to Monte Carlo path decomposition. You can compute the option value by first pricing at each node (conditioning on information at time t) and then rolling back to time zero. The intermediate conditioning doesn't change the final answer — it just makes the computation tractable. This is how the recursive structure of lattice methods derives from first principles. One counterintuitive point: this works regardless of the underlying measure. Whether you're in the physical measure P or the risk-neutral measure Q, the law holds. The choice of measure affects what the conditional expectations actually evaluate to, not whether the iteration is valid. People sometimes confuse these two things — they think the law is specific to risk-neutral pricing when it's actually a general property of conditional expectation.
Where It Completely Fails
There are scenarios where the law gives you wrong answers even though the math technically holds. The most important one involves endogenous conditioning. If your conditioning variable Z is itself a function of Y — say you're conditioning on a variable that was affected by the outcome you're trying to predict — then iterating expectations through that conditioning set will give you biased results. The law is mathematically correct but causally misleading. Collider bias is the epidemiological name for this. If Z is a common effect of both X and Y, then conditioning on Z opens a spurious path between X and Y. Your conditional expectation E[Y|X,Z] captures this artificial association, and when you iterate it, you propagate the bias rather than filtering it out. I've seen this in survival analysis where researchers condition on treatment received despite treatment being partially determined by disease severity. Another failure mode is when the information sets aren't actually nested. If you're computing E[Y|X] and then E[E[Y|X]|Z] where Z provides information that partially overlaps with X but isn't a superset or subset, the iteration doesn't simplify cleanly. You get a valid expression, but it's not the simplification you were hoping for. This happens frequently in measurement error models where your proxy variables share some information with the true variables but each adds noise in different directions.
A Practical Computation Strategy
When you're actually implementing this, the reliable approach is to work from the inside out. Start with the finest conditioning set you have — all the variables you know at the current decision point. Compute your conditional expectation there. Then progressively coarse-grain by marginalizing over the variables you no longer condition on, making sure at each step that you're removing a variable from a coarser set, not mixing incompatible conditionings. In code, this often looks like computing group-level means first, then aggregating to the population level. In Python with pandas, you'd do something like df.groupby('tier')['default'].mean() to get the conditional expectation at the tier level, then average those means weighted by group size to recover the unconditional estimate. The weighting matters — a simple unweighted average of group means is only correct if the groups are the same size, which they rarely are. The most common implementation error I see is forgetting that the outer expectation weights by the distribution of the conditioning variable. E[E[Y|X]] isn't the average of conditional expectations across observed X values — it's the average weighted by the probability of each X. In sampled data this means you need inverse probability weighting or importance weighting if your sample doesn't reflect the population distribution of X.

I use a simple check whenever I'm applying iterated expectations to real data. After computing the unconditional estimate through iteration, I compare it directly to the raw mean of Y. They should match within sampling error. If they don't, I've either weighted incorrectly, included a variable that shouldn't be in the conditioning set, or violated the nested sigma-algebra requirement. This sanity check catches most mistakes before they propagate into final estimates.